Ask Us Everything Recap: Bringing Enterprise Storage Simplicity to Azure
What happens when you take the enterprise storage capabilities IT teams rely on and deliver them as a fully managed, Azure-native experience? That question was at the heart of our latest Ask Us Everything, focused on Everpure Cloud Azure Native for Azure VMs. And judging by the questions from attendees, storage admins and cloud practitioners are thinking beyond simply moving workloads to Azure. They’re asking how to get there without trading familiar enterprise capabilities for higher costs, more operational overhead, or another collection of storage tiers to manage. Everpure experts David Stamen, Nick Scuola, and Joe Houghes dug into those questions—and the conversation surfaced several useful takeaways. “Azure already has storage. What makes Everpure different?” Cloud storage can mean navigating different offerings, tiers, feature sets, and regional availability. Joe contrasted that with the enterprise storage model Everpure customers know: capabilities delivered consistently through the Purity OS, rather than requiring administrators to continually determine which storage option provides which feature. Everpure Cloud for Azure Native brings capabilities including thin provisioning, deduplication, compression, performance, and availability into an experience designed to operate natively as an Azure service. Customers can deploy and consume it through Azure Marketplace, and get benefits they’re used to with their on-prem Everpure, all without managing the underlying storage infrastructure themselves. That distinction matters: IT gets enterprise-grade block storage, without turning cloud storage into another infrastructure management project. “How do I balance performance with cost?” Attendees naturally wanted to know about performance tiers—and the answer illustrated the service’s approach to simplicity. Instead of selecting among traditional on-prem array models or architecting around underlying infrastructure, customers simply choose the performance they need. The experts described a slider-based model for adjusting storage-pool performance, with Everpure handling everything behind the service. That abstraction becomes particularly valuable as Azure evolves. The panel discussed how underlying Azure storage improvements have previously delivered both performance gains and lower infrastructure costs. With a managed service, Everpure can incorporate infrastructure changes behind the scenes, rather than requiring customers to redesign their environments every time the cloud platform changes. As Nick summarized, the objective is the outcome: deliver the service level that customers need, while Everpure handles how it gets delivered. “Can cloud storage actually help reduce our Azure spend?” Cost was a recurring theme. We polled attendees, and half responded that they were “very concerned” about their Azure storage spend. One important lever that can help lower costs is data reduction. Thin provisioning, deduplication, and compression can reduce the physical capacity required, although results depend heavily on workload and data type. The experts noted that the majority of traditional application data benefit greatly from data reduction capabilities built into Everpure Cloud, while already-compressed or encrypted data naturally offer less reduction. The consumption model is simplified, too. Everpure Cloud for Azure Native combines the service and underlying infrastructure into a Marketplace purchase rather than separating software licensing from Azure infrastructure costs. Customers simply choose how much capacity and performance they need, and then receive it as one service and one bill. “Does this simplify my storage management job?” Perhaps the most important answer of the session: Yes! The experts described storage deployments that can be stood up in hours rather than turning implementation into a weeks- or months-long project. For example: once a storage pool is created, volumes can be connected to workloads using Azure VM extensions, simplifying the process of getting storage in front of an application. For experienced storage practitioners, that may be the biggest shift. Everpure Cloud for Azure Native isn’t about recreating every storage-management task in Azure. It’s about abstracting more of those tasks away so teams can concentrate on all their other work: applications, data, migrations, automation, and new initiatives. Or, as Nick put it during the session: the goal is to help free up customers to manage their applications and data—not their storage. That’s a cloud operating model storage admins can get behind. Check out this and all our other Ask Us Everything sessions. And, keep the conversation going by jumping into the Everpure Community.71Views1like0Comments
Cooking with “Enterprise Data Cloud”: Recipes for your Datacenter
September 24 | Register Now! Looking for practical ways to streamline your datacenter or hybrid cloud environment and run it more reliably? Following up from last September’s episode, “Cloud - A Place or a Strategy? Unpacking the Everpure Enterprise Data Cloud” (EDC) with JD Wallace, host Andrew Miller invites Michael Sasse (Principal Technology Strategist with Everpure for 11 years) to discuss how to make EDC real for YOU in the midst of the many industry changes from even just 12 months ago. We’ll explore: Changing customer needs: What Michael has heard as he discusses EDC with customers, including how speed and efficiency matters more than ever and the risk of being replaced if you’re perceived as the “department of no”. What EDC is: If you love dogs, you’ll love this (join us to see why). We’ll look at how EDC is driving the simplicity that FlashArray™ brought to the storage industry throughout the datacenter and cloud. Cooking the EDC souffle (making It real): We’ll look at the building blocks of EDC from a technical perspective — things like Fleets, Topology Groups, Presets, observability, governance, automation and more. Of course, underpinning all of this is Evergreen//One™. Presenting to the (exec) table: Think of this as delivering the meal. Having reviewed the building blocks, we’ll look at the outcomes both you and your executives care about. Think of this as 1) who is leveraging EDC, 2) how has it helped (measurable outcomes), and 3) why does it matter? Even better, we’ll discuss the EDC Blueprint: how Everpure is linking our products and features to outcomes that your CIO and CTO care about. September 24 | Register Now!70Views0likes0Comments
Everpure Cloud: Building an Efficient Storage Platform in Microsoft Azure
September 17 | Register Now More organizations are migrating VMs and containerized apps into Azure and hitting a wall: native cloud storage wasn't built to provide the enterprise data services they rely on. Teams are lifting workloads into the cloud only to discover unpredictable costs, the inability to manage their storage from a unified platform, and data protection gaps. Join us to learn how to easily scale demanding, storage-heavy workloads without sacrificing data requirements or budget. With the right storage platform as your foundation, your hybrid cloud environment can deliver flexibility, cost savings, and operational simplicity. Key takeaways: Versatile workload support: Seamlessly run and manage mixed enterprise workloads on Everpure Cloud without compromising performance or flexibility. Streamlined Azure integration: Rapidly provision and scale Everpure Cloud using familiar, standard Azure-native tools and workflows. Unified management and security: Simplify data management across cloud and on-premises environments with consistent controls, governance, and built-in data protection. Optimized storage TCO: Significantly reduce overall enterprise storage costs through efficient resource utilization. Register Now!300Views0likes0CommentsEnterprise Data Cloud: Managing Data, Not Just Storage
August 6 | Register Now Infrastructure teams have always managed applications. AI requires them to manage data. That's a different challenge, and most platforms weren't built for it. The Enterprise Data Cloud architecture from Everpure bridges that gap, bringing data intelligence into the same platform infrastructure teams already manage, so infrastructure and data teams are finally working from a single, unified view. In this session, we'll dig into what it means to manage a platform built for both operational performance and AI readiness, and the changes when infrastructure can finally gain visibility into its data, not just storage. Key takeaways: Why the shift from application-centric to data-first infrastructure changes how platforms need to be managed How Everpure brings data intelligence into the operational layer without adding tools, teams, or complexity What shared visibility across infrastructure and data teams actually unlocks for AI initiatives How to manage a platform that serves every workload, from archive to AI Register Now!188Views0likes0CommentsThe Containers Must Flow: Extending Kubernetes Principles to Your Data
July 7 | Register Now! Kubernetes (K8s) sits at the center of the known universe, steering the massive shift from legacy systems to next-generation applications and modern virtualization. In this vast desert of infrastructure, one truth remains absolute: they who control the data layer control the universe. For July 2026, your Kwisatz Haderach of hosts, Andrew Miller, invites mentat James McShane to explore these tectonic shifts—and why Portworx® is even more vital today than 5+ years ago when acquired by Everpure, formerly Pure Storage®, to be the ultimate k8s data layer. Here’s what we'll traverse on our journey: The path of the mentat James: From large-scale virtualization to massive K8s clusters, and even piloting K8s on autonomous drones (the ultimate hunter-seekers). The weirding way of modern tech: the explosion of new K8s developments with a focus on KubeVirt and how it’s reshaping modern virtualization trends. The litany against data loss: Core storage needs in K8s environments, the foundational Portworx design principles built to survive them, and why they matter when the sandworms of downtime strike. The voice of Portworx: New capabilities designed to conquer KubeVirt/VMware migrations, establish unified control planes, and shift your focus from rigid mechanics to pure intent (Imperative vs. Declarative)--dare we say, bending the infrastructure to your will. Register Now!146Views0likes0CommentsAccelerate 2026 - Part 1 - Everyone Wants Your Data
Back in February, I wrote that I had never been to Pure//Accelerate. This year, I still am not in Las Vegas. I watched the Everpure Accelerate 2026 opening keynote live from my home office, which turned out to be a different kind of vantage point. Not better than being there. Not worse. Just different. You do not get the hallway energy. You do not get the sponsor booths. You do not get the accidental conversations that happen while looking for coffee (or tea in my case). You do not get to read the room in the same way. You are not surrounded by the noise, the music, the badge lanyards, the customer reactions, or that strange conference feeling where everyone is tired and energized at the same time. A keynote viewed remotely has to work harder because the production does not carry you in the same way. If the speakers are just reading slides, you feel it immediately. If the story is thin, the distance makes it thinner. If the message is only a collection of announcements, you start checking email. But if the story is real, the distance does something interesting. It removes some of the theater. You are left with the words, the pacing, the ideas, and whether the people on stage actually believe what they are saying. This morning, the parts that landed with me were not the parts that felt the most polished. They were the parts where the keynote stopped sounding like a keynote and started sounding like people trying to explain a real shift in the industry. For me, the strongest moments came from Charlie Giancarlo, Chadd Kenney, Shawn Rosemarin, and the NVIDIA conversation. Not because they had the most slides. Not because they had the most numbers. They landed because they are storytellers. That matters more than we sometimes admit in enterprise technology. A slide reader can tell you what a product does. A storyteller can tell you why the product had to exist and why it matters to the customer or partner. There is a difference. And this morning, the difference mattered. Charlie’s most important line came early, and it changed the shape of the keynote. He said he was not going to talk about data storage. He was going to talk about data. For a storage company’s major customer event, that is not a small pivot. It would have been easy for Everpure to spend the morning celebrating the familiar things. Growth. Customer count. Market share. Flash leadership. Subscription run rate. Fusion adoption. Gartner recognition. Net Promoter Score. Performance numbers. Efficiency numbers. All of that was there, and all of that matters. But the real keynote was not about proving that Everpure is good at storage. The real keynote was about arguing that storage is no longer the highest-level conversation. Data is. That is where the rebrand from Pure Storage to Everpure starts to become more than a name change. A company called Pure Storage can be excellent at arrays, controllers, upgrades, density, performance, and simplicity. A company called Everpure has to earn the right to talk about the enterprise data cloud, and that is a much larger promise. It is also a much riskier promise. Because once you move north of storage, you are no longer talking only about where data lives. You are talking about who controls it, who understands it, who governs it, who protects it, and who gets to use it. That is where Charlie’s message became interesting. His argument was that the enterprise has spent decades living in an application-centric architecture. ERP had one version of the business. CRM had another. ServiceNow had another. HR systems had another. Analytics platforms copied data out of all of them. Data lakes were built to make sense of the mess. Now AI agents are being asked to reason across that same fragmented landscape. That is the problem. Not AI in theory. AI on top of fragmented truth. We have all seen some version of this. The definition of a customer changes depending on which system you ask. The data in one application does not quite match the data in another. A report is technically correct, but only according to one source. A copy was made for analytics, another for backup, another for a project, another for a data science team, and one more because someone needed it urgently two years ago and nobody knows if it is still being used. Now imagine asking an AI agent to act on that. That is where the phrase “Data Primacy” becomes more than keynote language. From what I understood this morning, Data Primacy is Everpure’s argument that data should no longer be trapped inside applications as a secondary object. The data itself, along with its context, relationships, governance, and sources of truth, has to become primary. Applications still matter. Workflows still matter. SaaS still matters. But the enterprise cannot keep allowing every application to define its own version of reality and then expect AI to make intelligent decisions across the pile. That is not sustainable. One of the strongest lines from Charlie was the idea that every vendor wants your data. Every SaaS vendor wants your data. Every analytics vendor wants your data. Every AI vendor wants your data. But what they really want is not just the data. They want the context. They want the meaning. They want to know how a customer in one system relates to a contract in another, a support case in another, an invoice in another, a shipment in another, a security policy in another, and a business outcome somewhere else entirely. In the AI era, context is the new land grab. That is the sentence I kept coming back to during the keynote. Everyone wants your data, but the bigger fight is over who owns the context. That is why this morning did not feel like just another AI infrastructure pitch. It felt like Everpure trying to move the conversation from managing arrays to managing truth. That is a big claim. It needs proof. And that is where Chadd Kenney’s part of the keynote mattered. Chadd is one of those speakers who can make infrastructure feel like an actual story instead of a list of capabilities. That is not easy. Storage features can get very technical very quickly, and if you are not careful, everything turns into a blur of replication, snapshots, policies, performance, controllers, and acronyms. But Chadd framed the platform in a way that made sense. First, the unified data plane stores the data. Then the intelligent control plane governs and operates it. Then the universal data intelligence layer helps understand it. Together, those pieces create a different operating model. That phrase, operating model, is important. Because the most interesting part of the demo was not just that Fusion can automate tasks. It was that Everpure is trying to change the relationship between people and infrastructure. The old world asks humans to be perfect by hand. Log into this array. Check that policy. Fix that snapshot setting. Compare it to the spreadsheet. Make sure the production workloads are covered. Exclude dev and test. Check compliance. Update the retention period. Open the change. Wait for the window. Hope nobody missed one. We have normalized that kind of work for years. Then we call it operational discipline. Sometimes it is. But sometimes it is just human beings being forced to compensate for systems that do not understand intent. The Fusion demos showed something better. Define the policy once. Attach intent to the workload. Let the control plane detect drift. Let it show violations. Let it recommend a fix. In some cases, let it act. In other cases, keep the human in the loop, but stop making the human do repetitive work that the platform should be able to understand. The ransomware snapshot example was a perfect illustration. A customer mandate changes retention from fifteen days to thirty days. In many environments, that becomes a manual chase across infrastructure. In the keynote demo, it became a policy problem, a compliance view, a remediation path, and an audit trail. That is what infrastructure teams actually need. Not another dashboard that tells them something is broken. A system that understands what “correct” looks like and helps keep the environment there. The workload mobility demo made the same point from a performance angle. If the platform can see that a workload is trending toward a service level violation, recommend a better placement, validate the move, and relocate that workload without the application owner noticing, that is not just automation. That is infrastructure keeping a promise quietly. And quiet matters. The best infrastructure usually disappears. Nobody sends a thank-you note because latency did not spike. Nobody opens a champagne bottle because a replication policy worked. Nobody celebrates the outage that did not happen. But those invisible wins are the difference between a team that spends its life firefighting and a team that gets to work on the next thing. That is why the Active Cluster for File demo also worked. Synchronous replication for file sounds technical, and it is. But the emotional value is simple. When something fails, the business does not want a heroic recovery story. It wants no story at all. The workload quietly packed its bags and moved. That line stayed with me because disaster recovery should be boring. Boring is the goal. Boring means the policy worked, the automation worked, the architecture worked, and the humans did not have to assemble on a bridge call at 2 a.m. to save the day. Then Shawn Rosemarin took the keynote into the AI conversation, and again, the strength was in the framing. The bottleneck stalling AI is not compute. It is not models. It is not tooling. It is data. That is the part of the AI conversation that I think many customers are starting to feel more clearly. For the last few years, the market has been obsessed with models and GPUs. That made sense. There was a lot to understand, and the infrastructure requirements are real. But most customers are not trying to build the next frontier model. They are trying to unlock the intelligence that already exists inside their own business. Their documents. Their contracts. Their transactions. Their support history. Their clinical records. Their policies. Their engineering files. Their internal knowledge. Their institutional memory. That does not become useful just because someone points a model at it. It becomes useful when the data is prepared, classified, curated, governed, indexed, vectorized, and delivered with the right context at the right time. That is why the Everpure Data Stream announcement with NVIDIA mattered. The message was not simply, “We can feed GPUs fast,” although performance absolutely matters. The more important message was that enterprise AI needs a way to make data AI-ready without creating another silo, another copy, another stale version of the truth. Shawn made the point clearly: other vendors want you to copy your data into their system. But a copy is always behind. That is such a simple sentence, but it carries a lot of weight. A copy has to be protected. A copy has to be governed. A copy has to be reconciled. A copy has to be secured. A copy can drift. If AI is going to answer questions, automate workflows, make recommendations, or support decisions, stale context is not just inefficient. It is dangerous. That is where the NVIDIA conversation added credibility. The point was not just that Everpure has a partner logo on a slide. The point was that AI has become a full-stack infrastructure problem. Data has to move efficiently. GPUs cannot sit idle waiting for bytes. Inference needs low latency and quick access to the right information. Agents need context. Networking matters. Storage matters. Hardware matters again. I liked the line about hardware being cool again. I liked it because it is funny, but also because it is true. For years, parts of the industry talked as if infrastructure had become invisible. Cloud abstracted it. SaaS hid it. Software ate the world, and many people acted as if the physical layer was someone else’s problem. AI ended that illusion. When customers are investing serious money in GPUs and trying to build real AI capability, storage is not a commodity. Networking is not plumbing. Metadata performance is not trivia. Power is not someone else’s concern. Operational excellence is not optional. The physical world is back in the strategy conversation. Maybe it never left. Maybe some people just stopped looking. That is why the keynote worked for me, even from my home office. Not because every demo was relevant to every customer. Not because every phrase was perfect. Not because I think one keynote answers every question. That is what the next two days are for. It worked because the best speakers were not just announcing things. They were connecting the dots. Charlie explained why the application-centric model is running out of room. Chadd showed what it looks like when infrastructure starts operating from intent instead of manual heroics. Shawn connected AI success back to data readiness instead of model worship. The NVIDIA conversation reminded everyone that AI is not magic. It is infrastructure, data movement, context, governance, and execution. That is a story. And in enterprise technology, the story matters because customers are not just buying features. They are buying a way out of the mess they are already in. The mess is fragmentation. AI did not create that mess, but AI is making it impossible to ignore. That may be the real takeaway from day one of Accelerate. The AI era is forcing enterprises to confront the data architecture choices they have been living with for decades. The old model was manageable when humans were the ones reconciling the gaps. It becomes much more dangerous when agents begin acting on top of those gaps at machine speed. That is why Everpure’s move toward Data Primacy is worth paying attention to. It is not just a product direction. It is a point of view. The application should not own the truth. The copy should not become the truth. The dashboard should not pretend to be the truth. The enterprise needs to own its data, understand its context, govern its use, and make it available to applications, analytics, and AI in a way that is coherent and trustworthy. That is easy to say and very hard to do. But this morning, for the first time, I felt the full shape of what Everpure is trying to become after the rebrand. Not just a storage company with a new name. Not just a platform company using AI language because everyone has to. But a company trying to move the enterprise conversation north of storage and into the question that will define the next decade: Who owns the context of your business? Because everyone wants your data. The companies that win will be the ones that know what it means. I appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere105Views1like1CommentHealthcare Sessions at Accelerate 2026
Accelerate is almost here! 🙌 Check out our special track tailored for healthcare professionals. Hear from Everpure experts about the latest trends and strategies for data management success in healthcare. If this sounds right up your alley, we’ve curated a list of must-attend breakout sessions focused on all things Healthcare. Check out these don't miss sessions: Modernizing Epic Infrastructure: Performance, Flexibility, Resilience, and Virtualization Evolving Everpure Cloud Value: A Smarter Hybrid Cloud Approach for Healthcare Predictable Imaging Economics: Powering End-to-End Solutions with Price-per-Study Edge AI in Production: Real-Time Decision-Making in Sanofi’s Cryo-EM Core Will you be joining us in person? Drop a comment below with the session you're most interested in and what you hope to learn!345Views2likes0CommentsFinancial Services Sessions at Accelerate 2026
Accelerate is almost here! 🙌 Check out our special track designed to connect with FSI professionals. Hear from Everpure experts about the latest trends and strategies for data management success in Financial Services. If this sounds right up your alley, we’ve curated a list of must-attend breakout sessions focused on all things Financial Services. Check out these don't miss sessions: Why 95% of AI Pilots Fail at Scale, and How a Finance Sector MSP Beat the Odds Sovereign by Design: Delivering a Cloud Operating Model within the Firm’s Own Borders Cyber Defense in a Flash: Spotting the Smoke Before the Fire Will you be joining us in person? Drop a comment below with the session you're most interested in and what you hope to learn!75Views1like0CommentsJoin Everpure Cloud at Pure Accelerate 2026
If you're coming to Pure Accelerate, make time for the Everpure™ Cloud sessions. This year's lineup brings together breakout sessions, flash talks, and a community meetup focused on modern cloud storage across Azure and AWS, workload design, hybrid cloud strategy, and practical ways to improve cost efficiency and operational simplicity. Whether you're evaluating how to support Azure VMs at scale, looking for better patterns for hybrid workloads, or trying to bring more predictability to cloud storage costs, these sessions are designed to help you move from strategy to execution. Why attend the Everpure Cloud sessions? Cloud teams are under pressure to do more than just migrate. They need to control costs, simplify operations, and build architectures that can adapt as business needs change. At Pure Accelerate, the Everpure Cloud sessions will focus on exactly those conversations, with content spanning architecture, scale, FinOps, storage operations, and real-world workload guidance. This is a strong opportunity to hear how Everpure Cloud supports modern cloud environments across Azure, AWS, and hybrid use cases, while giving infrastructure teams more flexibility in how they scale and manage storage. Featured Everpure Cloud sessions at Pure Accelerate Breakout sessions Modern Azure Storage with Everpure Cloud: Architecture, Scale & FinOps — Thursday, June 18, 1:45–2:30 PM PT. Configuring Workloads for Everpure Cloud: Architectures, Patterns, and Gotchas — Thursday, June 18, 1:45–2:30 PM PT. Maximizing Hybrid SQL Server 2025 on Azure with Everpure Cloud — Wednesday, June 17, 2:45–3:30 PM PT. These breakout sessions are ideal for attendees who want a deeper look at architecture decisions, workload best practices, and ways to align cloud storage performance with cost and scale requirements. Flash talks Everpure Cloud Azure Native for Azure VMs in 15 Minutes — Thursday, June 18, 2:45–3:05 PM PT. Accelerating Storage Operations with Everpure Cloud — Thursday, June 18, 3:15–3:35 PM PT. Evolving Everpure Cloud Value: A Smarter Hybrid Cloud Approach for Healthcare— Thursday, June 18, 12:30–12:50 PM PT. Public Cloud Experience, Private Cloud Economics— Thursday, June 18, 12:00–12:20 PM PT. If you want high-value takeaways in a shorter format, these flash talks are a great way to quickly explore how Everpure Cloud can help streamline operations, support Azure VM environments, and improve the economics of cloud storage. Community session Community Meetup: You're Moving to the Cloud: Now What? — Wednesday, June 17, 5:30–6:30 PM PT. This meetup is a great fit for anyone looking to exchange ideas with peers, hear different perspectives on cloud adoption, and join a broader conversation around the challenges and opportunities that come with moving to the cloud. Meet the Everpure cloud team at booth If you're in Las Vegas for Pure Accelerate, stop by the Everpure Cloud showcase booth to continue the conversation in person and to learn how organizations are reducing storage costs, simplifying operations, and scaling hybrid cloud environments more efficiently. Learn more To explore the Everpure Cloud portfolio in more detail, visit the Everpure Cloud webpage. For deeper technical guidance, check out these Knowledge Portal resources: Everpure Cloud Dedicated for Azure documentation Everpure Cloud Dedicated for AWS documentation Everpure Cloud Azure Native documentation Add Everpure Cloud to Your Pure Accelerate Agenda If cloud cost optimization, operational simplicity, and scalable storage architectures are priorities for your team, be sure to add these sessions to your Pure Accelerate schedule. We look forward to seeing you there. Ready to join us in Las Vegas? Register now for Pure Accelerate 2026 and start building your agenda. We look forward to seeing you there.380Views2likes0Comments"Where’s Waldo?", But for your Data
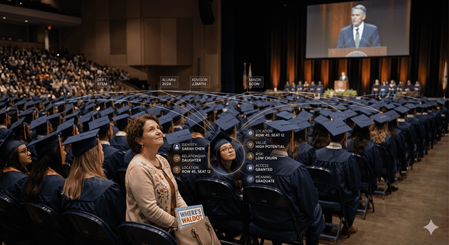
This past Saturday, my wife and I sat at my son’s college graduation ceremony doing what every proud parent does after running out of tears and tissues: staring at the giant screen, scanning a crowd of thousands, and playing a very emotional, very expensive version of Where’s Waldo? The camera pulled back and showed the graduating class. Thousands of caps. Thousands of gowns. Thousands of people who had just survived exams, group projects, late-night studying, bad cafeteria decisions, emotional phone calls home, and whatever personal version of “I’ll start the paper tomorrow” they subscribed to. Somewhere in that sea of mostly identical academic robes was my son. I knew he was there. We had dropped him off at college years earlier, paid tuition, bought supplies, endured move-in day, survived the separation anxiety, worried about him, cheered for him, and occasionally pretended to be calmer than we actually were. I knew exactly why we were in that room. But on that screen, in that moment, he was just one face among thousands. So I started searching for him. Every parent around me was probably doing some version of the same thing. We were not looking at a graduating class in the abstract. We were looking for our graduate. Everyone else on that screen mattered deeply to someone, but to us they were mostly context without identity: a massive, moving, emotional dataset with almost no metadata attached. That was the strange thing about the picture. It showed us everything and told us almost nothing. There were thousands of people on the screen, but unless you already knew who you were looking for, you did not really know what you were looking at. Somewhere between the pride, the camera angle, and my increasingly poor performance at parental facial recognition, my brain did what my brain unfortunately does. It connected a very human moment to the way enterprises think about data. Because this is exactly the problem most organizations have with their data. They know it is there. They know there is a lot of it. They know some of it is incredibly valuable, some of it is probably risky, and some of it is duplicated, outdated, forgotten, regulated, misplaced, or being accessed by people and systems nobody has thought about in years. But knowing there is a crowd is not the same thing as knowing who is in it. That is the part we do not talk about enough. For years, data management conversations were mostly about where the data lived, how it was protected, how fast it could be accessed, and how much it cost to keep it all running. Those things still matter. They will always matter. But they are no longer enough. The new question is not simply, “Where is the data?” The better question is, “What is this data, who does it belong to, why does it exist, who is using it, where has it moved, what risk does it carry, and should this AI model, business process, analyst, application, or employee be touching it at all?” That is a very different conversation, and that is why 1touch matters. Not because the industry needed one more product logo, one more acronym, or one more keynote phrase that sounds important until everyone quietly admits they are not exactly sure what it means. 1touch matters because it is aimed directly at the problem of not knowing. The lie of visibility Most organizations believe they have visibility into their data because they have tools that can show them infrastructure. They can show arrays, volumes, file systems, buckets, databases, dashboards, latency charts, replication status, backup jobs, snapshots, anomalies, alerts, and the occasional red icon that ruins someone’s morning. All of that is useful. None of it guarantees understanding. An IT team can tell you a volume is 87 percent full, but that does not mean they know it contains expired customer records, old HR exports, forgotten underwriting files, production data copied into a test environment, or a spreadsheet with 40,000 Social Security numbers created in 2018 by someone who left the company three reorganizations ago. A security team can tell you an alert fired, but that does not mean they know whether it represents real exposure, a false positive, or just another noisy event in a pile nobody has enough hours to investigate. A data team can point to a lake, a warehouse, a catalog, and a governance process, but that does not mean the data is clean, trusted, current, properly classified, or safe to feed into an AI workflow. This is the uncomfortable truth: enterprise data visibility has often meant visibility into containers, not contents. We could see the auditorium. We could count the very uncomfortable seats. But we still could not tell which graduate was my son. The graduation screen was not useless. It showed scale. It proved the event was real. It helped me understand the crowd. But until I could identify the person I cared about, the picture was incomplete. Enterprise data estates work the same way. The problem is not that organizations have no tools. They often have too many. The problem is that many tools see the surface of the environment but miss the identity, relationship, movement, and meaning of the data inside it. That gap was inconvenient in the old world. In the AI world, it is dangerous. AI does not forgive ignorance Before generative AI entered every boardroom conversation, the consequences of not knowing your data were already serious: compliance exposure, bloated infrastructure costs, security blind spots, slow audits, manual discovery, painful legal requests, cloud migration delays, and business users waiting weeks for access to information because nobody could confidently say what was safe to use. Then AI showed up and made the problem louder. AI feeds on data. Lots of it. Structured data, unstructured data, documents, emails, transcripts, PDFs, customer records, logs, knowledge bases, support case histories, SaaS exports, file shares, objects, and anything else that might help a model answer a question, summarize a situation, automate a workflow, or make a decision. That sounds exciting until you remember that most enterprises do not fully know what is in all of those places. And AI is not magic. If the input is wrong, the output inherits that problem. Sometimes the model hallucinates. Sometimes it exposes something it should not. Sometimes it makes a recommendation based on data that was never supposed to leave a specific jurisdiction. Sometimes it answers confidently from a document that was obsolete three policies ago. Sometimes it gives the right answer to the wrong person, which may be the scariest version of all because the technology can look like it is working while quietly violating the trust model of the business. That is why “AI-ready data” cannot simply mean “we pointed a model at a repository.” That is not readiness. That is hope with an API call. AI-ready data needs context. It needs classification, identity, policy, and confidence. It needs a way to distinguish between a harmless document, a restricted record, a regulated attribute, an exposed credential, and a data fragment that only becomes sensitive when connected to other fragments somewhere else. A number or a name by itself may not mean much. A location, transaction, or timestamp by itself may not mean much either. But connect the number to the name, the name to the patient record, the patient record to a geography, the geography to a regulation, the regulation to a storage location, and the storage location to an access path, and suddenly you are not looking at random data anymore. You are looking at risk. Or value. Often both. This is where 1touch becomes important, because its value is not just identifying patterns and sticking labels on files. Its value is in discovering, classifying, and contextualizing data across environments so organizations can understand not only what exists, but what it means. That distinction matters. The difference between labeling and knowing At graduation, every student had the same basic label: graduate. That label was accurate, but it was wildly insufficient. One graduate may be heading to medical school. Another may be joining a startup. Another may be the first person in their family to earn a degree. Another may have worked two jobs to get there. Another may have changed majors three times and somehow still finished on time, which frankly deserves its own medal. The label tells you the category. The context tells you the story. Data works the same way. A traditional tool might identify something that looks like a credit card number, Social Security number, email address, medical code, account number, or passport field. That is useful, but it can also create noise. Strings of digits appear everywhere. Test data looks real. Real data looks fake. A file name can lie. A folder path can be misleading. A database column called “ID” might be harmless, or it might be the key to everything. Context is what turns a guess into intelligence. 1touch approaches this problem by looking at the broader semantic environment around the data. It is not just asking, “Does this pattern match something sensitive?” It is asking, “What surrounds it? What system did it come from? Who accesses it? Where does it move? What other data is connected to it? What business process does it support? What regulatory meaning does it carry?” That matters because in the real world, data risk rarely lives in a single isolated field. It lives in relationships. The same way my son was not immediately identifiable to the room because he was wearing a cap and gown like everyone else, sensitive enterprise data is often not obvious because it is dressed like everything else. It sits in file shares, databases, cloud repositories, SaaS platforms, mainframes, archives, exports, and forgotten project folders. It blends into the crowd. The old approach was to scan the crowd every so often and hope you recognized enough faces. The newer requirement is continuous understanding: discovering data where it lives, watching how it moves, connecting fragments across systems, and building a living map of identity, access, classification, and risk. Not a once-a-year inventory. Not a spreadsheet. Not a governance theater exercise where everyone nods in a meeting and then goes back to copying production data into development because the test system “needed something realistic.” A living map. That is the real promise. Why this matters The value of 1touch can be easy to undersell if we describe it only as sensitive data discovery or Data Security Posture Management (DSPM). Those descriptions may be accurate, but they are not the business problem. A prospect is not waking up hoping to buy a classification engine. They are waking up with pressure from the board, auditors, regulators, cyber insurers, application owners, AI initiatives, cloud migration teams, and business leaders who want faster access to “clean” data without increasing risk. And for those of us who have been around this industry long enough to have a few emotional support scars, this problem is not new. We were talking about lifecycle data management and data classification projects 20 years ago. Kazeon, StoredIQ, and others were all trying to help customers understand what was hiding inside their unstructured data environments before the phrase “dark data” became a fashionable way to describe a very unfashionable mess. I personally used Kazeon back in 2006, before EMC acquired it and eventually killed it. The idea was right. The experience was painful. I remember a project where it took almost two months to scan the environment, process the results, and prepare the report. We finally sat down with the customer, proudly showed them the findings from roughly 5TB of unstructured data, and waited for the moment where they would appreciate all the classification goodness we had brought into their lives. Instead, the customer looked at us and asked the only question that mattered: “Where is the rest of my 55TB?” There are moments in a technical meeting when the room temperature changes without the thermostat being involved. This was one of them. Apparently the tool did not have permissions to scan the rest of the environment. So after two months of work, the result was technically accurate and practically incomplete, which is the most dangerous kind of confidence. We had a report. We had charts. We had findings. What we did not have was the whole truth. That is why this matters now. The enterprise data problem did not begin with AI. AI simply made the consequences of incomplete understanding much harder to ignore. Twenty years ago, a bad classification project meant a frustrated customer, an awkward meeting, and a lot of manual cleanup. Today, the same kind of blind spot can contaminate an AI pipeline, expose regulated data, break a sovereignty policy, delay a migration, or give executives a false sense of security. For existing customers, the value is even more strategic. They already trust the platform to store, protect, move, and serve their data. The next logical question is whether it can help them understand the data as well. That is the bridge 1touch helps build. That is important because customers are tired of stitching together disconnected tools where one product sees storage, another sees identity, another sees security events, another sees data catalogs, another sees cloud posture, and another sees compliance workflows. Everyone sees something, but nobody sees enough. Customers do not need more fragmented visibility. They need connected context. Most importantly, it helps us explain why the conversation has moved from where data sits to what the data actually means. Back to the screen Eventually, during the ceremony, I found my son. Definitely when his name was announced and he walked across that stage. But the moment stayed with me because it was such a simple reminder: seeing a crowd is not the same as knowing the people in it. Every person on that screen had a story, a history, a family somewhere in the stands trying to yell the loudest, and a future that was about to begin. From a distance, they looked identical. Up close, they were anything but. Enterprise data is like that too. From a dashboard, it can look like capacity, files, objects, tables, volumes, buckets, repositories, shares, records, and logs. But inside that data are customer identities, patient histories, citizens tax records, contracts, intellectual property, employee information, business secrets, stale copies, duplicate exports, forgotten archives, useful insights, hidden risks, and the raw material for the next generation of AI-driven business processes. The organizations that win will not be the ones that simply store the most data. They will be the ones that know what their data means. That is why 1touch matters. Because the future of data management is not just finding Waldo. It is understanding the entire crowd. Appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere57Views0likes0Comments