Get rid of stressful infrastructure headaches. Everpure Fusion handles your data, autonomously.
It happens! It's 11:45 PM on a Friday. An alert fires and storage latency has spiked across a production workload. The operator digs in and traces it back to an automated tiering policy that quietly moved a hot dataset to a slower tier because it looked idle based on a 24-hour access window, right before a scheduled batch job that runs every weekend. Nobody changed anything. The policy did exactly what it was configured to do. But nobody remembers configuring it that way, the documentation hasn't been touched in two years, and the monitoring dashboard shows storage as "healthy" because utilization is fine. It's just in the wrong place. The operator overrides the tier, performance recovers, and spends the next hour writing an incident report for a problem that shouldn't exist. A system that was supposed to make life easier made a decision with no context, no warning, and no visibility into why. That's the anger that doesn't go away quickly. It's not just frustration at the incident. It's the feeling that the tools are working against you instead of with you. The core problem in that story was a system making decisions with no context, no warning, and no visibility. Everpure Fusion attacks each of those problems: Unified visibility across the entire fleet: Everpure Fusion provides a global dataset as a single source of truth for discovery, management, and configuration of storage arrays so the operator isn't piecing together what happened across multiple dashboards, multiple arrays, multiple tickets after the fact. They see the full picture in one place, before things go wrong. Intelligent workload placement: Rather than static policies quietly acting on stale access patterns, Everpure Fusion uses AI-guided placement to boost performance and efficiency for every workload. It understands workload behavior, not just utilization snapshots, the kind of context that would have caught a batch job pattern before tiering the dataset down. Policy-driven governance with real control: Automated orchestration cuts manual tasks and speeds service delivery, while unified controls simplify audits, reduce risk, and prove compliance fast. Policies are visible, documented, and governable. Not buried configs nobody remembers setting. Built into the platform, not bolted on: Evepure Fusion is now simply a part of Purity, meaning it is not an add-on you have to install or buy, but rather a core piece of the Purity operating system. The operator doesn't have to manage another tool. The intelligence is already there. The operator in that story didn't need more alerts. They needed a system that understood context, made decisions transparently, and gave them control without requiring them to be online at midnight to maintain it. That's exactly the gap Everpure Fusion is designed to close - with One Fleet, Zero Complexity. Why policy-driven storage operations matter Everpure Fusion is built as the core of Everpure intelligent control plane that manages all arrays including FlashArray, FlashBlade, and cloud as a unified fleet, with one topology, one API, and one operational framework regardless of protocol or local - datacenter, cloud or edge. That uniformity is what makes policy enforcement reliable at scale. Everpure Fusion introduces workload-based provisioning through presets, which are predefined policy-driven templates for specific workload types, encoding protection policies, replication, and SafeMode retention from the moment a workload is provisioned, not patched in after an incident. Admins no longer need to pre-plan and tune deployments manually, which reduces the risk of non-compliance and improves resiliency by ensuring workloads are provisioned correctly from the beginning. The result is infrastructure that enforces your intent, not just your last manual action. Intelligent placement, rebalancing, and fleet-scale capacity control If you manage storage at scale, you've probably seen this scenario play out more than once. One array is buried, running hot, and screaming for relief. Three aisles over, another array is sitting at 40% utilization, doing almost nothing. And somewhere in between, your team is scrambling to provision capacity, kick off an emergency migration, and explain to stakeholders why an SLA was missed on a workload that, in hindsight, never should have been placed there in the first place. This is not a people problem. It is a tooling problem. And it is remarkably common. Everpure Fusion starts solving this problem at the moment of provisioning. When a new workload lands, most storage systems do a simple capacity check and place it wherever space is available. Everpure Fusion does something fundamentally different. The placement engine evaluates every array in the fleet simultaneously, looking at IOPS headroom, throughput capacity, and physical utilization before making a decision. The goal is not just to find somewhere to put the workload. It is to find the right home for it, one where it can live comfortably for the long term without creating a bottleneck down the road. Think of it as placing workloads with intention rather than convenience. Of course, environments do not stay static. Workloads grow, usage patterns shift, and an array that looked healthy six months ago can become a problem today. Everpure Fusion accounts for this with continuous rebalancing built directly into its operation. When an array starts trending toward overload, Everpure Fusion detects it and begins orchestrating data movement across the fleet automatically. No manual intervention required. No application downtime. Data migrates in the background while workloads keep running, and arrays that were sitting underutilized suddenly become productive members of your infrastructure. At fleet scale, now supporting up to 64 arrays, this turns capacity management from a constant firefight into something that largely runs itself. What makes this possible without disruption is how Everpure Fusion executes the move under the hood. It leverages ActiveCluster to stretch the volume across both the source and target arrays simultaneously, creating a synchronous mirror in place. Once the stretch is established, volumes are connected on the target array and hosts auto-discover the new target paths through standard multipathing. The target then validates that path usage is healthy and confirmed before any cutover begins. Only after that validation is complete are the volumes disconnected from the source, ensuring there is zero gap in access at any point in the sequence. Everpure Fusion then unstretches from the source array to complete the rebalance and release its capacity. The result is a seamless, non-disruptive migration that the application never sees. What truly sets Everpure Fusion apart from a standard load balancer is what happens under the hood. Powered by Pure1 AI and up to 30 days of historical workload data, Everpure Fusion does not just look at what is happening right now. It looks at what is about to happen. Say you have a workload that runs a heavy batch job every Saturday night. Everpure Fusion knows that. It has seen the pattern. So when the placement engine is evaluating tier assignments, it will never recommend moving that workload to a lower-performance tier just because it looks quiet on a Tuesday afternoon. It understands what Tuesday quiet actually means in context. And if that workload somehow ends up on the wrong tier, perhaps through a manual change or a migration gone sideways, Everpure Fusion will proactively raise a violation before the weekend arrives. Not after the SLA is missed. Before. The cumulative effect is that customers can operate their fleets closer to full utilization without the anxiety that normally comes with it. Underused hardware gets activated, incremental purchases get deferred, and the reactive, always-behind-the-curve model of capacity management starts to look like a problem from a previous era. And Everpure Fusion does not stop at the infrastructure layer. Through its integration with Pure1 Application Intelligence, Everpure Fusion gains deeper visibility into the nature of the workloads themselves, not just how they behave, but what they actually are. That additional context means smarter decisions at every level, from initial placement to long-term tier management, grounded in a more complete picture of what your environment is really doing. Workload rebalance and mobility will be available towards the end of 2026. Compliance as part of the control plane Most storage compliance workflows follow the same pattern: an audit is announced, someone pulls reports from three different tools, cross-references configuration against a spreadsheet of expected settings, and spends two weeks proving that workloads are protected the way they're supposed to be. Then the audit ends and nothing changes until the next one. That model breaks at fleet scale. When you're managing dozens of arrays across multiple sites and protocols, manual audits don't just slow you down — they leave gaps that only get discovered at the worst possible time. Everpure Fusion Compliance is built into the control plane, not bolted on after provisioning. Because Everpure Fusion presets encode protection policies, replication requirements, SafeMode retention, and QoS settings at deployment time, Everpure Fusion always knows what every workload's intended configuration is. Drift detection is continuous — not periodic. When a workload deviates from its preset, Everpure Fusion instantly surfaces the violation — visible in the UI, queryable via API or CLI, and accessible to AI agents through an MCP server. Remediation can be triggered directly through the same interfaces, without pulling in a separate tool or writing a custom script. Fleet-wide compliance dashboards give storage admins a live view of posture across every array, with exportable audit-ready reports that don't require manual assembly. The shift is meaningful: compliance becomes a property of how the fleet operates, not a project that interrupts how the team works. Everpure Fusion Compliance will be available towards the end of 2026. From dashboards and scripts to natural-language fleet operations You know the drill. A latency spike hits production. You open three dashboards, run a handful of CLI queries, dig through alert logs, and piece together enough context to understand what happened — and by then, you've already spent 45 minutes on a problem that should have taken five. The issue isn't the tools. It's that the context your fleet holds is trapped across systems that don't talk to each other. Everpure Fusion MCP Server changes that. Built on the open Model Context Protocol standard, it connects any MCP-compatible AI assistant — Claude, ChatGPT, Copilot, or internal agents — directly to live Everpure Fusion fleet state. Arrays, workloads, capacity, performance metrics, alert history, configuration, and placement data are normalized into clean, structured JSON and made available to AI in real time, pulled directly from Everpure Fusion and Purity REST APIs. The result: instead of navigating dashboards and stitching together CLI output, you ask a question. "Which arrays are approaching capacity?" "What's driving latency on this workload?" "Which workloads are drifting from their preset?" Everpure Fusion MCP Server answers from live fleet context, not stale snapshots. This is the on-ramp to agentic storage operations. Everpure Fusion already enforces policy and placement across the fleet. Pure1 adds AI-driven analytics and recommendations on top. Together, they give infrastructure operators the foundation to move from reactive troubleshooting to intent-driven, increasingly autonomous fleet management. Using topology groups to encode real infrastructure boundaries If your Everpure Fusion fleet's topology model lives in a color-coded spreadsheet, three wikis, and the institutional memory of one senior admin who never takes vacation — this is for you. Everpure Fusion, built into Purity for FlashArray and FlashBlade, introduces Topology Groups: fleet-scoped objects that let you describe your arrays in the same language your architecture diagrams already use — regions, availability zones, datacenters, rows, racks. No more provisioning a Everpure Fusion workload and hoping it lands in the right building. A Everpure Fusion Topology Group is a hierarchical, tree-structured object. Groups nest up to 10 levels deep (global → us-east → az-us-east-1a → dc01 → row3 → rack12), each array belongs to exactly one parent, and cycles are rejected at write time. Critically, they encode placement semantics — not access control. RBAC stays in Pure1 Resource Groups; topology stays in Everpure Fusion topology. Once modeled, Everpure Fusion presets reference groups using <group>.arrays notation. Everpure Fusion intersects the preset's allowed arrays with the group's membership at placement time. If there's no overlap, Everpure Fusion provisioning fails fast with a clear error — not silently in the wrong zone. The Everpure Fusion CLI shorthand makes automation clean: purevol list --context az-us-east-1a.arrays Everpure Fusion membership changes propagate automatically across the fleet. You stop maintaining a second source of truth outside the control plane. Stop treating topology as tribal knowledge. With Everpure Fusion, make it a first-class part of the intelligent control plane. Extending the model to Kubernetes and virtualization Most infrastructure operators are managing two parallel storage worlds right now: traditional VMs and databases on one side, Kubernetes-based containerized workloads on the other. Separate toolchains. Separate provisioning workflows. Separate everything. Everpure Fusion changes that. Through the Portworx Fusion Controller, Everpure Fusion extends its policy and placement control plane directly into Kubernetes — without forcing developers to change their existing workflows. Everpure Fusion auto-discovers your FlashArray and FlashBlade fleet, then exposes Everpure Fusion presets as native Kubernetes StorageClasses. That means when a developer requests a persistent volume, Everpure Fusion's placement engine resolves it against your existing policy constraints — storage class, protection policy, topology group, replication requirements — the same way it does for any other Everpure Fusion workload. No separate control plane for modern environments. No array-by-array configuration for each cluster. New arrays added to the fleet are automatically discovered and configured, so the operational model stays consistent as infrastructure grows. For VMware environments, Everpure Fusion extends the same operational model through the Everpure Fusion vSphere plugin, connecting storage management directly into virtualization workflows instead of running it as a separate administrative domain. The result: one control plane, one set of policies, one placement engine — spanning VMs, containers, and databases across the fleet. That is fewer parallel stacks to operate, less configuration drift between environments, and a more scalable path to consistent storage operations across the full infrastructure stack. Everpure Fusion as the storage admin foundation for autonomous operations The through-line across everything covered in this blog is simple: Everpure Fusion gives infrastructure operators a unified, policy-driven control plane that enforces intent consistently — across provisioning, placement, compliance, topology, and now Kubernetes and virtualization. That foundation matters because autonomous storage operations do not start with AI. They start with structure. Topology groups encode where workloads belong. Presets encode how they should be configured. Everpure Fusion presets exposed as StorageClasses ensure Kubernetes environments follow the same rules as everything else. When that structure is in place, AI can recommend, optimize, and eventually act — because the context is already clean, trusted, and machine-readable. For storage admins, the shift is real: less time resolving incidents caused by placement decisions nobody remembers making, more time defining the intent that governs the fleet. Everpure Fusion is that foundation — built into Purity, not bolted on. Want to learn more about Everpure Fusion? Check out the following links to dive deeper: Join the Everpure Fusion Mastery Program to build expertise, complete hands-on activities and earn rewards. Sign up for a Fusion test drive to try it out on your own time. Check out more about Fusion product details. Watch our cool new Fusion demo videos. Read Everpure Fusion Datasheet152Views0likes0CommentsAccelerate 2026 - Part 2 - The Light Switch Test
Earlier, in Part 1, I wrote that the Everpure Accelerate 2026 opening keynote did not really feel like a storage keynote. My takeaway from day one was simple: Everyone wants your data. The bigger question is who owns the context. Day two answered a different question. If day one was about why the Enterprise Data Cloud matters, day two was about how customers are supposed to get there without turning it into another giant transformation project that sounds great on stage or in a boardroom and then dies somewhere between budget approval, staffing constraints, internal politics, and the next urgent outage. That is why the second keynote mattered. It was not trying to restart the vision. The vision had already been established. It was about turning that vision into something customers could actually use: a methodology, a blueprint, and a way to connect data architecture to risk reduction, efficiency, agility, modernization, and business outcomes. And then John Colgrove, Coz, did what Coz does. He simplified the whole thing. Not by making it smaller. By making it clearer. The phrase that stayed with me from his session was not a technical phrase. It was not Enterprise Data Cloud, Data Primacy, Fusion, data intelligence, or workload mobility, even though all of those ideas were underneath what he was saying. It was the light switch. Coz talked about walking into a room at home and turning on the light. You know exactly what is going to happen. It is simple. It is obvious. It works the way you expect it to work. Then he compared that to walking into a conference room at the office, where five people spend the first few minutes trying to figure out how to turn on the right lights, dim the screen area, wake up the display, connect the laptop, and make the audio work. Everyone has lived that moment. It is also a perfect way to explain what Everpure has been trying to do since the beginning. Make the complicated thing feel like the light switch. That may sound too simple for enterprise infrastructure, but I think it is exactly the point. The best infrastructure does not feel simple because the problem is simple. It feels simple because somebody did the hard engineering work to hide complexity without hiding control. That has always been part of the Everpure story. When Pure Storage first became known in the market, the message was not only flash performance. Performance mattered, of course. But the thing customers really felt was that the experience was different. The arrays were simpler. The upgrades were non-disruptive. The support model was different. Evergreen architecture was different. The idea that you could keep modernizing without the usual forklift pain was different. Over time, that simplicity moved from one array to more of the environment. Fusion extended the idea from a single system to a fleet. Policy, placement, automation, workload mobility, service levels, compliance, and lifecycle management started to move from device-by-device thinking toward something broader. Now, with the Enterprise Data Cloud, Everpure is trying to move that simplicity again. From array to fleet. From fleet to data. From data storage to data management. That was the thread both Nirav Sheth and Coz pulled through the keynote, and I think it connected day two back to day one in a very useful way. They made it clear that the move from Pure Storage to Everpure is not an abandonment of what got the company here. It is a continuation of the same journey. That matters because customers are rightfully skeptical when technology companies rebrand or expand their message. They wonder whether the company is moving away from the thing they trusted. They wonder whether the new story is strategy or just vocabulary. Coz addressed that directly. We are not abandoning storage infrastructure. We are going to keep building the best storage infrastructure we can. But we are also going higher, because to build better infrastructure, you have to understand more about the data above it. That is a founder’s version of the message. Less theater. More first principles. If you store data, you want to know what it is. You want to know how it will be accessed. You want to know how often. You want to know what it relates to. You want to know whether there are copies. You want to know whether those copies create risk. You want to know whether the rules are being followed. The problem, as Coz pointed out, is that nobody really knows the future. The infrastructure has to be built for agility. That word gets overused, but in this context it matters. Agility is the ability to change without breaking everything. It is the ability to move workloads non-disruptively. It is the ability to rebalance a fleet. It is the ability to modernize hardware without turning it into a migration event. It is the ability to adjust policies as risk changes. It is the ability to bring intelligence to data that already exists instead of forcing the business to start over. That is where the Enterprise Data Cloud story becomes more practical. And I personally think the Enterprise Data Cloud Success Blueprint was the clearest example of that. I liked this part because it moved the conversation away from “look at all these capabilities” and toward “here is why it matters to you” and “what outcomes are you trying to drive?” That is where a lot of technology conversations go wrong. We get excited about the architecture and forget that customers are not buying architecture for the sake of architecture. They are trying to solve business problems with limited people, limited time, limited budget, and increasing pressure from every direction. They are dealing with supply chain constraints. They are being asked to do more with the same team. They are trying to create VMware optionality without making a reckless move. They are modernizing applications while still running legacy workloads that cannot just disappear. They are dealing with cyber risk, ransomware, and minimum viable business recovery. They are being asked to support AI before the data foundation is ready. The blueprint framework organized those pressures into three simple categories: risk reduction, efficiency, and agility. That may seem obvious, but obvious is underrated. Risk reduction is not just a security feature. It is knowing whether your data is protected, whether your snapshot policies are aligned, whether you can recover the minimum viable business, whether sensitive data is duplicated everywhere, and whether compliance follows the data instead of living in someone’s spreadsheet. Efficiency is not just a density number. It is energy efficiency, automation, operational scale, fewer manual tasks, fewer migrations, and fewer people spending nights and weekends babysitting infrastructure that should be managing itself. Agility is not just modernization language. It is VMware optionality, container readiness, AI readiness, cloud flexibility, application mobility, and the freedom to make the next decision without being trapped by the last one. I think that is a much better way to have the conversation with customers. Not “Do you want this product?” But “Which business outcome are you trying to improve, and what is standing in the way?” The Red Hat and CSX discussion made that practical. When Eric Grabill from CSX talked about Positive Train Control, sensors along the tracks, safety requirements, and systems where a loss of data can affect train operations, the conversation moved from platform strategy into the real world. That is where infrastructure earns its keep. CSX has already moved a large portion of its applications to Kubernetes on OpenShift, but still has legacy VMs remaining. That is the real enterprise pattern. It is not containers or VMs. It is containers and VMs. It is cloud and on-premises. It is modern and legacy. It is AI coming next while everything else still has to run today. The Red Hat and Portworx conversation made the point that modernization cannot mean creating another disconnected stack. Customers need one operating model across VMs, containers, and eventually AI workloads. They need a practical transition path, not a big bang migration. They need data services that protect the applications, not just compute platforms that can host them. The St. Elizabeth Healthcare conversation made the same point in a more personal way. Charles Shepherd talked about joining St. Elizabeth in 1997, starting at the help desk, moving through Novell, GroupWise, backups, storage, and eventually becoming part of the team responsible for systems that support a healthcare environment that never really stops. What stayed with me was not only the technical story. It was the laptop on vacation. Anyone who has worked in infrastructure understands that detail. The laptop that comes with you just in case. The phone you keep checking because maybe something happened. The family event where part of your brain is still in the data center. The trip where you are physically present but operationally on standby. That is not a feature comparison. That is a life comparison. Charles said he recently was able to go to his niece’s graduation and not get called. That sounds small only if you have never been the person who always gets called. He also talked about more than one hundred hardware upgrades and more than one hundred fifty Purity upgrades without downtime. He talked about moving from older systems to modern ones without the traditional forklift migration pain. He talked about change boards becoming comfortable with upgrades during the day because the process had earned trust. That is the kind of customer proof that matters. It shows what the solution that was delivered gives back. It gives back time, trust and confidence. That connects directly to the light switch idea. Simplicity is not cosmetic. It is not just a better UI. It is not just fewer clicks. Simplicity changes what people can spend their time on. It changes what teams believe they can safely do. And it changes whether the infrastructure team is trapped maintaining the past or free to prepare for what comes next. Coz also said something important about time. This Enterprise Data Cloud journey is not a one-year story. It is not one product cycle. It is not done because it showed up in an Accelerate keynote. Coz described it as a journey that will take five to ten years, and even then, it will not really be done because the solution will keep improving. I appreciate that kind of honesty. So when a founder says this is a long journey, I believe that more than I believe a slide that says “seamless transformation” in large font. But I also think now is the right time for the journey to become possible. And Coz reminded us that the best version of this is not complexity with better branding. The best version is the light switch. Coz, in the most Coz way possible, reminded everyone that the goal is not to make enterprise infrastructure sound impressive. The goal is to make the hard things feel obvious. Like turning on the lights. I appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere108Views0likes0Comments
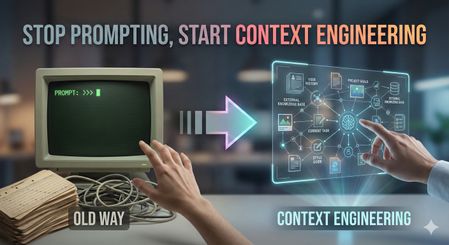
Stop Prompting, Start Context Engineering
This blog post argues that Context Engineering is the critical new discipline for building autonomous, goal-driven AI agents. Since Large Language Models (LLMs) are stateless and forget information outside their immediate context window, Context Engineering focuses on assembling and managing the necessary information—such as session history, long-term memory (embeddings, RAG indexes), and tool outputs—for the agent every single turn. The post asserts that storage, not the LLM or the prompt, is the primary performance bottleneck for AI at scale. The speed of the underlying storage architecture dictates the agent's responsiveness because it must quickly retrieve and persist context data repeatedly.260Views3likes0Comments