Recent Content
ActiveCluster for File Veeam Backup
Hello everyone :-) we recently got a Flasharray with the new "ActiveCluster for File" feature, which is pretty nice. We are trying to switch to Veeam. We are using VMware. I therfore created a Linux based Veeam Backup & Replication Server as well as linux based proxies in our vCenter. Backing up VMs via the hot-add transport mode works without any issues. The issue that we are facing is, how do we backup the NFS shares created from the "ActiveCluster for File"? Because Veeam sees the VMDKs from the VMs in the vCenter but doesen't see the NFS mounts from Everpure in the guest OS of the VM. My questions and thoughts are: Is it possible to create an physical Linux based on Veeam proxy and connected it to the Everpure FlashArray? According to this link, Everpure doesn't support the storage snapshot Integration feature https://helpcenter.veeam.com/docs/vbr/userguide/storage_system_requirements.html?ver=13 This is the Plugin I wanted to use with the physical proxy which is connected to the FlashArray https://www.veeam.com/kb4129 I can add the NFS Share into Veeam and create backjobs but how does it technically work? It uses the VBR Server as an proxy.. But is that the right way? How can I create Veeam backup jobs for NFS mounts (which are mounted on VMs in the vCenter, which Veeam doesn't see) provided by ActiveCluster for File ? How does a Veeam file share backup work technically and how should the recommended backup design be in this scenario? Thank you!SolvedActive Cluster for File
Hello everyone :-) I'm new to Active Cluster for File and I'm looking for some documentation or introductory material. I'd like to understand: How Active Cluster for File works How it is configured via the management interface General setup, requirements, and administration tasks If anyone can point me to official documentation, knowledge base articles, or deployment guides, I would really appreciate it. Thanks!SolvedMaximum IOPS
Hello! Sorry if this a little confusing, I am still fairly new to the storage array system! I am curious as to if there is a way to see the maximum IOPS allowed on my array. Context: We routinely perform updates to databases on multiple servers across the array and due to our previous SAN's limitations we are currently limiting the number of databases we update simultaneously. Looking at the dashboard I can see that there doesn't seem to be any large spikes in the IOPS while performing said updates, but was curious if there was an easy way for me to compare the numbers I'm seeing to the maximum allowed to try and get a metric of how good/bad the performance is. Thanks in advance!Solved58Views1like5CommentsFirst Preset and Counting
A bit routine, but this preset creates a volume to be used as a VMware datastore with a set regular size of 16GB. It also ensures "VMware Datastore" is in the volume name to quickly ascertain what the volume's use case is. Lastly, snapshots are taken every 6 hours and retained for 5-days. Create Regular Size 16GB Volume for a VMware Datastore w/6h5d Snapshots83Views5likes4CommentsActiveCluster for File Veeam Backup
Hello everyone :-) we recently got a Flasharray with the new "ActiveCluster for File" feature, which is pretty nice. We are trying to switch to Veeam. We are using VMware. I therfore created a Linux based Veeam Backup & Replication Server as well as linux based proxies in our vCenter. Backing up VMs via the hot-add transport mode works without any issues. The issue that we are facing is, how do we backup the NFS shares created from the "ActiveCluster for File"? Because Veeam sees the VMDKs from the VMs in the vCenter but doesen't see the NFS mounts from Everpure in the guest OS of the VM. My questions and thoughts are: Is it possible to create an physical Linux based on Veeam proxy and connected it to the Everpure FlashArray? According to this link, Everpure doesn't support the storage snapshot Integration feature https://helpcenter.veeam.com/docs/vbr/userguide/storage_system_requirements.html?ver=13 This is the Plugin I wanted to use with the physical proxy which is connected to the FlashArray https://www.veeam.com/kb4129 I can add the NFS Share into Veeam and create backjobs but how does it technically work? It uses the VBR Server as an proxy.. But is that the right way? How can I create Veeam backup jobs for NFS mounts (which are mounted on VMs in the vCenter, which Veeam doesn't see) provided by ActiveCluster for File ? How does a Veeam file share backup work technically and how should the recommended backup design be in this scenario? Thank you!Azure Red Hat OpenShift with Everpure Cloud
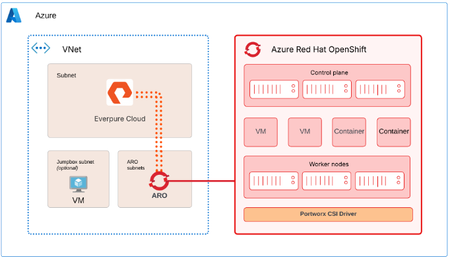
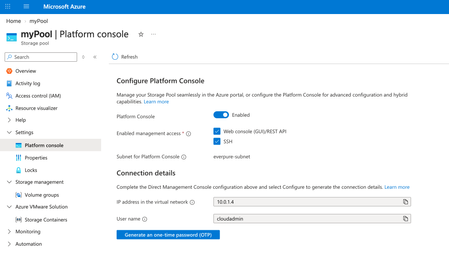
Azure Red Hat OpenShift (ARO) can use Everpure Cloud for persistent block storage, for VMs and containers. Both Everpure Cloud options - Everpure Cloud Azure Native and Everpure Cloud Dedicated are certified with ARO, and the cluster-side setup is nearly identical for both. This post covers the architecture, configuration sequence, and the checks that catch most problems early. Two storage options, one ARO procedure Everpure Cloud Dedicated is an array you deploy into your Azure subscription. Everpure Cloud Azure Native is delivered through the Azure portal, where you deploy a Storage Pool into a delegated subnet in your own Azure Virtual Network. With Azure Native you manage the array through the Platform Console, which gives you the Purity GUI, REST API, and CLI. It's disabled by default and you enable it per Storage Pool. With Dedicated you use the Purity interface directly. Architecture ARO provides the compute platform for VMs and containers. The Storage Pool (or Dedicated array) provides persistent block storage, and PX-CSI connects the ARO worker nodes to it to provision and manage volumes. The solution uses two paths. Management path. PX-CSI talks to the Purity management endpoint to create and manage volumes. With Azure Native, the Platform Console is how you get that endpoint. Data path. iSCSI traffic flows between the ARO worker nodes and the storage over the Azure virtual network. Deploy the ARO cluster and the storage in the same Azure region and virtual network. Put ARO in its dedicated subnets and the Azure Native Storage Pool in a separate subnet delegated to the Everpure Cloud service. A jump host VM is optional, and it's handy for reaching both the cluster and the Platform Console. For the data path, keep it short and boring. Everpure's field guidance is no virtual network peering and no user-defined routes or virtual appliances between the workers and the storage. Walkthrough Enable the Platform Console (Azure Native only) In the Azure portal, open the Storage Pool, go to Settings, then Platform console, and set it to Enabled. Pick the access methods you need (GUI and REST API, and optionally SSH) and select Configure. Copy the management IP address and the cloudadmin user name from Connection details, then generate a one-time password. It's shown once, so copy it before you close the dialog. Browse to https://<management-IP-address>, sign in as cloudadmin, and create a local administrator account right away. cloudadmin is only for first access. Make sure your Network Security Group allows TCP 80 and 443 for the GUI and REST API, and TCP 22 if you enabled SSH, and limit those rules to your management addresses. Prepare the OpenShift cluster Log in to the cluster from your Azure VM, create the Portworx namespace, and turn on user workload monitoring so OpenShift can scrape Portworx metrics. RESOURCE_GROUP="<ARO cluster resource group name>" CLUSTER_NAME="<ARO cluster name>" ADMIN_PW=$(az aro list-credentials --name $CLUSTER_NAME \ --resource-group $RESOURCE_GROUP --query "kubeadminPassword" -o tsv) API_URL=$(az aro show --name $CLUSTER_NAME \ --resource-group $RESOURCE_GROUP --query "apiserverProfile.url" -o tsv) oc login $API_URL -u kubeadmin -p $ADMIN_PW oc create namespace portworx apiVersion: v1 kind: ConfigMap metadata: name: cluster-monitoring-config namespace: openshift-monitoring data: config.yaml: | enableUserWorkload: true Apply that with oc apply -f. Then, in the ARO web console, go to Ecosystem -> Software Catalog, search for Portworx Enterprise, and install it into the portworx namespace. Don't create a StorageCluster yet. It comes after the worker nodes and the credentials are ready. Configure worker nodes PX-CSI attaches volumes over iSCSI, so the workers need multipath and udev settings that match Everpure's Linux recommendations. Create a multipath.conf with "user_friendly_names no" and "find_multipaths no" (each controller has a single path), and a udev.rules file with the recommended queue depth and tuning. The same two files go on every worker. Base64-encode both with base64 -w0, and wrap them in a MachineConfig. apiVersion: machineconfiguration.openshift.io/v1 kind: MachineConfig metadata: name: 98-worker-pure-multipath labels: machineconfiguration.openshift.io/role: worker spec: config: ignition: version: 3.2.0 storage: files: - path: /etc/multipath.conf mode: 0644 contents: source: data:text/plain;charset=utf-8;base64,<base64-multipath-conf> - path: /etc/udev/rules.d/99-pure-storage.rules mode: 0644 contents: source: data:text/plain;charset=utf-8;base64,<base64-udev-rules> systemd: units: - name: iscsid.service enabled: true - name: multipathd.service enabled: true oc apply -f 98-worker-pure-multipath.yaml oc get mcp worker -w The Machine Config Operator merges this into the worker pool and rolls it out one node at a time, cordoning, draining, applying, and rebooting each. Wait until the worker pool shows Updated as True. Give PX-CSI access to the array Create a user with the Storage Admin role (or an equivalent tenant-scoped role if you use secure multi-tenancy) and generate an API token for it. On Dedicated, that looks like this: pureadmin create --access-policy storage_admin px-pure-user ssh px-pure-user@<array-management-IP> pureadmin create --api-token On Azure Native, do the same from the Platform Console. Next, describe the array in a pure.json file and load it into a secret in the portworx namespace. { "FlashArrays": [ { "MgmtEndPoint": "<management-endpoint-IP>", "APIToken": "<api-token>" } ] } oc create secret generic px-pure-secret \ --namespace portworx \ --from-file=pure.json=/path/to/pure.json The secret name has to be px-pure-secret, because PX-CSI looks for that name by default. Generate and apply the PX-CSI StorageCluster Open Portworx Central, go to Spec List, Create New Spec, and choose PX-CSI. Pick a supported release (26.1.x in the documented setup), set the namespace to portworx, choose Azure Red Hat OpenShift (or generic OpenShift, since the YAML is valid for both), set the access type to Block Storage and the SAN type to iSCSI, and leave the rest at defaults. Download the manifest and apply it. oc project portworx oc apply -f px-csi-storagecluster.yaml Watch the StorageCluster in the console until it reads Running. During creation PX-CSI reads px-pure-secret, parses pure.json, and uses those endpoints and the token to manage volumes. Verify and use oc get pods -n portworx | grep -E 'px|pure-csi' oc get storagecluster -n portworx All PX-CSI pods should be Running and the StorageCluster should report Online or Running. oc get sc PX-CSI creates several default px-pure-csi-* StorageClasses, pick your PX-CSI StorageClass with backend: pure_block or create your own. Create a PVC or VM against the class, bind it to a pod, and you'll see the volume appear in the Platform Console or Purity UI. When something doesn't work Start at the bottom of the stack and work up. Connectivity. From a worker, run iscsiadm discovery against the array endpoint, and check that initiator names are unique. Node configuration. Confirm multipath.conf and the udev rules landed on every worker, and that iscsid and multipathd are running. PX-CSI. Check that the pods are Running, the StorageCluster is Online, and px-pure-secret exists in the same namespace as the operator. Connect to workers oc get nodes oc debug node/<worker> -T -- chroot /host Check services (ensure iscsid and multipathd services are enabled and running on workers) and check config files are updated. cat /etc/multipath.conf cat /etc/udev/rules.d/99-pure-storage.rules Resources Everpure Cloud Dedicated with Azure Red Hat OpenShift and PX-CSI Deployment GuideEverpure Cloud Azure Native: A closer look at the Platform Console
In this post, I thought to take a closer look at the Platform Console for Everpure Cloud Azure Native. It provides access to a Storage Pool through the familiar Purity GUI, REST API, and CLI, giving storage administrators an additional way to handle advanced configurations. The important distinction here is that the Platform Console complements the Azure-native experience. It does not replace it. Azure remains the primary interface for day-to-day management, while the Platform Console is intended for specific tasks that Azure does not expose. What does it add? Let's start with the practical use cases. Storage configuration outside Azure Resource Manager The Platform Console allows you to create and manage Purity resources such as standalone volumes, hosts, host groups, protection groups, and snapshot policies outside Azure Resource Manager (ARM). This gives administrators more flexibility when a supported storage workflow requires objects or settings that are not available through the Azure-native interface. For teams already familiar with Purity, it also means working with interfaces they already know. Snapshot management For resources managed through the Platform Console, you can create manual snapshots, configure snapshot schedules, and restore snapshots. The benefit here is control over when recovery points are created and how snapshot protection is configured for those resources. However, it is important to keep resource ownership clear when using both Azure and the Platform Console. More on that below. Automation and monitoring Supported storage workflows can be automated through the REST API, SDKs, or CLI. Local users can generate API tokens for REST access and upload SSH public keys for command-line access. Array metrics can also be collected through the OpenMetrics endpoint using a local-user API token. This provides a way to collect storage metrics for monitoring workflows, alongside the ability to script supported administrative tasks rather than perform each operation manually. Getting access One Platform Console is available per Storage Pool. It is disabled by default and must be explicitly enabled from Azure. In the Azure portal, open the Storage Pool and navigate to Settings → Platform console. Web console and REST API access are enabled together, while SSH can be enabled independently. Once the configuration is applied, the portal provides the management IP address and the pre-created cloudadmin user name. Initial access uses a one-time password generated from Azure. The cloudadmin account is temporary: it’s reserved for this first sign-in and removed when the password expires. Generating a new password recreates it. After signing in, create your own local users for ongoing administration. The management interfaces use the same delegated subnet as the storage data path. Because of that, use Network Security Groups to restrict management access to the administrative hosts that need it. Application VMs do not need Platform Console access to consume storage. Two interfaces, but not interchangeable resource management This is probably the most important operational consideration. Resources created through Azure are tracked in Azure. Resources created through the Platform Console exist on the array, but are not visible to the Azure-native interface. There is also no hard isolation between the two. Changing or deleting an Azure-created resource through the Platform Console can leave Azure with stale information, causing subsequent operations to fail or report an incorrect state. A practical rule is therefore: Manage the lifecycle of Azure-created volumes and volume groups through Azure. Use the Platform Console for resources created there, or for specifically documented advanced configuration. Keep a record of resources created outside Azure so they are not overlooked during decommissioning. The summary The Platform Console adds flexibility where the Azure-native interface does not expose a supported storage operation. Familiar Purity tools, snapshot management, automation, and access to array metrics give administrators more options for advanced workflows. The key is to use those options deliberately: keep routine management in Azure, limit console access to the people and systems that need it, and maintain clear ownership of resources across the two interfaces. For the supported workflows, access requirements, and configuration instructions, refer to the Platform Console for Everpure Cloud Azure Native KB.27Views3likes0CommentsUsing AI to Help Manage your Data Infrastructure (Ask Us Everything Recap)
AI is showing up everywhere in IT. But for storage admins, the real question is whether it can actually help save time and make managing infrastructure easier. That was the focus of our latest Ask Us Everything, where Everpure experts Anand Madhavan (Director of Product Management), Ameerul Shah (Product Manager) and Russell Cagle (Tech Lead), fielded questions from the Everpure Community about putting AI to work in real-world storage environments. What can Pure1 AI Copilot actually do? The discussion started with the basics: How was this tool designed to help IT professionals? Anand described it as the next step in Everpure’s long-running focus on simplicity. Instead of searching documentation, digging through multiple screens, or remembering commands, IT folks can ask questions in natural language. Pure1 AI Copilot uses information from Everpure knowledge sources along with data about your own fleet to help find the answers you need. That means you can ask important things like: What’s the latency on this array? Which arrays need an upgrade and why? ? What alerts should I be concerned about? No deep knowledge is needed to get actionable answers. Importantly, Pure1 AI Copilot is currently focused on finding answers, and giving you options. It can reason out a problem and recommend what to do next, but it doesn’t simply start executing commands. And this is by design: Everpure’s approach separates AI reasoning from deterministic execution, so there aren’t any surprises. Pure1 AI Copilot works with capabilities such as Workflow Orchestration and Everpure FusionTM Presets to automate tasks, so you stay in control. Can AI really make troubleshooting faster? Consider that familiar question: “My array was slow last night. What happened?” Traditionally, answering it might require piecing together telemetry, documentation, CLI information, alerts, and possibly opening a support case. Triage Assistant is designed to work through that investigation process for you—checking alerts and upgrades, looking for latency spikes, identifying busy volumes, and then providing evidence and recommended next steps. Ameerul shared that an investigation that might otherwise stretch across a day or two could potentially produce useful answers through Copilot in a matter of minutes. That’s the kind of AI benefit storage teams can appreciate: less hunting for information and more time spent on solving problems. What if I want to use my own AI assistant? This is where the conversation turned to MCP servers. Russell explained that the Pure1 Manage MCP server gives compatible AI assistants (like Claude, Cursor, etc.) access to Pure1 Manage data. That opens some intriguing possibilities because storage rarely operates in isolation. When asked whether Pure1 AI Copilot could understand environments beyond Everpure, such as VMware and Azure, the answer highlighted the bigger opportunity behind MCP. That is, connecting Everpure data with MCP servers for other parts of your infrastructure, so an AI assistant can correlate information across storage, virtualization, networking, observability, and other systems. Instead of becoming yet another management silo, data on Everpure storage can become part of the AI tools that IT admins are already using. Do I need an MCP server for every array? For admins managing larger environments, one attendee had a very practical question: If I have 18 arrays, do I need 18 MCP servers? No—and that answer gets to an important difference in Everpure’s approach. With Everpure Fusion, the focus is the fleet rather than individual arrays, so its MCP server can work across a fleet containing multiple FlashArray and FlashBlade systems. Configure it once rather than treating every array as a separate management island. And that extends into monitoring fleets—rather than logging into dozens of systems and assembling the picture yourself, Pure1 AI Copilot can help provide a fleet-wide health view and then let you drill into systems requiring attention. What’s next? The panel of experts discussed everything from future support for OpenStack and vCenter correlation, to extending into replication analysis and write capabilities The takeaway was simple: AI isn’t being positioned as a replacement for the storage admin. Think of it as a “high-performing teammate”: It can help find you information, investigate problems, explain unfamiliar environments, accelerate onboarding, and bring fleet-wide storage intelligence into the AI tools you already use. For IT teams continually being asked to “get more done with less”, that may be the most useful application of AI of all: spending less time managing the complexity of storage and more time managing the data that matters. Check out this and all our other Ask Us Everything sessions. And, keep the conversation going by jumping into the Everpure Community.26Views2likes0CommentsNDU replacement/upgrade
Hello everyone, I have a question I do not find an answer. I have found these two commands that may or may not do the same thing, but can't confirm anywhere purewes controller setattr --verify-array <array_name> ct0 --mode secondary and puredb run giveback --safe <---- run from ct0 Supposedly, they both set ct0 as secondary, therefore ct1 as primary. But, is it? What is the difference? ThanksRecommended Beginner Recipes
Greetings, I am just starting my Pure1 Workflows journey, and wanted to know some "Recipe ideas" others would recommend for beginners in order to get the hang of how to create them before progressing onto more complex ones? Example, setting up monitoring, provisioning volumes, etc...185Views1like5Comments
Tags
Featured Content
AI is showing up everywhere in IT. But for storage admins, the real question is whether it can actually help save time and make managing infrastructure easier. That was the focus of our latest Ask U...
13 days ago Hey Everpure Community — We're Sarah and Pranav, a user researcher and designer on the Everpure team working to make Pure1 and Evergreen//One subscriptions work better for the people who rely on ...
5 months ago