Data Intelligence Live: Know Your Data Before Your Agents Do
November 17 | Register Now Most teams are being asked to put enterprise data in front of AI agents without knowing what that data contains, who owns it, or who can reach it. In this live session, we start with a data estate that looks ordinary (file shares, databases, a stray JSON export) and run Everpure Data Intelligence against it in real time. You'll watch discovery, classification, and context build up on screen, including the moment a single innocuous file turns into thousands of regulated data elements. Then we close the loop: label at the source, trigger a policy action, and let an AI assistant ask the estate which data is safe to use. Key takeaways: Discovery at the source: How Everpure Data Intelligence connects to structured, unstructured, cloud, on-prem, and mainframe sources and classifies content in place, without moving or copying data Classification to context: What the knowledge graph adds beyond a sensitivity tag (owner, access, relationships, policy) and why that's what AI needs to trust a dataset Metadata-only triage: How the new Everpure Data Intelligence File Edition surfaces age, freshness, and ownership signals across shares before any content scan Intelligence to action: Writing labels back to native metadata, triggering alerts and workflows, and querying findings in plain language Register Now!24Views0likes0CommentsWhen AI Starts Acting, Who Controls What It Can Do?
There is a new piece in The Data Wire with Richard Galvez and Andrea Moccia of Options Technology on what changes when AI begins to act. CyberArk’s 2025 identity-security research found that machine identities outnumber human identities 82 to 1, and 42% of them carry privileged or sensitive access. Agents will likely inherit some of that access. For a bank, the question may be less what an agent was asked to do and more what it could discover and do with the access it already has. Is that question being asked at your institution before agents reach production?20Views2likes0Comments
The Data Leadership Forum on AI - Get the payoff AI promised
October 28, 2026 3:30 PM ET | 12:30 PM PT 2:00 PM GMT | 3:00 PM CET Every organization is racing to deliver value from AI—yet most are hitting the same wall: the data. Gartner predicts 60% of AI projects will be abandoned because they aren’t supported by AI-ready data. A new approach is needed—one built on data primacy, not application-centric fragmentation—to close the growing gap between AI's promise and its payoff. Join data and AI leaders for a candid reckoning with what's really standing between potential and production: data readiness, governance, and true intelligence about your entire data estate. Hear it straight from the people shaping the conversations. Agenda The AI Value Gap — Why AI Isn't Delivering the Business Value We Expected Yet Bernard Gavgani Senior Advisor to General Management for Innovation, former Group CIO, BNP Paribas Ashish Gupta General Manager, Data Management, Everpure Data Primacy — The Missing Link Between AI Potential and Business Value Charles Giancarlo Chairman & CEO, Everpure Data Leader Perspective — A Tested Approach to Bring AI to Production Chris Tambos Executive Advisor, Data & AI, Everpure, former leader of Data & AI for Fortune Brands. Lynn Lucas Chief Marketing Officer, Everpure Register Now39Views0likes0CommentsWaddle on, federal friends. 🐧
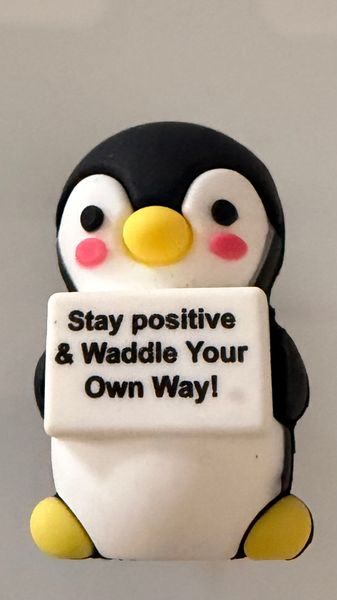
We know the rush of federal busy season is behind us, but the work doesn’t stop. My kids gave me this little toy from their school's "Friday Shop" and it made me smile. Hope this spreads some encouragement for the week ahead. How are our federal folks doing? Drop a comment below. 👇21Views0likes0Comments
How much more inference could you get from the GPUs you already have?
As inference workloads grow, it’s not always the GPU compute that becomes the bottleneck. Recomputing tokens of a known context vs reloading from KV cache can take up a lot of GPU bandwidth and limit how many workloads you can run in a given amount of time. That’s one of the things we’ve been working on with PureKVA, reusing KV cache so you can get more out of the GPU capacity you already have. With v1.2, we’ve also added a 3-tier memory architecture, TurboQuant KV cache support, along with things like multi-tenancy and storage isolation. We’re seeing some of the benefits internally as well, particularly around reducing throttling when usage spikes. Curious what others are seeing. Is GPU compute the bigger constraint for you, or GPU memory?38Views1like0CommentsAI Can Write Your Data Platform. Who’s Going to Keep It Running?
AI can write SQL, generate pipelines, build infrastructure, create database migrations, and even diagnose production problems. But what happens when it confidently does the wrong thing? As AI becomes part of how we build and operate modern data platforms, the key question is no longer just, “Can AI generate this?” It’s whether we can trust the result, deploy it safely, observe what happens, and recover when things go wrong. Join Hamish Watson for a practical session on bringing AI-assisted development into production reality. Drawing on experience across SQL Server, cloud platforms, Databricks, and database DevOps, Hamish will explore how version control, CI/CD, automated testing, drift detection, observability, and governance help keep AI-generated changes safe and recoverable. The session will include practical examples, lessons learned, and a live demo. And, because live demos rarely go exactly to plan, there may even be a surprise or two. AI might be able to write your data platform. The more important question is: who’s going to keep it running? Register for the session27Views0likes0CommentsCurious about home lab or on-prem models
A friend told me to stop trying to squeeze local models onto my gaming PC and just buy the right box. So I did, and hoping not to regret it. Ordered a BOSGAME M5. Ryzen AI Max+ 395, 128GB unified memory, up to 96GB of it assignable to the GPU. Size of a hardcover book. I've been running LM Studio with models off Hugging Face. Fine for small stuff. So, people who've actually done this at home... What are you running besides LM Studio? What hardware did you buy and regret? Where does unified memory fall apart in practice? One ask. Human answers only. I can already ask a model what a model thinks. I want to know what broke in your house at 11pm on a Tuesday.1KViews5likes5CommentsPureKVA v1.2 now GA
Pure KVA (Key-Value Accelerator) is an enterprise AI solution designed to speed up large language model (LLM) inference by storing and reusing precomputed attention key-value states. Want to learn more about PureKVA and what it can do for you? Check out the link here for more information and how to get started: https://support.everpuredata.com/r/pure-kva/pure-kva-overview-and-architecture Version 1.2 is now available for download. Check out the highlights of what's new below. What is new in v1.2 PureKVA v1.2 adds the following capabilities: Containerized deployment in Openshift/Kubernetes S3 and S3overRDMA support Multi-tenancy with storage isolation support Three-tiered memory architecture for improved performance Nemotron model support PureKVA now supports offloading TurboQuant-quantized KV caches for vLLM. Get v1.2: https://support.everpuredata.com/r/pure-kva/pure-kva-release-v1-2131Views0likes0CommentsAI & Data Discovery
Would love your take on this GovLoop piece from my colleague, JimWeaver (former WA and NC CIO, ran NASCIO). One line that really stuck out to me: in a legislative hearing nobody asks if the model works. They ask where the data came from and who touched it. His first AI move in North Carolina wasn't buying a model. Instead, it was about data discovery. What do we have, where does it live, how clean is it. Has anyone here done similar data discovery efforts? How long did it actually take, and what surprised you? https://www.govloop.com/community/blog/building-an-ai-ready-data-foundation-for-state-and-local-government/148Views2likes1CommentOne Year of “Ask Us Everything”: John “Coz” Colgrove on Everpure’s Past, Present, and Future
A special Ask Us Everything anniversary conversation with Everpure cofounder John “Coz” Colgrove explores Everpure’s origins, technical innovations, AI, and the future of data management.48Views0likes0Comments