Why Enterprises Still Need an Ontology
Data Under Pressure User Group Join us for a session with Argenis Fernandez, Distinguished Engineer at Nike, on Why Enterprises Still Need an Ontology. 📅 September 23, 2026 | 9:00 AM PST 🔗 Register: https://purestorage.zoom.us/webinar/register/WN_sK9Bkfz6QrmXxXKzLBzTCw#/registration What you'll get: Why talking the same language across your org matters A walk through the four-layer enterprise data stack A 4-cell rubric for evaluating your own ontology layer Don't miss this one if you're thinking about data architecture, governance, or how to get teams speaking a common language.61Views1like0Comments
The Art of Sizing: How to Size an Exadata Migration Without Overbuying Storage
If you are moving Oracle databases off Exadata, the first sizing mistake is usually looking at only one database at a time. Exadata is not a traditional Oracle architecture. Some of the work that would normally happen on the database host is performed by the storage cells, including capabilities such as Storage Indexes, Smart Scan, and—depending on the database version and workload—vector offloading. That changes what the storage numbers mean. A successful migration therefore needs to answer two different questions: How much I/O is the current Exadata environment really performing? Which parts of that work will move to the database hosts, change shape, or disappear when the architecture changes? This installment of The Art of Sizing walks through a practical way to answer both questions. Why Exadata sizing is different In a conventional Oracle environment, it is common to begin with the database-level system statistics and identify the read and write workload for that database. That is still useful on Exadata, but it is not enough. Exadata is often a consolidated platform running multiple databases across multiple storage cells. The migration target must be sized for the estate as a whole, not just for whichever database happens to be easiest to measure. The other difference is architectural: Exadata reports include physical work performed by the cells. That work can include processing that a non-Exadata design may need to perform elsewhere. The implication is simple: Do not copy an Exadata number directly into a replacement-storage calculator and assume the result is equivalent. First, understand what the number includes. Then normalize it for the target architecture. Start with the familiar metrics—but use the global view For a normal Oracle workload, the starting point is the System Statistics (Global) view. The key measurements are: Read IOPS: physical read total IO requests Write IOPS: physical write total IO requests Read MB/s: physical read total bytes Write MB/s: physical write total bytes These measures establish the workload profile, but a per-database view can hide the scale of a consolidated Exadata environment. Figure 1: The Global Activity Statistics view provides the starting point for reading Oracle read and write activity. The detailed statistics show the specific physical-read and physical-byte measures that should be carried into the analysis. Figure 2: Example physical-read measures from the global statistics output. The important word here is global. If Exadata is hosting several databases, collect the workload across the full environment. A replacement platform must be able to absorb the combined demand, including concurrent peaks that may not be visible when databases are reviewed independently. Use the Exadata AWR Global RAC report to see the platform as a whole The Exadata AWR Global RAC report is valuable because it brings the consolidated environment into view. It shows the disk types, cell counts, disk counts, IOPS, and bandwidth associated with the Exadata storage layer. In the example from the source report, the cells are performing approximately: 615,244 IOPS 28,899 MB/s Those values come from the F/6.2T and H/20.0T disk groups shown in the report: 404,115 IOPS plus 211,129 IOPS equals approximately 615,244 IOPS 24,297 MB/s plus 4,602 MB/s equals approximately 28,899 MB/s Figure 3: Example Exadata storage-cell performance summary. These are useful sizing inputs, but they are not automatically the final requirements for the migration target. They describe the physical work being performed inside the Exadata architecture. That distinction matters because Exadata is doing more than simply storing blocks. Account for the work Exadata is doing for you When you leave Exadata, some of the platform behavior may need to be reproduced through database design, host resources, or application changes. The exact impact depends on the workload, database version, SQL mix, and target architecture, so the assessment must be validated with the DBA and application teams. Exadata capability or behavior Migration sizing question Storage Indexes Will equivalent filtering be provided by indexes, partitioning, clustering, or SQL changes? Smart Scan Will more data be returned to the host because the target platform does not perform the same cell-side filtering? Vector offloading Where will vector-related processing occur, and what CPU, memory, and I/O will it require? Consolidated storage cells Will the target platform handle the same concurrency and peak overlap across all databases? Large SGA requirements Does the target need additional host memory to preserve cache behavior and avoid turning cell-side efficiency losses into repeated reads? Table and index layout Do large tables need new indexes, partitioning, or access-path changes to deliver comparable performance? This is the part of the migration that is easiest to underestimate. The goal is not merely to reproduce the observed Exadata I/O. The goal is to understand the work behind that I/O and decide where it will run after the migration. Normalize ASM redundancy before sizing capacity The Exadata summary also shows how much storage is allocated and used through ASM. This is where capacity can be overstated if the redundancy model is carried into the new architecture without question. The source example uses ASM High Redundancy. In ASM, that means the database data is stored with three copies. If the target storage platform supplies its own protection and the design uses ASM External Redundancy, the database layer may need only one logical copy. Figure 4: Example ASM disk groups with High Redundancy and their allocated and used capacity. As a first-order capacity normalization, moving from three ASM copies to one logical copy reduces the ASM-replicated requirement by approximately 66.7 percent. For example, 600 TB represented under a three-copy ASM model could correspond to roughly 200 TB of logical database data before adding target-platform protection, snapshots, growth, recovery copies, and operational headroom. That is not a universal storage-sizing answer. It is a normalization step. Before using it in a purchase or design, confirm: Whether External Redundancy is appropriate for the target architecture How the storage platform protects data and handles failure domains Whether the design includes snapshots, replication, backup staging, or disaster recovery copies How much free space and growth headroom the environment requires Whether the capacity numbers are raw, usable, allocated, or actually consumed The key lesson is that database redundancy and storage redundancy should be evaluated together. Counting both without understanding the division of responsibility can lead to buying protection twice. Do not reduce performance by the same percentage automatically It is tempting to apply the same 66.7 percent reduction to IOPS and MB/s because the ASM model moves from three copies to one. That can be a useful initial hypothesis, but it is not a guaranteed performance result. Read and write behavior can change differently. Exadata cell processing may be removed. Host-side indexes or partitioning may add work. The target storage platform may also use a different protection scheme, data-reduction method, caching model, or concurrency profile. A better approach is to use the Exadata numbers as a measured baseline, then build a target model with explicit assumptions: Baseline physical read and write IOPS Baseline read and write bandwidth Peak and average behavior across the full database estate Expected change in host-side processing Expected impact of indexes, partitioning, and larger SGA requirements Target protection and redundancy model Growth, recovery, and availability requirements That model gives the migration team something it can test instead of a single inflated number or an overly optimistic discount. A practical Exadata migration sizing workflow The process can be summarized in six steps: Collect the Global RAC and Exadata AWR reports for the full environment. Record average and peak IOPS, bandwidth, storage utilization, disk types, and database concurrency. Separate database workload from Exadata cell-side processing and identify what may move to the hosts. Normalize ASM redundancy so database copies are not counted twice with storage protection. Add target-specific requirements for CPU, memory, indexes, partitioning, snapshots, replication, recovery, and growth. Validate the model with short-window performance data and a representative migration or proof of concept. The first four steps create the sizing baseline. The last two turn that baseline into a design that can survive real workloads. The sizing lesson Exadata migration sizing is not a matter of copying the largest number from an AWR report into a storage proposal. It is an exercise in separating three things: The work the current environment is performing The protection and redundancy that are being counted today The work and protection the target architecture will need tomorrow In the example discussed here, the Exadata cells show roughly 615,244 IOPS and 28,899 MB/s, while the ASM configuration indicates High Redundancy with three copies of the data. Those are important facts, but they are starting points—not automatic target requirements. The most reliable design is the one that measures the whole estate, understands the Exadata features behind the measurements, removes duplicated redundancy, and then adds back the host, protection, recovery, and growth requirements of the destination platform. That is the art of sizing an Exadata migration: not buying for the biggest number, but understanding what the number actually represents. Final thought When an Exadata migration is undersized, the problem usually appears after the architecture is already difficult to change. When it is oversized, the organization pays for capacity and performance that may never be used. The better path is disciplined normalization. Measure Exadata as a consolidated system. Identify which work will move. Separate database redundancy from storage protection. Then size the target for the workload you are actually building—not the architecture you are leaving behind. That is how sizing turns a migration estimate into an engineering decision.56Views0likes0Comments
Actionable Assessments: Prepare Your Infrastructure for Oracle 26ai
August 20 | Register Now As organizations adopt Oracle AI Database 26ai with capabilities like AI vector search, understanding whether their existing data infrastructure can support these new workloads becomes increasingly important, while keeping costs under control. Join us as we explore how to analyze peak workload concurrency, optimize storage redundancy, and map advanced feature dependencies. Attendees will walk away with an actionable framework for evaluating their own environment, including access to a complimentary, privacy-first Everpure readiness assessment to help automate the planning process. Key takeaways: See your true workload and capture a consolidated, hour-by-hour view of peak demand. Crush storage bloat and learn how real-world environments are safely shrinking their storage footprints. Learn how to align infrastructure for active features like TDE, HCC, and Smart Scan without over-buying hardware. Secure your assessment and get exact sizing recommendations. Register Now!59Views0likes0CommentsThe Art of Sizing: The Seven Signals That Help Decide Oracle 26ai Readiness
The Art of Sizing — Series Categories: Databases · Oracle · AI and Machine Learning By Thomas Stutesman, Principal Field Solutions Architect, Everpure A migration readiness scorecard turns raw Oracle AWR telemetry into seven plain-language signals — and shows you exactly where a lift-and-shift would carry yesterday's problems into tomorrow's platform. The migration everyone is planning for Across the industry, many organizations are now looking to move to Oracle AI Database 26ai. The release promises autonomous efficiency, AI-driven insight, and native vector search — but for most teams the path forward is clouded by one uncomfortable question: is our current infrastructure sized for tomorrow, or are we carrying the weight of yesterday's inefficiencies? The 26ai Migration Readiness scorecard is one of the helpful tools Everpure has created to make that migration easier. It takes the telemetry you already have — your Oracle Automatic Workload Repository (AWR) reports — and translates it into a clear, consistent read on where each database stands, so you move with evidence instead of assumptions. This is the first idea in our Art of Sizing series: for a decade, cheap flash and fast cores let us over-provision and "throw hardware at it." Oracle 26ai — with real vector workloads and a hardware market where components cost more and take longer to arrive — ends that era. Disciplined sizing is back, and it starts with reading the right signals. What the scorecard shows Point the assessment at an estate and it produces a single view: every database, scored across seven signals, rolled up into a combined readiness score. In one illustrative example across eight databases, the combined readiness score was 118 out of 168 — with 0 Ready, 7 Caution, and 1 Risk. None were a clean lift-and-shift: seven needed validation and tuning, and one needed remediation before it could move. Each database is scored across the seven signals with a simple traffic light, and the lights roll up into a score out of 21 — seven signals, three points each: Ready — 3 points — inside the healthy threshold Caution — 2 points — worth validating Risk — 1 point — attend to before you move A score of 18–21 is favorable, 13–17 means review needed, and below 13 flags remediation. Think of it as a current-state indicator that tells you where the risk concentrates — not a migration certification. A red flag doesn't mean "cannot migrate." It means the problem will follow you into 26ai — or get worse — if you size the new environment from the old box instead of from the evidence. The seven signals, one by one These are the value items to worry about when sizing for and moving to 26ai. For each, here is what it reads from AWR, why it drives your target design, what a red is telling you, and how Everpure helps you act on it. Signal 01 — System Capacity Reads DB Time against available CPU cores, average active sessions, and host CPU pressure. This sets the compute floor for the target and drives per-core Oracle licensing — size to the old ceiling and you inherit the old bottleneck. On top of that, 26ai's vector and embedding work adds fresh CPU demand. Red means: the source is already CPU-bound; moving as-is relocates the constraint. You need real headroom, not a like-for-like footprint. How Everpure helps: the assessment reports peak (not averaged) CPU demand per database and translates it into a right-sized core count — so the target is provisioned for the real workload plus deliberate headroom, and licensing is planned rather than guessed. Signal 02 — SQL & Parse Reads hard-parse rate, literal (non-bind) SQL, library-cache and cursor-sharing behaviour. 26ai changes optimizer behaviour, so heavy hard-parsing burns CPU, pressures the shared pool, and invites plan regressions on the new release. Red means: application-level SQL that will keep burning CPU or regress on cutover. Plan-stability work (SQL Plan Management, baselines) and shared-pool sizing belong before the move. How Everpure helps: because the assessment looks at the whole estate, not one instance, it surfaces shared SQL/parse patterns across databases — so one remediation effort (often "add bind variables") protects many migrations and lowers the CPU you have to size and license for. Signal 03 — Wait Profile Shows how DB Time splits across CPU, I/O, concurrency, and commit/log waits. It tells you what kind of bottleneck you are actually sizing for — a commit-bound database and an I/O-bound one need very different target designs. Red means: DB Time is dominated by a problematic wait (log file sync, buffer busy, latch/enqueue). Sizing CPU or storage without addressing it just moves the pain. How Everpure helps: Everpure maps the dominant wait class to the right lever — low, predictable write latency on FlashArray for commit/log waits; CPU or memory changes for concurrency waits — so the target attacks the real bottleneck instead of over-buying everywhere. Signal 04 — I/O Profile Reads read/write IOPS, throughput, block size, and latency. This is the direct input to storage sizing, and it separates latency-sensitive OLTP from bandwidth-driven scan/DW workloads — which size very differently. Averages hide the peak windows that actually test the array. Red means: real I/O demand the target tier must sustain. Under-provision here and everything above it — waits, capacity, response time — degrades. How Everpure helps: the assessment moves beyond averages to hour-by-hour peak-window analysis and turns it into a concrete IOPS/throughput/latency target for FlashArray — sub-millisecond and consistent, so the design performs at peak, not just on paper. Signal 05 — Memory Reads SGA/PGA sizing, buffer-cache behaviour, and Oracle's own memory advisories. Right-sizing memory on the target avoids trading RAM savings for a flood of avoidable physical I/O — and under-sized memory quietly inflates the I/O profile, so the two signals move together. Red means: memory is under-provisioned and driving physical reads that should be cache hits. Size SGA/PGA to demand rather than copying the old config. How Everpure helps: Everpure correlates memory pressure with observed I/O, so recommendations account for both together — enough memory to cut needless physical reads, and storage sized for what genuinely reaches disk. Signal 06 — Temp & Work Reads temp tablespace usage, sort/hash spills, PGA work-area activity, and multipass operations. Analytics, reporting, and AI-adjacent workloads live or die on temp and PGA — and 26ai vector operations add sort/compute patterns you have not sized for before. Red means: large sorts/hashes are spilling to temp; without PGA and temp sizing, the workload is slow on day one regardless of platform. How Everpure helps: the assessment quantifies spill behaviour and feeds it into PGA and temp-tier sizing, while FlashArray's consistent low latency keeps unavoidable spill cheap rather than catastrophic. Signal 07 — Segment Risk Reads large or fast-growing segments, chaining, LOBs, partitioning, and use of features like TDE, Hybrid Columnar Compression, and Smart Scan. These are the objects that don't migrate cleanly — reorg candidates, feature-compatibility items, and capacity-growth landmines. Red means: schema-level cleanup, not just capacity: objects that need reorg, or that depend on features the target must be configured to support from day one. How Everpure helps: Everpure auto-detects active features (TDE, HCC, Smart Scan) so the target is configured for them without over-provisioning, and replaces full clones and legacy triple-copy redundancy with space-efficient snapshots and external redundancy to reclaim capacity. From evidence to a right-sized migration The scorecard is the front door. Behind it is an assessment built to turn these seven signals into decisions you can defend to procurement and operations alike. It captures every instance for an ecosystem view, replaces multi-day averages with peak-window analysis, and translates raw metrics into specific storage and configuration recommendations for a 26ai target. It runs privacy-first — hostnames and SQL identifiers are masked, and only the actionable results are shared. Sometimes the biggest finding is what you don't need to buy. One prospect expected to buy 200 TB. The workload needed 18 TB. The gap was legacy ASM high-redundancy (three data copies) plus full clones for dev/test. Moving to Oracle-recommended external redundancy on Everpure and space-efficient snapshots reclaimed roughly two-thirds of the footprint and eliminated over 180 TB of wasted capacity — exactly the kind of trap that nameplate-based sizing would have locked in. From there, a right-sized design lands on a platform built for database density: Everpure FlashArray//XL R5 delivers sub-millisecond, consistent latency and industry-leading data reduction that absorbs vector growth economically. Pure Fusion presets encode your sizing discipline once so every 26ai environment is provisioned the same way, and Pure1 adds fleet-wide performance, capacity forecasting, and application-level context. A sizing-first path to 26ai Assess. Send your AWR reports; the 26ai Readiness Assessment is generated automatically, with identifiers masked. Interpret the signals. Reds are the pre-migration punch list; cautions are the validate list. Watch for fleet-wide patterns. Remediate reds first. Fix CPU, SQL/parse, dominant waits, and segment issues before cutover. Right-size the target. Size compute, memory, temp/PGA, and storage to the measured peak — and strip out redundancy and clone inflation. Provision consistently. Use Pure Fusion presets so every environment is built to the same standard. Validate with a pilot. Confirm behaviour against a representative pilot and target telemetry before scaling the wave. Summary Oracle 26ai brings back the art of sizing. The 26ai Migration Readiness scorecard reads seven signals from your AWR data — System Capacity, SQL & Parse, Wait Profile, I/O Profile, Memory, Temp & Work, and Segment Risk — so you can remediate the reds, right-size the target to your real workload, and move to 26ai with confidence instead of guesswork. Know where you stand — send us an AWR report, and Everpure's Oracle experts will run the 26ai Readiness Assessment on your environment and walk you through the seven signals, your remediation punch list, and a right-sized target design. The readiness score is an AWR-derived, current-state indicator to guide investigation and planning. It is not a migration certification, a final target-platform sizing, or a target-array headroom calculation — those decisions require workload requirements, target telemetry, compatibility checks, and a representative pilot. Database figures shown are illustrative. Oracle is a trademark of Oracle Corporation. © 2026 Everpure, Inc.39Views0likes0Comments
Navigating the Tsunami, Reshaping the Data Industry
August 18 | Register Now! For August 2026, host Andrew Miller invites Andy Yun to Coffee Break. As a DBA himself with a long career in the data + database field, Andy now talks to Everpure customers (or sometimes “future customers”) every day about data and database challenges and solutions. We’ll wander through: Andy’s history with key mentoring lessons (both those he has learned and has helped others with), the value of soft skills in a deeply technical role, and why a solution architect works at Everpure. Database & DBA landscape - simultaneously keeping up “business as usual” while adapting to the AI tsunami that’s here whether we like it or not. Andy’s top DBA & database tips on Everpure from chatting with DBAs and customers every day. What’s new in the data landscape at Everpure - everything from an Oracle 26ai readiness assessment, to mind-blowing SQL backup throughput numbers, to how recent Everpure acquisitions impact you. Register Now!55Views0likes0CommentsThe Art of Sizing: Breaking the Myths of Oracle Compression
If you work in storage or databases, you have probably heard the pitch: turn on Oracle compression, send fewer bytes, save space, reduce I/O, and lower cost. That sounds great on a slide. In the real world, it is often the opposite. This installment of The Art of Sizing breaks down one of the most persistent myths in enterprise infrastructure: that Oracle host-based compression is automatically a win. We are going to walk through the major compression types, where they help, where they hurt, and why the wrong compression decision can actually create more cost, more network traffic, more I/O, and more work for both storage admins and DBAs. The goal is not to say compression is bad. The goal is to size it correctly, understand where it belongs, and avoid paying premium dollars to make your systems do extra work. Why this myth survives Compression has a good reputation for a reason. Historically, it solved real problems. Storage was expensive, bandwidth was limited, and shrinking data was often the simplest path to efficiency. That logic still holds in some places. But in Oracle environments, especially transactional ones, the story gets more complicated. Oracle is not just writing datafiles. It is writing redo, managing undo, reorganizing blocks, updating symbol tables, and sometimes re-processing data later for deeper compression. That means a “smaller data footprint” does not always equal a smaller infrastructure burden. Sometimes it just shifts the burden somewhere else. First, let’s separate the compression families Not all compression is the same, and not all of it behaves the same way in Oracle. 1. General lossless compression This is the classic world of ZIP, GZIP, LZ77, LZ78, DEFLATE, ZSTD, and similar algorithms. The point is simple: reduce size without losing information. These methods are excellent for files, backups, archives, and many data services. Modern storage platforms use fast versions of these ideas in ways that are largely invisible to the application. 2. Lossy compression Think JPEG, MP3, MPEG, and H.264. These formats intentionally throw away some data in exchange for dramatic size reduction. They are incredibly effective for media, but they are not relevant for Oracle datafiles because databases generally require exact fidelity. 3. Oracle database compression This is where the confusion starts. Oracle has several different compression approaches, each with different behavior, licensing implications, and performance trade-offs: - Basic Table Compression - Advanced Row Compression - Advanced Index Compression - SecureFiles LOB Compression - Hybrid Columnar Compression - RMAN Backup Compression - Automatic Data Optimization and ILM-driven background re-compression Lumping all of those together under “Oracle compression” is one of the fastest ways to make bad architecture decisions. The big myth: compressed writes mean less work Here is the myth in plain English: If Oracle compresses the data before it sends it to storage, the network carries fewer bytes, the array writes less data, and the whole system gets more efficient. What that myth ignores is the full lifecycle of an Oracle write. In active transactional systems, Oracle prioritizes commit latency. That means the redo stream is written first, and it is written uncompressed. Later, as blocks fill and thresholds are crossed, Oracle may compress or re-compress them in memory. That structural change can generate additional redo. If data is later pushed into deeper formats through background optimization or archive-style compression, the system may read, process, and write the same data again. So yes, one part of the path may get smaller. But the total system effort often gets bigger. Figure 1: The life of a compressed I/O inside Oracle (OLTP write path). Notice that data is NOT compressed when it first travels to storage as redo, that write amplification happens at the threshold-hit step, and that this is where the footprint can start to grow. How to actually see it happening This is the part both DBAs and storage admins care about: how do you know Oracle is revisiting blocks, delaying compression, and generating extra work after the commit already succeeded? The threshold delay, in plain English With Advanced Row Compression, Oracle does not usually compress every row the moment it is inserted. Instead, rows are typically written into the block uncompressed first so Oracle can keep transactional latency low. Oracle keeps watching the remaining free space in that 8KB block. Once the block crosses an internal fullness threshold, Oracle goes back, builds or updates the symbol table, batch-compresses the block in memory, and then has to account for that structural change. That delayed work is what I mean by the threshold delay. So the timeline looks more like this: user writes data Oracle writes redo for durability commit returns quickly the block stays in buffer cache the block fills further threshold is crossed Oracle compresses or re-compresses the block in memory additional redo and block maintenance activity can follow That is why the system can look quiet at commit time and then busy again later. How you can tell Oracle is "redoing" things You are usually not looking for one giant smoking gun. You are looking for a pattern where post-commit activity does not line up with the simple story of "we wrote it once and moved on." Common signs include: redo generation that seems higher than expected for the amount of business data changed continued redo and log write activity after the original insert burst is over CPU spikes around block maintenance rather than just around user SQL periodic write bursts that do not line up cleanly with front-end transaction volume maintenance-window bandwidth spikes when colder data is being reworked into deeper compression formats storage-side churn where the array still sees a lot of activity even though the data was supposedly "compressed already" At the database layer, the giveaway is often the mismatch between application change volume and the total work observed in redo, background activity, and later data movement. At the storage layer, the giveaway is seeing traffic patterns that look like read-process-write loops rather than a single smooth write path. Why the database can get larger after a few days This confuses a lot of people because they expect compression to make the footprint immediately smaller and keep it smaller. Figure 2: The background ADO/HCC re-compression path. Days or weeks after the initial write, background jobs read cold data off the array, re-process it on the host, and write it back, so segments can grow from extra redo, undo, rewritten copies, and unreclaimed space. But Oracle compression can create delayed growth behaviors for several reasons: new rows may land uncompressed first and only later be reorganized recompression work can generate extra redo and undo background optimization jobs may read old blocks, reorganize them, and write new versions back out old extents may not be reclaimed immediately even after data is moved or rewritten free space inside segments may become fragmented in ways that do not instantly shrink the physical files if data is updated repeatedly, blocks can split, migrate, or be rewritten in ways that increase segment size before any long-term savings appear So what looks like "compression should have made this smaller" can become "the system created more structures, more history, and more rewritten copies before it settled down." For storage admins, this often shows up as a database that writes out one size on day one and then consumes more logical or physical space over the next several days as Oracle continues block maintenance, redo generation, archive activity, and background reorganization. The practical operator lesson If you want to understand whether compression is helping or hurting, do not just compare the first write size to the final stored size. Instead, look at the full lifecycle: initial redo volume later redo spikes buffer-cache and CPU behavior around block fullness archive log growth background maintenance windows segment growth over time instead of only at load completion storage bandwidth and write churn several days after the original ingest That is where the threshold delay becomes visible. That is where the myth breaks. Why host-based compression can cost more money This is where The Art of Sizing matters most. Compression is often sold as a capacity story, but in Oracle it can quickly become a licensing and CPU story. Advanced Row Compression and SecureFiles LOB Compression are paid features. That means you are not just paying in cycles, you may be paying in Oracle licensing. And if compression overhead pushes CPU consumption higher, you may end up needing to license more cores just to preserve the performance you had before. That is a brutal trade: - You pay for the compression feature. - You spend host CPU running the compression feature. - You may need more licensed cores because of the compression feature. - You still do not eliminate redo overhead. At that point, “saving space” can become one of the most expensive optimizations in the stack. Why it can create more network traffic This is the part that surprises people. On transactional writes, the redo stream still moves as uncompressed change data so Oracle can preserve low-latency commit behavior. That means the initial transactional path does not magically shrink just because the table eventually lands in a compressed state. Then the hidden traffic starts: - secondary redo generated when blocks are compressed or re-compressed - additional log activity to track structural changes - background movement when colder data is reorganized into deeper compression formats - read-process-write cycles for jobs like ADO or HCC-related maintenance For the SAN, that can mean less of a neat “compressed payload” story and more of a churn story. Why it can create more I/O Storage admins know this instinctively: once a system starts revisiting the same data repeatedly, the theoretical savings usually get eaten by operational noise. That is what can happen here. A write is not always a single write anymore. It can become: - the original transactional activity - redo logging for durability - later in-memory compression work - secondary redo for compression state changes - future background read-and-rewrite operations for deeper compression That is not reduced work. That is redistributed work, with extra steps. For busy OLTP systems, that redistribution can show up as more write amplification, more jitter, and more performance variance than people expected when they first heard the word “compression.” Why it creates more operational work Compression decisions do not just affect hardware. They create administrative drag. DBAs have to understand which compression mode is active, what is licensed, what is free, what silently triggered usage, and how it affects redo, CPU, and maintenance windows. Storage admins have to explain why the array still sees redo churn, why bandwidth spikes appear during data reorganization, and why dedupe or downstream efficiency may not look the way a simplified Oracle story suggested. And everyone gets more work when performance troubleshooting starts with a bad assumption. A quick breakdown of the Oracle compression types Basic Table Compression Good for bulk loads and relatively static datasets. It is not a magic answer for active transactional workloads because standard ongoing DML does not benefit the same way. Advanced Row Compression This is the big one in OLTP discussions. It supports active transactional operations, but it is also where deferred compression, block threshold behavior, secondary redo, and paid licensing can combine into a very expensive surprise. Advanced Index Compression Useful in the right indexing scenarios, especially with repetitive keys. This is more targeted and usually not the villain in the story, but it still needs to be understood separately from table compression. SecureFiles LOB Compression Can reduce footprint for large objects like documents, JSON, XML, and similar content, but it pushes work onto host CPU and can throttle ingestion performance when volumes are high. Hybrid Columnar Compression Very powerful for analytics, archival, and cold data patterns. It is not designed like OLTP row compression, and it often belongs in a very different conversation. When used through background movement or deep reorganization, it can generate substantial read-process-rewrite churn. RMAN Backup Compression A separate discussion from live transactional compression. Useful when applied deliberately, but some algorithms can also introduce licensing implications. The sizing lesson This is the heart of the series. Do not size from the brochure claim. Size from the full path of work. When evaluating compression, ask these questions: - What happens on the initial write path? - What happens to redo? - What CPU tax lands on the host? - Does this feature introduce licensing cost? - Will background maintenance create bursts of read-write churn later? - Is the data really a good fit for host-side database compression, or would array-level reduction be cleaner? If you do not answer those questions, you are not sizing compression. You are just hoping it behaves the way marketing described it. Where compression often belongs instead For many environments, especially where modern storage platforms provide inline reduction, the cleaner design is to let the database do database work and let the array do storage work. Figure 3: Myth vs reality, where should compression live? Host-side compression adds CPU, redo, and license cost, while array-level compression keeps host writes normal and delivers predictable I/O with global dedupe. That changes the equation: - less host CPU consumed by compression logic - fewer surprises tied to paid database options - fewer extra redo side effects from re-compression behavior - more predictable storage-side efficiency - a simpler operational model for both DBAs and storage teams That does not mean every Oracle compression feature is wrong. It means compression should be placed where it creates the least total system friction. And in many real-world environments, that is not at the host. Final thought: compression is not free just because it saves space Compression can absolutely be part of a smart architecture. But if you only measure saved capacity and ignore processor cost, network churn, redo behavior, maintenance overhead, and operational complexity, you can easily end up paying more to store less. That is the myth this post is here to break. In The Art of Sizing, the best design is not the one with the smallest number on a capacity chart. It is the one that delivers the best total outcome across cost, performance, simplicity, and operational sanity. And when it comes to Oracle compression, that usually starts with asking a harder question: Is this actually reducing work, or just moving it somewhere more expensive? Coming next In the next installment, we will look at the relationship between compression and encryption in Oracle, and why that combination can further change what the storage team sees and what the database team pays for.91Views0likes0CommentsThe Art of Sizing: When Your "Safe" Standby Database Starts Hurting Production
In earlier posts in The Art of Sizing, the focus was on what happens when Oracle systems create their own instability through design shortcuts that seem harmless at first. This post extends that same idea into Data Guard, where a standby database that looks like passive insurance can become part of the foreground performance problem when it is undersized or poorly observed. That is the trap with synchronous disaster recovery. The standby is not just sitting there waiting for a failover. In MAX AVAILABILITY or MAX PROTECTION with SYNC AFFIRM, the primary commit path is directly dependent on the standby receiving redo, writing it to the standby redo log, and acknowledging that write before user sessions are released. When that standby server is short on CPU, struggling on storage, or starved for memory, the latency does not stay isolated on the remote side. It propagates backward into production as log file sync pain, commit stalls, and application slowdown. Why this problem is easy to miss The diagnostic challenge is that the evidence is often sitting on the standby side, but a physical standby in Active Data Guard read-only mode does not behave like a normal local AWR source. Standard local AWR reporting is not enough, and if Remote Management Framework is not already configured, the team can be in the middle of an incident without the standby visibility they actually need. That is what makes this a sizing topic rather than just a monitoring topic. If the standby participates in the commit path, then its storage behavior, CPU headroom, and buffer pressure are part of the production design whether teams acknowledge that or not. How to expose standby performance in Oracle 19c In Oracle 19c, the practical answer is to enable RMF so the primary can collect standby performance snapshots remotely and store them safely in the primary SYSAUX tablespace. The configuration sequence below is the key setup step that makes standby AWR reporting usable during a real production event. -- 1. Enable Management Pack Access on both instances ALTER SYSTEM SET control_management_pack_access='DIAGNOSTIC+TUNING' SCOPE=BOTH; -- 2. Register Nodes and Establish Topology on Primary EXEC DBMS_UMF.configure_node('NODE_PRIMARY', 'PRIMARY'); EXEC DBMS_UMF.configure_node('NODE_STANDBY', 'STANDBY'); EXEC DBMS_UMF.create_topology('ADG_AWR_TOPOLOGY'); -- 3. Link Remote Topology and Enable AWR Service EXEC DBMS_UMF.register_node( 'ADG_AWR_TOPOLOGY', 'NODE_STANDBY', 'DB_LINK_TO_STANDBY', 'DB_LINK_TO_PRIMARY', 'AS_NODE', 'TRUE' ); EXEC DBMS_WORKLOAD_REPOSITORY.register_remote_database( node_name => 'NODE_STANDBY' ); Once the standby is registered, reports can be generated from the primary by running awrrpti.sql and selecting the standby DBID from the menu. What to watch for in a standby AWR report The most useful way to read a standby AWR during a production slowdown is to correlate primary symptoms with standby evidence. The issue usually presents itself as one of a few recognizable patterns. Primary production symptom Standby AWR red flag Likely meaning Spike in log file sync and high SYNC transport lag High log file parallel write on the standby, especially above roughly 5 to 10 ms The standby storage tier is underperforming and slowing standby redo log flushes. Primary LGWR stalls on LNS wait on send Standby host CPU utilization near 100 percent or a high load average The standby is CPU-starved and RFS processes are not acknowledging packets quickly enough. Commit stalls appear at particular hours High ASH on the standby from user reporting activity Heavy Active Data Guard reporting is taking CPU and buffer cache away from recovery work. Flush delays and transport buffer saturation High free buffer waits or checkpoint completed during MRP Buffer cache is too small or DBWR is saturated on the standby. The sizing lesson underneath the incident The bigger lesson is that standby design is not a secondary hardware conversation. In synchronous architectures, the primary database is only as fast as the weakest link in the standby path. That means a disaster recovery platform should not be treated as a low-priority landing zone built from slower storage, thinner CPU allocation, or loosely governed reporting workloads. If it participates in commit acknowledgment, it participates in production performance. The practical operating principles are straightforward: Keep the standby infrastructure performance-symmetric with production where synchronous protection is required. If Active Data Guard is used for reporting, govern those read workloads so they cannot starve RFS or MRP activity. Enable RMF-based standby AWR collection before there is a crisis, not during one. Final thought A standby database is supposed to be your safety net. But in synchronous Data Guard, a poorly sized or poorly monitored standby can become part of the outage story itself. That is the real point here: availability architecture is still performance architecture, and the standby is still part of the sizing equation. That is also why this topic belongs in The Art of Sizing series. Good sizing is not just about capacity. It is about understanding which components quietly sit inside the critical path, and making sure they are designed, monitored, and governed accordingly. Sources The Art of Sizing Data Guard and the Hidden Cost of Small Redo Decisions112Views0likes0CommentsClaude Code as Database SRE: Catching What Your Monitoring Never Will with Everpure Fusion MCP
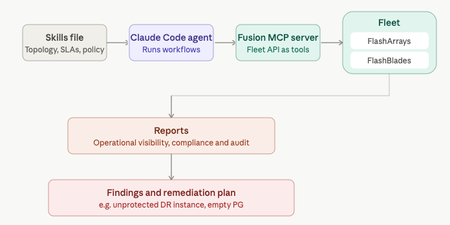
Your DR site might be quietly unprotected and no alert will tell you. That's the gap Anthony Nocentino, Principal Architect at Everpure, Microsoft Data Platform MVP, and self-described computer nerd set out to catch. He built a Database SRE agent using Claude Code and the Everpure Fusion MCP server to audit SQL Server fleets against compliance policy, uncovering a silently unprotected DR instance before disaster struck. Read the full report at "Using Claude Code as a Database SRE Agent with the Everpure Fusion MCP Server"36Views0likes0CommentsThe Future of Intelligent Data Platforms: AI-Powered Search in SQL Server 2025
July 23 | Register Now! Semantic search allows applications to find relevant information based on meaning, rather than exact words. In this session, we'll look at how SQL Server 2025 implements this technology using native vector support and demonstrate how it can be used to build intelligent search experiences. You’ll see practical examples for generating, storing, and querying vectors, plus guidance on evaluation and performance trade-offs. Attendees will leave with an actionable plan to pilot semantic search and measure impact in their environment. Here is what to expect: Understand how vector search differs from keyword search Generate and store embeddings in a repeatable workflow Perform semantic searches using SQL Server's vector capabilities Evaluate performance impacts of vector indexes Register Now!140Views0likes0CommentsThe Art of Sizing: Data Guard, Redo Storms, and the Hidden Cost of Bursty Commits
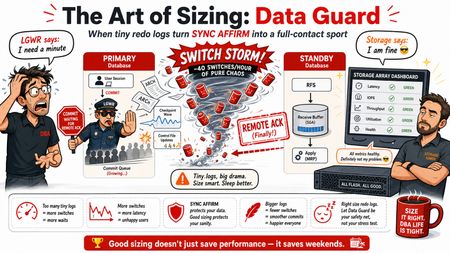
In the previous edition of The Art of Sizing, I focused on redo log switches and why they are so often blamed on storage first. This post extends that same discussion into Oracle Data Guard, where small sizing decisions on the primary database can grow into larger architectural issues across both sites. What begins as an undersized redo design can quickly show up as commit latency, transport sensitivity, standby stress, and misleading storage symptoms. That is the central lesson of Data Guard sizing: the standby does not just replicate business activity. It also replicates the quality of the redo design underneath it. When the redo layer is stable and appropriately sized, Data Guard behaves predictably. When redo is bursty, logs are too small, and switches occur too often, Data Guard magnifies the weakness rather than hiding it. Why Data Guard exists Oracle began shipping standby database capability in the Oracle 8.0.4 era, and by Oracle9i it had evolved into Oracle Data Guard as a formal disaster recovery and availability framework with stronger automation and management capabilities. Its purpose was clear: organizations needed a supported way to maintain a remote copy of production data for failover, switchover, and business continuity without relying on improvised processes around archived redo streams alone. That purpose remains the same today. Data Guard is designed to preserve recoverability and availability, but it does not remove the physical realities of latency. Network round-trip time still matters. Remote acknowledgment still matters. Standby write latency still matters. If the primary database is generating redo in sharp, repetitive bursts while cycling through undersized logs, Data Guard will expose that weakness very quickly. The three transport modes and where commit actually waits Before looking at storms and bursts, it helps to ground the discussion in the three common transport models. Figure 1 shows the practical difference between SYNC AFFIRM, SYNC NOAFFIRM, and ASYNC: not just how redo is transported, but where the acknowledgment point sits relative to the foreground commit path. Figure 1: Oracle Data Guard transport modes showing the acknowledgment point for SYNC AFFIRM, SYNC NOAFFIRM, and ASYNC. In SYNC AFFIRM, the primary commit waits until the standby has performed a durable remote write before the user receives a successful commit response. That provides the strongest protection model of the three, but it also creates the highest commit latency because the foreground path now includes local redo handling, network transport, standby receive processing, standby redo log writes, and remote disk acknowledgment. In SYNC NOAFFIRM, the transport remains synchronous, but the commit can clear once the standby has received the redo into memory rather than waiting for a remote disk flush to complete. That reduces latency compared with AFFIRM while preserving synchronous transport behavior. In ASYNC, the primary does not wait for remote acknowledgment in the foreground commit path. That produces the lowest commit latency, but it also introduces a possible data-loss window if the primary fails before the redo is fully transported and protected at the standby site. The practical takeaway is straightforward. If the business requirement is near-zero or zero data loss and the network and standby design can support it, AFFIRM may be appropriate. If synchronous behavior is required but remote disk flush latency is too expensive, NOAFFIRM is often the more balanced operational choice. If foreground response time matters more than immediate remote durability, ASYNC is usually the cleanest fit. Why redo sizing matters so much This is where many environments make a costly mistake. Teams often treat transport mode as the primary design decision while treating redo log sizing as background plumbing. In reality, redo log sizing is one of the strongest predictors of whether Data Guard feels stable or painful under load. Long-standing Oracle practice is clear: a healthy system should not be switching redo logs constantly. A normal target is roughly 3 to 5 switches per hour during peak activity, not a switch every minute or two. Once switch frequency becomes excessive, Oracle begins manufacturing its own turbulence. Every switch drives checkpoint advancement, dirty buffer flushing, control file updates, and archiver coordination. That churn is disruptive even on a standalone system. In a Data Guard architecture, it becomes a cross-site problem. Earlier telemetry showed that sustained redo rates in the range of about 34 MB/s to 39 MB/s, combined with undersized logs, were enough to create a switch-storm pattern and the kind of latency that often gets blamed on storage first. What a Data Guard switch storm looks like Figure 2 makes that switch storm visible. It shows a database switching roughly 40 times per hour compared with a best-practice target of around 3 to 5 switches per hour. More importantly, it shows that both SYNC AFFIRM and SYNC NOAFFIRM suffer from the same local Oracle storm on the primary side: repeated checkpoint work, ARCn pressure, control file activity, and rising commit latency. The real difference is not whether the local storm exists, but where the remote acknowledgment point sits in the commit path. Figure 2: Data Guard under a redo log switch storm, showing how 40 switches per hour drive repeated checkpoint pressure, ARCn pressure, and commit latency spikes in both synchronous modes. Under SYNC AFFIRM, the pain is greatest because the foreground commit must survive both the local churn and the full remote durable-write acknowledgment before the user is released. Under SYNC NOAFFIRM, the latency penalty is lower because the remote disk flush is removed from the foreground path, but the primary still absorbs the same switch storm locally. Under ASYNC, the commit may clear quickly, but the standby can still fall behind in transport or apply if redo arrives faster than the downstream system can consume it. Why storage can look healthy while the database feels bad This is the point where DBAs and storage teams often talk past one another. Repeated switch-driven checkpoint waves create short, sharp, bursty I/O patterns rather than a smooth write stream. The array can look healthy on paper. Average latency can look acceptable. The platform may still have plenty of headroom. Yet the database users can still be feeling brief but repetitive stalls every time the redo architecture forces another checkpoint cycle and another wave of coordination work. That is why a fast array does not automatically eliminate the problem. The issue is often not sustained bandwidth exhaustion. The issue is workload shape. If redo arrives in spikes and the logs are too small, the backend experiences bursty pressure rather than a smooth average. Even an excellent array can be difficult to interpret when the real pain occurs in short windows that disappear inside broader averages. This is also why coarse AWR timing can be deceptive. A 15-minute reporting window can smooth dozens of short checkpoint spikes and log-switch bursts into something that looks moderate. If the system is switching every 90 seconds or every couple of minutes, you often need 1-minute granularity, or finer if the tooling allows it, to see the real pattern. Array-side telemetry is especially useful here because it can expose the microburst behavior more clearly than coarse Oracle summaries do. Why SYNC AFFIRM degrades under bursty redo Figure 3 brings the entire problem into focus. It shows why a system with 4 GB redo logs switching more than 40 times per hour can turn what looks like a modest average redo rate into a foreground and background stress event across the Oracle stack and the storage layer. Figure 3: Why SYNC AFFIRM drives high log file sync under bursty redo, showing the burst pattern, the foreground commit chain, switch-generated extra work, and wait propagation across Oracle and the SAN. The first panel shows the source pattern: burst redo rather than a smooth stream. The slide describes 4 GB online redo logs, more than 40 switches per hour, approximately one switch every 1 to 2 minutes, roughly 160 GB of redo per hour, and an average redo rate near 45 MB/s. Its warning is exactly right: the average rate can look modest while the instantaneous pattern is bursty and repetitive. That distinction matters because a database can look reasonable in average throughput terms while performing badly in commit latency. The bursts fill small logs quickly, and each rapid switch triggers another round of local and remote work. The second panel walks the critical SYNC AFFIRM commit path. A foreground user issues a commit. LGWR serializes the commit records. Redo is written to the local primary redo log. It is then transported synchronously to the standby, received by RFS, written to standby redo logs, flushed to disk, and only then acknowledged back to the primary so the commit can be released. In other words, remote durable write is not a side activity in AFFIRM; it is part of the foreground commit path itself. The third panel explains why log file sync gets dramatically worse under this pattern. The wait does not inherit one isolated delay. It inherits the full chain: LGWR serialization, local redo write service time, inter-site RTT and jitter, standby receive service time, standby redo write service time, remote durable flush acknowledgment, and then the repeated switch churn that injects checkpoint, control file, and archiver coordination every 90 seconds or so. The fourth panel makes another important point: this is not just an LGWR issue. Foreground stress appears in user sessions, LGWR, the commit path, log file switch completion exposure, log buffer space pressure, and transaction stall behavior. Background stress lands on DBWn, CKPT, ARCn, RFS, standby redo log writes, and control file sequence metadata work. A switch storm is not a single bottleneck; it is a coordinated pattern of foreground and background pressure. The fifth panel is especially useful for storage teams because it shows the backend write pattern. The SAN is not observing a flat 45 MB/s stream. It is seeing primary redo writes, shipped redo, standby redo writes, archiver rereads after switch, and additional checkpoint-driven datafile writes, with several components shown at roughly 160 GB/hour minimum and checkpoint-driven activity identified as workload dependent and burst amplified. That is why the backend can appear healthy in average terms while still absorbing violent front-end bursts and queue spikes. The sixth panel shows the cascading shape of the workload. A redo burst fills the log. A switch occurs. Extra writes and rereads hit storage and SAN. Foreground commits wait for remote durable acknowledgment in SYNC AFFIRM. Log file sync escalates. The slide describes each switch as producing an echo of extra work, and that is an accurate way to think about it. The stress symptoms listed on the right side of the slide align closely with what experienced teams often see during these events: very high log file sync, elevated log file switch completion waits, log buffer space pressure, sensitivity in SYNC remote write or redo transport, SAN queue bursts, and front-end write spikes. The key lesson is that local write latency alone may not look catastrophic, yet the foreground commit experience can still become severe because the full path is waiting on the entire chain to clear. What improves when redo logs get larger The encouraging part of the story is that the operating pattern can be improved significantly even when the protection model stays the same. Figure 4 shows the outcome teams actually want: the same workload, the same SYNC AFFIRM design, but far fewer self-inflicted switch events because the online redo logs are larger. Figure 4: Modeled impact of increasing online redo logs under SYNC AFFIRM, showing that redo volume remains similar while switch frequency, checkpoint turbulence, and burst-driven array stress fall materially. The comparison is straightforward. At roughly the same redo generation volume of about 160 GB per hour, moving from 8 GB logs to 40 GB logs reduces the switch rate from about 20 switches per hour to about 4 switches per hour. That changes the approximate switch interval from around 3 minutes to around 15 minutes while keeping the commit path mode the same: SYNC AFFIRM. The protection model has not changed, but the operating pattern has. Checkpoint wave frequency becomes much lower. Archiver wakeups and control-file churn become much lower. The array-facing write pattern becomes flatter and less bursty. The workload-shape panel is especially valuable because it shows that redo volume is not the same thing as switch turbulence. With 8 GB logs, the environment hits repeated switch boundaries and repeated checkpoint flush waves throughout the hour. With 40 GB logs, those boundaries are much less frequent, the checkpoint waves are much less repetitive, and the system spends far less time manufacturing its own instability. That reinforces the core message of this post: many Data Guard performance problems are not caused by total redo volume alone. They are caused by the shape of the workload and by how often Oracle is forced to react to full logs, checkpoints, archiver cycles, and control-file updates. The Oracle task impact model in the slide also matches real-world behavior. With larger logs, LGWR commit pressure is lower, log file sync exposure is lower, CKPT activity is much lower, DBWn flush pressure is much lower, ARCn archive pressure is much lower, control-file update churn is much lower, and log switch completion risk is much lower. This does not mean larger logs magically remove the cost of SYNC AFFIRM. The caveat panel in the slide is correct: if remote AFFIRM acknowledgment remains the dominant bottleneck, log file sync may improve only partially. But checkpoint, archiver, and control-file churn should still drop materially, and the write pattern presented to the array should smooth out. That is the practical point storage teams need to see. A larger redo configuration does not reduce the need for remote durable acknowledgment in SYNC AFFIRM, but it does reduce the self-inflicted switch overhead around that acknowledgment path. In many environments, that is enough to materially reduce front-end write burstiness, queue depth volatility, in-flight spike risk, and visible host-side latency spikes. Final thought Data Guard is a very capable product, but it is also brutally honest. It reflects the quality of the primary redo design with very little mercy. If the logs are too small, the switches are too frequent, and the workload is bursty, SYNC AFFIRM will make that weakness highly visible by placing remote durable acknowledgment inside an already stressed commit path. The array may be fast. The network may be fast. The standby may be healthy. But if the redo architecture is wrong, the full chain can still stall. That is the real art of sizing Data Guard. It is not just about how much redo is generated. It is about how that redo arrives, how quickly logs fill, how often switches occur, where the acknowledgment point sits, and whether the measurement tools are granular enough to reveal the truth before averages hide it. Sources Oracle Log Switch Architecture Analysis & Blog Framework Storage Performance & Redo Architecture Root Cause Analysis V2 1 Oracle9i Data Guard Concepts Oracle 9i - Oracle FAQ racle 11g Data Guard and RAC Oracle Redo Log Sizing Cost-Benefit & Performance Savings Analysis161Views0likes0Comments