Ask Us Everything About Storage for Databases!
💬 Get ready for our March 2026 edition of Ask Us Everything, this Thursday, March 19th at 9 AM Pacific. This month is all about Storage for Databases! If you have a burning question, feel free to ask it here early and we'll add it to the list to answer tomorrow. Or if we can't get it answered live, our Everpure experts can follow up here. Anthony Nocentino, rarsenault-pure & dpoorman are the experts answering your questions during the conversation and on the community. See you this Thursday! (Oh, and if you haven't registered yet, there's still time!) Or, check out these great self-serve resources: Solutions Page: https://www.purestorage.com/solutions/databases.html Blogs: https://blog.purestorage.com/perspectives/sql-server-2025-mission-critical-workloads/ https://blog.purestorage.com/solutions/data-platform-oracle-ai-database-26ai/ https://blog.purestorage.com/purely-technical/using-t-sql-snapshot-backup-multi-array-database-snapshots/ https://blog.purestorage.com/products/exploring-modern-data-storage-challenges-and-changes/700Views1like0Comments
Boston Pure User Group (PUG) at Trillium - Fort Point!
Simplify IT, Empower Data - Over a Pint at Trillium - Fort Point Join us August 21 2025, and connect, learn, and engage with your fellow IT pros for an afternoon filled with exciting announcements from the recent Pure//Accelerate event and our vision for the Enterprise Data Cloud, as well as an engaging discussion on modern virtualization and a demo of Fusion. Fusion is a fully integrated platform that federates multiple arrays—such as FlashArray and FlashBlade—into a unified fleet, enabling centralized, cloud-like management, streamlined resource provisioning, and enhanced visibility across multi-array environments. Rob Quast, Principal Technologist from Pure Storage will be presenting on the above topics with additional input from other Pure technologists. The complete agenda is below. Please register if you plan on attending: Register Here Agenda 2:00 PM - Welcome & Cheers Light intro by host & Pure representatives. Local brew served!! 2:15 PM - Accelerate Highlights: What You Missed (or Want More Of) A high-level recap of key announcements: Fusion, Evergreen One, FlashBlade//SR2 2:45 PM - Enterprise Data Cloud: The Vision and The Why Why it matters: cutting complexity, controlling cost, and scaling for AI 3:15 PM - Fusion in Action: Simplifying Storage with Intelligence Live demo or use-case storytelling around automation, presets, and governance 3:45 PM - Break & Bites Grab a drink, mingle, enjoy local food 4:15 PM - Rethinking Virtualization in 2025 What’s next after VMware? Discuss Pure + Nutanix, KubeVirt, Azure/AWS paths 4:45 PM - Ask Me Anything (AMA) Panel Interactive Q&A with Pure team + customer guest if available 5:15 PM - Cheers & Networking Open networking, brewery tour optional We look forward to seeing you!499Views0likes1Comment
Unlock AI Capabilities: Best Practices for Risk-Free Oracle 26ai Upgrades
April 16 | Register Now! Upgrading to Oracle AI Database 26ai with AutoUpgrade simplifies the database process. Yet many teams can struggle with the storage infrastructure risk from performance variability, downtime and operational complexity during the transition. This session explores how to remove this infrastructure friction from Oracle 19c to 26ai upgrades by leveraging non-disruptive storage operations, snapshot-based rollback, and consistent performance at scale. Learn how to: Upgrade to Oracle 26ai using infrastructure best practices Align to a unified data platform Provide a stable foundation for AI-enabled workloads Register Now!400Views0likes0Comments
The Lost Art of Sizing
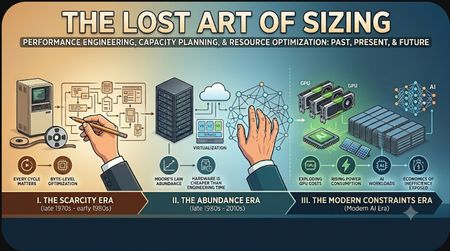
Introduction — Why This Series Exists Technology has gone through one of the most extraordinary economic transformations in modern history. For over four decades, the industry benefited from continuously cheaper computing resources, exponentially faster processors, collapsing storage costs, and an almost limitless ability to scale systems through virtualization and cloud computing. During that time, many of the operational disciplines that once defined great engineering slowly faded into the background. Precise sizing, deep performance analysis, workload modeling, and resource optimization became less visible as organizations increasingly relied on abundant infrastructure to compensate for inefficiencies. But the economics are changing. Today we are entering an era defined by: exploding GPU costs massive AI infrastructure investments rising power consumption thermal and density limitations increasingly expensive semiconductor fabrication and cloud bills that are exposing years of architectural inefficiency As these pressures grow, the industry is rediscovering something earlier generations of technologists already understood: Efficiency matters. And ultimately: Sizing matters. This blog series is intended to explore both the history and the future of performance engineering, capacity planning, and system sizing. The first blog — this one — focuses on how the industry arrived where it is today: the Scarcity Era of computing the transition into abundance the rise of cloud abstraction and the re-emergence of constraints in the modern AI era Future blogs will move from theory and history into practical engineering. They will examine modern system architectures and explore the many bottlenecks that organizations often overlook, including: CPU saturation memory pressure NUMA effects storage latency queue depth issues network bottlenecks virtualization overhead cloud inefficiencies database scaling challenges and workload contention patterns The series will also discuss methods for properly monitoring, modeling, tuning, and sizing these environments. Because the scope of the subject is so large, future entries will likely be broken into multiple specialized blogs by technology area. Some topics may themselves require multi-part deep dives. About the Author I started my career in technology in 1978 working on a Basic Four-computer system during the early years of enterprise computing. Over the decades, I have worked across operations, engineering, architecture, product management, database performance tuning, and large-scale infrastructure analysis. I have architected sizing and performance analysis tools for technology vendors, worked internationally on database and infrastructure performance engagements, and spent much of my career focused on understanding how systems behave under real-world workloads. My background includes extensive work with Oracle technologies, enterprise performance tuning, workload analysis, and capacity planning across multiple industries and platforms. Today, I am employed at Everpure as a Field Solution Architect specializing in Oracle technologies and performance engineering. Having worked through the mainframe era, distributed systems revolution, virtualization, cloud computing, and now the rise of AI infrastructure, I believe the industry is once again approaching a point where operational discipline, efficiency, and proper sizing will become critical engineering skills. This series is both a technical discussion and a historical perspective from someone who has watched these cycles evolve over nearly five decades. The Lost Art of Sizing Part I — The Scarcity Era In the late 1970s, I started my career in technology. My first roles were in operations, running jobs on mainframes overnight and performing backups. Over time, I moved throughout the IT organization before eventually transitioning into engineering and product management in the late 1980s. I often refer to the 1970s and early 1980s as The Scarcity Era of computing. During that time, computing resources were extraordinarily expensive: Storage could cost the equivalent of hundreds of thousands of dollars per gigabyte Memory was frequently measured in tens or hundreds of thousands of dollars per megabyte CPU performance was discussed in terms of MIPS (Millions of Instructions Per Second), with systems delivering only a handful of MIPS costing millions of dollars Every component in the system represented a major financial investment. Because resources were scarce and expensive, sizing was treated almost as a science. Capacity planning was not optional — it was foundational to the survival of the business. Over-sizing a system could waste enormous capital. Under-sizing it could bring critical business operations to a halt. Every byte mattered. Every CPU cycle mattered. Every disk spindle mattered. This environment created a culture of discipline: Applications were optimized aggressively Developers understood resource constraints Operations teams monitored utilization closely Architects carefully modeled workloads Performance engineering was considered a core technical skill In many organizations, some of the best engineers were the people who could make systems smaller, faster, and more efficient. Software engineering was deeply connected to hardware realities. You could not simply “add more servers.” There often were no additional servers to add. This scarcity shaped an entire generation of technologists. Part II — The Abundance Era Then something extraordinary happened. Beginning in the late 1980s and accelerating through the 1990s and 2000s, the economics of computing changed completely. Moore’s Law, semiconductor scaling, manufacturing efficiencies, and global supply chains created an era of unprecedented abundance. For nearly forty years: CPUs became exponentially faster Memory became dramatically cheaper Storage costs collapsed Networks became faster Virtualization increased utilization Cloud computing made infrastructure appear almost limitless For the first time in computing history, performance improvements arrived faster than software inefficiencies could consume them. This fundamentally changed engineering culture. Disciplines that had once been mandatory slowly became optional. Applications no longer had to be highly optimized because hardware improvements continuously masked inefficiencies. Instead of tuning software, organizations increasingly solved problems by purchasing more infrastructure. A new mindset emerged: Hardware is cheaper than engineering time. And for many years, that was largely true. The rise of virtualization and cloud computing accelerated this transition even further. Infrastructure became abstracted from the engineers writing the software. Developers no longer saw physical systems, disk arrays, or memory limitations. Resources became API calls and provisioning scripts. Eventually, many organizations evolved toward a model where applications were simply “thrown over the wall” into the cloud. If performance was poor: allocate more CPUs add more memory scale horizontally increase cloud spending The business unit would absorb the cost. The direct connection between engineering decisions and infrastructure economics became increasingly invisible. In many environments: poor code was tolerated inefficient queries were normalized oversized containers became standard massive memory consumption was accepted idle cloud resources accumulated unchecked Traditional sizing disciplines faded because the financial pain was no longer immediate or visible to the engineering teams creating the workloads. The cloud did not eliminate capacity planning — it merely changed who paid for bad sizing decisions. In the mainframe era, poor sizing decisions were catastrophic because hardware was scarce. In the cloud era, poor sizing decisions became operational expenditures hidden inside monthly invoices. The result was a generation of systems that often consumed vastly more resources than their actual business function required. Ironically, many of the operational disciplines developed during the Scarcity Era were not technically obsolete — they had simply become economically unnecessary for a time. But that may now be changing again. Part III — The Return of Constraints For nearly four decades, the technology industry operated under a powerful assumption: Tomorrow’s hardware would solve today’s software problems. For a long time, that assumption held true. If an application consumed too much CPU: processors became faster If memory usage grew: RAM became cheaper If storage exploded: disk costs continued collapsing If workloads increased: cloud platforms scaled almost infinitely The economics of computing continuously compensated for inefficient engineering. But today, something significant is changing. The industry is beginning to encounter limits again. Not theoretical limits — real economic, physical, and operational limits. Modern computing infrastructure is no longer getting dramatically cheaper at the rate it once did. Instead, we are seeing: exploding GPU costs rising power consumption thermal limitations expensive high-bandwidth memory enormous cloud infrastructure bills increasingly expensive semiconductor fabrication AI workloads consuming unprecedented resources For the first time in decades, inefficient software design is becoming economically visible again. And this has exposed a reality that many organizations had quietly ignored for years: poor code oversized architectures inefficient databases excessive abstraction layers uncontrolled cloud sprawl wasteful microservice designs badly tuned queries overallocated Kubernetes clusters massive idle infrastructure footprints For years, these inefficiencies were masked by cheap hardware and elastic cloud scaling. Now they are appearing directly on financial statements. The cloud did not eliminate waste. It made waste easier to hide. Until the bills became too large to ignore. At the same time, another challenge has emerged. Many of the people who developed the operational disciplines of the Scarcity Era are no longer in the industry. They have: retired moved into leadership transitioned into consulting or left technology entirely The generation that deeply understood: workload modeling performance engineering memory optimization queue management efficient batch processing storage layout capacity forecasting low-level tuning is steadily disappearing. Much of that knowledge was never fully documented because it was simply considered part of being an experienced engineer. As a result, many younger organizations grew up in an environment where: infrastructure felt unlimited optimization seemed unnecessary cloud scaling replaced careful design operational cost was someone else’s problem Now the industry faces a difficult transition. The old constraints are returning, but many of the disciplines required to manage those constraints have faded. In many ways, the industry is rediscovering something that earlier generations of technologists already understood: Resources are never truly infinite. Eventually: power matters memory matters storage matters latency matters thermal density matters architecture matters And ultimately: sizing matters. The art of sizing has returned. Not because technology stopped advancing, but because economics, physics, and scale have once again forced the industry to confront efficiency. What was once viewed as an outdated operational skill may soon become one of the most important engineering disciplines again. Part IV — History Does Not Repeat, But It Rhymes What we are seeing today in technology is historically unusual — but it is not entirely unprecedented. Other industries have gone through similar transitions where periods of explosive advancement, falling costs, and seemingly limitless growth eventually collided with economic and physical realities. The railroad industry is one example. In the early days of rail expansion during the Industrial Age, railroads transformed economies. Expansion happened rapidly. Costs initially fell as infrastructure scaled, routes expanded, and technology improved. For a time, railroads represented nearly unlimited economic optimism. But eventually the easy growth ended. The cost of expanding and maintaining rail infrastructure began rising dramatically. Marginal improvements became more expensive. Complexity increased. Maintenance became a larger percentage of operating cost. Competition intensified. Returns diminished. The industry did not disappear. In fact, railroads remained enormously valuable to the economy. But the economics changed. The same pattern appeared in other industrial and technological revolutions: aviation after the jet age nuclear power generation telecommunications infrastructure automobile manufacturing even electrical grid expansion Early stages were driven by rapid gains and falling relative costs. Later stages became dominated by: scale complexity infrastructure costs power requirements operational efficiency regulation and diminishing economic returns on incremental improvements Technology did not stop advancing. It simply became harder, more expensive, and more complex to continue advancing at the same pace. That is increasingly where modern computing appears to be heading. We are now entering the Age of AI. AI will absolutely create enormous value. In many ways, it already has. But there is growing evidence that the economics of this era are going to be very different from the cloud and consumer internet revolutions that preceded it. AI infrastructure is extraordinarily expensive: massive GPU clusters enormous power consumption advanced cooling systems high-bandwidth memory increasingly expensive semiconductor fabrication global supply chain dependencies For years, the technology industry operated almost like a perpetual motion machine where computing became continuously cheaper while performance improved exponentially. Today, the relationship between cost and performance is changing. That does not mean AI is a failure. Far from it. But technological revolutions are not light switches. They are transitions. And transitions are messy. Industries often overspend before they stabilize. Architectures evolve through trial and error. Infrastructure expands ahead of efficient utilization. Economic models mature slowly. The railroad era experienced this. The electrical age experienced this. The internet boom experienced this. And now AI appears to be entering a similar phase. The challenge for the next generation of technologists will not simply be building larger systems. It will be learning how to build efficient, economically sustainable systems again. Which may ultimately bring the industry back to a lesson many believed had become obsolete: The art of sizing never really disappeared. It was merely waiting for constraints to return.307Views1like0CommentsWhen Data Becomes the Mission
Why state and local government, cities, and research universities are reorganizing infrastructure around data itself If you remember one thing from this article: infrastructure used to organize around applications. Increasingly, now it organizes around data. If you spend enough time around enterprise infrastructure, you start to notice something about how conversations begin. Someone asks about storage. Not in a philosophical way. In a practical way. How much capacity do we have left? What’s the refresh cycle? Is this staying on premises or moving to cloud? What’s the backup strategy? For years, that framing made perfect sense. Infrastructure was the foundation, and the job of infrastructure teams was to keep the lights on and the foundation solid. But lately, in conversations with customers across state and local government, municipalities, cities, and universities, something feels different. Because eventually someone says something like this: “We have this data… but we can’t actually use it.” And that is when the real conversation begins. Why the public sector reveals the truth about data There’s a perspective I heard recently that stuck with me. The public sector isn’t a niche market. It’s a microcosm of the entire enterprise technology world. At first that sounds counterintuitive. The stereotype is that government IT has been quietly living under a rock since the previous century, next to a beige server and a stack of COBOL manuals. But if you look closely, the opposite is true. State agencies, cities, and research institutions operate in environments that combine nearly every architectural challenge the private sector faces — all at once. Massive datasets Highly distributed users Strict security requirements Long retention policies Global collaboration And an absolute requirement that systems remain available when people need them most. In other words, the public sector experiences the full spectrum of data challenges simultaneously. If you want to stress-test a data architecture, put it inside government. Think about it. A state government may run thousands of systems across dozens of agencies, each serving different missions but increasingly sharing the same underlying data. A city manages infrastructure at the physical edge of society — traffic, water, SCADA, emergency services — where real-time decisions depend on accurate information. Universities generate some of the largest research datasets on earth while collaborating across institutions and countries. Each of these environments demands something slightly different from infrastructure. But they all demand the same thing from data: Security. Integrity. Mobility. Context. Availability. And when those requirements collide in one environment, something interesting happens. The solutions that work there tend to work everywhere. A laboratory for the modern data enterprise This is why many technology leaders quietly view the public sector as something more than a vertical market. It’s a laboratory for enterprise-scale data architecture. If a platform can operate in a world where: sensitive personal data must remain protected • systems span thousands of locations • regulatory oversight is constant • and uptime has real public consequences …then that architecture will almost certainly succeed in commercial environments. Banks, manufacturers, healthcare providers, and global enterprises face the same challenges. Just rarely all at once. Government simply compresses those problems into a single environment. Solve the data problem for government, and you solve it for the enterprise. That’s one reason the shift toward data-centric platforms is becoming so important. When organizations treat infrastructure as a place to store files, they solve only a small part of the problem. But when they treat data as the central operational asset — something that must be understood, governed, protected, and made usable across environments — the architecture begins to look very different. And the public sector, with all its complexity, becomes the place where those architectures are tested first. Which brings us back to the shift we’re seeing across the industry. Because once you start looking at infrastructure through the lens of data itself, something else becomes obvious. The center of gravity has moved. When multiple systems depend on the same dataset, the data becomes part of the operating foundation. And once that happens, moving it — or even restructuring it — becomes dramatically harder. Which brings us to the concept that explains a lot of what is happening right now. The quiet physics of data gravity The first time I heard the term “data gravity” wasn’t in a conference keynote or a vendor presentation. It was in 2015, when a recruiter from a startup called DataGravity (now Anomalo) reached out and asked if I would be interested in interviewing. At the time, the idea sounded fascinating — and slightly theoretical. The company was built around the premise that data itself was becoming the most valuable asset in the data center, and that infrastructure needed to understand the content, context, and behavior of data, not just store it. The name alone hinted at something deeper: the idea that as datasets grow, they start exerting a kind of gravitational pull on the systems around them. Back then, it felt like an interesting concept. Today it feels like a description of reality. The term “data gravity” itself was introduced by Dave McCrory back in 2010, and it turns out to be a remarkably accurate way to describe modern infrastructure. Dave McCrory Blog The idea is simple. As datasets grow, they become harder to move. More applications depend on them. More workflows connect to them. More policies govern them. Eventually, the architecture starts organizing around the data itself. Not because someone designed it that way. Because the physics of large systems leave you very little choice. Imagine trying to relocate a state Medicaid dataset that has been integrated with multiple benefit programs, identity verification systems, and fraud detection tools. Technically possible? Sure. Operationally trivial? Not even close. The larger and more interconnected the dataset becomes, the stronger its gravitational pull. Compute moves closer to the data. Applications move closer to the data. Infrastructure reorganizes around the data. This is why organizations that once talked primarily about storage capacity are now talking about data platforms. The center of gravity moved. When data stops being passive The moment data becomes operational, everything changes. For years, most organizations treated data as something that accumulated quietly inside systems. Applications produced it. Storage kept it safe. Backups made sure it could be restored. But that model starts to break down when the data itself becomes part of real-time decision making. You can see this most clearly in environments that generate enormous volumes of information. Cities now run infrastructure that continuously streams telemetry — traffic sensors, utility meters, environmental monitors, emergency response platforms. A water meter that once reported usage once a month might now generate thousands of readings per year. A traffic system that once relied on static timing can adapt dynamically to real-time conditions. Each improvement creates more data. More importantly, it creates operational dependence on that data. Universities experience the same phenomenon in a different form. Research environments produce extraordinary datasets across genomics, climate science, and artificial intelligence. Sequencing a single human genome generates roughly 100 gigabytes of raw data, and large research programs may create terabytes or petabytes of new information every week. In those environments the challenge isn’t just storing data. It’s feeding it fast enough to the systems that depend on it. Modern research clusters and GPU environments can process enormous volumes of information, but only if the underlying data pipeline keeps up. When storage cannot deliver data fast enough, expensive compute resources sit idle and discovery slows down. And that reveals an important truth about modern infrastructure. When systems depend on data in real time, the question stops being where the infrastructure lives. The question becomes whether the data is available, trustworthy, and recoverable. That distinction also explains why ransomware has become so disruptive to public institutions. Attackers understand that the real leverage is not the servers or the network. It’s the data. When access to data disappears, the services built on top of it disappear as well. Which brings us back to the deeper shift happening across the industry. If data has become this central to operations, services, and discovery, then managing it as a passive byproduct of infrastructure is no longer enough. Infrastructure alone is no longer the strategic layer. The strategic layer is the data itself. Organizations still need performance, availability, and resilience. Those fundamentals have not changed. What has changed is the expectation that infrastructure should also help organizations understand, govern, protect, and use their data more effectively. That is a very different problem than simply storing it. And it is the reason the conversation is evolving from storage management to data management platforms. The real punch line Public sector organizations didn’t set out to become data enterprises. Over time the data accumulated. Then the dependencies formed. And eventually everything started orbiting the datasets that mattered most. Data has gravity. Data has risk. Data has power. Infrastructure still matters. But increasingly, the real mission is something else entirely. The mission is the data. Appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere302Views0likes0CommentsBoosting SQL Server Backup/Restore Performance: Threads and Parallelism
In this post, we’ll discuss day 1 tuning you can do on your database hosts to take full advantage of your new high-performance backup storage. We’ll go over a few tricks around database layout and backup configuration for maximum throughput, discuss some quirks with SMB, and finally discuss using S3 effectively.300Views1like0Comments
SQL Server on Kubernetes - Faster, Safer Database Operations
April 16 | Register Now! Running SQL Server in containers can speed up provisioning and customization. But standalone containers lack the high availability and data services that enterprises require, making Kubernetes essential for resilient environments. Portworx® by Everpure extends Kubernetes with enterprise-grade data services—such as volume cloning—to reliably run stateful workloads like SQL Server and simplify database lifecycle management. In this session, we’ll demonstrate how to modernize SQL Server while improving resilience, flexibility, and operational efficiency. Key Takeaways How to deploy and operate SQL Server on Kubernetes with built‑in resilience and scalability How to migrate SQL Server from Windows-based environments and explore KubeVirt as an additional deployment option How Portworx data services simplify SQL Server database management, testing, and recovery Register Now300Views0likes0Comments