Your Last Line of Defense: Everpure + CrowdStrike: Active Defender in Action
October 20 | Register Now AI attacks breach in 29 minutes, driving ransomware toward $74B, while 90% of logs sit invisible in cold tiers*. See how Everpure and CrowdStrike Falcon® bring together visibility, intelligence, investigation, and automated response to turn storage into an active defender. Key takeaways: Extensive CrowdStrike and Everpure integrations: How Falcon NG-SIEM (visibility), Threat Graph (intelligence), Falcon LogScale (investigation), and Fusion SOAR (response) cover the full detect-to-remediate lifecycle. Closed-loop architecture: How telemetry, normalization, triage, and SOAR action combine so storage events become one continuous detection-to-response loop. Speed to containment: How Fusion SOAR turns a FlashArray™ or FlashBlade® detection into containment action within seconds, not hours. *(Source: 2026 CrowdStrike Global Threat Report) Register Now!154Views0likes0CommentsBeyond Awareness: Awareness Won't Save You, Recovery Will
October 15 | Register Now AI has compressed breakout times to minutes, exposing the gap between knowing you're at risk and recovering from it. Rick Orloff, CISO, and Chris Brandt, Consulting Field Solutions Architect, show why resilience, not awareness, decides survival, and how to build the active-defender architecture that closes the gap. We’ll cover: Worse than expected — how the AI threat has grown dramatically in 2026. Backup vs. cyber recovery, and why you need a tested "minimum viable business" plan. How storage becomes an active defender: built-in security, connected detection, dynamic recovery. A real Fortune 100 recovery story showing resilience in action when prevention fails. Register Now!73Views0likes0CommentsPurity//FB 4.8.6 FR has released
We are happy to announce the general availability of 4.8.6, the seventh Feature Release in the 4.8/4.9 line, helping customers move from managing storage to managing their data, with governance that enforces itself, a fleet that runs as one, and real-time insight that keeps critical workloads performing, all with less manual effort and less risk. See the release notes for all the details about the features and improvements included in this release.45Views0likes0CommentsOne Year of “Ask Us Everything”: John “Coz” Colgrove on Everpure’s Past, Present, and Future
A special Ask Us Everything anniversary conversation with Everpure cofounder John “Coz” Colgrove explores Everpure’s origins, technical innovations, AI, and the future of data management.48Views0likes0CommentsEnabling Agentic AI via Pure1 Manage MCP Server
Everpure now offers a Pure1® Manage MCP Server so you can query information about your fleet using natural language questions. In this post, I’ll explain how the Pure1 Manage MCP Server works. The first section will explain MCP in general, and the second section will explain how to use our specific server. Feel free to skip to the Quick Start section if you’re already familiar with MCP and just need the parameters to plug into your host. What is MCP? MCP stands for "Model Context Protocol," and it's a way for users to connect their AI applications to external systems using tool calls. MCP tools are fundamentally rooted in application programming interfaces (APIs). An API is a set of rules and protocols that allows different software applications to communicate with each other. It acts as an intermediary, enabling one piece of software (the client) to request information or functionality from another piece of software (the server) without needing to know the server's internal workings. For instance, when you check the weather on your phone, the weather app uses an API to send a request to a weather service, which then returns the current weather data. AI applications have trouble making API calls directly because APIs are designed for completeness and correctness, not for an LLM to use easily. When an AI application wants to use an external system to handle a user’s request, it uses the MCP protocol to make a tool call. The AI (client) requests a function (the tool) from an external system (the server), and the system executes the function and returns a result. This makes MCP a system that standardizes and mediates API-like interactions, allowing AI models to leverage external, real-world capabilities. For more information, see this article on the MCP website: “What is the Model Context Protocol (MCP)?” How can customers benefit from the Pure1 Manage MCP Server? The Pure1 Manage MCP Server enables customers to securely integrate AI assistants, copilots, and agentic systems with live Pure1 telemetry and operational data—without building custom API integrations. It transforms Pure1 from a dashboard-centric experience into an AI-accessible platform, enabling natural language interaction, contextual automation, and real-time operational intelligence. Customers benefit from faster AI integration, reduced engineering effort, preserved security controls, and improved decision velocity across hybrid environments. What types of customer workflows are best suited for MCP? The Pure1 Manage MCP Server is particularly well-suited for agentic and AI-driven workflows, including: Fleet telemetry integration with customer copilots Expose Pure1 telemetry—arrays, volumes, workloads, metrics, and alerts—into internal copilots, chatbots, or AI platforms via MCP endpoints. Value: Unified operational visibility across hybrid and multi-platform environments Automation with context awareness Use MCP to validate storage state, health, performance, or capacity before executing provisioning, backup, or disaster recovery workflows. Value: Safer automation with contextual validation, reduced execution errors, and greater rollback confidence Hybrid cloud observability Correlate Everpure array performance and capacity metrics with application, VM, container, or cloud telemetry across environments. Value: Faster troubleshooting and improved end-to-end performance insights Conversational operational analytics Enable operators to ask real-time natural language questions, such as: “Which arrays are nearing capacity risk?” “Show me the top latency spikes in the last 24 hours.” “Summarize all critical alerts across regions.” Value: Rapid insight without navigating dashboards or exporting reports What the Pure1 Manage MCP Server can do The Pure1 Manage MCP Server exposes the Pure1 Manage REST APIs to AI applications. This means you can ask ad hoc questions about your fleet using natural language, and your AI application will use the server’s tools to query the answer. No programming required. Example conversation Here’s an example conversation demonstrating the use of the Pure1 Manage MCP Server: User: "What is the name of my oldest FlashArray and what is its serial number?" Chatbot:Processing Request: The AI recognizes this as a request for fleet information requiring a tool call. Tool Invocation: Get_hardware Response: The oldest FlashArray in your fleet is named FA-Prod-01 with serial number FA10123456. User: "Can you show me the average I/O latency for that array over the last 7 days?" Chatbot: Let me first check the available latency metrics, then query the historical data: Tool Invocation: Get_metrics Tool Invocation: Get_metrics_history Response: The average I/O latency for FA-Prod-01 (serial FA10123456) over the last 7 days was 0.385 milliseconds. User: "How many arrays do I have in total that are still under warranty?" Chatbot: Processing Request: The AI recognizes this as a request for a count of arrays filtered by warranty status. Tool Invocation: Get_array_support_contracts Response: You currently have 12 arrays in your fleet that are still under active warranty. Quick start Step 1: Register an API key in Pure1 Manage The Pure1 Manage MCP Server leverages the Pure1 Manage REST APIs. In order to access those APIs, you need to register an API key in Pure1 Manage. To do that, follow the directions in the The Pure1® REST API introductory blog post. After going through the instructions, you will have an application id and a private key file, which will be used to generate an access token to access the MCP server in step 2. Step 2: Set up the pure1_token_factory.py script Prerequisites: you need Python 3.12 or greater to run the script. Download pure1_token_factory.zip. Unzip the archive. Go to the unzipped folder in your command-line terminal. Optional but recommended: create and activate a Python virtual environment: python3 -m venv .venv source .venv/bin/activate Install the requirements: pip3 install -r requirements.txt. Run python3 pure1_token_factory.py <application_id> <private_key_file> Copy the generated access token from the script output for the next step. Step 3: Add remote MCP server to your AI application Follow the directions for your AI application to add a remote MCP server (see the Pure1 Manage MCP Server User Guide for instructions for specific chatbots). In general, they need the following information: Remote MCP Server address: https://api.pure1.purestorage.com/mcp Authorization type: header Header name: Authorization Header value: Bearer <access-token> Important: <access-token> is just a placeholder for the access token you generated in step 2. The actual header value should look something like “Bearer eyJ0eXAiO…” Important: you need to generate a new access token every 10 hours and copy it into your AI application You’ll need to run pure1_token_factory.py to generate a new access token every 10 hours, and manually copy the access token into your AI application’s config. Claude Desktop instructions Claude Desktop is a special case because it doesn’t let you set the Authorization header directly. You have to run the mcp-remote local MCP server and configure that to use the Pure1 Manage remote MCP server. Prerequisites You need to have Node.js version 18 or newer installed on your system. Configuration In Claude Desktop, go to Settings > Developer, and click Edit Config. Open the claude_desktop_config.json file in a plain-text editor like VS Code. Configure the mcp-remote server, which is necessary to pass the Authorization header to the Pure1 Manage MCP Server. Paste the token into the configuration file, then restart Claude Desktop. { "mcpServers": { "Pure1 API": { "command": "npx", "args": [ "-y", "mcp-remote", "https://api.pure1.purestorage.com/mcp", "--header", "Authorization:${AUTHORIZATION_HEADER}" ], "env": { "AUTHORIZATION_HEADER": " Bearer <paste access token here>" } } } Note: there might be other configuration options in this file. Be sure to leave them unchanged, and only insert the Pure1 API config in the mcpServers section. The space in the AUTHORIZATION_HEADER environment variable is important. It's there to work around a bug in Windows argument parsing. Please note that: The first time it uses a tool, it will ask you for permission. You can grant permission to all tools at once by going to Customize > Connectors > Pure1 API, and selecting Always Allow under Other tools. For more detailed instructions from Anthropic, please refer to: Connect to local MCP servers - Model Context Protocol.819Views1like0Comments
Using Pure1 AI Copilot to Assess CVE Exposure and Get Upgrade Recommendations
Fleet Security Assessment The Pure1 Fleet Security Assessment provides a fleet-wide view of the security posture of FlashArray and FlashBlade systems by correlating each asset's current software version against Everpure's curated CVE database. Determine whether an asset is exposed to a known CVE A storage administrator can: Log into Pure1. Navigate to Fleet Security Assessment. View all registered arrays within the fleet. For each array, Pure1 automatically identifies: Current Purity version Product family (FlashArray / FlashBlade) Array Name Array ID Serial Number Pure1 compares the running Purity version against the Everpure Product Security Advisory database and determines: Whether the version is affected by known CVEs. Severity of each vulnerability (Critical, High, Medium, Low). Whether a fix is available. Whether a workaround exists. Whether the CVE affects the customer's specific product. Selecting an individual array allows the administrator to review: CVE ID CVSS Score Severity Description Affected component Security Bulletin Fixed version Mitigation guidance This enables administrators to quickly prioritize remediation activities based on risk across their entire storage estate. Using AI Copilot AI Copilot provides a conversational interface to the same security intelligence, allowing administrators to ask questions in natural language rather than navigating multiple dashboards. Examples include: "Is array FA-01 exposed to any critical security vulnerabilities?" Another example: "Which arrays in my fleet are exposed to critical CVEs?" Administrators could also ask: "Show me every FlashBlade affected by OpenSSH vulnerabilities." or "Which arrays are running unsupported Purity versions?" Intelligent Upgrade Recommendations Rather than simply identifying vulnerable arrays, AI Copilot can also recommend an upgrade. AI Copilot will go beyond security and determine whether the array is actually ready for upgrade. Example prompt: "Can I safely upgrade FA-01 to Purity 6.9.4?" AI evaluates: Hardware compatibility Controller generation Installed DirectFlash modules Current Purity version Intermediate upgrade requirements Known upgrade restrictions Health status Replication configuration SafeMode Supportability Current alerts Capacity utilization Pending hardware failures Replication synchronization Outstanding upgrade blockers And determines the most appropriate version based on the customer's environment based on customer’s Current Purity version Current LLR Current ER Security vulnerabilities Feature requirements Hardware support Known software defects Current advisories Upgrade path complexity Engineering recommendations Customer support policy Example: Users could ask: "What version should I upgrade to?" Fleet-wide Upgrade Planning AI could also answer strategic questions such as: "Show every array requiring a security upgrade."or "Which arrays should be upgraded in the next 30 days?" Conclusion The integration of Pure1 Fleet Security Assessment and AI Copilot fundamentally transforms storage security management from a reactive, manual task into a proactive, data-driven strategy. By providing deep visibility into CVE exposure across the entire fleet and delivering intelligent, context-aware Purity upgrade recommendations, Pure1 empowers administrators to mitigate risks before they can be exploited. This shift to strategic fleet planning ensures that storage environments remain resilient, compliant, and optimized, allowing organizations to focus on innovation rather than crisis management.213Views0likes0Comments
The Art of Sizing: Breaking the Myths of Oracle Compression
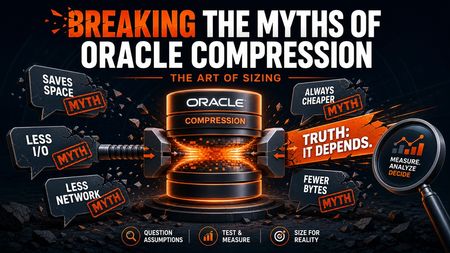
If you work in storage or databases, you have probably heard the pitch: turn on Oracle compression, send fewer bytes, save space, reduce I/O, and lower cost. That sounds great on a slide. In the real world, it is often the opposite. This installment of The Art of Sizing breaks down one of the most persistent myths in enterprise infrastructure: that Oracle host-based compression is automatically a win. We are going to walk through the major compression types, where they help, where they hurt, and why the wrong compression decision can actually create more cost, more network traffic, more I/O, and more work for both storage admins and DBAs. The goal is not to say compression is bad. The goal is to size it correctly, understand where it belongs, and avoid paying premium dollars to make your systems do extra work. Why this myth survives Compression has a good reputation for a reason. Historically, it solved real problems. Storage was expensive, bandwidth was limited, and shrinking data was often the simplest path to efficiency. That logic still holds in some places. But in Oracle environments, especially transactional ones, the story gets more complicated. Oracle is not just writing datafiles. It is writing redo, managing undo, reorganizing blocks, updating symbol tables, and sometimes re-processing data later for deeper compression. That means a “smaller data footprint” does not always equal a smaller infrastructure burden. Sometimes it just shifts the burden somewhere else. First, let’s separate the compression families Not all compression is the same, and not all of it behaves the same way in Oracle. 1. General lossless compression This is the classic world of ZIP, GZIP, LZ77, LZ78, DEFLATE, ZSTD, and similar algorithms. The point is simple: reduce size without losing information. These methods are excellent for files, backups, archives, and many data services. Modern storage platforms use fast versions of these ideas in ways that are largely invisible to the application. 2. Lossy compression Think JPEG, MP3, MPEG, and H.264. These formats intentionally throw away some data in exchange for dramatic size reduction. They are incredibly effective for media, but they are not relevant for Oracle datafiles because databases generally require exact fidelity. 3. Oracle database compression This is where the confusion starts. Oracle has several different compression approaches, each with different behavior, licensing implications, and performance trade-offs: - Basic Table Compression - Advanced Row Compression - Advanced Index Compression - SecureFiles LOB Compression - Hybrid Columnar Compression - RMAN Backup Compression - Automatic Data Optimization and ILM-driven background re-compression Lumping all of those together under “Oracle compression” is one of the fastest ways to make bad architecture decisions. The big myth: compressed writes mean less work Here is the myth in plain English: If Oracle compresses the data before it sends it to storage, the network carries fewer bytes, the array writes less data, and the whole system gets more efficient. What that myth ignores is the full lifecycle of an Oracle write. In active transactional systems, Oracle prioritizes commit latency. That means the redo stream is written first, and it is written uncompressed. Later, as blocks fill and thresholds are crossed, Oracle may compress or re-compress them in memory. That structural change can generate additional redo. If data is later pushed into deeper formats through background optimization or archive-style compression, the system may read, process, and write the same data again. So yes, one part of the path may get smaller. But the total system effort often gets bigger. Figure 1: The life of a compressed I/O inside Oracle (OLTP write path). Notice that data is NOT compressed when it first travels to storage as redo, that write amplification happens at the threshold-hit step, and that this is where the footprint can start to grow. How to actually see it happening This is the part both DBAs and storage admins care about: how do you know Oracle is revisiting blocks, delaying compression, and generating extra work after the commit already succeeded? The threshold delay, in plain English With Advanced Row Compression, Oracle does not usually compress every row the moment it is inserted. Instead, rows are typically written into the block uncompressed first so Oracle can keep transactional latency low. Oracle keeps watching the remaining free space in that 8KB block. Once the block crosses an internal fullness threshold, Oracle goes back, builds or updates the symbol table, batch-compresses the block in memory, and then has to account for that structural change. That delayed work is what I mean by the threshold delay. So the timeline looks more like this: user writes data Oracle writes redo for durability commit returns quickly the block stays in buffer cache the block fills further threshold is crossed Oracle compresses or re-compresses the block in memory additional redo and block maintenance activity can follow That is why the system can look quiet at commit time and then busy again later. How you can tell Oracle is "redoing" things You are usually not looking for one giant smoking gun. You are looking for a pattern where post-commit activity does not line up with the simple story of "we wrote it once and moved on." Common signs include: redo generation that seems higher than expected for the amount of business data changed continued redo and log write activity after the original insert burst is over CPU spikes around block maintenance rather than just around user SQL periodic write bursts that do not line up cleanly with front-end transaction volume maintenance-window bandwidth spikes when colder data is being reworked into deeper compression formats storage-side churn where the array still sees a lot of activity even though the data was supposedly "compressed already" At the database layer, the giveaway is often the mismatch between application change volume and the total work observed in redo, background activity, and later data movement. At the storage layer, the giveaway is seeing traffic patterns that look like read-process-write loops rather than a single smooth write path. Why the database can get larger after a few days This confuses a lot of people because they expect compression to make the footprint immediately smaller and keep it smaller. Figure 2: The background ADO/HCC re-compression path. Days or weeks after the initial write, background jobs read cold data off the array, re-process it on the host, and write it back, so segments can grow from extra redo, undo, rewritten copies, and unreclaimed space. But Oracle compression can create delayed growth behaviors for several reasons: new rows may land uncompressed first and only later be reorganized recompression work can generate extra redo and undo background optimization jobs may read old blocks, reorganize them, and write new versions back out old extents may not be reclaimed immediately even after data is moved or rewritten free space inside segments may become fragmented in ways that do not instantly shrink the physical files if data is updated repeatedly, blocks can split, migrate, or be rewritten in ways that increase segment size before any long-term savings appear So what looks like "compression should have made this smaller" can become "the system created more structures, more history, and more rewritten copies before it settled down." For storage admins, this often shows up as a database that writes out one size on day one and then consumes more logical or physical space over the next several days as Oracle continues block maintenance, redo generation, archive activity, and background reorganization. The practical operator lesson If you want to understand whether compression is helping or hurting, do not just compare the first write size to the final stored size. Instead, look at the full lifecycle: initial redo volume later redo spikes buffer-cache and CPU behavior around block fullness archive log growth background maintenance windows segment growth over time instead of only at load completion storage bandwidth and write churn several days after the original ingest That is where the threshold delay becomes visible. That is where the myth breaks. Why host-based compression can cost more money This is where The Art of Sizing matters most. Compression is often sold as a capacity story, but in Oracle it can quickly become a licensing and CPU story. Advanced Row Compression and SecureFiles LOB Compression are paid features. That means you are not just paying in cycles, you may be paying in Oracle licensing. And if compression overhead pushes CPU consumption higher, you may end up needing to license more cores just to preserve the performance you had before. That is a brutal trade: - You pay for the compression feature. - You spend host CPU running the compression feature. - You may need more licensed cores because of the compression feature. - You still do not eliminate redo overhead. At that point, “saving space” can become one of the most expensive optimizations in the stack. Why it can create more network traffic This is the part that surprises people. On transactional writes, the redo stream still moves as uncompressed change data so Oracle can preserve low-latency commit behavior. That means the initial transactional path does not magically shrink just because the table eventually lands in a compressed state. Then the hidden traffic starts: - secondary redo generated when blocks are compressed or re-compressed - additional log activity to track structural changes - background movement when colder data is reorganized into deeper compression formats - read-process-write cycles for jobs like ADO or HCC-related maintenance For the SAN, that can mean less of a neat “compressed payload” story and more of a churn story. Why it can create more I/O Storage admins know this instinctively: once a system starts revisiting the same data repeatedly, the theoretical savings usually get eaten by operational noise. That is what can happen here. A write is not always a single write anymore. It can become: - the original transactional activity - redo logging for durability - later in-memory compression work - secondary redo for compression state changes - future background read-and-rewrite operations for deeper compression That is not reduced work. That is redistributed work, with extra steps. For busy OLTP systems, that redistribution can show up as more write amplification, more jitter, and more performance variance than people expected when they first heard the word “compression.” Why it creates more operational work Compression decisions do not just affect hardware. They create administrative drag. DBAs have to understand which compression mode is active, what is licensed, what is free, what silently triggered usage, and how it affects redo, CPU, and maintenance windows. Storage admins have to explain why the array still sees redo churn, why bandwidth spikes appear during data reorganization, and why dedupe or downstream efficiency may not look the way a simplified Oracle story suggested. And everyone gets more work when performance troubleshooting starts with a bad assumption. A quick breakdown of the Oracle compression types Basic Table Compression Good for bulk loads and relatively static datasets. It is not a magic answer for active transactional workloads because standard ongoing DML does not benefit the same way. Advanced Row Compression This is the big one in OLTP discussions. It supports active transactional operations, but it is also where deferred compression, block threshold behavior, secondary redo, and paid licensing can combine into a very expensive surprise. Advanced Index Compression Useful in the right indexing scenarios, especially with repetitive keys. This is more targeted and usually not the villain in the story, but it still needs to be understood separately from table compression. SecureFiles LOB Compression Can reduce footprint for large objects like documents, JSON, XML, and similar content, but it pushes work onto host CPU and can throttle ingestion performance when volumes are high. Hybrid Columnar Compression Very powerful for analytics, archival, and cold data patterns. It is not designed like OLTP row compression, and it often belongs in a very different conversation. When used through background movement or deep reorganization, it can generate substantial read-process-rewrite churn. RMAN Backup Compression A separate discussion from live transactional compression. Useful when applied deliberately, but some algorithms can also introduce licensing implications. The sizing lesson This is the heart of the series. Do not size from the brochure claim. Size from the full path of work. When evaluating compression, ask these questions: - What happens on the initial write path? - What happens to redo? - What CPU tax lands on the host? - Does this feature introduce licensing cost? - Will background maintenance create bursts of read-write churn later? - Is the data really a good fit for host-side database compression, or would array-level reduction be cleaner? If you do not answer those questions, you are not sizing compression. You are just hoping it behaves the way marketing described it. Where compression often belongs instead For many environments, especially where modern storage platforms provide inline reduction, the cleaner design is to let the database do database work and let the array do storage work. Figure 3: Myth vs reality, where should compression live? Host-side compression adds CPU, redo, and license cost, while array-level compression keeps host writes normal and delivers predictable I/O with global dedupe. That changes the equation: - less host CPU consumed by compression logic - fewer surprises tied to paid database options - fewer extra redo side effects from re-compression behavior - more predictable storage-side efficiency - a simpler operational model for both DBAs and storage teams That does not mean every Oracle compression feature is wrong. It means compression should be placed where it creates the least total system friction. And in many real-world environments, that is not at the host. Final thought: compression is not free just because it saves space Compression can absolutely be part of a smart architecture. But if you only measure saved capacity and ignore processor cost, network churn, redo behavior, maintenance overhead, and operational complexity, you can easily end up paying more to store less. That is the myth this post is here to break. In The Art of Sizing, the best design is not the one with the smallest number on a capacity chart. It is the one that delivers the best total outcome across cost, performance, simplicity, and operational sanity. And when it comes to Oracle compression, that usually starts with asking a harder question: Is this actually reducing work, or just moving it somewhere more expensive? Coming next In the next installment, we will look at the relationship between compression and encryption in Oracle, and why that combination can further change what the storage team sees and what the database team pays for.144Views0likes0CommentsEnterprise Data Cloud: Managing Data, Not Just Storage
August 6 | Register Now Infrastructure teams have always managed applications. AI requires them to manage data. That's a different challenge, and most platforms weren't built for it. The Enterprise Data Cloud architecture from Everpure bridges that gap, bringing data intelligence into the same platform infrastructure teams already manage, so infrastructure and data teams are finally working from a single, unified view. In this session, we'll dig into what it means to manage a platform built for both operational performance and AI readiness, and the changes when infrastructure can finally gain visibility into its data, not just storage. Key takeaways: Why the shift from application-centric to data-first infrastructure changes how platforms need to be managed How Everpure brings data intelligence into the operational layer without adding tools, teams, or complexity What shared visibility across infrastructure and data teams actually unlocks for AI initiatives How to manage a platform that serves every workload, from archive to AI Register Now!219Views0likes0CommentsClaude Code as Database SRE: Catching What Your Monitoring Never Will with Everpure Fusion MCP
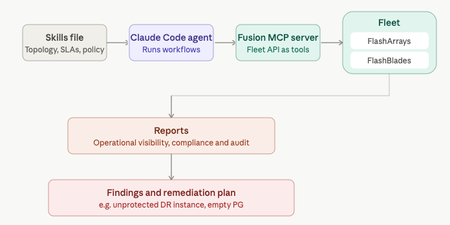
Your DR site might be quietly unprotected and no alert will tell you. That's the gap Anthony Nocentino, Principal Architect at Everpure, Microsoft Data Platform MVP, and self-described computer nerd set out to catch. He built a Database SRE agent using Claude Code and the Everpure Fusion MCP server to audit SQL Server fleets against compliance policy, uncovering a silently unprotected DR instance before disaster struck. Read the full report at "Using Claude Code as a Database SRE Agent with the Everpure Fusion MCP Server"69Views0likes0Comments
Flashblade with Splunk OTEL
Hi Team, I have FBS100 in lab environment and Splunk Observability cloud. Done integration on FB end and I got the test results showing as integrated. But somehow the test metrics are not getting populated in Splunk cloud portal. Q1- As per documentation it states adding ingest endpoint of Splunk but only API endpoints works? Does documenation needs an update? Q2 - Is OTEL collector working natively in Purity has been blessed by OTEL vendors like Splunk? Thanks378Views1like1Comment