Flashblade & Ansible collection
Hello community, We are facing some issues with our FlashBlade when provisioning policies with Ansible. We have updated all the components (py-pure-client and the collection), and we are failing on a simple policy deployment. - name: Test purestorage.flashblade.purefb_policy: name: "filesystem_export_policy" enabled: True policy_type: "nfs" at: True client: "mynfsexport.flashblade.local" secure: True security: "sys" permission: "rw" access: "no-squash" fb_url: "{{ fb_host }}" api_token: "{{ fb_api_token }}" The complete stack trace is : The full traceback is: Traceback (most recent call last): File "/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py", line 107, in <module> _ansiballz_main() File "/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py", line 99, in _ansiballz_main invoke_module(zipped_mod, temp_path, ANSIBALLZ_PARAMS) File "/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py", line 47, in invoke_module runpy.run_module(mod_name='ansible_collections.purestorage.flashblade.plugins.modules.purefb_policy', init_globals=dict(_module_fqn='ansible_collections.purestorage.flashblade.plugins.modules.purefb_policy', _modlib_path=modlib_path), File "<frozen runpy>", line 226, in run_module File "<frozen runpy>", line 98, in _run_module_code File "<frozen runpy>", line 88, in _run_code File "/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py", line 4233, in <module> File "/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py", line 4008, in main File "/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py", line 2392, in update_nfs_policy AttributeError: 'ErrorResponse' object has no attribute 'items' fatal: [localhost]: FAILED! => { "changed": false, "module_stderr": "Traceback (most recent call last):\n File \"/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py\", line 107, in <module>\n _ansiballz_main()\n File \"/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py\", line 99, in _ansiballz_main\n invoke_module(zipped_mod, temp_path, ANSIBALLZ_PARAMS)\n File \"/home/user/.ansible/tmp/ansible-tmp-1778656887.1852276-3067455-48057529014464/AnsiballZ_purefb_policy.py\", line 47, in invoke_module\n runpy.run_module(mod_name='ansible_collections.purestorage.flashblade.plugins.modules.purefb_policy', init_globals=dict(_module_fqn='ansible_collections.purestorage.flashblade.plugins.modules.purefb_policy', _modlib_path=modlib_path),\n File \"<frozen runpy>\", line 226, in run_module\n File \"<frozen runpy>\", line 98, in _run_module_code\n File \"<frozen runpy>\", line 88, in _run_code\n File \"/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py\", line 4233, in <module>\n File \"/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py\", line 4008, in main\n File \"/opt/tmp/tmp/ansible_purestorage.flashblade.purefb_policy_payload_xaietsz7/ansible_purestorage.flashblade.purefb_policy_payload.zip/ansible_collections/purestorage/flashblade/plugins/modules/purefb_policy.py\", line 2392, in update_nfs_policy\nAttributeError: 'ErrorResponse' object has no attribute 'items'\n", "module_stdout": "", "msg": "MODULE FAILURE: No start of json char found\nSee stdout/stderr for the exact error", "rc": 1 } If the policy is already set, the playbook runs perfectly fine. The problem occurs when a new policy is injected. However, we have to install the collection from GitHub. It seems that the artifact built and installed by Ansible Galaxy is not correct. Some commits are not propagated. For example, with the FlashBlade collection 1.24 (installed from Galaxy), we have: >>> from pypureclient.flashblade import ( ... PolicyRuleObjectAccessCondition, ... PolicyRuleObjectAccessPost, ... PolicyRuleObjectAccess, ... NfsExportPolicy, ... NfsExportPolicyRule, ... Policy, ... PolicyPatch, ... PolicyRule, ... SmbSharePolicyRule, ... SmbSharePolicy, ... SmbClientPolicyRule, ... SmbClientPolicy, ... ObjectStoreAccessPolicyPost, ... NetworkAccessPolicy, ... NetworkAccessPolicyRule, ... WormDataPolicy, ... ) Traceback (most recent call last): File "<stdin>", line 1, in <module> File "/home/user/conda/envs/ansible/lib/python3.12/site-packages/pypureclient/flashblade/__init__.py", line 40, in __getattr__ raise ImportError(f'module {__package__} has no attribute {name}') ImportError: module pypureclient.flashblade has no attribute PolicyPatch We have compared the archive from GitHub and there are many differences with the upstream collection code. To help, find my my env package : Package Version ----------------- ----------- annotated-types 0.7.0 ansible-core 2.18.5 bcrypt 5.0.0 certifi 2026.4.22 cffi 2.0.0 cryptography 44.0.0 dnspython 2.8.0 invoke 3.0.3 Jinja2 3.1.4 MarkupSafe 2.1.1 packaging 24.1 paramiko 5.0.0 pip 24.2 py-pure-client 1.88.0 pycparser 2.22 pydantic 2.13.4 pydantic_core 2.46.4 PyJWT 2.12.1 PyNaCl 1.6.2 python-dateutil 2.9.0.post0 PyYAML 6.0.2 resolvelib 1.0.1 setuptools 75.8.2 six 1.17.0 typing_extensions 4.15.0 typing-inspection 0.4.2 urllib3 2.7.0 wheel 0.45.0 And our flashblades are running the Purity//FB 4.6.9. If anyone has a lead to help us get our Ansible back up and running, I thank them in advance. We appreciate your help. Matth1KViews0likes10CommentsAnnouncing the General Availability of Purity//FB 4.7.10 LLR
We are happy to announce the general availability of 4.7.10, the first Long-Life Release (LLR) of the 4.6/4.7 line, providing long-term maintenance of the 4.6 feature set with consistency in capabilities, user experience, and interoperability. For more detailed information about bug fixes and security updates included in each release, see the release notes. Highlights The 4.7 LLR adds many new features and improvements for customers upgrading from the 4.5 LLR: AI and high-performance workload acceleration Major gains for AI, HPC, and other demanding unstructured workloads through higher-performance platform options, increased bandwidth, better read/write concurrency, and S3 over RDMA, provide customers faster time to results, better GPU utilization, and more value from large-scale file and object environments. Lower cost at scale with smarter data placement and efficiency Zero Move Tiering for file and object, larger supported system scale, tenant-level performance controls, and DeepReduce for FlashBlade//E help customers scale capacity more efficiently, improve workload density, and reduce total cost of ownership without adding operational complexity. Stronger security and compliance Important security capabilities including NFS over TLS, mutual TLS, FIDO2 and authentication policy support for SSH, object auditing, and proactive Purity patching, helping customers protect data in flight, strengthen access controls, simplify compliance, and respond faster to risk. Multi-tenancy and service delivery Realms, management access policies, secure multi-tenancy for object, local users and groups, and Fusion workload and preset enhancements give customers stronger isolation, simpler delegated administration, and more consistent service delivery across shared environments and dark sites. Improved observability, resilience, and operations On-box observability, richer protocol and connection statistics, Rapid Replica enhancements, larger-scale file data protection, and hardware-based availability improvements make it easier for customers to troubleshoot faster, protect more data at scale, and run mission-critical environments with greater confidence. This release is supported on the following FlashBlade Platforms: FB//S100, FB//S200 (R1, R2), FB//S500 (R1, R2), FB//ZMT, FB//E, FB//EXA Release recommendations Customers looking for long-term maintenance of the complete 4.6 feature set are encouraged to upgrade to the 4.7 LLR. Customers looking for the latest features as soon as they are available should upgrade to the 4.8 FR. Check out our AI Copilot intelligent assistant for deeper insights into release content and recommendations. EOL schedule The 4.6/4.7 release line is planned to reach End-of-Life (EOL) in April 2029. Links and References Purity//FB 4.7 Release Notes Everpure Product Lifecycle and Support Policies Overview Purity//FB Release and End-of-Life Schedule Purity//FB Release Guidelines FlashBlade Hardware and End-of-Support FlashBlade Capacity and Feature Limits Pure1 Manage AI Copilot800Views0likes0CommentsEnabling Agentic AI via Pure1 Manage MCP Server
Everpure now offers a Pure1® Manage MCP Server so you can query information about your fleet using natural language questions. In this post, I’ll explain how the Pure1 Manage MCP Server works. The first section will explain MCP in general, and the second section will explain how to use our specific server. Feel free to skip to the Quick Start section if you’re already familiar with MCP and just need the parameters to plug into your host. What is MCP? MCP stands for "Model Context Protocol," and it's a way for users to connect their AI applications to external systems using tool calls. MCP tools are fundamentally rooted in application programming interfaces (APIs). An API is a set of rules and protocols that allows different software applications to communicate with each other. It acts as an intermediary, enabling one piece of software (the client) to request information or functionality from another piece of software (the server) without needing to know the server's internal workings. For instance, when you check the weather on your phone, the weather app uses an API to send a request to a weather service, which then returns the current weather data. AI applications have trouble making API calls directly because APIs are designed for completeness and correctness, not for an LLM to use easily. When an AI application wants to use an external system to handle a user’s request, it uses the MCP protocol to make a tool call. The AI (client) requests a function (the tool) from an external system (the server), and the system executes the function and returns a result. This makes MCP a system that standardizes and mediates API-like interactions, allowing AI models to leverage external, real-world capabilities. For more information, see this article on the MCP website: “What is the Model Context Protocol (MCP)?” How can customers benefit from the Pure1 Manage MCP Server? The Pure1 Manage MCP Server enables customers to securely integrate AI assistants, copilots, and agentic systems with live Pure1 telemetry and operational data—without building custom API integrations. It transforms Pure1 from a dashboard-centric experience into an AI-accessible platform, enabling natural language interaction, contextual automation, and real-time operational intelligence. Customers benefit from faster AI integration, reduced engineering effort, preserved security controls, and improved decision velocity across hybrid environments. What types of customer workflows are best suited for MCP? The Pure1 Manage MCP Server is particularly well-suited for agentic and AI-driven workflows, including: Fleet telemetry integration with customer copilots Expose Pure1 telemetry—arrays, volumes, workloads, metrics, and alerts—into internal copilots, chatbots, or AI platforms via MCP endpoints. Value: Unified operational visibility across hybrid and multi-platform environments Automation with context awareness Use MCP to validate storage state, health, performance, or capacity before executing provisioning, backup, or disaster recovery workflows. Value: Safer automation with contextual validation, reduced execution errors, and greater rollback confidence Hybrid cloud observability Correlate Everpure array performance and capacity metrics with application, VM, container, or cloud telemetry across environments. Value: Faster troubleshooting and improved end-to-end performance insights Conversational operational analytics Enable operators to ask real-time natural language questions, such as: “Which arrays are nearing capacity risk?” “Show me the top latency spikes in the last 24 hours.” “Summarize all critical alerts across regions.” Value: Rapid insight without navigating dashboards or exporting reports What the Pure1 Manage MCP Server can do The Pure1 Manage MCP Server exposes the Pure1 Manage REST APIs to AI applications. This means you can ask ad hoc questions about your fleet using natural language, and your AI application will use the server’s tools to query the answer. No programming required. Example conversation Here’s an example conversation demonstrating the use of the Pure1 Manage MCP Server: User: "What is the name of my oldest FlashArray and what is its serial number?" Chatbot:Processing Request: The AI recognizes this as a request for fleet information requiring a tool call. Tool Invocation: Get_hardware Response: The oldest FlashArray in your fleet is named FA-Prod-01 with serial number FA10123456. User: "Can you show me the average I/O latency for that array over the last 7 days?" Chatbot: Let me first check the available latency metrics, then query the historical data: Tool Invocation: Get_metrics Tool Invocation: Get_metrics_history Response: The average I/O latency for FA-Prod-01 (serial FA10123456) over the last 7 days was 0.385 milliseconds. User: "How many arrays do I have in total that are still under warranty?" Chatbot: Processing Request: The AI recognizes this as a request for a count of arrays filtered by warranty status. Tool Invocation: Get_array_support_contracts Response: You currently have 12 arrays in your fleet that are still under active warranty. Quick start Step 1: Register an API key in Pure1 Manage The Pure1 Manage MCP Server leverages the Pure1 Manage REST APIs. In order to access those APIs, you need to register an API key in Pure1 Manage. To do that, follow the directions in the The Pure1® REST API introductory blog post. After going through the instructions, you will have an application id and a private key file, which will be used to generate an access token to access the MCP server in step 2. Step 2: Set up the pure1_token_factory.py script Prerequisites: you need Python 3.12 or greater to run the script. Download pure1_token_factory.zip. Unzip the archive. Go to the unzipped folder in your command-line terminal. Optional but recommended: create and activate a Python virtual environment: python3 -m venv .venv source .venv/bin/activate Install the requirements: pip3 install -r requirements.txt. Run python3 pure1_token_factory.py <application_id> <private_key_file> Copy the generated access token from the script output for the next step. Step 3: Add remote MCP server to your AI application Follow the directions for your AI application to add a remote MCP server (see the Pure1 Manage MCP Server User Guide for instructions for specific chatbots). In general, they need the following information: Remote MCP Server address: https://api.pure1.purestorage.com/mcp Authorization type: header Header name: Authorization Header value: Bearer <access-token> Important: <access-token> is just a placeholder for the access token you generated in step 2. The actual header value should look something like “Bearer eyJ0eXAiO…” Important: you need to generate a new access token every 10 hours and copy it into your AI application You’ll need to run pure1_token_factory.py to generate a new access token every 10 hours, and manually copy the access token into your AI application’s config. Claude Desktop instructions Claude Desktop is a special case because it doesn’t let you set the Authorization header directly. You have to run the mcp-remote local MCP server and configure that to use the Pure1 Manage remote MCP server. Prerequisites You need to have Node.js version 18 or newer installed on your system. Configuration In Claude Desktop, go to Settings > Developer, and click Edit Config. Open the claude_desktop_config.json file in a plain-text editor like VS Code. Configure the mcp-remote server, which is necessary to pass the Authorization header to the Pure1 Manage MCP Server. Paste the token into the configuration file, then restart Claude Desktop. { "mcpServers": { "Pure1 API": { "command": "npx", "args": [ "-y", "mcp-remote", "https://api.pure1.purestorage.com/mcp", "--header", "Authorization:${AUTHORIZATION_HEADER}" ], "env": { "AUTHORIZATION_HEADER": " Bearer <paste access token here>" } } } Note: there might be other configuration options in this file. Be sure to leave them unchanged, and only insert the Pure1 API config in the mcpServers section. The space in the AUTHORIZATION_HEADER environment variable is important. It's there to work around a bug in Windows argument parsing. Please note that: The first time it uses a tool, it will ask you for permission. You can grant permission to all tools at once by going to Customize > Connectors > Pure1 API, and selecting Always Allow under Other tools. For more detailed instructions from Anthropic, please refer to: Connect to local MCP servers - Model Context Protocol.800Views1like0Comments
Ask Us Everything Recap: Making Purity Upgrades Simple
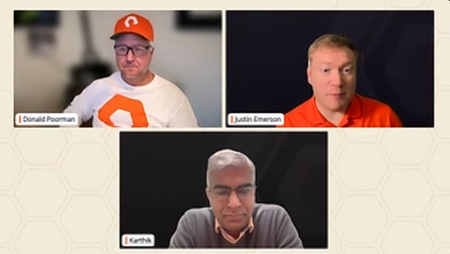
At our recent Ask Us Everything session, we put a spotlight on something every storage admin has an opinion about: software upgrades. Traditionally, storage upgrades have been dreaded — late nights, service windows, and the fear of downtime. But as attendees quickly learned, Pure Storage Purity upgrades are designed to be a very different experience. Our panel of Pure Storage experts included our host Don Poorman, Technical Evangelist, and special guests Sean Kennedy and Rob Quast, Principal Technologists. Here are the questions that sparked the most conversation, and the insights our panel shared. “Are Purity upgrades really non-disruptive?” This one came up right away, and for good reason. Many admins have scars from upgrade events at other vendors. Pure experts emphasized that non-disruptive upgrades (NDUs) are the default. With thousands performed in the field — even for mission-critical applications — upgrades run safely in the background. Customers don’t need to schedule middle-of-the-night windows just to stay current. “Do I need to wait for a major release?” Attendees wanted to know how often they should upgrade, and whether “dot-zero” releases are safe. The advice: don’t wait too long. With Pure’s long-life releases (like Purity 6.9), you can stay current without chasing every new feature release. And because Purity upgrades are included in your Evergreen subscription, you’re not paying extra to get value — you just need to install the latest version. Session attendees found this slide helpful, illustrating the different kinds of Purity releases. “How do self-service upgrades work?” Admins were curious about how much they can do themselves versus involving Pure Storage support. The good news: self-service upgrades are straightforward through Pure1, but you’re never on your own. Pure Technical Services knows that you're running an upgrade, and if an issue arises you’re automatically moved to the front of the queue. If you want a co-pilot, then of course Pure Storage support can walk you through it live. Either way, the process is fast, repeatable, and built for confidence. Upgrading your Purity version has never been easier, now that Self Service Upgrades lets you modernize on your schedule. “Why should I upgrade regularly?” This is where the conversation shifted from fear to excitement. Staying current doesn’t just keep systems secure — it unlocks new capabilities like: Pure Fusion™: a unified, fleet-wide control plane for storage. FlashArray™ Files: modern file services, delivered from the same trusted platform. Ongoing performance, security, and automation enhancements that come with every release. One attendee summed it up perfectly: “Upgrading isn’t about fixing problems — it’s about getting new toys.” The Takeaway The biggest lesson from this session? Purity upgrades aren’t something to fear — they’re something to look forward to. They’re included with your Evergreen subscription, they don’t disrupt your environment, and they unlock powerful features that make storage easier to manage. So if you’ve been putting off your next upgrade, take a fresh look. Chances are, Fusion, Files, or another feature you’ve been waiting for is already there — you just need to turn it on. 👉 Want to keep the conversation going? Join the discussion in the Pure Community and share your own upgrade tips and stories. Be sure to join our next Ask Us Everything session, and catch up with past sessions here!800Views3likes2CommentsGeneral Availability of Purity//FB 4.5.6
We are excited to announce the general availability of Purity//FB 4.5.6 Purity 4.5.6 Release Highlights Introducing Purity//FB 4.5.6, designed to simplify managing a fleet of systems, optimize geographically distributed workflows, and expand the environments that can deploy FlashBlade. Key highlights include: Fusion for FlashBlade: Support for FlashBlade is available now on Pure Fusion, enabling FlashBlade to create, or join a fleet of arrays, simplifying deployments, scaling, and management of data across both FlashArrays and FlashBlades. Pure Fusion now also delivers a single consistent interface for deploying file and object workloads. Rapid Replicas: The remote fetching and caching capability enables file data to be distributed efficiently and allows collaborative development across multiple Data centers, remote sites or, increasingly, workloads in the cloud. QoS ceiling for File System: Purity//FB adds support for creating custom QoS policies defining ceiling limits for IOPS and bandwidth per filesystem. Storage administrators can leverage QoS ceiling to ensure predictable performance and mitigate resource contention. Legal Hold support for File System: Allows users to apply legal hold on files, folders and sub-folders. Once applied the file/folder can’t be deleted by the user until the legal hold is removed. This capability supports compliance for enterprises in regulated industries by providing mandatory legal hold capabilities for files and folders. 18.6TB QLC DFM Support for S100: provides lower entry-point (130TB raw) for customers to experience the power and goodness of FlashBlade//S and also provides heterogeneous expansion capability on //S100 systems with 18.6TB and 37.5TB DFMs. FlashBlade//S500 with NVIDIA DGX SuperPOD: Purity//FB 4.5.6 introduces the integration of FlashBlade with NVIDIA DGX SuperPOD to provide a high-performance, scalable solution for AI and other high-performance computing applications. Object Secure Token Service: Secure Token Services helps FlashBlade to integrate with Single Sign ON (SSO) architectures (Federated Identity models). It simplifies management of user and group access to FlashBlade resources like buckets and objects. Increased Object Account and Bucket Scale: Scalability in FlashBlade Object storage is enhanced with the latest release. FlashBlade will be able to support up to 30K replication relations and up to 5K remote credentials while setting up replication. Object Active-Active Replication: Beginning with Purity//FB 4.5.6, Active-Active Replication between multi-site writable buckets is now Generally Available. No qualification document or approval for setting up replication is needed. However, active-active replication of classic buckets still requires PM approval. Please contact your Pure Storage Representative for assessment and approval for classic buckets. We recommend using multi-site writable buckets for all scenarios including single site deployments. Capacity Consolidation on FB//S & FB//E: provides support for upgrading smaller capacity DFMs to larger capacity DFMs in FlashBlade//S and FlashBlade//E systems. TLS Policy and Ciphers: TLS Policy allows customers to create and maintain custom TLS policies & Ciphers for FlashBlade network interfaces. TLS policy helps centralize management and controls for all inbound network traffic. The policy helps narrow down attack surface and vulnerability exploitation for transports over the network. Updates to Zero Move Tiering (ZMT): FlashBlade//ZMT system adds support for 1,2,3 and 4 DFM per blade configs in 1S:1E offering. New SKUs offer low starting capacity points for Hot storage class and large Cold archival storage. This indirectly improves TCO for customers with predictable performance and cost efficiency. ABE Support for File System: Access-based Enumeration (ABE) allows administrators to hide objects (files and folders) from users who don’t have permissions (Read or List) on a network shared folder in order to access them. MMC Support for File System: Administrators can now go into Microsoft Management Console (MMC) to list open inaccessible files and choose to close them. The full list of new features and enhancements can be found in the Purity//FB 4.5.6 Release Notes.800Views2likes0CommentsAsk Us Everything about Object Storage
💬 Get ready for our February 2026 edition of Ask Us Everything, this Friday, February 20th at 9 AM Pacific. This month is all about Object Storage. If you have a burning question, feel free to ask it here early and we'll add it to the list to answer tomorrow. Or if we can't get it answered live, our Pure Storage experts can follow up here. Karthik Srinivasan, Flashman & dpoorman are the experts answering your questions during the conversation and here on the community. See you this Friday! (Oh, and if you haven't registered yet, there's still time!) Or, check out this self-serve resource: Object Storage Webinar EDIT: Thanks for joining in! If you have additional burning questions and comments, leave them in the comments below for the team!799Views0likes0Comments
Simplifying Observability: Native OpenTelemetry in Purity
As enterprises modernize and accelerate their infrastructure through automation, blind spots become more expensive. When systems move faster, teams need telemetry that’s reliable, portable, and easy to integrate across a heterogeneous stack. Pure Storage’s Enterprise Data Cloud vision reflects that shift: infrastructure that delivers cloud-like simplicity and speed while preserving the control, security, and performance enterprises expect. Fusion supports this by standardizing and scaling self-service workflows, turning storage into an on-demand platform. But faster operations require a stronger feedback loop. As automation increases, teams need confidence that systems remain healthy and predictable. That’s why consolidated observability is foundational. Instead of running separate monitoring tools per layer, organizations are centralizing telemetry into a single observability platform that can correlate signals end-to-end; from the end user’s experience (e.g. browser or mobile app), through the network and application code, all the way down to infrastructure like servers, databases, containers, and storage. This consolidation reduces redundant tools and fragmented dashboards while giving teams the correlated insights they need to resolve incidents faster and make better decisions. The Siloed Vendor Problem Yet achieving this unified vision has proven challenging. Traditional infrastructure vendors have long provided proprietary monitoring tools designed exclusively for their own products. A storage vendor offers one monitoring interface, the compute vendor another, and the network vendor yet another. Each tool uses different data formats, separate dashboards, and incompatible alerting mechanisms. For organizations running heterogeneous environments (which is nearly all of them), this creates an untenable situation. IT teams must context-switch between multiple tools, correlate data manually across platforms, and maintain expertise in numerous vendor-specific interfaces. When an application performance issue arises, determining whether the root cause lies in storage latency, network congestion, or compute resource exhaustion becomes an exercise in detective work across disconnected systems. The promise of consolidated observability cannot be realized with vendor-specific, siloed monitoring tools. A different approach is needed. The Open Standard Solution This challenge has driven the industry toward open, vendor-agnostic standards that enable telemetry interoperability. OpenMetrics emerged as one such standard, providing a common data model for exposing metrics (counters, gauges, and histograms) in a format that any observability platform can consume. By standardizing metric exposition, OpenMetrics reduced vendor lock-in and became foundational to Prometheus-based monitoring at scale. However, standardizing the format of metrics is only one part of what organizations need to make consolidated observability work in practice. Enterprises also need consistency in how telemetry is named, described, transported, and exported, so that infrastructure data can flow cleanly across heterogeneous environments without bespoke integrations. Enter OpenTelemetry, which expands on the same vendor-neutral principles to create a comprehensive observability framework. In other words, it helps ensure telemetry isn’t just emitted in a readable format, but is also structured and delivered in a way that remains portable across vendors and backends. Think of it as establishing the equivalent of a USB standard for telemetry data: any "device" (an application or infrastructure component) can plug into any "peripheral" (an observability platform) without requiring proprietary connectors. The primary benefit is profound: freedom from vendor lock-in. Organizations can choose best-of-breed observability platforms based on capabilities and cost rather than being constrained by what their infrastructure vendors support. The External Agent Bottleneck OpenTelemetry and OpenMetrics have made consolidated observability technically feasible, but most storage vendors have adopted these standards through what can only be described as a "bolt-on" approach. This forces customers to manage a complex chain of external agents, sidecars, or dedicated VMs, just to get telemetry from their platforms visualized onto their dashboards. This presents a problem that’s two-fold: Operational Overhead: Instead of simply consuming data, IT teams are burdened with sizing, patching, and troubleshooting the monitoring infrastructure itself. New Failure Modes: If an agent crashes or becomes misconfigured, visibility into critical infrastructure disappears precisely when it's needed most. Teams find themselves monitoring their monitoring infrastructure; a meta-problem that defeats the original purpose. The Native Integration Imperative In the Pure Storage platform, observability is a first-class capability instead of an afterthought. Thus, Pure Storage has taken a different path: an OpenTelemetry collector embedded into Purity OS. Instead of asking customers to deploy and maintain external agents, exporters, or intermediary infrastructure, Pure Storage platforms will now expose telemetry in standardized OpenTelemetry format as an intrinsic platform capability. The result is sending storage telemetry directly into any OpenTelemetry-compatible Observability platform-of-choice (eg., Datadog, Dynatrace, Splunk, Grafana, etc.). Fig. Numbers represent the sequence of steps in the workflow Pure Storage’s commitment has always been simplicity. Native OpenTelemetry in Purity OS extends that principle to observability: less integration friction, fewer moving parts, and more time spent acting on insight instead of maintaining the pipeline. More information on the native integration of OpenTelemetry Collector within Purity//FB can be found here. Purity//FA to follow soon.799Views0likes0CommentsPure Storage FlashBlade//S 100 Now Veeam Ready. Because Backups Deserve Better
Good news: Pure Storage has expanded our presence in the Veeam Ready database with two brand-new validations! 🎉 In addition to our existing platforms that already have Veeam Ready validations, FlashBlade//S 100 is now officially validated for both Repository and Object with Immutability use cases, solidifying our position as a trusted, high-performance platform for cyber resilience. But what does that actually mean? And why should you care? Let’s break it down. Why Use Object for Backups? Backups used to be simple, you’d write them to tape or a local disk and hope for the best. But today’s environments are more complex, distributed, and under constant threat from ransomware. That’s where object storage steps in. Here’s why object storage is becoming the go-to for modern backup: Scalability: Object storage can handle petabytes of data like a champ. Need more capacity? Just add more objects, no forklift upgrades needed. Simplicity: Flat namespace, no file hierarchies, and built-in metadata = less complexity for your team. Immutability: This is the big one. With S3 Object Lock features, your backups become tamper-proof, which is exactly what you need when ransomware comes knocking. So, if you’re backing up with Veeam Data Platform and you’re not using object storage, it might be time for a rethink. Enter: FlashBlade//S 100 Now, let’s talk about the star of the show: FlashBlade//S 100. This isn’t just any storage system. It’s unified fast file and object storage on an all-flash platform. That means it’s built to handle file workloads and the massive throughput of object-based backup and recovery, all from the same system at the same time. Here’s what sets it apart: 🚀 Performance: All-flash speed coupled with Pure’s ultra-fast object protocol mean backups complete faster and, as those backup datasets grow ever larger, that speed becomes essential for meeting tight recovery time objectives (RTOs). Traditional disk just can’t keep up when seconds count. 🧩 Unified access: File and object protocols on the same box? Yes, please. 🧱 Immutability built in: Ransomware can’t touch what it can’t change. FlashBlade//S supports object lock natively. 🔒 Enterprise security: End-to-end encryption, multi-tenancy, and API-driven operations come standard. 📈 Simple to scale: Whether you’re starting small or scaling up for multi-petabyte archives, FlashBlade’s scale out architecture lets you grow and non-disruptive upgrades from FlashBlade//S100 to FlashBlade//S200 or FlashBlade//S500, ensure continued investment protection and scalability It’s not just storage. It’s a future-ready data platform for backup, recovery, and beyond. So...What Is the Veeam Ready Program? The Veeam Ready Program is a qualification process designed to help Veeam’s technology partners (like us!) prove that their solutions actually work with Veeam Backup & Replication™. Think of it as Veeam’s stamp of approval. A way to separate the real-deal backup solutions from the “trust us, it works” crowd. Pure Storage already had Veeam ready validations but the new FB//S100 is designed for entry-level enterprise use cases. These new validations give customers the confidence that no matter what size their workloads are, whether it’s tens of Terabytes in a remote/branch office or multiple petabytes in the datacentre, Pure and Veeam have a solution that’s already been validated. ✅ Veeam Ready - Repository 🔗View Listing (Veeam Ready - Repository Certification) FlashBlade//S 100 passed Veeam’s tests as a primary backup repository. It’s fast, reliable, and perfect for ingest-heavy workloads, synthetic fulls, and instant recoveries. ✅ Veeam Ready - Object with Immutability 🔗View Listing (Veeam Ready - Object with Immutability Certification) This certifies FlashBlade//S as a Veeam-compatible object target, complete with immutability support. Use it for long-term retention and ensure your data is locked down and protected. Ready to Modernize Your Backups? Whether you’re dealing with backup sprawl, tightening your ransomware defenses, or just tired of slow recoveries, the Veeam + Pure Storage combo is ready for you. ✔️ Veeam Ready ✔️ Flash performance ✔️ Object immutability ✔️ Future-proof architecture What’s not to love? Let’s build something better. For your backups and your business.600Views1like1Comment