Proxmox VE Disaster Recovery with FlashArray, Part 1: Protect and Prepare
Proxmox VE Disaster Recovery with FlashArray, part 1 of 3. So you've got Proxmox VE running on FlashArray, and someone has asked the question every virtualization team gets eventually: what happens if we lose the site? If you came from VMware, the reflex answer is VCF Live Recovery (the artist formerly known as Site Recovery Manager). Proxmox doesn't have one. What it does have is a storage layer that is just Linux: iSCSI, multipath and LVM. That turns out to be a pretty good fit for array replication, because the array can move the data and everything Proxmox needs to bring a VM back is either on that data or in a small text file. This series walks through recovering a set of VMs at a recovery site from FlashArray asynchronous replication. No automation, no orchestration product. Just the commands, in order, with the output you should expect to see. I ran the whole thing end to end on Proxmox VE 9.2 and Purity//FA 6.12: a DR test that leaves production running, a cleanup, a second test, and then a planned failover. It ended up too long for one post, so it's in three. This first one sets everything up: what the array replicates and what it doesn't, protecting the VMs, and getting the rest of what the DR site needs over there. Part two prepares the DR site and runs the DR test, and part three is the failover and what to do when IDs collide. What replication covers, and what it doesn't Before running a single command, it helps to be clear about what actually lands at the DR site. Item Where it lives Replicated by the array? VM disks LVs in a volume group on a FlashArray volume Yes LVM metadata (VG and LV names) On the same volume Yes VM configuration ( /etc/pve/qemu-server/<vmid>.conf ) The Proxmox cluster file system on the source nodes No Storage definitions ( /etc/pve/storage.cfg ) Same No Bridges and VLANs /etc/network/interfaces on each node No ISO images, cloud-init snippets, hookscripts Usually local storage No The top two rows are the array's job. The bottom four are yours. The good news is that a VM config is a short text file, and once the disks are visible at the DR site, recovering a VM is mostly a matter of putting that file back in the right place with the right bridge name. The example environment Production DR Proxmox VE Two-node cluster pve-prod-01 , pve-prod-02 pve-dr-01 FlashArray fa-prod fa-dr Protocol iSCSI, shared LVM iSCSI, shared LVM VM network bridge vlan100 vmbr0 fa-prod already has an array connection to fa-dr for replication. Both Proxmox sites are already set up for iSCSI and multipath per the Proxmox VE iSCSI quick start, and pve-dr-01 already has iSCSI sessions to fa-dr . Three VMs make up the "application" we want to protect: VMID Name Disks 801 dr-web-01 scsi0 on pve-dr-lvm01 802 dr-db-01 scsi0 on pve-dr-lvm01 , scsi1 (data) on pve-dr-lvm02 803 dr-app-01 scsi0 on pve-dr-lvm02 dr-db-01 has its OS disk on one FlashArray volume and its data disk on another. I did that on purpose. It is the case where replicating volumes one at a time goes wrong, and it is why everything below uses a protection group. Protect the VMs at the source Lay out the storage Each FlashArray volume carries one LVM volume group, and each volume group is one Proxmox storage: FlashArray volume Volume group Proxmox storage pve-dr-demo-vol-01 pve-dr-vg01 pve-dr-lvm01 pve-dr-demo-vol-02 pve-dr-vg02 pve-dr-lvm02 The rule of thumb is simple: the volume is the unit of replication, so put VMs that need to fail over together on the same set of volumes, and put those volumes in the same protection group. If another team's VMs share your volume group, they come along for the ride every time you recover. Record which volume holds which VMs At recovery time you'll be looking at volumes on one system and volume groups on another, so write the mapping down while production is healthy. Production may not be there to ask when you need the answer, so this record is only useful if a copy already lives at the DR site, next to the config copies. The link between the two is the WWID: for a FlashArray volume, the Linux WWID is 3624a9370 followed by the volume's serial number in lowercase. This script prints each FlashArray-backed PV with its serial, volume group and the VMIDs that have disks on it. Save it on each production node as /usr/local/sbin/pve-dr-inventory and make it executable ( chmod +x ), because you'll run it again every time you send copies to the DR site: #!/bin/bash # FlashArray serial -> volume group -> VMIDs on this node, for the DR site. echo "# $(hostname) $(date -u +%FT%TZ)" for pv in $(pvs --noheadings -o pv_name | grep -o '/dev/mapper/3624a9370[0-9a-f]*'); do vg=$(pvs --noheadings -o vg_name "$pv" | tr -d ' '); [ -n "$vg" ] || continue serial=$(basename "$pv" | sed 's/^3624a9370//' | tr a-f A-F) vms=$(lvs --noheadings -o lv_name "$vg" | grep -o 'vm-[0-9]*' | sort -u | tr '\n' ' ') echo "serial=$serial vg=$vg vms: $vms" done # pve-dr-inventory # pve-prod-01 2026-11-02T20:07:05Z serial=A1B2C3D4E5F6A7B800000001 vg=pve-dr-vg01 vms: vm-801 vm-802 serial=A1B2C3D4E5F6A7B800000002 vg=pve-dr-vg02 vms: vm-802 vm-803 It lists every FlashArray-backed volume group the node can see, not only the protected ones, which is fine. With shared LVM every node sees the same volume groups. If some of your storage is restricted to particular nodes, run it on each of those nodes too. Match the serials against the array: fa-prod> purevol list pve-dr-demo-vol-01 pve-dr-demo-vol-02 Name Size Source Created Serial pve-dr-demo-vol-01 100G - 2026-11-02 10:47:45 PST A1B2C3D4E5F6A7B800000001 pve-dr-demo-vol-02 100G - 2026-11-02 10:47:54 PST A1B2C3D4E5F6A7B800000002 Now you have the whole chain: FlashArray volume, serial, volume group, Proxmox storage ID, VMs. It goes to the DR site along with the configs, a little further down. Naming each volume group after its FlashArray volume makes the chain readable without the lookup, but the serial is the part that can't be wrong. If production is gone and this record never made it across, most of the chain can be rebuilt from the DR site alone. Step 4 of the DR test, in part two, shows how. The one link that can't be rebuilt is which storage ID goes with which volume group, and that comes from production's storage.cfg , which is the next thing to copy. Create the protection group On fa-prod , create a protection group with both volumes and fa-dr as the target: fa-prod> purepgroup create --vollist pve-dr-demo-vol-01,pve-dr-demo-vol-02 --targetlist fa-dr pve-dr-demo-pg Name Source Targets Host Groups Hosts Volumes pve-dr-demo-pg fa-prod fa-dr - - pve-dr-demo-vol-01 pve-dr-demo-vol-02 A protection group snapshot captures every member volume at the same point in time. That's what makes dr-db-01 safe: its OS disk and its data disk come back from the same instant, not from two snapshots taken a few seconds apart. Now give it a replication schedule and decide how long the DR array keeps replicas. This replicates hourly, keeps every replica for a day, and then keeps four per day for a week: fa-prod> purepgroup schedule --replicate-frequency 1h pve-dr-demo-pg fa-prod> purepgroup retain --target-all-for 1d --target-per-period 4 --target-period-length 1d --target-days 7 pve-dr-demo-pg fa-prod> purepgroup enable --replicate pve-dr-demo-pg fa-prod> purepgroup list --schedule pve-dr-demo-pg Name Schedule Enabled Frequency At Blackout pve-dr-demo-pg snap False 1h - - replicate True 1h - - The replication frequency is your recovery point objective. If you replicate hourly, you can lose up to an hour of writes in an unplanned failover. Pick the number with the application owner, not for them. You can also take a snapshot and replicate it right now, which is what I use for DR tests and for the last step before a planned failover: fa-prod> purepgroup snap --replicate-now --suffix drtest1 pve-dr-demo-pg Name Source Created pve-dr-demo-pg.drtest1 pve-dr-demo-pg 2026-11-02 10:56:28 PST One thing to know about on-demand snapshots: unless you add --apply-retention , Purity keeps them until you destroy them. That's handy for a test you want to repeat. It's less handy six months later when someone asks where the space went. Send the DR site what the array doesn't replicate The array replicates the disks. Three more things have to reach the DR site some other way, and all three are small text files: What Why the DR site needs it VM configs, /etc/pve/nodes/*/qemu-server/*.conf Without them there is nothing to start: no CPU, memory, NICs, or list of disks. Storage definitions, /etc/pve/storage.cfg The only record of which storage ID maps to which volume group. The configs reference disks by storage ID. Look at dr-db-01 : it has a vm-802-disk-0 in both volume groups, so the LV names alone can't tell you which one is pve-dr-lvm01:vm-802-disk-0 . The inventory from pve-dr-inventory The serial → volume group → VMs chain from the previous section, so you can check that you've connected the right volumes. Do it by hand From any production node that can SSH to the DR node, run these three commands: # 1. VM configs from every node in the cluster rsync -a /etc/pve/nodes/*/qemu-server/ root@pve-dr-01:/root/dr-configs/ # 2. Production's storage definitions, under a name that can't be mistaken for the DR cluster's own rsync -a /etc/pve/storage.cfg root@pve-dr-01:/root/dr-configs/storage.cfg.prod # 3. The volume inventory /usr/local/sbin/pve-dr-inventory | ssh root@pve-dr-01 'cat > /root/dr-configs/inventory.prod' rsync is installed on Proxmox VE by default. If you prefer scp , it works just as well. Make sure /root/dr-configs exists on the DR node before the first run ( ssh root@pve-dr-01 mkdir -p /root/dr-configs ). A couple of things in there are on purpose. I read /etc/pve/nodes/*/qemu-server/ rather than /etc/pve/qemu-server , because the short path is a link to whichever node you happen to be logged in to, and in a two-node cluster that's only half your VMs. The longer path pulls both halves into one directory. VMIDs are unique across the cluster, so nothing overwrites anything, and since /etc/pve is shared it doesn't matter which production node you run it from. The files land in a plain directory on the DR node. Not in /etc/pve over there. Drop them into /etc/pve on the DR side and you've just registered production's VMs on the DR cluster, and production's storage.cfg would replace the DR cluster's own. I also left off --delete . If someone removes a VM in production, its config sticks around in the DR copy until somebody cleans it up, and I'd rather have a stale file than a missing one. Check what arrived: # ls /root/dr-configs 801.conf 802.conf 803.conf inventory.prod storage.cfg.prod # grep -A2 "pve-dr-lvm0" /root/dr-configs/storage.cfg.prod lvm: pve-dr-lvm01 vgname pve-dr-vg01 content images,rootdir -- lvm: pve-dr-lvm02 vgname pve-dr-vg02 content rootdir,images These copies are only as current as the last time you sent them. If someone adds a disk to dr-db-01 and nobody resends, the DR site gets a VM with a disk missing from its config. The new LV is on the replicated volume. The config just doesn't know about it. At a minimum, rerun the three commands after any change to a protected VM's hardware or to the storage layout, and before every DR test. Or let cron do it The same three commands, in a script on a production node, keep the copies current without anyone remembering. Save this as /usr/local/sbin/pve-dr-sync and make it executable: #!/bin/bash set -e rsync -a /etc/pve/nodes/*/qemu-server/ root@pve-dr-01:/root/dr-configs/ rsync -a /etc/pve/storage.cfg root@pve-dr-01:/root/dr-configs/storage.cfg.prod /usr/local/sbin/pve-dr-inventory | ssh root@pve-dr-01 'cat > /root/dr-configs/inventory.prod' Then schedule it in /etc/cron.d/pve-dr-sync : */15 * * * * root /usr/local/sbin/pve-dr-sync The node running the job needs SSH key access to the DR node. Install the script on more than one production node if you want the job to keep running when a node is down. Running it twice is harmless. With a 15-minute schedule, the copies can be up to 15 minutes behind a change, which is usually far less than the replication interval anyway. Either way, the DR copies of these files only exist because production sent them. That's why the cron job or the manual routine has to run before you need it. On the day production is gone, there's nothing left to copy from. Here is what one of them looks like: # cat /root/dr-configs/802.conf agent: 1 boot: order=scsi0 cicustom: user=local:snippets/pve-dr-demo-user.yaml cores: 2 cpu: x86-64-v2-AES ide2: pve-dr-lvm01:vm-802-cloudinit,media=cdrom ipconfig0: ip=dhcp memory: 2048 name: dr-db-01 net0: virtio=BC:24:11:00:08:02,bridge=vlan100 ostype: l26 scsi0: pve-dr-lvm01:vm-802-disk-0,iothread=1,size=10G scsi1: pve-dr-lvm02:vm-802-disk-0,iothread=1,size=20G scsihw: virtio-scsi-single serial0: socket smbios1: uuid=6f1e2d3c-4b5a-4968-8776-a5b4c3d2e1f0 vga: serial0 vmgenid: 0a9b8c7d-6e5f-4a3b-9c2d-1e0f9a8b7c6d Read it with DR eyes. The disks reference storage IDs, so if you recreate the same storage IDs at the DR site, those lines work unchanged. Three lines will not work: bridge=vlan100 names a bridge that doesn't exist on pve-dr-01 . cicustom points at local:snippets , which isn't replicated. ide2 is a cloud-init drive. Proxmox regenerates it at boot, and it would need that snippet. If you change the cloud-init settings, the generated instance ID changes too, and cloud-init treats the VM as brand new on first boot. For a recovered VM, I would rather remove the drive. Same story for an ISO left in a virtual CD-ROM ( ide2: local:iso/... ), or a hookscript sitting on local storage. Any one of these keeps the VM from starting at the DR site. The error will point you at the config, though, not at the storage. Also note that dr-db-01 has a vm-802-disk-0 on both storages. Proxmox numbers disks per storage, so that is normal, and it's another reason to keep the storage IDs identical on both sides. That's the production side done. The VMs replicate on a schedule, and the DR site has copies of everything the array doesn't carry. In part two I get the DR site ready and then use all of it to run a full DR test while production keeps running.84Views1like0Comments
Containers, Kubernetes, and Modern VMs: Your Storage Questions Answered
From persistent storage and disaster recovery to modern alternatives for traditional VMs, Everpure experts answered your questions about making the move to Kubernetes. Containers and Kubernetes are changing how IT teams deploy and manage applications. But what happens to your data when applications become more portable, infrastructure becomes more dynamic, and traditional VMs start sharing the stage with containers? That was the focus of our latest Ask Us Everything session, featuring Everpure experts Jon Owings and Nathan Wood. As always, attendees drove the conversation, bringing questions about persistent storage, migration, disaster recovery, Portworx by Everpure, and what Kubernetes means for their existing infrastructure. Why should storage be a priority when adopting Kubernetes? Jon kicked things off with an important reminder: Organizations spend considerable time choosing their Kubernetes platform, but don't always give storage the same attention. Unlike traditional VM environments, Kubernetes introduces new requirements for managing persistent data across containers, clusters, and locations. Nathan compared storage to the foundation of a house. You wouldn't build a house without considering the foundation; if storage is the foundation of modern apps, why approach Kubernetes differently? The takeaway: Don't assume that provisioning volumes is enough. Think about performance, data protection, portability, and automation from the beginning. Can I migrate production databases to Kubernetes without downtime? One attendee asked how to move an existing production database from on-premises infrastructure into Kubernetes without disrupting operations. Jon explained that migration options range from open-source tools requiring downtime to commercial solutions supporting live cutovers. Nathan emphasized that migration planning must account for the application, database, and storage layers. Their advice? Start with your data requirements, understand your downtime tolerance, and involve the right experts. There's no one-size-fits-all migration strategy. How does Portworx simplify persistent storage and disaster recovery? Another attendee wanted to understand disaster recovery when using FlashArray Direct Access or FlashBlade Direct Access, particularly when recovering to another site with different arrays. Jon explained that direct-attached storage approaches can require additional workflows and automation to coordinate recovery. That's where Portworx Enterprise offers a different approach. Rather than building and maintaining custom scripts for every recovery scenario, Portworx provides Kubernetes-native storage management capabilities designed to simplify data mobility and recovery across environments. It's a significant departure from traditional, infrastructure-specific storage management. What should we measure beyond uptime? Jon and Nathan were asked which metrics matter most when reporting storage performance. The answer: Latency, latency, latency. Availability matters, but application performance depends on more than whether infrastructure is running. The experts discussed measuring latency, response times, and performance at the application, node, and cluster levels. Portworx provides consistent metrics across different storage vendors and cloud environments, with Prometheus and Grafana offering visualization options. Can Kubernetes become an alternative to traditional VMs? For organizations with substantial VMware investments, Kubernetes can support both containerized applications and modern VM workloads. Jon explained that organizations should evaluate their application requirements rather than simply recreate their existing virtualization environment. Kubernetes offers opportunities for greater flexibility across on-premises, hybrid-cloud, and multicloud environments, while Portworx helps address the persistent storage requirements that accompany those choices. How do we get started—and convince our leadership this is the right path? A longtime VMware customer asked how to make the business case up the management chain for the move to Kubernetes. Jon and Nathan agreed: Lead with risk reduction, not technology. Explain how flexibility, portability, and infrastructure choices can help the business adapt. Nathan also recommended hands-on learning environments where teams can experiment, demonstrate value, and build confidence. Keep the conversation going! Whether you're exploring Kubernetes, evaluating modern VM options, or already managing production containers, this session reinforced one important lesson: Modern applications need a modern approach to storage. Check out the full Ask Us Everything replay for more practical advice from Jon and Nathan (and find all our other Ask Us Everything sessions here), and keep the conversation going by jumping into the Everpure Community!4Views0likes0CommentsPHIF: Modular Hypervisor Integrations and a VMware Migration Path That Doesn't Depend on VDDK
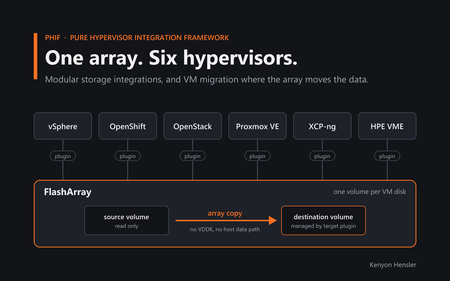
This post first ran on my personal blog, vSkeeBall. The code is on GitHub at PureStorage-OpenConnect/pure-hypervisor-integration-framework. For most of my career, virtualization meant VMware. Storage vendors built their integrations for vSphere, backup tools were built around VMware's APIs, and migration tools treated VMware as a source by reading its virtual disks and copying the blocks somewhere else. That's not the world most of the customers I talk to live in anymore. They're running vSphere next to OpenShift Virtualization, Proxmox VE, XCP-ng, HPE VM Essentials or OpenStack, and sometimes several of those at once. Some of the assumptions under the old tooling are changing too. In August 2026 Red Hat documented that VMware's Virtual Disk Development Kit (VDDK) images are no longer on the old public download, and you now have to request access from VMware/Broadcom. One workaround Red Hat called out was storage offload/XCOPY. Microsoft's Azure Migrate docs say the agentless VMware appliance needs VDDK too, and if you can't get it, you should use agent-based migration instead. I'd already been chewing on a question that this made a lot more relevant: what if moving a VM didn't depend on pulling its data out through the source hypervisor's disk SDK at all? That question ended up being one of the more interesting parts of PHIF, the Pure Hypervisor Integration Framework. PHIF started with a simpler goal. I wanted an easier way to hook a FlashArray up to a bunch of different virtualization platforms. Over time it turned into an experiment around three questions: Can the hypervisor storage integrations be modular and useful on their own, with no management framework at all? Can one capability-driven control plane automate those integrations without becoming something you're stuck with? Once the hypervisors share the same storage, can the array itself become the migration path? From what I've built so far, I think the answer to all three is yes. One thing up front: PHIF is a side project of mine, not a supported Everpure product. There's more on that at the end. Every hypervisor wants storage differently Going in, I figured this was mostly an API problem. The APIs turned out to be the easy part. The hard part is that every platform has its own idea of what storage looks like: VMware has VMFS, vVols, NFS and RDMs. OpenStack wants storage through Cinder. OpenShift and Kubernetes want CSI. Proxmox has its own storage plugin model. XCP-ng has Storage Repositories and SMAPI. HPE VM Essentials is built on Morpheus and KVM, with yet another plugin model. You could hide all of that behind one lowest-common-denominator layer, but you'd throw away most of what makes each platform worth running. So PHIF standardizes the orchestration and lets each platform keep its native integration model. PHIF can connect a FlashArray, deploy or configure the right integration for each platform, manage credentials, run day-2 operations and coordinate VM migrations, without pretending the platforms are the same underneath. Capabilities instead of if-statements Each hypervisor in PHIF is a connector, and the connector declares what that platform supports. The capability list right now looks like this: CONNECT, DEPLOY_PLUGIN, CONFIGURE, HOST_REGISTER, CONNECTIVITY, PROVISION_DATASTORE, PROVISION_VOLUME, SNAPSHOT, CLONE, RESIZE, QOS, REPLICATION, HEALTH, REMOVE, VM_INVENTORY, VM_LIFECYCLE, MIGRATE The front end doesn't carry a pile of "if it's vSphere, show these buttons" logic. It shows whatever each connector says it implements. Adding a hypervisor mostly means writing a new connector. The registry finds it on its own, and the shared services (FlashArray client, job engine, secrets and log streaming) are already there. This is one of my favorite screens in the app. All six platforms show up as peers, even though they look nothing alike under the hood. You don't need PHIF to use the plugins This is the part I care about most. PHIF can install the integrations, configure them, manage their lifecycle and use them in a migration, but several of them can be installed by hand and run without PHIF at all. I didn't want PHIF sitting between the hypervisor and the array. It sits above the integration instead: PHIF | deploy / configure / manage v Hypervisor | native plugin v FlashArray PHIF is an orchestration plane. It isn't in the VM's I/O path, and the storage integration keeps working if PHIF goes away. So if all you want is better FlashArray integration on Proxmox, XCP-ng or HPE VM Essentials, just grab that plugin. You don't have to run the web app or touch migration. Proxmox For Proxmox I wrote a custom purefa storage type as a real PVE::Storage::Plugin , so it runs inside Proxmox's own storage framework. The model is one FlashArray volume per VM disk. Instead of one big shared LUN with LVM on top and guest disks carved out of it, every guest disk gets its own volume: VM 101 |-- disk-0 -------- FlashArray volume A |-- disk-1 -------- FlashArray volume B VM 102 |-- disk-0 -------- FlashArray volume C Those volumes show up in the VM as raw multipathed block devices. Snapshots and clones happen on the array, and each disk keeps its own identity there. None of that needs PHIF. You can install the plugin, define the storage, set up multipathing and register the hosts yourself. PHIF just automates those steps. XCP-ng XCP-ng needed a completely different implementation, built on SMAPIv3: a volume plugin for the FlashArray-backed VDI lifecycle, a datapath that hands the raw multipathed device to the VM, and a host component for things like cleaning up multipath maps. Same idea as Proxmox, though: one VDI, one FlashArray volume, with snapshots and clones done on the array. I've validated it on a live two-host pool. PHIF can deploy it across a pool, or you can install it on the hosts yourself. HPE VM Essentials VME is Morpheus plus KVM, so this one is a native Morpheus/VME storage plugin. It registers FlashArray storage inside VME and lets VME drive the per-disk operations, with one volume per VM disk and snapshot, clone and resize offloaded to the array. I've validated it on a live VME appliance. PHIF can upload and configure it, or you can build and install it by hand. vSphere, OpenShift and OpenStack These three already had integrations: the FlashArray Cinder driver, Portworx CSI, and the vSphere plugin with VASA, VMFS and vVols. PHIF automates deploying and configuring them, and after that Cinder is still Cinder and CSI is still CSI. I don't want PHIF to fix one lock-in problem by adding a new mandatory dependency. How I think about the layers Layer 1 Native storage integration Layer 2 Deployment and configuration automation Layer 3 Lifecycle and day-2 operations Layer 4 Cross-hypervisor orchestration and migration Layer 1 is useful by itself, and you can stop there. Each layer above it is optional. Migration works because the storage model underneath is already there, but the plugins don't exist just to enable migration. Remove PHIF and they keep running. You lose the automation, not the storage integration. The management layer Nothing exotic here. It's a React SPA in front of a FastAPI backend, with an auto-discovered connector registry, a shared FlashArray REST client, an async job engine and encrypted credential storage. Operations run over HTTP APIs, SSH, Ansible or Kubernetes tooling. It runs under Docker Compose or Kubernetes/Helm. There's also a mock mode that stubs out the array and hypervisor I/O, so you can walk through every workflow without any real infrastructure. Day-2 operations PHIF exposes whatever each connector implements as day-2 operations: host registration, connectivity, provisioning, snapshots, clones, resize, QoS, replication, health checks and plugin lifecycle, depending on the platform. The UI is organized around six workflows: FlashArrays, API keys, hypervisors, operations, migrations, and jobs/log history. PHIF still stays out of the data path. The deployment wizard A lot of PHIF's value is just replacing a stack of per-platform install runbooks with one repeatable flow: discover the environment, find the nodes and interfaces, install the integration, set up storage networking, register the hosts, connect the FlashArray and validate. If you only run one environment, you probably don't need the wizard. That's the point of keeping the integrations modular. Then the storage layer became the migration layer I didn't set out to build migration. It came out of the storage design. Once several hypervisors keep each VM disk as its own FlashArray volume, a cross-hypervisor migration starts to look very different. The usual picture has the migration software acting as the data mover: Source hypervisor -> virtual disk -> migration software (read blocks, transfer blocks) -> destination storage -> destination hypervisor But if both platforms are attached to the same FlashArray, the source disk is already sitting on the hardware that's going to serve the destination. In a lot of cases there's no reason to copy it through a migration server. So PHIF captures the source VM's logical configuration, creates a matching VM and managed disks on the destination, and fills those destination volumes with a FlashArray copy-with-overwrite. The source volumes stay the source of the data, and the big block copy happens inside the array instead of going through the migration host. PHIF orchestration Source VM Destination VM | | v v Source FA volume --- array copy ---> Destination FA volume (inside FlashArray) PHIF coordinates. The array moves the data. Copy vs. move PHIF supports both. In copy mode, the source VM stays put while PHIF builds the destination and copies each source volume into a destination-managed volume. In move mode, the source is shut down first and only removed once the destination is created and running. If a migration fails, PHIF cleans up the half-built destination, and in copy mode the source is never touched. I've run boot-confirmed migrations in both directions across all the migration-capable platforms sharing one FlashArray. To be clear, this doesn't hand the same LUN from one hypervisor to another. The destination plugin creates its own volume and the array copies into it, so each platform keeps its own ownership and naming. Migration groups and scheduling Once single-VM migration worked, I added groups, with a shared source and destination, network mapping, scheduling and concurrency controls. That still sits above the plugins, and the plugins don't need it. Why VDDK matters here VDDK is how third-party tools have traditionally read VMware virtual disks. It works, but it puts VDDK squarely in your migration path: VMware VMDK -> VDDK -> migration software -> destination If your migration tool needs VDDK to read the source disk, its version compatibility, licensing and availability are all your problem. PHIF's VMware migration doesn't use VDDK. I didn't build it that way because of the August change. It's a side effect of leaning on the array and VMware's own host tooling instead. PHIF still uses the hypervisor APIs for the VM config, NICs and MACs, network mappings and creating the destination VM. It just doesn't pull the bulk data out through VDDK. RDMs are the easy case An RDM already has an identity as a storage device. PHIF resolves its device ID against the FlashArray, finds the volume, and that volume goes straight into the array-based workflow. VMFS takes more work A VMDK on VMFS is a file. The array holds the datastore, but there's no dedicated volume behind each individual VMDK, so PHIF has to change how the storage is represented. For a VMFS source, PHIF provisions a new FlashArray volume, presents it to ESXi as an RDM, and clones the VMDK onto it with vmkfstools . Where the VMware storage path supports it, that clone is VAAI/XCOPY offloaded to the array. Before: VM -> VMDK file -> VMFS -> FlashArray datastore volume Prep: VMDK file --(vmkfstools / VAAI-XCOPY)--> dedicated FA volume Migration: dedicated FA volume --(FlashArray copy)--> destination-managed FA volume -> destination VM No VDDK required. I also find it interesting that Red Hat independently pointed to storage offload/XCOPY as a way around its own VDDK dependency. vSphere as a destination vSphere can be the destination too. By default PHIF attaches the destination disks as virtual-mode RDMs backed by dedicated FlashArray volumes, which keeps the volume-per-disk model. If you'd rather end up with native VMFS VMDKs, there's an optional conversion. That step is different, because going from a raw device into a file on VMFS does need host-side data movement. PHIF runs it with VMware's storage operations and verifies the result before it frees the temporary volumes. That matters to me. An abstraction should make things simpler, but it shouldn't hide where the bytes are actually moving. Let the hardware do what it's good at Arrays already have snapshots, volume copies, clones, host mappings, replication and QoS. We think of those as storage features, but a lot of them work as mobility tools too. A volume copy can copy a VM disk, and a snapshot gives you a rollback point. So why push all the data through a migration appliance when the array that already owns it can do the copy? I think the VDDK situation points at a bigger issue. If leaving platform A requires a proprietary disk-access SDK from platform A, that SDK is part of your portability strategy whether you planned for it or not. PHIF splits the work. The hypervisor handles what it understands (inventory, CPU and memory, firmware, power state, networks and VM creation), and the array handles the volumes, copies, mappings and data. Who owns the VM? This project has also changed how I think about VM ownership. We usually draw the hypervisor on top, owning everything down to the array. I've started thinking of it as two halves: the compute platform owns the VM config and runs it, and the array owns the durable data that any of these hypervisors can consume. Real migrations still have plenty of complications (boot modes, drivers, disk formats, networking), but the data doesn't have to belong to one hypervisor. What PHIF is, and what it isn't PHIF is an independent, experimental project. It is not a supported Everpure product, and it isn't covered by a support agreement, warranty or SLA. That matters because it does real things to real infrastructure. It can create and destroy array volumes, change storage connectivity and multipathing, apply Kubernetes components, and create, power off or delete VMs. Try it in a lab, start in mock mode, and only point it at data you can afford to lose. The custom Proxmox, XCP-ng and HPE VM Essentials plugins are just as experimental. I put the code out so people can look at it, test it, change it and hopefully make it better. Where it stands today As of right now, PHIF has connectors for six environments: vSphere, OpenShift, OpenStack, Proxmox, XCP-ng and HPE VM Essentials. Each integration has been validated on hardware, and the migration engine has been tested on live hardware between the migration-capable platforms sharing the same FlashArray. That's enough to prove out the architecture. Next I'd like to add more hypervisors through the connector model and see whether array replication opens up cross-array mobility. And since it's modular, you can reuse the one piece you like without buying into the rest. Wrapping up For me, the interesting part of PHIF isn't the UI or the migration wizard. It's how the work is split underneath: the integrations are the foundation, PHIF handles orchestration, and the array is the data plane. When everything shares the same array, you can ask what the storage hardware can do for you. The VDDK changes made that more timely, but they aren't why I built it this way. They just show why those dependency boundaries matter. Sometimes a hypervisor migration really does mean moving a lot of data. But when the source and destination share capable storage, the migration server doesn't have to be the thing doing the moving. The source code, docs, deployment instructions, connector guides and the standalone plugins are all on GitHub: PureStorage-OpenConnect/pure-hypervisor-integration-framework. If you give it a try, I'd like to hear how it goes, so drop a comment here or open an issue on the repo. PHIF is an independent experimental project. It is not a supported Everpure product, is not covered by a support agreement, warranty or SLA, and can perform destructive infrastructure operations. Test it only in environments and against data you can afford to lose.31Views0likes0Comments
Get rid of stressful infrastructure headaches. Everpure Fusion handles your data, autonomously.
It happens! It's 11:45 PM on a Friday. An alert fires and storage latency has spiked across a production workload. The operator digs in and traces it back to an automated tiering policy that quietly moved a hot dataset to a slower tier because it looked idle based on a 24-hour access window, right before a scheduled batch job that runs every weekend. Nobody changed anything. The policy did exactly what it was configured to do. But nobody remembers configuring it that way, the documentation hasn't been touched in two years, and the monitoring dashboard shows storage as "healthy" because utilization is fine. It's just in the wrong place. The operator overrides the tier, performance recovers, and spends the next hour writing an incident report for a problem that shouldn't exist. A system that was supposed to make life easier made a decision with no context, no warning, and no visibility into why. That's the anger that doesn't go away quickly. It's not just frustration at the incident. It's the feeling that the tools are working against you instead of with you. The core problem in that story was a system making decisions with no context, no warning, and no visibility. Everpure Fusion attacks each of those problems: Unified visibility across the entire fleet: Everpure Fusion provides a global dataset as a single source of truth for discovery, management, and configuration of storage arrays so the operator isn't piecing together what happened across multiple dashboards, multiple arrays, multiple tickets after the fact. They see the full picture in one place, before things go wrong. Intelligent workload placement: Rather than static policies quietly acting on stale access patterns, Everpure Fusion uses AI-guided placement to boost performance and efficiency for every workload. It understands workload behavior, not just utilization snapshots, the kind of context that would have caught a batch job pattern before tiering the dataset down. Policy-driven governance with real control: Automated orchestration cuts manual tasks and speeds service delivery, while unified controls simplify audits, reduce risk, and prove compliance fast. Policies are visible, documented, and governable. Not buried configs nobody remembers setting. Built into the platform, not bolted on: Evepure Fusion is now simply a part of Purity, meaning it is not an add-on you have to install or buy, but rather a core piece of the Purity operating system. The operator doesn't have to manage another tool. The intelligence is already there. The operator in that story didn't need more alerts. They needed a system that understood context, made decisions transparently, and gave them control without requiring them to be online at midnight to maintain it. That's exactly the gap Everpure Fusion is designed to close - with One Fleet, Zero Complexity. Why policy-driven storage operations matter Everpure Fusion is built as the core of Everpure intelligent control plane that manages all arrays including FlashArray, FlashBlade, and cloud as a unified fleet, with one topology, one API, and one operational framework regardless of protocol or local - datacenter, cloud or edge. That uniformity is what makes policy enforcement reliable at scale. Everpure Fusion introduces workload-based provisioning through presets, which are predefined policy-driven templates for specific workload types, encoding protection policies, replication, and SafeMode retention from the moment a workload is provisioned, not patched in after an incident. Admins no longer need to pre-plan and tune deployments manually, which reduces the risk of non-compliance and improves resiliency by ensuring workloads are provisioned correctly from the beginning. The result is infrastructure that enforces your intent, not just your last manual action. Intelligent placement, rebalancing, and fleet-scale capacity control If you manage storage at scale, you've probably seen this scenario play out more than once. One array is buried, running hot, and screaming for relief. Three aisles over, another array is sitting at 40% utilization, doing almost nothing. And somewhere in between, your team is scrambling to provision capacity, kick off an emergency migration, and explain to stakeholders why an SLA was missed on a workload that, in hindsight, never should have been placed there in the first place. This is not a people problem. It is a tooling problem. And it is remarkably common. Everpure Fusion starts solving this problem at the moment of provisioning. When a new workload lands, most storage systems do a simple capacity check and place it wherever space is available. Everpure Fusion does something fundamentally different. The placement engine evaluates every array in the fleet simultaneously, looking at IOPS headroom, throughput capacity, and physical utilization before making a decision. The goal is not just to find somewhere to put the workload. It is to find the right home for it, one where it can live comfortably for the long term without creating a bottleneck down the road. Think of it as placing workloads with intention rather than convenience. Of course, environments do not stay static. Workloads grow, usage patterns shift, and an array that looked healthy six months ago can become a problem today. Everpure Fusion accounts for this with continuous rebalancing built directly into its operation. When an array starts trending toward overload, Everpure Fusion detects it and begins orchestrating data movement across the fleet automatically. No manual intervention required. No application downtime. Data migrates in the background while workloads keep running, and arrays that were sitting underutilized suddenly become productive members of your infrastructure. At fleet scale, now supporting up to 64 arrays, this turns capacity management from a constant firefight into something that largely runs itself. What makes this possible without disruption is how Everpure Fusion executes the move under the hood. It leverages ActiveCluster to stretch the volume across both the source and target arrays simultaneously, creating a synchronous mirror in place. Once the stretch is established, volumes are connected on the target array and hosts auto-discover the new target paths through standard multipathing. The target then validates that path usage is healthy and confirmed before any cutover begins. Only after that validation is complete are the volumes disconnected from the source, ensuring there is zero gap in access at any point in the sequence. Everpure Fusion then unstretches from the source array to complete the rebalance and release its capacity. The result is a seamless, non-disruptive migration that the application never sees. What truly sets Everpure Fusion apart from a standard load balancer is what happens under the hood. Powered by Pure1 AI and up to 30 days of historical workload data, Everpure Fusion does not just look at what is happening right now. It looks at what is about to happen. Say you have a workload that runs a heavy batch job every Saturday night. Everpure Fusion knows that. It has seen the pattern. So when the placement engine is evaluating tier assignments, it will never recommend moving that workload to a lower-performance tier just because it looks quiet on a Tuesday afternoon. It understands what Tuesday quiet actually means in context. And if that workload somehow ends up on the wrong tier, perhaps through a manual change or a migration gone sideways, Everpure Fusion will proactively raise a violation before the weekend arrives. Not after the SLA is missed. Before. The cumulative effect is that customers can operate their fleets closer to full utilization without the anxiety that normally comes with it. Underused hardware gets activated, incremental purchases get deferred, and the reactive, always-behind-the-curve model of capacity management starts to look like a problem from a previous era. And Everpure Fusion does not stop at the infrastructure layer. Through its integration with Pure1 Application Intelligence, Everpure Fusion gains deeper visibility into the nature of the workloads themselves, not just how they behave, but what they actually are. That additional context means smarter decisions at every level, from initial placement to long-term tier management, grounded in a more complete picture of what your environment is really doing. Workload rebalance and mobility will be available towards the end of 2026. Compliance as part of the control plane Most storage compliance workflows follow the same pattern: an audit is announced, someone pulls reports from three different tools, cross-references configuration against a spreadsheet of expected settings, and spends two weeks proving that workloads are protected the way they're supposed to be. Then the audit ends and nothing changes until the next one. That model breaks at fleet scale. When you're managing dozens of arrays across multiple sites and protocols, manual audits don't just slow you down — they leave gaps that only get discovered at the worst possible time. Everpure Fusion Compliance is built into the control plane, not bolted on after provisioning. Because Everpure Fusion presets encode protection policies, replication requirements, SafeMode retention, and QoS settings at deployment time, Everpure Fusion always knows what every workload's intended configuration is. Drift detection is continuous — not periodic. When a workload deviates from its preset, Everpure Fusion instantly surfaces the violation — visible in the UI, queryable via API or CLI, and accessible to AI agents through an MCP server. Remediation can be triggered directly through the same interfaces, without pulling in a separate tool or writing a custom script. Fleet-wide compliance dashboards give storage admins a live view of posture across every array, with exportable audit-ready reports that don't require manual assembly. The shift is meaningful: compliance becomes a property of how the fleet operates, not a project that interrupts how the team works. Everpure Fusion Compliance will be available towards the end of 2026. From dashboards and scripts to natural-language fleet operations You know the drill. A latency spike hits production. You open three dashboards, run a handful of CLI queries, dig through alert logs, and piece together enough context to understand what happened — and by then, you've already spent 45 minutes on a problem that should have taken five. The issue isn't the tools. It's that the context your fleet holds is trapped across systems that don't talk to each other. Everpure Fusion MCP Server changes that. Built on the open Model Context Protocol standard, it connects any MCP-compatible AI assistant — Claude, ChatGPT, Copilot, or internal agents — directly to live Everpure Fusion fleet state. Arrays, workloads, capacity, performance metrics, alert history, configuration, and placement data are normalized into clean, structured JSON and made available to AI in real time, pulled directly from Everpure Fusion and Purity REST APIs. The result: instead of navigating dashboards and stitching together CLI output, you ask a question. "Which arrays are approaching capacity?" "What's driving latency on this workload?" "Which workloads are drifting from their preset?" Everpure Fusion MCP Server answers from live fleet context, not stale snapshots. This is the on-ramp to agentic storage operations. Everpure Fusion already enforces policy and placement across the fleet. Pure1 adds AI-driven analytics and recommendations on top. Together, they give infrastructure operators the foundation to move from reactive troubleshooting to intent-driven, increasingly autonomous fleet management. Using topology groups to encode real infrastructure boundaries If your Everpure Fusion fleet's topology model lives in a color-coded spreadsheet, three wikis, and the institutional memory of one senior admin who never takes vacation — this is for you. Everpure Fusion, built into Purity for FlashArray and FlashBlade, introduces Topology Groups: fleet-scoped objects that let you describe your arrays in the same language your architecture diagrams already use — regions, availability zones, datacenters, rows, racks. No more provisioning a Everpure Fusion workload and hoping it lands in the right building. A Everpure Fusion Topology Group is a hierarchical, tree-structured object. Groups nest up to 10 levels deep (global → us-east → az-us-east-1a → dc01 → row3 → rack12), each array belongs to exactly one parent, and cycles are rejected at write time. Critically, they encode placement semantics — not access control. RBAC stays in Pure1 Resource Groups; topology stays in Everpure Fusion topology. Once modeled, Everpure Fusion presets reference groups using <group>.arrays notation. Everpure Fusion intersects the preset's allowed arrays with the group's membership at placement time. If there's no overlap, Everpure Fusion provisioning fails fast with a clear error — not silently in the wrong zone. The Everpure Fusion CLI shorthand makes automation clean: purevol list --context az-us-east-1a.arrays Everpure Fusion membership changes propagate automatically across the fleet. You stop maintaining a second source of truth outside the control plane. Stop treating topology as tribal knowledge. With Everpure Fusion, make it a first-class part of the intelligent control plane. Extending the model to Kubernetes and virtualization Most infrastructure operators are managing two parallel storage worlds right now: traditional VMs and databases on one side, Kubernetes-based containerized workloads on the other. Separate toolchains. Separate provisioning workflows. Separate everything. Everpure Fusion changes that. Through the Portworx Fusion Controller, Everpure Fusion extends its policy and placement control plane directly into Kubernetes — without forcing developers to change their existing workflows. Everpure Fusion auto-discovers your FlashArray and FlashBlade fleet, then exposes Everpure Fusion presets as native Kubernetes StorageClasses. That means when a developer requests a persistent volume, Everpure Fusion's placement engine resolves it against your existing policy constraints — storage class, protection policy, topology group, replication requirements — the same way it does for any other Everpure Fusion workload. No separate control plane for modern environments. No array-by-array configuration for each cluster. New arrays added to the fleet are automatically discovered and configured, so the operational model stays consistent as infrastructure grows. For VMware environments, Everpure Fusion extends the same operational model through the Everpure Fusion vSphere plugin, connecting storage management directly into virtualization workflows instead of running it as a separate administrative domain. The result: one control plane, one set of policies, one placement engine — spanning VMs, containers, and databases across the fleet. That is fewer parallel stacks to operate, less configuration drift between environments, and a more scalable path to consistent storage operations across the full infrastructure stack. Everpure Fusion as the storage admin foundation for autonomous operations The through-line across everything covered in this blog is simple: Everpure Fusion gives infrastructure operators a unified, policy-driven control plane that enforces intent consistently — across provisioning, placement, compliance, topology, and now Kubernetes and virtualization. That foundation matters because autonomous storage operations do not start with AI. They start with structure. Topology groups encode where workloads belong. Presets encode how they should be configured. Everpure Fusion presets exposed as StorageClasses ensure Kubernetes environments follow the same rules as everything else. When that structure is in place, AI can recommend, optimize, and eventually act — because the context is already clean, trusted, and machine-readable. For storage admins, the shift is real: less time resolving incidents caused by placement decisions nobody remembers making, more time defining the intent that governs the fleet. Everpure Fusion is that foundation — built into Purity, not bolted on. Want to learn more about Everpure Fusion? Check out the following links to dive deeper: Join the Everpure Fusion Mastery Program to build expertise, complete hands-on activities and earn rewards. Sign up for a Fusion test drive to try it out on your own time. Check out more about Fusion product details. Watch our cool new Fusion demo videos. Read Everpure Fusion Datasheet157Views0likes0CommentsWhat We Learned About ActiveCluster for File from the Latest “Ask Us Everything”
The newly-announced ActiveCluster for file extends Everpure’s synchronous replication to unstructured workloads–so it was no surprise that the latest Ask Us Everything session drew a lot of attention. Attendees came ready with practical questions about how it works, where it fits, and what it could mean for real production environments. And host Don Poorman, Product Manager Quinn Summers, and Principal Technologist Russell Pope brought the Everpure answers. The conversation showed just how this new approach can help modernize resiliency, mobility, and day-to-day operations. Let’s break down the biggest takeaways. “Is This Just HA… or Something More?” One of the most interesting threads came early: is ActiveCluster for file just another high availability solution? Short answer: no. Attendees pushed on this, and the response from Everpure’s team was clear—this is about data mobility and policy-driven management, not just surviving a failure. Instead of treating HA as a one-off configuration, ActiveCluster is designed to align storage behavior with business intent. That shift matters. In traditional environments, HA is often bolted on and managed manually. Here, policies define things like performance, protection, and placement—and the system enforces them automatically across the fleet. For many in the session, that was a “wait, this is different” moment. The Big Comparison: Legacy Replication vs. ActiveCluster A standout question came from someone evaluating ActiveCluster as a replacement for legacy approaches like NetApp SVMDR. The discussion highlighted a key difference: granularity and consistency. Legacy solutions often replicate at a coarser level (think entire systems or large aggregates), which doesn’t always align with how applications are structured. ActiveCluster instead works at the realm level, where both data and configuration are synchronously mirrored. That means: No mismatched failover scope No rebuilding configs on the other side No “did we forget something?” during a failover It’s a cleaner, more application-aligned model—and that resonated with the audience. “What Actually Happens During a Failover?” Attendees asked the right questions: Is failover automatic? What about DNS changes? How fast does it happen? The answers were refreshingly direct. In a stretched Layer 2 setup, failover is fully automatic and transparent—clients don’t even notice. In more complex network designs, there may be some redirection (like DNS updates), but the data is already in sync. And timing? The expectation is on the order of seconds (often under 10). This is a variable currently unmatched by any legacy storage competitor to Everpure. There was also a lot of interest in how Everpure avoids split-brain scenarios. The mediator service—hosted by Everpure or deployed locally if needed—acts as a lightweight “tie breaker” during network partitions. No extra infrastructure to manage in most cases, and no guesswork about which side should stay active. Simplicity Came Up… A Lot If there was one theme that kept coming back, it was simplicity. One attendee asked about setup, and the answer was basically: it’s wizard-driven. That sparked a broader discussion about how legacy storage often assumes admins have time to relearn complex workflows. In reality, most teams are juggling multiple systems. The ability to stand up synchronous replication with a few guided steps—not scripts, not custom tooling—landed well. Even testing reflects that philosophy. Instead of complex test procedures, the guidance was simple: pull cables, simulate real failures, and observe behavior. No artificial “test modes”—just real-world validation. Data Mobility Is the Real Story Another strong theme was mobility. ActiveCluster doesn’t just protect data—it enables you to move it. The “stretch and unstretch” workflow means datasets can be mirrored, shifted, and re-homed without disruption. That’s a big departure from traditional models, where moving data often means downtime, migration projects, or both. For teams thinking about workload placement, lifecycle management, or hybrid environments, this opens up new options. Real-World Use Cases The audience also pushed beyond file shares into real workloads: Financial trading and payment systems Healthcare imaging and research data VMware/NFS environments The takeaway: if it’s mission-critical and file-based, it’s a candidate. Final Thought: Even More on the Horizon Even with some initial constraints (like starting with new file systems), the field feedback shared during the session was telling: customers are ready to adopt this early. Why? Because the core value—resiliency, mobility, and simplicity—is already there. And if the session proved anything, it’s that Everpure is building this in close collaboration with the community. The questions weren’t just answered—they’re shaping what comes next. If you’re evaluating how to modernize file services, Everpure’s approach is definitely one to consider. Check out this and all our other Ask Us Everything sessions. And, keep the conversation going by jumping into the Everpure Community.183Views0likes0Comments
Ask Us Everything: Pure Storage + Nutanix — What the Community Really Wanted to Know
The January Ask Us Everything (AUE) session tackled one of the hottest topics in infrastructure right now: what Pure Storage and Nutanix are doing together—and what that means for our customers. Judging by the volume and depth of questions, it’s clear that many of you are actively evaluating next-generation virtualization options and want real answers, not marketing slides. With Cody Hosterman (Sr Director Product Management, Pure Storage), Thomas Brown (Field CTO, Nutanix), myself - Joe Houghes (Field Solutions Architect, Pure Storage), and our host Don Poorman (Technical Evangelist, Pure Storage), the conversation went deep into architecture, migration realities, and the practical problems this joint solution is designed to solve. Here are the biggest takeaways from what attendees asked—and what they learned. This is joint engineering, not just “interoperability” One of the most important clarifications came early: this isn’t a case of “here’s a LUN, good luck.” Nutanix has natively integrated Pure Storage FlashArray APIs directly into the Nutanix stack. That means: No plugins to install No bolt-on frameworks to manage No separate operational silos In Prism, the Nutanix management plane, Pure Storage behaves like a first-class storage backend. Snapshots, protection, provisioning, and automation are driven from Nutanix, while Pure Storage delivers its strengths—performance, data reduction, SafeMode, and simplicity—under the covers. NVMe/TCP support is a deliberate, forward-looking choice Several attendees asked why Fibre Channel or legacy protocols weren’t the focus. The answer: this solution is built for where infrastructure is going, not where it’s been. By standardizing on NVMe/TCP over Ethernet, Pure and Nutanix: Avoid decades of SCSI and FC tech debt Enable massive bandwidth scalability (100G, 400G, and beyond) Lay the groundwork for modern security features like TLS and in-band authentication This is a design meant to still make sense 10 years from now. Object-style vDisks eliminate old datastore limits A recurring “aha” moment came when attendees learned how vDisks are implemented. Instead of traditional filesystem-based datastores (with all their historical limits), each virtual disk maps directly to a Pure Storage volume. What that unlocks: Petabyte-scale virtual disks (no more 64TB ceilings) No datastore gymnastics to scale performance No artificial limits inherited from legacy file systems This felt especially relevant for customers running large databases, analytics platforms, or fast-growing enterprise apps. HCI isn’t going away—this complements it A key question from the audience: Does this replace Nutanix HCI? The answer was a clear no. Nutanix HCI still makes perfect sense for many workloads. But when customers: Need to scale storage independently of compute Have performance-heavy or capacity-dense workloads Want an “apples-to-apples” replacement for traditional VMware + external storage …Pure Storage + Nutanix provides a clean alternative without forcing architectural compromises. Migration is real, and the hard parts were addressed honestly Migration questions dominated the session—and the tone was refreshingly pragmatic. Attendees learned: Nutanix Move is fully supported and preserves Purity’s data reduction–which makes this a zero-cost migration in terms of storage capacity VMware NSX rules can be translated into Nutanix Flow during migration Backup tools (Veeam, Rubrik, Commvault, Cohesity, etc.) continue to work without re-engineering or changes in backup operations Most migration risk doesn’t lie in the hypervisor—it’s overlooked third-party dependencies The guidance was consistent: plan carefully, take stock of any dependencies, and don’t rush a wholesale cutover just to meet an artificial deadline. No user ever wants to be forced to do that. Operational simplicity is a major design goal A subtle but powerful theme emerged: you don’t need to tune this solution. VMware users often ask about “nerd knobs” and the need to tweak things to get them working right. In this solution, they’re mostly gone—and intentionally so. Best practices for queue depths, multipathing, performance tuning and more are already baked into the platform by the joint engineering teams. Improvements are managed through upgrades, eliminating the need for manual scripting or implementing performance tweaks for a "snowflake" deployment. The result of this best-of-breed, jointly-engineered solution is consistency, predictability, and easier support—especially during migrations–so that you can focus on the work that makes your business run. The roadmap is active—and community feedback matters This solution was not positioned as “done and dusted.” The GA release is the foundation, not the finish line. Capabilities like Kubernetes support, deeper snapshot orchestration, VDI validation, and migration optimizations are all on the roadmap. And importantly: your use cases drive priorities. And the Pure Storage Community is a great place to drop your feedback for the teams! Keep the conversation going This partnership sparked a lot of interest for a reason: it’s not just about changing hypervisors—it’s about modernizing how infrastructure works. If you missed the live session—or want to dive deeper—join the ongoing discussion in the Pure Storage Community: 👉 https://purecommunity.purestorage.com/discussions/virtualization/ask-us-everything-about-pure-storage--nutanix/3634 You’ll find Pure Storage and Nutanix experts answering follow-ups, clarifying edge cases, and sharing lessons learned from real deployments. While you’re there, be sure to check out past Ask Us Everything events—they’re packed with practical, practitioner-level insights.420Views1like0CommentsOptimizing VMware ESXi iSCSI Performance with iSCSI Buffers
Optimizing VMware ESXi iSCSI performance involves a multi-faceted approach, touching on network configuration, ESXi settings, and even your storage array's capabilities. One of the common ways to improve iSCSI performance is network configuration (crucial for iSCSI) and ESXi host configuration. In this blog post, I’ll focus on improving iSCSI performance via ESXi host advanced configuration settings. To improve ESXi iSCSI performance via advanced settings, you're primarily looking at parameters that control how the ESXi host interacts with the iSCSI storage at a deeper level. These settings should always be modified with caution, preferably after consulting VMware (Broadcom) documentation or your storage vendor's recommendations, as incorrect changes can lead to instability or worse performance. Recommended steps for adjusting ESXi advanced settings: Understand your workload: Identify if your workload is sequential or random, small block or large block, read-heavy or write-heavy. This influences which settings might be most beneficial. Identify bottlenecks: Use esxtop, vCenter performance charts, and your storage array's monitoring tools to pinpoint where the bottleneck lies (host CPU, network, storage array controllers, disks). Consult documentation: Always refer to VMware's (Broadcom) official KBs and your storage vendor's best practices guides. Change one setting at a time: Make only one change, then thoroughly test and monitor the impact. This allows you to isolate the effect of each change. Make incremental adjustments: Don't make drastic changes. Increase/decrease values incrementally. Test in a lab: If possible, test performance changes in a lab environment before implementing them in production. Be prepared to revert: Make a note of default values before making changes so you can easily revert if issues arise. There are several ESXi advanced settings (VMkernel parameters) that can influence iSCSI performance, for example, iSCSI session cloning, DSNRO, iSCSI adapter device queue depth, MaxIoSize, and others. I’ll focus on the relatively new configuration setting available from vSphere 7.0 U3d onwards, which allows adjusting iSCSI socket buffer sizes. iSCSI Socket Buffer Sizes There are two advanced parameters for adjusting iSCSI socket buffer sizes: SocketSndBufLenKB and SocketRcvBufLenKB. Both those parameters control the size of the TCP send and receive buffers for iSCSI connections and are configurable via ESXi host advanced settings (go to Host > Configure > System > Advanced Settings > Search for ISCSI.SocketSndBufLenKB and ISCSI.SocketRcvBufLenKB). The receive buffer size affects read performance, while the send buffer size affects write performance. For high-bandwidth (10Gbps+) or high-latency networks, increasing these buffers can significantly improve TCP throughput by allowing more data to be "in flight" over the network. This is related to the bandwidth delay product (BDP); see details below. What Value Should I Use? These settings are tunable from vSphere 7.0 U3d onwards; the default values are set to 600KB for SocketSndBufLenKB and 256KB for SocketRcvBufLenKB and can be adjusted up to 6MB for both parameters. My recommendation is to calculate the BDP in your environment, adjust the iSCSI socket buffer sizes, test them, and monitor the results with esxtop (see a how-to below). Note that larger buffers consume more memory on the ESXi host. While generally not a major concern unless extremely large values are used, it's something to be aware of. Bandwidth Delay Product (BDP) Now, let’s take a closer look at the bandwidth delay product (BDP). BDP is a fundamental concept in networking that represents the maximum amount of data that can be in transit (on the "wire") at any given time over a network path. It's essentially the "volume" of the network pipe between two points. Why Is BDP Important for TCP/iSCSI? Transmission Control Protocol (TCP), which iSCSI relies on, uses a "windowing" mechanism to control the flow of data. The TCP send and receive buffers (also known as TCP windows) dictate how much data can be sent before an acknowledgment (ACK) is received. If your TCP buffers are smaller than the BDP, the TCP window will close before the network pipe is full. This means the sender has to stop and wait for ACKs, even if the network link has more capacity. This leads to underutilization of bandwidth and reduced throughput. If your TCP buffers are equal to or larger than the BDP, the sender can keep sending data continuously, filling the network pipe. This ensures maximum throughput and efficiency. When Is BDP Configuration Most Relevant? BDP configuration is important for: High-bandwidth networks: 10/25/40/50/100Gbps iSCSI networks High-latency networks: Stretched clusters, long-distance iSCSI, cloud environments, or environments with multiple network hops between ESXi and storage For typical 1Gbps iSCSI networks with low latency, the default buffer sizes are usually sufficient, as the BDP will likely be smaller than the defaults. However, as network speeds increase, accurately sizing your TCP buffers becomes more critical for maximizing performance. How to Calculate BDP BDP = Bandwidth (BW) × Round Trip Time (RTT) Where: Bandwidth (BW): The data rate of the network link, typically measured in bits per second (bps) or bytes per second (Bps). In ESXi contexts, this refers to the speed of your iSCSI NICs (e.g., 1Gbps, 10Gbps). Round Trip Time (RTT): The time it takes for a packet to travel from the sender to the receiver and back again, measured in seconds (or milliseconds, which then needs conversion to seconds for the formula). This accounts for network latency. Monitoring with esxtop Modifying ESXi advanced settings can yield significant performance benefits, but it requires a deep understanding of your environment and careful, methodical execution and monitoring. I highly recommend watching esxtop metrics for storage performance to monitor the results and see the outcomes of the above changes. How to Use esxtop The most common way is to SSH into your ESXi host, but you can also access the ESXi command line directly from the ESXi host console. Once you are there, type esxtop and press Enter. You'll see the CPU view by default. To get to the disk-related views, press one of the following keys: d (Disk Adapter View/HBA View): Shows performance metrics for your storage adapters (HBAs, software iSCSI adapters, etc.). This is useful for identifying bottlenecks at the host bus adapter level. u (Disk Device View/LUN View): Displays metrics for individual storage devices (LUNs or datastores). This is often the most useful view for identifying shared storage issues. v (Disk VM View/Virtual Machine Disk View): Shows disk performance metrics per virtual machine. This helps you identify which VMs are consuming the most I/O or experiencing high latency. Once you're in a disk view (d, u, or v), you can monitor these key storage metrics: Latency metrics (the most important): DAVG/cmd (device average latency): This tells you how long the storage array itself is taking to process commands. High DAVG often indicates a bottleneck on the storage array (e.g., slow disks, busy controllers, insufficient IOPS). KAVG/cmd (kernel average latency): This represents the time commands spend within the ESXi VMkernel's storage stack. High KAVG often points to queuing issues on the ESXi host. Look at QUED along with KAVG. If KAVG is high and QUED is consistently high, it suggests the ESXi host is queuing too many commands because the path to the storage (or the storage itself) can't keep up. This could be due to a low configured queue depth (Disk.SchedNumReqOutstanding, iscsivmk_LunQDepth) or a saturated network path. GAVG/cmd (guest average latency): This is the end-to-end latency seen by the virtual machine's guest operating system. It's the sum of DAVG + KAVG. This is what the VM and its applications are experiencing. If GAVG is high, you then use DAVG and KAVG to pinpoint where the problem lies. Thresholds: While specific thresholds vary by workload and expectation (e.g., database VMs need lower latency than file servers), general guidelines are: ~10-20ms sustained: Starting to see performance impact. >20-30ms sustained: Significant performance issues are likely. >50ms sustained: Severe performance degradation. I/O metrics: CMDS/s (commands per second): The total number of SCSI commands (reads, writes, and others like reservations). This is often used interchangeably with IOPS. READS/s/WRITES/s: The number of read/write I/O operations per second. MBREAD/s/MBWRTN/s: The throughput in megabytes per second. This tells you how much data is being transferred. Queuing metrics: QUED (queued commands): The number of commands waiting in the queue on the ESXi host. A persistently high QUED value indicates a bottleneck further down the storage path (either the network, the iSCSI adapter, or the storage array itself). This is a strong indicator that your queue depth settings might be too low, or your storage can't handle the incoming load. ACTV (active commands): The number of commands currently being processed by the storage device. QLEN (queue length): The configured queue depth for the device/adapter. Conclusion Modifying iSCSI socket buffer sizes is another method to tune the ESXi iSCSI connection for better performance. Together with other ESXi tunables, it can bring better performance to your storage backend. If the iSCSI connection is already tuned for maximum performance, another option is to implement a more modern protocol such as NVMe over TCP, which Pure Storage fully supports with our arrays.2.4KViews2likes5CommentsHyper-V: The Municipal Fleet Pickup: Familiar, Capable, and Still Worth Considering
Hyper-V remains a practical, cost-efficient option for Windows-centric environments, offering strong features and seamless Azure integration. This blog explores where it shines, where it struggles, and how Pure ensures enterprise-grade data protection no matter which virtualization road you take.215Views1like0CommentsWho’s Driving Virtualization? Kicking Off the Road Trip
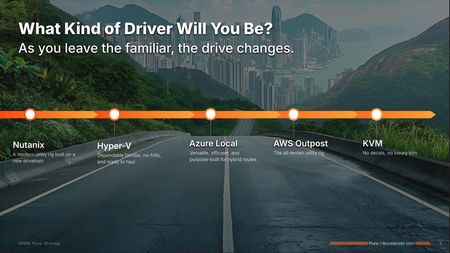
Over the years, VMware vSphere has been the gold-standard — the reliable luxury sedan of the datacenter. It’s delivered a smooth ride with powerful features, a robust ecosystem, and enough polish to keep your operations humming. Many of us have built entire practices, architectures, and skill sets around that platform. But with the Broadcom acquisition, the road has changed. New licensing structures, evolving product bundles, and operational shifts have created uncertainty — the equivalent of finding out that your well-loved sedan suddenly takes only premium-priced fuel and requires a new maintenance shop. So what are your options? Stick with VMware? That’s still a perfectly valid choice, especially if you double down on modernizing how you run it. Enhancing vSphere with Pure’s FlashArray, FlashBlade, and Fusion gives you ways to simplify, automate, and reduce costs, while maintaining that familiar driving experience. Look for an alternative? That’s where things get interesting. Because changing hypervisors isn’t like changing lanes on the highway — it’s more like switching to a whole different vehicle, with a new dashboard, new handling, new maintenance, and a different driving style. Framing the Conversation: The Virtualization Vehicle Metaphor In our session, we used a driving metaphor to illustrate these choices: 🚛 Hyper-V — The Municipal Fleet Pickup Reliable, widely available, low-cost. If you know Windows, you know Hyper-V, and the licenses may already be in your toolbox. 🚙 Nutanix AHV — The Retro-Modern Concept Car Streamlined, integrated, designed for simplicity. An HCI approach that reimagines what virtualization can look like. 🚐 Azure Local — The Electric Sprinter Van Hybrid-ready, with a familiar dashboard if you live in the Microsoft ecosystem. Built for flexible, modern routes. 🚗 AWS Outposts — The Off-Road Luxury SUV The same AWS powertrain, but adapted to handle rugged hybrid terrain on-premises. 🏎️ KVM — The EV Sports Car That’s Actually a Customized Japanese Compact (or maybe a well-used Ranger) Flexible, open-source, highly modifiable — but definitely for drivers who are ready to get their hands dirty and do their own tuning. Each of these “vehicles” comes with a different mix of: ✅ migration effort ✅ operational changes ✅ skill requirements ✅ and data protection needs Key Takeaways from Accelerate Here’s what stood out during our live session and the conversations that followed: ✅ There is no drop-in replacement for VMware. Each platform brings its own challenges and benefits. ✅ Migration is not just technical — it’s cultural, operational, and often requires reskilling your team. ✅ Modernizing with vSphere is still a strong path — with storage, automation, and security improvements, you can get more from what you already own. ✅ Pure is built to be your co-pilot — no matter which hypervisor you choose, we’re there to help you protect, manage, and move data seamlessly. One theme that resonated was that the driver matters as much as the car. Your organization’s skills, processes, and risk tolerance all shape which road makes sense. You can’t pick a new hypervisor in a vacuum — you have to look at what you can maintain, what you can train for, and what you can support. Where We’re Going with This Series We had a ton of material packed into Accelerate — far more than fits in a single session recap. So here on Pure Community, I’ll be breaking down each of these hypervisors in detail, one at a time. Here’s what you can expect: 🚛 Hyper-V We’ll dig into its Windows ecosystem strengths, where it works well, and what trade-offs come with a move from VMware. 🚙 Nutanix AHV Here we will take a look at how a platform that once was a integrated HCI. Can offer simplicity when it meets enterprise-grade capabilities on Pure Storage — and where it may leave gaps. 🚐 Azure Local Let's explore the strength is a hybrid-ready strategy. The native integrations, and what to watch out for when moving workloads from traditional hypervisors. 🚗 AWS Outposts Together we’ll break down why Outposts is not just a “VMware replacement,” but really an AWS extension, with its own Day 2 and migration realities. 🏎️ KVM We’ll explore the open-source options, why so many see it as a cost-saver, and the skills you’ll need to manage it at scale. So, Who’s Driving? My biggest takeaway from Accelerate is this: Your hypervisor journey is less about the technology, and more about the people and processes behind it. Every route — modernize VMware, switch to a new platform, or blend hybrid options — has trade-offs. But with the right planning, the right skills, and the right partners, you can make the journey smoother. Pure is committed to being your co-pilot, whichever path you choose. Whether you’re rolling out Fusion, looking to modernize with FlashArray, or exploring migration options, our ecosystem and integrations are designed to keep your data resilient, performant, and simple to manage. Join the Discussion I’d love to hear from you: 🚗 Are you staying on VMware? 🚗 Modernizing your vSphere environment? 🚗 Kicking the tires on an alternative hypervisor? What worries you? What excites you? Drop a comment below — to keep the conversation going. Let’s keep mapping this road trip — together.184Views3likes0Comments