Recent Discussions

Curious about home lab or on-prem models
A friend told me to stop trying to squeeze local models onto my gaming PC and just buy the right box. So I did, and hoping not to regret it. Ordered a BOSGAME M5. Ryzen AI Max+ 395, 128GB unified memory, up to 96GB of it assignable to the GPU. Size of a hardcover book. I've been running LM Studio with models off Hugging Face. Fine for small stuff. So, people who've actually done this at home... What are you running besides LM Studio? What hardware did you buy and regret? Where does unified memory fall apart in practice? One ask. Human answers only. I can already ask a model what a model thinks. I want to know what broke in your house at 11pm on a Tuesday.Introducing Pure Storage Data Stream for AI Data Readiness
Cool news to share from Pure's presence at NVIDIA GTC this week - the announcement of a new solution - Pure Storage Data Stream - that accelerates data readiness by automating and speeding up the ingestion, transformation, and optimization of data for enterprise AI pipelines. "Data Stream is a GPU-centric AI-powered, integrated hardware and software stack built for data readiness to automate and accelerate the ingestion, transformation, and optimization of data for enterprise AI pipelines. It is a core component of Pure Storage Data Platform built for enterprise inference use cases, using the NVIDIA AI Data Platform reference design, a comprehensive, single-appliance, jointly engineered infrastructure stack tailored for AI inference via generative AI applications." Register for a preview here: https://www.pure.ai/data-stream.html Blog announcement: https://blog.purestorage.com/products/driving-the-future-of-ai-data-readiness-pure-storage-data-stream/Ludes11 months agoCommunity Manager900Views0likes0CommentsArtificial Intelligence (AI) Sessions at Accelerate 2026
Accelerate 2026 is right around the corner! 🚀 Learn how to build a blueprint for AI competitive advantage with the Everpure platform. Hear from industry experts and customers about best practices to create your AI factory—from pilot to production. If this sounds right up your alley, we’ve curated a list of must-attend breakout sessions focused on all things AI. Check out these don’t miss sessions: The State of AI, 2026: Top Advances and Their Impact on Global Enterprises Come See What We've Been Building: A Guided Tour of Everpure's Enterprise AI Portfolio Data Stream: Zero Friction from Storage to AI How are NeoClouds, Enterprises and Commercial Customers Adopting AI at Scale with Everpure 🎤 Featured Speaker We are thrilled to have Par Botes sharing deep-dive insights into the State of AI in 2026. You won't want to miss this keynote! Will you be joining us in person? Drop a comment below with the session you're most interested in and what you hope to learn!catud4 months agoCommunity Manager399Views2likes0Comments
A Petaflop in Your Backpack: RTX Spark and the Shift to Local AI
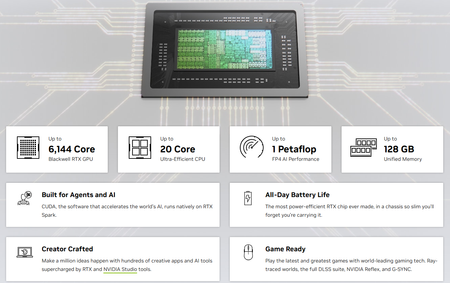
Alt headlines to A/B test: The Cloud-Bill Killer? RTX Spark Puts a Full Petaflop of AI on Your Lap Local AI Just Got Serious: 128 GB and a Petaflop, Unplugged Stop Renting GPUs. RTX Spark Brings Data-Center AI to Your Desk — and Your Bag For the last few years, doing real AI work meant one thing: renting someone else's hardware. Spin up an instance, watch the meter run, ship your data to a server you don't control, and hope the latency cooperates. RTX Spark is a bet that the next era looks different — that the most interesting AI will run where you are, on hardware you own. And the spec sheet backs up the ambition. The numbers that matter to builders Up to 1 petaflop of FP4 AI performance Up to 128 GB of unified memory Up to 6,144 cores of Blackwell RTX GPU Up to 20 cores of ultra-efficient CPU If you build with AI, two of these should stop your scroll. A full petaflop of FP4 is the kind of throughput that turns "let it run overnight" into "let it run over lunch." And 128 GB of unified memory is the unlock almost no portable machine offers: CPU and GPU share one giant pool, so you can hold large models and big context entirely in memory — no swapping, no artificial caps on the size of what you load. The workloads that used to demand a rack now fit in a bag. Why this is a big deal for AI work CUDA runs natively. The platform that accelerates the world's AI runs at full speed on RTX Spark — meaning the frameworks, libraries, and agentic stacks you already use just work. No exotic ports, no "supported soon." That changes the day-to-day in three concrete ways: Fewer cloud bills. Prototype, fine-tune, and run inference locally instead of burning credits every time you iterate. Your data stays yours. Sensitive datasets never leave the device — a quiet superpower for anyone working under compliance or NDA. Build agents anywhere. A genuinely portable petaflop means you can develop and test agentic workflows on a train, in a client's office, or off the grid entirely. For the wave of teams building agents and AI products right now, "local-first" stops being a compromise and starts being an advantage. A petaflop that doesn't need a power brick Here's the part that makes the rest believable: RTX Spark is built around the most power-efficient RTX chip ever made. That efficiency is why a petaflop can live in a slim chassis and last all day. Performance you can only use while tethered to a wall isn't really portable performance — and that's the trap RTX Spark is designed to avoid. When the work is done It's not all inference and fine-tuning. The same silicon makes RTX Spark a creator's machine — hundreds of creative apps and AI tools accelerated by RTX and NVIDIA Studio — and a genuine gaming rig after hours, with ray tracing, the full DLSS suite, NVIDIA Reflex, and G-SYNC. One device, three lives. The takeaway The story of AI has been a story of renting access to power. RTX Spark points at a different future: owning it, carrying it, and pointing it at whatever you're building — without the meter running. So here's the real question If you had a portable petaflop with 128 GB of unified memory, what's the first thing you'd run on it — a local LLM, an agent swarm, your own fine-tune? Drop it in the comments. I'm genuinely curious what this community would build first.saravananp4 months agoDay Hiker III200Views1like0CommentsWhat challenges have you faced in scaling your storage to meet the needs of AI workloads?
How are you addressing them?MacchiSmith1 year agoCommunity Manager151Views0likes0CommentsDo you believe that ChatGPT and similar AI technologies have the potential to outperform human testers in the future?
In this blog, The Role of Humans in AI Software Testing: It’s Bigger Than You Think, it dives into the AI’s need for human testers in improving its processes. More than a year after the launch of ChatGPT, its capabilities and functions have drawn astonished responses from users. Its ability to communicate intelligently and provide and store copious amounts of information has left the public in awe at how similar its functionality is to that of a human. Generative AI tools like ChatGPT.MacchiSmith2 years agoCommunity Manager132Views0likes0Comments