One Year of “Ask Us Everything”: John “Coz” Colgrove on Everpure’s Past, Present, and Future
A special Ask Us Everything anniversary conversation with Everpure cofounder John “Coz” Colgrove explores Everpure’s origins, technical innovations, AI, and the future of data management.54Views0likes0CommentsThe Vocabulary Problem Hiding Inside Your AI Strategy
Every enterprise I talk to right now is having some version of the same conversation: what do we upgrade, what do we expand, and how do we get ready for agents that need to touch everything. What's interesting is where that conversation actually stalls. It's rarely budget, and it's rarely the roadmap. It stalls because the room doesn't agree on what the words mean. "Data primacy." "Ontology." "Data lineage." "Enterprise data cloud." I hear these used almost interchangeably in vendor decks and internal strategy docs, and that's the problem: they're not synonyms. They're four different layers of the same stack, each answering a different question, and each one shows up as its own line item in your next upgrade cycle. Get the distinction wrong and you'll buy the wrong thing, staff the wrong team, or promise your board something your architecture can't actually deliver. Here's how they fit together, and why the difference matters for every expansion decision between here and wherever your AI transformation is headed. The 50-year assumption AI just broke For as long as most of us have built enterprise IT, applications came first and data came second. Each app owned its own dataset, held its own context, enforced its own definition of things. "Customer" in your CRM meant something different than "customer" in your billing system. That was fine, because a human was always in the loop to reconcile the difference. AI agents don't have that luxury. An agent reasoning across sales, support, and finance at the same time can't pause and wait for a human to translate between five definitions of "customer." It needs broad, timely, trustworthy access to data that means the same thing everywhere it shows up. That's the fracture point, and it's exactly why data primacy, ontology, and data lineage have all become urgent at once. They're the three things you need to fix that fracture, each doing a different part of the job. Data primacy: the "why" and the architecture Data primacy is the strategic answer to the app-centric problem: flip the model so data is primary and applications become secondary, interchangeable consumers of it. Everpure's CEO Charlie Giancarlo frames this around three principles, and honestly, they double as a decent audit checklist for your own architecture. Semantics travel with the data, not locked inside any one application. Data is conserved, not copied: one authoritative, governed source serves every agent and app that touches it. And governance lives at the data layer itself, not bolted on through app-level access controls. This is the executive-level framing. When you're building the case for why the next three years of infrastructure spend should look nothing like the last ten, data primacy is the language that resonates in that room. It's a statement about how IT should be architected, not a technical spec. Ontology: the "how" that makes it real Data primacy's first principle, that semantics travel with the data, doesn't happen on its own. Something has to formally define what a piece of data is, what it means, and how it relates to everything else in the enterprise. That something is an ontology: the properties, attributes, and classification schema that make raw data self-describing, instead of dependent on whichever application happens to be reading it. If data primacy is the destination, ontology is one of the roads that gets you there. It's a data-layer, semantic-layer capability: the dictionary and grammar that make your data readable by anything, including an agent that's never seen your schema before. Everpure Data Intelligence (formerly 1touch) is built specifically for this layer, using AI-driven classification to create a business-aware ontology that evolves as your data does, rather than going stale the moment your data model changes. Worth a look if ontology is anywhere on your upgrade list. Data lineage: the historical record that earns trust Ontology tells you what data means. Lineage tells you where it's been: the audit trail from origin, through every transformation, to wherever it's being used today. This is the layer that turns into a legal and regulatory requirement faster than the other two. When a regulator asks why your AI model rejected a loan applicant, "lineage" is the only acceptable answer. The EU AI Act, GDPR, and NIST frameworks are all raising the documentation bar here, and lineage is quickly moving from nice-to-have to table stakes: teams need to know where data originated, how it was transformed, and precisely which models it fed. Enterprise data cloud: where all three actually get operationalized Data primacy, ontology, and lineage are principles and capabilities. Somewhere, they have to live on real infrastructure: on-prem, edge, and public cloud, without turning into three separate management problems. That's what an enterprise data cloud is for. Think of it as the layer that turns data primacy from a philosophy into something you can actually run: a unified, virtualized layer of data governed by an intelligent control plane, delivered as-a-service, with automation and resilience built in rather than stitched together after the fact. It's the difference between managing storage and managing data: every array, every location, every cloud, under one system instead of a dozen silos each running their own rules. This is also where "delivered as a service" and "intelligent control plane" stop being slide-deck language and start showing up in practice: rebalancing and mobility, compliance monitoring and remediation, agentic workflows via MCP, all running on a unified data plane,(Everpure's enterprise data cloud) instead of bolted onto individual boxes. Evergreen//One is the consumption model that makes this deliverable as a service rather than a capital project. How the four concepts actually fit together Read top to bottom, and it's a stack, not a list. Data primacy sets the destination. Ontology and lineage are the two roads that get you there, one carrying meaning, the other carrying history. The enterprise data cloud is the ground all three roads are paved on. Why this vocabulary problem is actually a strategy problem Here's the part that matters for your next planning cycle. If your team talks "ontology" when the business actually needs a data primacy conversation, you'll end up buying a classification tool when leadership wants a mandate to change how every application relates to data. Talk "data primacy" to a room of data architects who need lineage documentation for an upcoming audit, and you'll sound like a slide deck instead of a plan. Every upgrade, every expansion, every step deeper into agentic AI is going to force this same translation problem. The stack doesn't care what you call it, but your budget, your compliance posture, and your ability to safely let agents loose on your data all depend on knowing which layer you're actually solving for. Get the vocabulary straight, and the roadmap gets a lot easier to write. Want to go deeper on evaluating your own ontology? Watch my conversation with Argenis Fernandez, Nike's Distinguished Software Engineer, on why enterprises still need one. Register here53Views0likes0CommentsEnabling Agentic AI via Pure1 Manage MCP Server
Everpure now offers a Pure1® Manage MCP Server so you can query information about your fleet using natural language questions. In this post, I’ll explain how the Pure1 Manage MCP Server works. The first section will explain MCP in general, and the second section will explain how to use our specific server. Feel free to skip to the Quick Start section if you’re already familiar with MCP and just need the parameters to plug into your host. What is MCP? MCP stands for "Model Context Protocol," and it's a way for users to connect their AI applications to external systems using tool calls. MCP tools are fundamentally rooted in application programming interfaces (APIs). An API is a set of rules and protocols that allows different software applications to communicate with each other. It acts as an intermediary, enabling one piece of software (the client) to request information or functionality from another piece of software (the server) without needing to know the server's internal workings. For instance, when you check the weather on your phone, the weather app uses an API to send a request to a weather service, which then returns the current weather data. AI applications have trouble making API calls directly because APIs are designed for completeness and correctness, not for an LLM to use easily. When an AI application wants to use an external system to handle a user’s request, it uses the MCP protocol to make a tool call. The AI (client) requests a function (the tool) from an external system (the server), and the system executes the function and returns a result. This makes MCP a system that standardizes and mediates API-like interactions, allowing AI models to leverage external, real-world capabilities. For more information, see this article on the MCP website: “What is the Model Context Protocol (MCP)?” How can customers benefit from the Pure1 Manage MCP Server? The Pure1 Manage MCP Server enables customers to securely integrate AI assistants, copilots, and agentic systems with live Pure1 telemetry and operational data—without building custom API integrations. It transforms Pure1 from a dashboard-centric experience into an AI-accessible platform, enabling natural language interaction, contextual automation, and real-time operational intelligence. Customers benefit from faster AI integration, reduced engineering effort, preserved security controls, and improved decision velocity across hybrid environments. What types of customer workflows are best suited for MCP? The Pure1 Manage MCP Server is particularly well-suited for agentic and AI-driven workflows, including: Fleet telemetry integration with customer copilots Expose Pure1 telemetry—arrays, volumes, workloads, metrics, and alerts—into internal copilots, chatbots, or AI platforms via MCP endpoints. Value: Unified operational visibility across hybrid and multi-platform environments Automation with context awareness Use MCP to validate storage state, health, performance, or capacity before executing provisioning, backup, or disaster recovery workflows. Value: Safer automation with contextual validation, reduced execution errors, and greater rollback confidence Hybrid cloud observability Correlate Everpure array performance and capacity metrics with application, VM, container, or cloud telemetry across environments. Value: Faster troubleshooting and improved end-to-end performance insights Conversational operational analytics Enable operators to ask real-time natural language questions, such as: “Which arrays are nearing capacity risk?” “Show me the top latency spikes in the last 24 hours.” “Summarize all critical alerts across regions.” Value: Rapid insight without navigating dashboards or exporting reports What the Pure1 Manage MCP Server can do The Pure1 Manage MCP Server exposes the Pure1 Manage REST APIs to AI applications. This means you can ask ad hoc questions about your fleet using natural language, and your AI application will use the server’s tools to query the answer. No programming required. Example conversation Here’s an example conversation demonstrating the use of the Pure1 Manage MCP Server: User: "What is the name of my oldest FlashArray and what is its serial number?" Chatbot:Processing Request: The AI recognizes this as a request for fleet information requiring a tool call. Tool Invocation: Get_hardware Response: The oldest FlashArray in your fleet is named FA-Prod-01 with serial number FA10123456. User: "Can you show me the average I/O latency for that array over the last 7 days?" Chatbot: Let me first check the available latency metrics, then query the historical data: Tool Invocation: Get_metrics Tool Invocation: Get_metrics_history Response: The average I/O latency for FA-Prod-01 (serial FA10123456) over the last 7 days was 0.385 milliseconds. User: "How many arrays do I have in total that are still under warranty?" Chatbot: Processing Request: The AI recognizes this as a request for a count of arrays filtered by warranty status. Tool Invocation: Get_array_support_contracts Response: You currently have 12 arrays in your fleet that are still under active warranty. Quick start Step 1: Register an API key in Pure1 Manage The Pure1 Manage MCP Server leverages the Pure1 Manage REST APIs. In order to access those APIs, you need to register an API key in Pure1 Manage. To do that, follow the directions in the The Pure1® REST API introductory blog post. After going through the instructions, you will have an application id and a private key file, which will be used to generate an access token to access the MCP server in step 2. Step 2: Set up the pure1_token_factory.py script Prerequisites: you need Python 3.12 or greater to run the script. Download pure1_token_factory.zip. Unzip the archive. Go to the unzipped folder in your command-line terminal. Optional but recommended: create and activate a Python virtual environment: python3 -m venv .venv source .venv/bin/activate Install the requirements: pip3 install -r requirements.txt. Run python3 pure1_token_factory.py <application_id> <private_key_file> Copy the generated access token from the script output for the next step. Step 3: Add remote MCP server to your AI application Follow the directions for your AI application to add a remote MCP server (see the Pure1 Manage MCP Server User Guide for instructions for specific chatbots). In general, they need the following information: Remote MCP Server address: https://api.pure1.purestorage.com/mcp Authorization type: header Header name: Authorization Header value: Bearer <access-token> Important: <access-token> is just a placeholder for the access token you generated in step 2. The actual header value should look something like “Bearer eyJ0eXAiO…” Important: you need to generate a new access token every 10 hours and copy it into your AI application You’ll need to run pure1_token_factory.py to generate a new access token every 10 hours, and manually copy the access token into your AI application’s config. Claude Desktop instructions Claude Desktop is a special case because it doesn’t let you set the Authorization header directly. You have to run the mcp-remote local MCP server and configure that to use the Pure1 Manage remote MCP server. Prerequisites You need to have Node.js version 18 or newer installed on your system. Configuration In Claude Desktop, go to Settings > Developer, and click Edit Config. Open the claude_desktop_config.json file in a plain-text editor like VS Code. Configure the mcp-remote server, which is necessary to pass the Authorization header to the Pure1 Manage MCP Server. Paste the token into the configuration file, then restart Claude Desktop. { "mcpServers": { "Pure1 API": { "command": "npx", "args": [ "-y", "mcp-remote", "https://api.pure1.purestorage.com/mcp", "--header", "Authorization:${AUTHORIZATION_HEADER}" ], "env": { "AUTHORIZATION_HEADER": " Bearer <paste access token here>" } } } Note: there might be other configuration options in this file. Be sure to leave them unchanged, and only insert the Pure1 API config in the mcpServers section. The space in the AUTHORIZATION_HEADER environment variable is important. It's there to work around a bug in Windows argument parsing. Please note that: The first time it uses a tool, it will ask you for permission. You can grant permission to all tools at once by going to Customize > Connectors > Pure1 API, and selecting Always Allow under Other tools. For more detailed instructions from Anthropic, please refer to: Connect to local MCP servers - Model Context Protocol.915Views1like0Comments
Using Pure1 AI Copilot to Assess CVE Exposure and Get Upgrade Recommendations
Fleet Security Assessment The Pure1 Fleet Security Assessment provides a fleet-wide view of the security posture of FlashArray and FlashBlade systems by correlating each asset's current software version against Everpure's curated CVE database. Determine whether an asset is exposed to a known CVE A storage administrator can: Log into Pure1. Navigate to Fleet Security Assessment. View all registered arrays within the fleet. For each array, Pure1 automatically identifies: Current Purity version Product family (FlashArray / FlashBlade) Array Name Array ID Serial Number Pure1 compares the running Purity version against the Everpure Product Security Advisory database and determines: Whether the version is affected by known CVEs. Severity of each vulnerability (Critical, High, Medium, Low). Whether a fix is available. Whether a workaround exists. Whether the CVE affects the customer's specific product. Selecting an individual array allows the administrator to review: CVE ID CVSS Score Severity Description Affected component Security Bulletin Fixed version Mitigation guidance This enables administrators to quickly prioritize remediation activities based on risk across their entire storage estate. Using AI Copilot AI Copilot provides a conversational interface to the same security intelligence, allowing administrators to ask questions in natural language rather than navigating multiple dashboards. Examples include: "Is array FA-01 exposed to any critical security vulnerabilities?" Another example: "Which arrays in my fleet are exposed to critical CVEs?" Administrators could also ask: "Show me every FlashBlade affected by OpenSSH vulnerabilities." or "Which arrays are running unsupported Purity versions?" Intelligent Upgrade Recommendations Rather than simply identifying vulnerable arrays, AI Copilot can also recommend an upgrade. AI Copilot will go beyond security and determine whether the array is actually ready for upgrade. Example prompt: "Can I safely upgrade FA-01 to Purity 6.9.4?" AI evaluates: Hardware compatibility Controller generation Installed DirectFlash modules Current Purity version Intermediate upgrade requirements Known upgrade restrictions Health status Replication configuration SafeMode Supportability Current alerts Capacity utilization Pending hardware failures Replication synchronization Outstanding upgrade blockers And determines the most appropriate version based on the customer's environment based on customer’s Current Purity version Current LLR Current ER Security vulnerabilities Feature requirements Hardware support Known software defects Current advisories Upgrade path complexity Engineering recommendations Customer support policy Example: Users could ask: "What version should I upgrade to?" Fleet-wide Upgrade Planning AI could also answer strategic questions such as: "Show every array requiring a security upgrade."or "Which arrays should be upgraded in the next 30 days?" Conclusion The integration of Pure1 Fleet Security Assessment and AI Copilot fundamentally transforms storage security management from a reactive, manual task into a proactive, data-driven strategy. By providing deep visibility into CVE exposure across the entire fleet and delivering intelligent, context-aware Purity upgrade recommendations, Pure1 empowers administrators to mitigate risks before they can be exploited. This shift to strategic fleet planning ensures that storage environments remain resilient, compliant, and optimized, allowing organizations to focus on innovation rather than crisis management.226Views0likes0CommentsAccelerate 2026 - Part 1 - Everyone Wants Your Data
Back in February, I wrote that I had never been to Pure//Accelerate. This year, I still am not in Las Vegas. I watched the Everpure Accelerate 2026 opening keynote live from my home office, which turned out to be a different kind of vantage point. Not better than being there. Not worse. Just different. You do not get the hallway energy. You do not get the sponsor booths. You do not get the accidental conversations that happen while looking for coffee (or tea in my case). You do not get to read the room in the same way. You are not surrounded by the noise, the music, the badge lanyards, the customer reactions, or that strange conference feeling where everyone is tired and energized at the same time. A keynote viewed remotely has to work harder because the production does not carry you in the same way. If the speakers are just reading slides, you feel it immediately. If the story is thin, the distance makes it thinner. If the message is only a collection of announcements, you start checking email. But if the story is real, the distance does something interesting. It removes some of the theater. You are left with the words, the pacing, the ideas, and whether the people on stage actually believe what they are saying. This morning, the parts that landed with me were not the parts that felt the most polished. They were the parts where the keynote stopped sounding like a keynote and started sounding like people trying to explain a real shift in the industry. For me, the strongest moments came from Charlie Giancarlo, Chadd Kenney, Shawn Rosemarin, and the NVIDIA conversation. Not because they had the most slides. Not because they had the most numbers. They landed because they are storytellers. That matters more than we sometimes admit in enterprise technology. A slide reader can tell you what a product does. A storyteller can tell you why the product had to exist and why it matters to the customer or partner. There is a difference. And this morning, the difference mattered. Charlie’s most important line came early, and it changed the shape of the keynote. He said he was not going to talk about data storage. He was going to talk about data. For a storage company’s major customer event, that is not a small pivot. It would have been easy for Everpure to spend the morning celebrating the familiar things. Growth. Customer count. Market share. Flash leadership. Subscription run rate. Fusion adoption. Gartner recognition. Net Promoter Score. Performance numbers. Efficiency numbers. All of that was there, and all of that matters. But the real keynote was not about proving that Everpure is good at storage. The real keynote was about arguing that storage is no longer the highest-level conversation. Data is. That is where the rebrand from Pure Storage to Everpure starts to become more than a name change. A company called Pure Storage can be excellent at arrays, controllers, upgrades, density, performance, and simplicity. A company called Everpure has to earn the right to talk about the enterprise data cloud, and that is a much larger promise. It is also a much riskier promise. Because once you move north of storage, you are no longer talking only about where data lives. You are talking about who controls it, who understands it, who governs it, who protects it, and who gets to use it. That is where Charlie’s message became interesting. His argument was that the enterprise has spent decades living in an application-centric architecture. ERP had one version of the business. CRM had another. ServiceNow had another. HR systems had another. Analytics platforms copied data out of all of them. Data lakes were built to make sense of the mess. Now AI agents are being asked to reason across that same fragmented landscape. That is the problem. Not AI in theory. AI on top of fragmented truth. We have all seen some version of this. The definition of a customer changes depending on which system you ask. The data in one application does not quite match the data in another. A report is technically correct, but only according to one source. A copy was made for analytics, another for backup, another for a project, another for a data science team, and one more because someone needed it urgently two years ago and nobody knows if it is still being used. Now imagine asking an AI agent to act on that. That is where the phrase “Data Primacy” becomes more than keynote language. From what I understood this morning, Data Primacy is Everpure’s argument that data should no longer be trapped inside applications as a secondary object. The data itself, along with its context, relationships, governance, and sources of truth, has to become primary. Applications still matter. Workflows still matter. SaaS still matters. But the enterprise cannot keep allowing every application to define its own version of reality and then expect AI to make intelligent decisions across the pile. That is not sustainable. One of the strongest lines from Charlie was the idea that every vendor wants your data. Every SaaS vendor wants your data. Every analytics vendor wants your data. Every AI vendor wants your data. But what they really want is not just the data. They want the context. They want the meaning. They want to know how a customer in one system relates to a contract in another, a support case in another, an invoice in another, a shipment in another, a security policy in another, and a business outcome somewhere else entirely. In the AI era, context is the new land grab. That is the sentence I kept coming back to during the keynote. Everyone wants your data, but the bigger fight is over who owns the context. That is why this morning did not feel like just another AI infrastructure pitch. It felt like Everpure trying to move the conversation from managing arrays to managing truth. That is a big claim. It needs proof. And that is where Chadd Kenney’s part of the keynote mattered. Chadd is one of those speakers who can make infrastructure feel like an actual story instead of a list of capabilities. That is not easy. Storage features can get very technical very quickly, and if you are not careful, everything turns into a blur of replication, snapshots, policies, performance, controllers, and acronyms. But Chadd framed the platform in a way that made sense. First, the unified data plane stores the data. Then the intelligent control plane governs and operates it. Then the universal data intelligence layer helps understand it. Together, those pieces create a different operating model. That phrase, operating model, is important. Because the most interesting part of the demo was not just that Fusion can automate tasks. It was that Everpure is trying to change the relationship between people and infrastructure. The old world asks humans to be perfect by hand. Log into this array. Check that policy. Fix that snapshot setting. Compare it to the spreadsheet. Make sure the production workloads are covered. Exclude dev and test. Check compliance. Update the retention period. Open the change. Wait for the window. Hope nobody missed one. We have normalized that kind of work for years. Then we call it operational discipline. Sometimes it is. But sometimes it is just human beings being forced to compensate for systems that do not understand intent. The Fusion demos showed something better. Define the policy once. Attach intent to the workload. Let the control plane detect drift. Let it show violations. Let it recommend a fix. In some cases, let it act. In other cases, keep the human in the loop, but stop making the human do repetitive work that the platform should be able to understand. The ransomware snapshot example was a perfect illustration. A customer mandate changes retention from fifteen days to thirty days. In many environments, that becomes a manual chase across infrastructure. In the keynote demo, it became a policy problem, a compliance view, a remediation path, and an audit trail. That is what infrastructure teams actually need. Not another dashboard that tells them something is broken. A system that understands what “correct” looks like and helps keep the environment there. The workload mobility demo made the same point from a performance angle. If the platform can see that a workload is trending toward a service level violation, recommend a better placement, validate the move, and relocate that workload without the application owner noticing, that is not just automation. That is infrastructure keeping a promise quietly. And quiet matters. The best infrastructure usually disappears. Nobody sends a thank-you note because latency did not spike. Nobody opens a champagne bottle because a replication policy worked. Nobody celebrates the outage that did not happen. But those invisible wins are the difference between a team that spends its life firefighting and a team that gets to work on the next thing. That is why the Active Cluster for File demo also worked. Synchronous replication for file sounds technical, and it is. But the emotional value is simple. When something fails, the business does not want a heroic recovery story. It wants no story at all. The workload quietly packed its bags and moved. That line stayed with me because disaster recovery should be boring. Boring is the goal. Boring means the policy worked, the automation worked, the architecture worked, and the humans did not have to assemble on a bridge call at 2 a.m. to save the day. Then Shawn Rosemarin took the keynote into the AI conversation, and again, the strength was in the framing. The bottleneck stalling AI is not compute. It is not models. It is not tooling. It is data. That is the part of the AI conversation that I think many customers are starting to feel more clearly. For the last few years, the market has been obsessed with models and GPUs. That made sense. There was a lot to understand, and the infrastructure requirements are real. But most customers are not trying to build the next frontier model. They are trying to unlock the intelligence that already exists inside their own business. Their documents. Their contracts. Their transactions. Their support history. Their clinical records. Their policies. Their engineering files. Their internal knowledge. Their institutional memory. That does not become useful just because someone points a model at it. It becomes useful when the data is prepared, classified, curated, governed, indexed, vectorized, and delivered with the right context at the right time. That is why the Everpure Data Stream announcement with NVIDIA mattered. The message was not simply, “We can feed GPUs fast,” although performance absolutely matters. The more important message was that enterprise AI needs a way to make data AI-ready without creating another silo, another copy, another stale version of the truth. Shawn made the point clearly: other vendors want you to copy your data into their system. But a copy is always behind. That is such a simple sentence, but it carries a lot of weight. A copy has to be protected. A copy has to be governed. A copy has to be reconciled. A copy has to be secured. A copy can drift. If AI is going to answer questions, automate workflows, make recommendations, or support decisions, stale context is not just inefficient. It is dangerous. That is where the NVIDIA conversation added credibility. The point was not just that Everpure has a partner logo on a slide. The point was that AI has become a full-stack infrastructure problem. Data has to move efficiently. GPUs cannot sit idle waiting for bytes. Inference needs low latency and quick access to the right information. Agents need context. Networking matters. Storage matters. Hardware matters again. I liked the line about hardware being cool again. I liked it because it is funny, but also because it is true. For years, parts of the industry talked as if infrastructure had become invisible. Cloud abstracted it. SaaS hid it. Software ate the world, and many people acted as if the physical layer was someone else’s problem. AI ended that illusion. When customers are investing serious money in GPUs and trying to build real AI capability, storage is not a commodity. Networking is not plumbing. Metadata performance is not trivia. Power is not someone else’s concern. Operational excellence is not optional. The physical world is back in the strategy conversation. Maybe it never left. Maybe some people just stopped looking. That is why the keynote worked for me, even from my home office. Not because every demo was relevant to every customer. Not because every phrase was perfect. Not because I think one keynote answers every question. That is what the next two days are for. It worked because the best speakers were not just announcing things. They were connecting the dots. Charlie explained why the application-centric model is running out of room. Chadd showed what it looks like when infrastructure starts operating from intent instead of manual heroics. Shawn connected AI success back to data readiness instead of model worship. The NVIDIA conversation reminded everyone that AI is not magic. It is infrastructure, data movement, context, governance, and execution. That is a story. And in enterprise technology, the story matters because customers are not just buying features. They are buying a way out of the mess they are already in. The mess is fragmentation. AI did not create that mess, but AI is making it impossible to ignore. That may be the real takeaway from day one of Accelerate. The AI era is forcing enterprises to confront the data architecture choices they have been living with for decades. The old model was manageable when humans were the ones reconciling the gaps. It becomes much more dangerous when agents begin acting on top of those gaps at machine speed. That is why Everpure’s move toward Data Primacy is worth paying attention to. It is not just a product direction. It is a point of view. The application should not own the truth. The copy should not become the truth. The dashboard should not pretend to be the truth. The enterprise needs to own its data, understand its context, govern its use, and make it available to applications, analytics, and AI in a way that is coherent and trustworthy. That is easy to say and very hard to do. But this morning, for the first time, I felt the full shape of what Everpure is trying to become after the rebrand. Not just a storage company with a new name. Not just a platform company using AI language because everyone has to. But a company trying to move the enterprise conversation north of storage and into the question that will define the next decade: Who owns the context of your business? Because everyone wants your data. The companies that win will be the ones that know what it means. I appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere194Views1like1Comment
The Art of Sizing: The Seven Signals That Help Decide Oracle 26ai Readiness
The Art of Sizing — Series Categories: Databases · Oracle · AI and Machine Learning By Thomas Stutesman, Principal Field Solutions Architect, Everpure A migration readiness scorecard turns raw Oracle AWR telemetry into seven plain-language signals — and shows you exactly where a lift-and-shift would carry yesterday's problems into tomorrow's platform. The migration everyone is planning for Across the industry, many organizations are now looking to move to Oracle AI Database 26ai. The release promises autonomous efficiency, AI-driven insight, and native vector search — but for most teams the path forward is clouded by one uncomfortable question: is our current infrastructure sized for tomorrow, or are we carrying the weight of yesterday's inefficiencies? The 26ai Migration Readiness scorecard is one of the helpful tools Everpure has created to make that migration easier. It takes the telemetry you already have — your Oracle Automatic Workload Repository (AWR) reports — and translates it into a clear, consistent read on where each database stands, so you move with evidence instead of assumptions. This is the first idea in our Art of Sizing series: for a decade, cheap flash and fast cores let us over-provision and "throw hardware at it." Oracle 26ai — with real vector workloads and a hardware market where components cost more and take longer to arrive — ends that era. Disciplined sizing is back, and it starts with reading the right signals. What the scorecard shows Point the assessment at an estate and it produces a single view: every database, scored across seven signals, rolled up into a combined readiness score. In one illustrative example across eight databases, the combined readiness score was 118 out of 168 — with 0 Ready, 7 Caution, and 1 Risk. None were a clean lift-and-shift: seven needed validation and tuning, and one needed remediation before it could move. Each database is scored across the seven signals with a simple traffic light, and the lights roll up into a score out of 21 — seven signals, three points each: Ready — 3 points — inside the healthy threshold Caution — 2 points — worth validating Risk — 1 point — attend to before you move A score of 18–21 is favorable, 13–17 means review needed, and below 13 flags remediation. Think of it as a current-state indicator that tells you where the risk concentrates — not a migration certification. A red flag doesn't mean "cannot migrate." It means the problem will follow you into 26ai — or get worse — if you size the new environment from the old box instead of from the evidence. The seven signals, one by one These are the value items to worry about when sizing for and moving to 26ai. For each, here is what it reads from AWR, why it drives your target design, what a red is telling you, and how Everpure helps you act on it. Signal 01 — System Capacity Reads DB Time against available CPU cores, average active sessions, and host CPU pressure. This sets the compute floor for the target and drives per-core Oracle licensing — size to the old ceiling and you inherit the old bottleneck. On top of that, 26ai's vector and embedding work adds fresh CPU demand. Red means: the source is already CPU-bound; moving as-is relocates the constraint. You need real headroom, not a like-for-like footprint. How Everpure helps: the assessment reports peak (not averaged) CPU demand per database and translates it into a right-sized core count — so the target is provisioned for the real workload plus deliberate headroom, and licensing is planned rather than guessed. Signal 02 — SQL & Parse Reads hard-parse rate, literal (non-bind) SQL, library-cache and cursor-sharing behaviour. 26ai changes optimizer behaviour, so heavy hard-parsing burns CPU, pressures the shared pool, and invites plan regressions on the new release. Red means: application-level SQL that will keep burning CPU or regress on cutover. Plan-stability work (SQL Plan Management, baselines) and shared-pool sizing belong before the move. How Everpure helps: because the assessment looks at the whole estate, not one instance, it surfaces shared SQL/parse patterns across databases — so one remediation effort (often "add bind variables") protects many migrations and lowers the CPU you have to size and license for. Signal 03 — Wait Profile Shows how DB Time splits across CPU, I/O, concurrency, and commit/log waits. It tells you what kind of bottleneck you are actually sizing for — a commit-bound database and an I/O-bound one need very different target designs. Red means: DB Time is dominated by a problematic wait (log file sync, buffer busy, latch/enqueue). Sizing CPU or storage without addressing it just moves the pain. How Everpure helps: Everpure maps the dominant wait class to the right lever — low, predictable write latency on FlashArray for commit/log waits; CPU or memory changes for concurrency waits — so the target attacks the real bottleneck instead of over-buying everywhere. Signal 04 — I/O Profile Reads read/write IOPS, throughput, block size, and latency. This is the direct input to storage sizing, and it separates latency-sensitive OLTP from bandwidth-driven scan/DW workloads — which size very differently. Averages hide the peak windows that actually test the array. Red means: real I/O demand the target tier must sustain. Under-provision here and everything above it — waits, capacity, response time — degrades. How Everpure helps: the assessment moves beyond averages to hour-by-hour peak-window analysis and turns it into a concrete IOPS/throughput/latency target for FlashArray — sub-millisecond and consistent, so the design performs at peak, not just on paper. Signal 05 — Memory Reads SGA/PGA sizing, buffer-cache behaviour, and Oracle's own memory advisories. Right-sizing memory on the target avoids trading RAM savings for a flood of avoidable physical I/O — and under-sized memory quietly inflates the I/O profile, so the two signals move together. Red means: memory is under-provisioned and driving physical reads that should be cache hits. Size SGA/PGA to demand rather than copying the old config. How Everpure helps: Everpure correlates memory pressure with observed I/O, so recommendations account for both together — enough memory to cut needless physical reads, and storage sized for what genuinely reaches disk. Signal 06 — Temp & Work Reads temp tablespace usage, sort/hash spills, PGA work-area activity, and multipass operations. Analytics, reporting, and AI-adjacent workloads live or die on temp and PGA — and 26ai vector operations add sort/compute patterns you have not sized for before. Red means: large sorts/hashes are spilling to temp; without PGA and temp sizing, the workload is slow on day one regardless of platform. How Everpure helps: the assessment quantifies spill behaviour and feeds it into PGA and temp-tier sizing, while FlashArray's consistent low latency keeps unavoidable spill cheap rather than catastrophic. Signal 07 — Segment Risk Reads large or fast-growing segments, chaining, LOBs, partitioning, and use of features like TDE, Hybrid Columnar Compression, and Smart Scan. These are the objects that don't migrate cleanly — reorg candidates, feature-compatibility items, and capacity-growth landmines. Red means: schema-level cleanup, not just capacity: objects that need reorg, or that depend on features the target must be configured to support from day one. How Everpure helps: Everpure auto-detects active features (TDE, HCC, Smart Scan) so the target is configured for them without over-provisioning, and replaces full clones and legacy triple-copy redundancy with space-efficient snapshots and external redundancy to reclaim capacity. From evidence to a right-sized migration The scorecard is the front door. Behind it is an assessment built to turn these seven signals into decisions you can defend to procurement and operations alike. It captures every instance for an ecosystem view, replaces multi-day averages with peak-window analysis, and translates raw metrics into specific storage and configuration recommendations for a 26ai target. It runs privacy-first — hostnames and SQL identifiers are masked, and only the actionable results are shared. Sometimes the biggest finding is what you don't need to buy. One prospect expected to buy 200 TB. The workload needed 18 TB. The gap was legacy ASM high-redundancy (three data copies) plus full clones for dev/test. Moving to Oracle-recommended external redundancy on Everpure and space-efficient snapshots reclaimed roughly two-thirds of the footprint and eliminated over 180 TB of wasted capacity — exactly the kind of trap that nameplate-based sizing would have locked in. From there, a right-sized design lands on a platform built for database density: Everpure FlashArray//XL R5 delivers sub-millisecond, consistent latency and industry-leading data reduction that absorbs vector growth economically. Pure Fusion presets encode your sizing discipline once so every 26ai environment is provisioned the same way, and Pure1 adds fleet-wide performance, capacity forecasting, and application-level context. A sizing-first path to 26ai Assess. Send your AWR reports; the 26ai Readiness Assessment is generated automatically, with identifiers masked. Interpret the signals. Reds are the pre-migration punch list; cautions are the validate list. Watch for fleet-wide patterns. Remediate reds first. Fix CPU, SQL/parse, dominant waits, and segment issues before cutover. Right-size the target. Size compute, memory, temp/PGA, and storage to the measured peak — and strip out redundancy and clone inflation. Provision consistently. Use Pure Fusion presets so every environment is built to the same standard. Validate with a pilot. Confirm behaviour against a representative pilot and target telemetry before scaling the wave. Summary Oracle 26ai brings back the art of sizing. The 26ai Migration Readiness scorecard reads seven signals from your AWR data — System Capacity, SQL & Parse, Wait Profile, I/O Profile, Memory, Temp & Work, and Segment Risk — so you can remediate the reds, right-size the target to your real workload, and move to 26ai with confidence instead of guesswork. Know where you stand — send us an AWR report, and Everpure's Oracle experts will run the 26ai Readiness Assessment on your environment and walk you through the seven signals, your remediation punch list, and a right-sized target design. The readiness score is an AWR-derived, current-state indicator to guide investigation and planning. It is not a migration certification, a final target-platform sizing, or a target-array headroom calculation — those decisions require workload requirements, target telemetry, compatibility checks, and a representative pilot. Database figures shown are illustrative. Oracle is a trademark of Oracle Corporation. © 2026 Everpure, Inc.83Views0likes0CommentsClaude Code as Database SRE: Catching What Your Monitoring Never Will with Everpure Fusion MCP
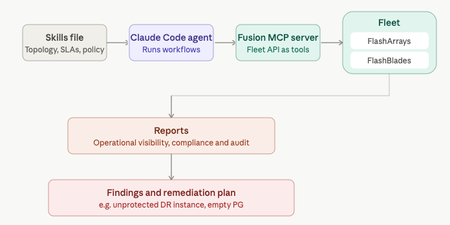
Your DR site might be quietly unprotected and no alert will tell you. That's the gap Anthony Nocentino, Principal Architect at Everpure, Microsoft Data Platform MVP, and self-described computer nerd set out to catch. He built a Database SRE agent using Claude Code and the Everpure Fusion MCP server to audit SQL Server fleets against compliance policy, uncovering a silently unprotected DR instance before disaster struck. Read the full report at "Using Claude Code as a Database SRE Agent with the Everpure Fusion MCP Server"73Views0likes0CommentsGet rid of stressful infrastructure headaches. Everpure Fusion handles your data, autonomously.
It happens! It's 11:45 PM on a Friday. An alert fires and storage latency has spiked across a production workload. The operator digs in and traces it back to an automated tiering policy that quietly moved a hot dataset to a slower tier because it looked idle based on a 24-hour access window, right before a scheduled batch job that runs every weekend. Nobody changed anything. The policy did exactly what it was configured to do. But nobody remembers configuring it that way, the documentation hasn't been touched in two years, and the monitoring dashboard shows storage as "healthy" because utilization is fine. It's just in the wrong place. The operator overrides the tier, performance recovers, and spends the next hour writing an incident report for a problem that shouldn't exist. A system that was supposed to make life easier made a decision with no context, no warning, and no visibility into why. That's the anger that doesn't go away quickly. It's not just frustration at the incident. It's the feeling that the tools are working against you instead of with you. The core problem in that story was a system making decisions with no context, no warning, and no visibility. Everpure Fusion attacks each of those problems: Unified visibility across the entire fleet: Everpure Fusion provides a global dataset as a single source of truth for discovery, management, and configuration of storage arrays so the operator isn't piecing together what happened across multiple dashboards, multiple arrays, multiple tickets after the fact. They see the full picture in one place, before things go wrong. Intelligent workload placement: Rather than static policies quietly acting on stale access patterns, Everpure Fusion uses AI-guided placement to boost performance and efficiency for every workload. It understands workload behavior, not just utilization snapshots, the kind of context that would have caught a batch job pattern before tiering the dataset down. Policy-driven governance with real control: Automated orchestration cuts manual tasks and speeds service delivery, while unified controls simplify audits, reduce risk, and prove compliance fast. Policies are visible, documented, and governable. Not buried configs nobody remembers setting. Built into the platform, not bolted on: Evepure Fusion is now simply a part of Purity, meaning it is not an add-on you have to install or buy, but rather a core piece of the Purity operating system. The operator doesn't have to manage another tool. The intelligence is already there. The operator in that story didn't need more alerts. They needed a system that understood context, made decisions transparently, and gave them control without requiring them to be online at midnight to maintain it. That's exactly the gap Everpure Fusion is designed to close - with One Fleet, Zero Complexity. Why policy-driven storage operations matter Everpure Fusion is built as the core of Everpure intelligent control plane that manages all arrays including FlashArray, FlashBlade, and cloud as a unified fleet, with one topology, one API, and one operational framework regardless of protocol or local - datacenter, cloud or edge. That uniformity is what makes policy enforcement reliable at scale. Everpure Fusion introduces workload-based provisioning through presets, which are predefined policy-driven templates for specific workload types, encoding protection policies, replication, and SafeMode retention from the moment a workload is provisioned, not patched in after an incident. Admins no longer need to pre-plan and tune deployments manually, which reduces the risk of non-compliance and improves resiliency by ensuring workloads are provisioned correctly from the beginning. The result is infrastructure that enforces your intent, not just your last manual action. Intelligent placement, rebalancing, and fleet-scale capacity control If you manage storage at scale, you've probably seen this scenario play out more than once. One array is buried, running hot, and screaming for relief. Three aisles over, another array is sitting at 40% utilization, doing almost nothing. And somewhere in between, your team is scrambling to provision capacity, kick off an emergency migration, and explain to stakeholders why an SLA was missed on a workload that, in hindsight, never should have been placed there in the first place. This is not a people problem. It is a tooling problem. And it is remarkably common. Everpure Fusion starts solving this problem at the moment of provisioning. When a new workload lands, most storage systems do a simple capacity check and place it wherever space is available. Everpure Fusion does something fundamentally different. The placement engine evaluates every array in the fleet simultaneously, looking at IOPS headroom, throughput capacity, and physical utilization before making a decision. The goal is not just to find somewhere to put the workload. It is to find the right home for it, one where it can live comfortably for the long term without creating a bottleneck down the road. Think of it as placing workloads with intention rather than convenience. Of course, environments do not stay static. Workloads grow, usage patterns shift, and an array that looked healthy six months ago can become a problem today. Everpure Fusion accounts for this with continuous rebalancing built directly into its operation. When an array starts trending toward overload, Everpure Fusion detects it and begins orchestrating data movement across the fleet automatically. No manual intervention required. No application downtime. Data migrates in the background while workloads keep running, and arrays that were sitting underutilized suddenly become productive members of your infrastructure. At fleet scale, now supporting up to 64 arrays, this turns capacity management from a constant firefight into something that largely runs itself. What makes this possible without disruption is how Everpure Fusion executes the move under the hood. It leverages ActiveCluster to stretch the volume across both the source and target arrays simultaneously, creating a synchronous mirror in place. Once the stretch is established, volumes are connected on the target array and hosts auto-discover the new target paths through standard multipathing. The target then validates that path usage is healthy and confirmed before any cutover begins. Only after that validation is complete are the volumes disconnected from the source, ensuring there is zero gap in access at any point in the sequence. Everpure Fusion then unstretches from the source array to complete the rebalance and release its capacity. The result is a seamless, non-disruptive migration that the application never sees. What truly sets Everpure Fusion apart from a standard load balancer is what happens under the hood. Powered by Pure1 AI and up to 30 days of historical workload data, Everpure Fusion does not just look at what is happening right now. It looks at what is about to happen. Say you have a workload that runs a heavy batch job every Saturday night. Everpure Fusion knows that. It has seen the pattern. So when the placement engine is evaluating tier assignments, it will never recommend moving that workload to a lower-performance tier just because it looks quiet on a Tuesday afternoon. It understands what Tuesday quiet actually means in context. And if that workload somehow ends up on the wrong tier, perhaps through a manual change or a migration gone sideways, Everpure Fusion will proactively raise a violation before the weekend arrives. Not after the SLA is missed. Before. The cumulative effect is that customers can operate their fleets closer to full utilization without the anxiety that normally comes with it. Underused hardware gets activated, incremental purchases get deferred, and the reactive, always-behind-the-curve model of capacity management starts to look like a problem from a previous era. And Everpure Fusion does not stop at the infrastructure layer. Through its integration with Pure1 Application Intelligence, Everpure Fusion gains deeper visibility into the nature of the workloads themselves, not just how they behave, but what they actually are. That additional context means smarter decisions at every level, from initial placement to long-term tier management, grounded in a more complete picture of what your environment is really doing. Workload rebalance and mobility will be available towards the end of 2026. Compliance as part of the control plane Most storage compliance workflows follow the same pattern: an audit is announced, someone pulls reports from three different tools, cross-references configuration against a spreadsheet of expected settings, and spends two weeks proving that workloads are protected the way they're supposed to be. Then the audit ends and nothing changes until the next one. That model breaks at fleet scale. When you're managing dozens of arrays across multiple sites and protocols, manual audits don't just slow you down — they leave gaps that only get discovered at the worst possible time. Everpure Fusion Compliance is built into the control plane, not bolted on after provisioning. Because Everpure Fusion presets encode protection policies, replication requirements, SafeMode retention, and QoS settings at deployment time, Everpure Fusion always knows what every workload's intended configuration is. Drift detection is continuous — not periodic. When a workload deviates from its preset, Everpure Fusion instantly surfaces the violation — visible in the UI, queryable via API or CLI, and accessible to AI agents through an MCP server. Remediation can be triggered directly through the same interfaces, without pulling in a separate tool or writing a custom script. Fleet-wide compliance dashboards give storage admins a live view of posture across every array, with exportable audit-ready reports that don't require manual assembly. The shift is meaningful: compliance becomes a property of how the fleet operates, not a project that interrupts how the team works. Everpure Fusion Compliance will be available towards the end of 2026. From dashboards and scripts to natural-language fleet operations You know the drill. A latency spike hits production. You open three dashboards, run a handful of CLI queries, dig through alert logs, and piece together enough context to understand what happened — and by then, you've already spent 45 minutes on a problem that should have taken five. The issue isn't the tools. It's that the context your fleet holds is trapped across systems that don't talk to each other. Everpure Fusion MCP Server changes that. Built on the open Model Context Protocol standard, it connects any MCP-compatible AI assistant — Claude, ChatGPT, Copilot, or internal agents — directly to live Everpure Fusion fleet state. Arrays, workloads, capacity, performance metrics, alert history, configuration, and placement data are normalized into clean, structured JSON and made available to AI in real time, pulled directly from Everpure Fusion and Purity REST APIs. The result: instead of navigating dashboards and stitching together CLI output, you ask a question. "Which arrays are approaching capacity?" "What's driving latency on this workload?" "Which workloads are drifting from their preset?" Everpure Fusion MCP Server answers from live fleet context, not stale snapshots. This is the on-ramp to agentic storage operations. Everpure Fusion already enforces policy and placement across the fleet. Pure1 adds AI-driven analytics and recommendations on top. Together, they give infrastructure operators the foundation to move from reactive troubleshooting to intent-driven, increasingly autonomous fleet management. Using topology groups to encode real infrastructure boundaries If your Everpure Fusion fleet's topology model lives in a color-coded spreadsheet, three wikis, and the institutional memory of one senior admin who never takes vacation — this is for you. Everpure Fusion, built into Purity for FlashArray and FlashBlade, introduces Topology Groups: fleet-scoped objects that let you describe your arrays in the same language your architecture diagrams already use — regions, availability zones, datacenters, rows, racks. No more provisioning a Everpure Fusion workload and hoping it lands in the right building. A Everpure Fusion Topology Group is a hierarchical, tree-structured object. Groups nest up to 10 levels deep (global → us-east → az-us-east-1a → dc01 → row3 → rack12), each array belongs to exactly one parent, and cycles are rejected at write time. Critically, they encode placement semantics — not access control. RBAC stays in Pure1 Resource Groups; topology stays in Everpure Fusion topology. Once modeled, Everpure Fusion presets reference groups using <group>.arrays notation. Everpure Fusion intersects the preset's allowed arrays with the group's membership at placement time. If there's no overlap, Everpure Fusion provisioning fails fast with a clear error — not silently in the wrong zone. The Everpure Fusion CLI shorthand makes automation clean: purevol list --context az-us-east-1a.arrays Everpure Fusion membership changes propagate automatically across the fleet. You stop maintaining a second source of truth outside the control plane. Stop treating topology as tribal knowledge. With Everpure Fusion, make it a first-class part of the intelligent control plane. Extending the model to Kubernetes and virtualization Most infrastructure operators are managing two parallel storage worlds right now: traditional VMs and databases on one side, Kubernetes-based containerized workloads on the other. Separate toolchains. Separate provisioning workflows. Separate everything. Everpure Fusion changes that. Through the Portworx Fusion Controller, Everpure Fusion extends its policy and placement control plane directly into Kubernetes — without forcing developers to change their existing workflows. Everpure Fusion auto-discovers your FlashArray and FlashBlade fleet, then exposes Everpure Fusion presets as native Kubernetes StorageClasses. That means when a developer requests a persistent volume, Everpure Fusion's placement engine resolves it against your existing policy constraints — storage class, protection policy, topology group, replication requirements — the same way it does for any other Everpure Fusion workload. No separate control plane for modern environments. No array-by-array configuration for each cluster. New arrays added to the fleet are automatically discovered and configured, so the operational model stays consistent as infrastructure grows. For VMware environments, Everpure Fusion extends the same operational model through the Everpure Fusion vSphere plugin, connecting storage management directly into virtualization workflows instead of running it as a separate administrative domain. The result: one control plane, one set of policies, one placement engine — spanning VMs, containers, and databases across the fleet. That is fewer parallel stacks to operate, less configuration drift between environments, and a more scalable path to consistent storage operations across the full infrastructure stack. Everpure Fusion as the storage admin foundation for autonomous operations The through-line across everything covered in this blog is simple: Everpure Fusion gives infrastructure operators a unified, policy-driven control plane that enforces intent consistently — across provisioning, placement, compliance, topology, and now Kubernetes and virtualization. That foundation matters because autonomous storage operations do not start with AI. They start with structure. Topology groups encode where workloads belong. Presets encode how they should be configured. Everpure Fusion presets exposed as StorageClasses ensure Kubernetes environments follow the same rules as everything else. When that structure is in place, AI can recommend, optimize, and eventually act — because the context is already clean, trusted, and machine-readable. For storage admins, the shift is real: less time resolving incidents caused by placement decisions nobody remembers making, more time defining the intent that governs the fleet. Everpure Fusion is that foundation — built into Purity, not bolted on. Want to learn more about Everpure Fusion? Check out the following links to dive deeper: Join the Everpure Fusion Mastery Program to build expertise, complete hands-on activities and earn rewards. Sign up for a Fusion test drive to try it out on your own time. Check out more about Fusion product details. Watch our cool new Fusion demo videos. Read Everpure Fusion Datasheet157Views0likes0CommentsAccelerate 2026 - Part 2 - The Light Switch Test
Earlier, in Part 1, I wrote that the Everpure Accelerate 2026 opening keynote did not really feel like a storage keynote. My takeaway from day one was simple: Everyone wants your data. The bigger question is who owns the context. Day two answered a different question. If day one was about why the Enterprise Data Cloud matters, day two was about how customers are supposed to get there without turning it into another giant transformation project that sounds great on stage or in a boardroom and then dies somewhere between budget approval, staffing constraints, internal politics, and the next urgent outage. That is why the second keynote mattered. It was not trying to restart the vision. The vision had already been established. It was about turning that vision into something customers could actually use: a methodology, a blueprint, and a way to connect data architecture to risk reduction, efficiency, agility, modernization, and business outcomes. And then John Colgrove, Coz, did what Coz does. He simplified the whole thing. Not by making it smaller. By making it clearer. The phrase that stayed with me from his session was not a technical phrase. It was not Enterprise Data Cloud, Data Primacy, Fusion, data intelligence, or workload mobility, even though all of those ideas were underneath what he was saying. It was the light switch. Coz talked about walking into a room at home and turning on the light. You know exactly what is going to happen. It is simple. It is obvious. It works the way you expect it to work. Then he compared that to walking into a conference room at the office, where five people spend the first few minutes trying to figure out how to turn on the right lights, dim the screen area, wake up the display, connect the laptop, and make the audio work. Everyone has lived that moment. It is also a perfect way to explain what Everpure has been trying to do since the beginning. Make the complicated thing feel like the light switch. That may sound too simple for enterprise infrastructure, but I think it is exactly the point. The best infrastructure does not feel simple because the problem is simple. It feels simple because somebody did the hard engineering work to hide complexity without hiding control. That has always been part of the Everpure story. When Pure Storage first became known in the market, the message was not only flash performance. Performance mattered, of course. But the thing customers really felt was that the experience was different. The arrays were simpler. The upgrades were non-disruptive. The support model was different. Evergreen architecture was different. The idea that you could keep modernizing without the usual forklift pain was different. Over time, that simplicity moved from one array to more of the environment. Fusion extended the idea from a single system to a fleet. Policy, placement, automation, workload mobility, service levels, compliance, and lifecycle management started to move from device-by-device thinking toward something broader. Now, with the Enterprise Data Cloud, Everpure is trying to move that simplicity again. From array to fleet. From fleet to data. From data storage to data management. That was the thread both Nirav Sheth and Coz pulled through the keynote, and I think it connected day two back to day one in a very useful way. They made it clear that the move from Pure Storage to Everpure is not an abandonment of what got the company here. It is a continuation of the same journey. That matters because customers are rightfully skeptical when technology companies rebrand or expand their message. They wonder whether the company is moving away from the thing they trusted. They wonder whether the new story is strategy or just vocabulary. Coz addressed that directly. We are not abandoning storage infrastructure. We are going to keep building the best storage infrastructure we can. But we are also going higher, because to build better infrastructure, you have to understand more about the data above it. That is a founder’s version of the message. Less theater. More first principles. If you store data, you want to know what it is. You want to know how it will be accessed. You want to know how often. You want to know what it relates to. You want to know whether there are copies. You want to know whether those copies create risk. You want to know whether the rules are being followed. The problem, as Coz pointed out, is that nobody really knows the future. The infrastructure has to be built for agility. That word gets overused, but in this context it matters. Agility is the ability to change without breaking everything. It is the ability to move workloads non-disruptively. It is the ability to rebalance a fleet. It is the ability to modernize hardware without turning it into a migration event. It is the ability to adjust policies as risk changes. It is the ability to bring intelligence to data that already exists instead of forcing the business to start over. That is where the Enterprise Data Cloud story becomes more practical. And I personally think the Enterprise Data Cloud Success Blueprint was the clearest example of that. I liked this part because it moved the conversation away from “look at all these capabilities” and toward “here is why it matters to you” and “what outcomes are you trying to drive?” That is where a lot of technology conversations go wrong. We get excited about the architecture and forget that customers are not buying architecture for the sake of architecture. They are trying to solve business problems with limited people, limited time, limited budget, and increasing pressure from every direction. They are dealing with supply chain constraints. They are being asked to do more with the same team. They are trying to create VMware optionality without making a reckless move. They are modernizing applications while still running legacy workloads that cannot just disappear. They are dealing with cyber risk, ransomware, and minimum viable business recovery. They are being asked to support AI before the data foundation is ready. The blueprint framework organized those pressures into three simple categories: risk reduction, efficiency, and agility. That may seem obvious, but obvious is underrated. Risk reduction is not just a security feature. It is knowing whether your data is protected, whether your snapshot policies are aligned, whether you can recover the minimum viable business, whether sensitive data is duplicated everywhere, and whether compliance follows the data instead of living in someone’s spreadsheet. Efficiency is not just a density number. It is energy efficiency, automation, operational scale, fewer manual tasks, fewer migrations, and fewer people spending nights and weekends babysitting infrastructure that should be managing itself. Agility is not just modernization language. It is VMware optionality, container readiness, AI readiness, cloud flexibility, application mobility, and the freedom to make the next decision without being trapped by the last one. I think that is a much better way to have the conversation with customers. Not “Do you want this product?” But “Which business outcome are you trying to improve, and what is standing in the way?” The Red Hat and CSX discussion made that practical. When Eric Grabill from CSX talked about Positive Train Control, sensors along the tracks, safety requirements, and systems where a loss of data can affect train operations, the conversation moved from platform strategy into the real world. That is where infrastructure earns its keep. CSX has already moved a large portion of its applications to Kubernetes on OpenShift, but still has legacy VMs remaining. That is the real enterprise pattern. It is not containers or VMs. It is containers and VMs. It is cloud and on-premises. It is modern and legacy. It is AI coming next while everything else still has to run today. The Red Hat and Portworx conversation made the point that modernization cannot mean creating another disconnected stack. Customers need one operating model across VMs, containers, and eventually AI workloads. They need a practical transition path, not a big bang migration. They need data services that protect the applications, not just compute platforms that can host them. The St. Elizabeth Healthcare conversation made the same point in a more personal way. Charles Shepherd talked about joining St. Elizabeth in 1997, starting at the help desk, moving through Novell, GroupWise, backups, storage, and eventually becoming part of the team responsible for systems that support a healthcare environment that never really stops. What stayed with me was not only the technical story. It was the laptop on vacation. Anyone who has worked in infrastructure understands that detail. The laptop that comes with you just in case. The phone you keep checking because maybe something happened. The family event where part of your brain is still in the data center. The trip where you are physically present but operationally on standby. That is not a feature comparison. That is a life comparison. Charles said he recently was able to go to his niece’s graduation and not get called. That sounds small only if you have never been the person who always gets called. He also talked about more than one hundred hardware upgrades and more than one hundred fifty Purity upgrades without downtime. He talked about moving from older systems to modern ones without the traditional forklift migration pain. He talked about change boards becoming comfortable with upgrades during the day because the process had earned trust. That is the kind of customer proof that matters. It shows what the solution that was delivered gives back. It gives back time, trust and confidence. That connects directly to the light switch idea. Simplicity is not cosmetic. It is not just a better UI. It is not just fewer clicks. Simplicity changes what people can spend their time on. It changes what teams believe they can safely do. And it changes whether the infrastructure team is trapped maintaining the past or free to prepare for what comes next. Coz also said something important about time. This Enterprise Data Cloud journey is not a one-year story. It is not one product cycle. It is not done because it showed up in an Accelerate keynote. Coz described it as a journey that will take five to ten years, and even then, it will not really be done because the solution will keep improving. I appreciate that kind of honesty. So when a founder says this is a long journey, I believe that more than I believe a slide that says “seamless transformation” in large font. But I also think now is the right time for the journey to become possible. And Coz reminded us that the best version of this is not complexity with better branding. The best version is the light switch. Coz, in the most Coz way possible, reminded everyone that the goal is not to make enterprise infrastructure sound impressive. The goal is to make the hard things feel obvious. Like turning on the lights. I appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere111Views0likes0Comments"Where’s Waldo?", But for your Data
This past Saturday, my wife and I sat at my son’s college graduation ceremony doing what every proud parent does after running out of tears and tissues: staring at the giant screen, scanning a crowd of thousands, and playing a very emotional, very expensive version of Where’s Waldo? The camera pulled back and showed the graduating class. Thousands of caps. Thousands of gowns. Thousands of people who had just survived exams, group projects, late-night studying, bad cafeteria decisions, emotional phone calls home, and whatever personal version of “I’ll start the paper tomorrow” they subscribed to. Somewhere in that sea of mostly identical academic robes was my son. I knew he was there. We had dropped him off at college years earlier, paid tuition, bought supplies, endured move-in day, survived the separation anxiety, worried about him, cheered for him, and occasionally pretended to be calmer than we actually were. I knew exactly why we were in that room. But on that screen, in that moment, he was just one face among thousands. So I started searching for him. Every parent around me was probably doing some version of the same thing. We were not looking at a graduating class in the abstract. We were looking for our graduate. Everyone else on that screen mattered deeply to someone, but to us they were mostly context without identity: a massive, moving, emotional dataset with almost no metadata attached. That was the strange thing about the picture. It showed us everything and told us almost nothing. There were thousands of people on the screen, but unless you already knew who you were looking for, you did not really know what you were looking at. Somewhere between the pride, the camera angle, and my increasingly poor performance at parental facial recognition, my brain did what my brain unfortunately does. It connected a very human moment to the way enterprises think about data. Because this is exactly the problem most organizations have with their data. They know it is there. They know there is a lot of it. They know some of it is incredibly valuable, some of it is probably risky, and some of it is duplicated, outdated, forgotten, regulated, misplaced, or being accessed by people and systems nobody has thought about in years. But knowing there is a crowd is not the same thing as knowing who is in it. That is the part we do not talk about enough. For years, data management conversations were mostly about where the data lived, how it was protected, how fast it could be accessed, and how much it cost to keep it all running. Those things still matter. They will always matter. But they are no longer enough. The new question is not simply, “Where is the data?” The better question is, “What is this data, who does it belong to, why does it exist, who is using it, where has it moved, what risk does it carry, and should this AI model, business process, analyst, application, or employee be touching it at all?” That is a very different conversation, and that is why 1touch matters. Not because the industry needed one more product logo, one more acronym, or one more keynote phrase that sounds important until everyone quietly admits they are not exactly sure what it means. 1touch matters because it is aimed directly at the problem of not knowing. The lie of visibility Most organizations believe they have visibility into their data because they have tools that can show them infrastructure. They can show arrays, volumes, file systems, buckets, databases, dashboards, latency charts, replication status, backup jobs, snapshots, anomalies, alerts, and the occasional red icon that ruins someone’s morning. All of that is useful. None of it guarantees understanding. An IT team can tell you a volume is 87 percent full, but that does not mean they know it contains expired customer records, old HR exports, forgotten underwriting files, production data copied into a test environment, or a spreadsheet with 40,000 Social Security numbers created in 2018 by someone who left the company three reorganizations ago. A security team can tell you an alert fired, but that does not mean they know whether it represents real exposure, a false positive, or just another noisy event in a pile nobody has enough hours to investigate. A data team can point to a lake, a warehouse, a catalog, and a governance process, but that does not mean the data is clean, trusted, current, properly classified, or safe to feed into an AI workflow. This is the uncomfortable truth: enterprise data visibility has often meant visibility into containers, not contents. We could see the auditorium. We could count the very uncomfortable seats. But we still could not tell which graduate was my son. The graduation screen was not useless. It showed scale. It proved the event was real. It helped me understand the crowd. But until I could identify the person I cared about, the picture was incomplete. Enterprise data estates work the same way. The problem is not that organizations have no tools. They often have too many. The problem is that many tools see the surface of the environment but miss the identity, relationship, movement, and meaning of the data inside it. That gap was inconvenient in the old world. In the AI world, it is dangerous. AI does not forgive ignorance Before generative AI entered every boardroom conversation, the consequences of not knowing your data were already serious: compliance exposure, bloated infrastructure costs, security blind spots, slow audits, manual discovery, painful legal requests, cloud migration delays, and business users waiting weeks for access to information because nobody could confidently say what was safe to use. Then AI showed up and made the problem louder. AI feeds on data. Lots of it. Structured data, unstructured data, documents, emails, transcripts, PDFs, customer records, logs, knowledge bases, support case histories, SaaS exports, file shares, objects, and anything else that might help a model answer a question, summarize a situation, automate a workflow, or make a decision. That sounds exciting until you remember that most enterprises do not fully know what is in all of those places. And AI is not magic. If the input is wrong, the output inherits that problem. Sometimes the model hallucinates. Sometimes it exposes something it should not. Sometimes it makes a recommendation based on data that was never supposed to leave a specific jurisdiction. Sometimes it answers confidently from a document that was obsolete three policies ago. Sometimes it gives the right answer to the wrong person, which may be the scariest version of all because the technology can look like it is working while quietly violating the trust model of the business. That is why “AI-ready data” cannot simply mean “we pointed a model at a repository.” That is not readiness. That is hope with an API call. AI-ready data needs context. It needs classification, identity, policy, and confidence. It needs a way to distinguish between a harmless document, a restricted record, a regulated attribute, an exposed credential, and a data fragment that only becomes sensitive when connected to other fragments somewhere else. A number or a name by itself may not mean much. A location, transaction, or timestamp by itself may not mean much either. But connect the number to the name, the name to the patient record, the patient record to a geography, the geography to a regulation, the regulation to a storage location, and the storage location to an access path, and suddenly you are not looking at random data anymore. You are looking at risk. Or value. Often both. This is where 1touch becomes important, because its value is not just identifying patterns and sticking labels on files. Its value is in discovering, classifying, and contextualizing data across environments so organizations can understand not only what exists, but what it means. That distinction matters. The difference between labeling and knowing At graduation, every student had the same basic label: graduate. That label was accurate, but it was wildly insufficient. One graduate may be heading to medical school. Another may be joining a startup. Another may be the first person in their family to earn a degree. Another may have worked two jobs to get there. Another may have changed majors three times and somehow still finished on time, which frankly deserves its own medal. The label tells you the category. The context tells you the story. Data works the same way. A traditional tool might identify something that looks like a credit card number, Social Security number, email address, medical code, account number, or passport field. That is useful, but it can also create noise. Strings of digits appear everywhere. Test data looks real. Real data looks fake. A file name can lie. A folder path can be misleading. A database column called “ID” might be harmless, or it might be the key to everything. Context is what turns a guess into intelligence. 1touch approaches this problem by looking at the broader semantic environment around the data. It is not just asking, “Does this pattern match something sensitive?” It is asking, “What surrounds it? What system did it come from? Who accesses it? Where does it move? What other data is connected to it? What business process does it support? What regulatory meaning does it carry?” That matters because in the real world, data risk rarely lives in a single isolated field. It lives in relationships. The same way my son was not immediately identifiable to the room because he was wearing a cap and gown like everyone else, sensitive enterprise data is often not obvious because it is dressed like everything else. It sits in file shares, databases, cloud repositories, SaaS platforms, mainframes, archives, exports, and forgotten project folders. It blends into the crowd. The old approach was to scan the crowd every so often and hope you recognized enough faces. The newer requirement is continuous understanding: discovering data where it lives, watching how it moves, connecting fragments across systems, and building a living map of identity, access, classification, and risk. Not a once-a-year inventory. Not a spreadsheet. Not a governance theater exercise where everyone nods in a meeting and then goes back to copying production data into development because the test system “needed something realistic.” A living map. That is the real promise. Why this matters The value of 1touch can be easy to undersell if we describe it only as sensitive data discovery or Data Security Posture Management (DSPM). Those descriptions may be accurate, but they are not the business problem. A prospect is not waking up hoping to buy a classification engine. They are waking up with pressure from the board, auditors, regulators, cyber insurers, application owners, AI initiatives, cloud migration teams, and business leaders who want faster access to “clean” data without increasing risk. And for those of us who have been around this industry long enough to have a few emotional support scars, this problem is not new. We were talking about lifecycle data management and data classification projects 20 years ago. Kazeon, StoredIQ, and others were all trying to help customers understand what was hiding inside their unstructured data environments before the phrase “dark data” became a fashionable way to describe a very unfashionable mess. I personally used Kazeon back in 2006, before EMC acquired it and eventually killed it. The idea was right. The experience was painful. I remember a project where it took almost two months to scan the environment, process the results, and prepare the report. We finally sat down with the customer, proudly showed them the findings from roughly 5TB of unstructured data, and waited for the moment where they would appreciate all the classification goodness we had brought into their lives. Instead, the customer looked at us and asked the only question that mattered: “Where is the rest of my 55TB?” There are moments in a technical meeting when the room temperature changes without the thermostat being involved. This was one of them. Apparently the tool did not have permissions to scan the rest of the environment. So after two months of work, the result was technically accurate and practically incomplete, which is the most dangerous kind of confidence. We had a report. We had charts. We had findings. What we did not have was the whole truth. That is why this matters now. The enterprise data problem did not begin with AI. AI simply made the consequences of incomplete understanding much harder to ignore. Twenty years ago, a bad classification project meant a frustrated customer, an awkward meeting, and a lot of manual cleanup. Today, the same kind of blind spot can contaminate an AI pipeline, expose regulated data, break a sovereignty policy, delay a migration, or give executives a false sense of security. For existing customers, the value is even more strategic. They already trust the platform to store, protect, move, and serve their data. The next logical question is whether it can help them understand the data as well. That is the bridge 1touch helps build. That is important because customers are tired of stitching together disconnected tools where one product sees storage, another sees identity, another sees security events, another sees data catalogs, another sees cloud posture, and another sees compliance workflows. Everyone sees something, but nobody sees enough. Customers do not need more fragmented visibility. They need connected context. Most importantly, it helps us explain why the conversation has moved from where data sits to what the data actually means. Back to the screen Eventually, during the ceremony, I found my son. Definitely when his name was announced and he walked across that stage. But the moment stayed with me because it was such a simple reminder: seeing a crowd is not the same as knowing the people in it. Every person on that screen had a story, a history, a family somewhere in the stands trying to yell the loudest, and a future that was about to begin. From a distance, they looked identical. Up close, they were anything but. Enterprise data is like that too. From a dashboard, it can look like capacity, files, objects, tables, volumes, buckets, repositories, shares, records, and logs. But inside that data are customer identities, patient histories, citizens tax records, contracts, intellectual property, employee information, business secrets, stale copies, duplicate exports, forgotten archives, useful insights, hidden risks, and the raw material for the next generation of AI-driven business processes. The organizations that win will not be the ones that simply store the most data. They will be the ones that know what their data means. That is why 1touch matters. Because the future of data management is not just finding Waldo. It is understanding the entire crowd. Appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere86Views0likes0Comments