Maximum IOPS
Hello! Sorry if this a little confusing, I am still fairly new to the storage array system! I am curious as to if there is a way to see the maximum IOPS allowed on my array. Context: We routinely perform updates to databases on multiple servers across the array and due to our previous SAN's limitations we are currently limiting the number of databases we update simultaneously. Looking at the dashboard I can see that there doesn't seem to be any large spikes in the IOPS while performing said updates, but was curious if there was an easy way for me to compare the numbers I'm seeing to the maximum allowed to try and get a metric of how good/bad the performance is. Thanks in advance!Solved93Views1like5Comments
PHIF: Modular Hypervisor Integrations and a VMware Migration Path That Doesn't Depend on VDDK
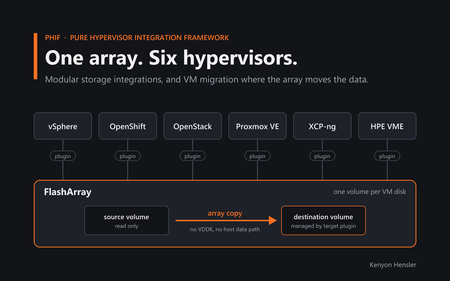
This post first ran on my personal blog, vSkeeBall. The code is on GitHub at PureStorage-OpenConnect/pure-hypervisor-integration-framework. For most of my career, virtualization meant VMware. Storage vendors built their integrations for vSphere, backup tools were built around VMware's APIs, and migration tools treated VMware as a source by reading its virtual disks and copying the blocks somewhere else. That's not the world most of the customers I talk to live in anymore. They're running vSphere next to OpenShift Virtualization, Proxmox VE, XCP-ng, HPE VM Essentials or OpenStack, and sometimes several of those at once. Some of the assumptions under the old tooling are changing too. In August 2026 Red Hat documented that VMware's Virtual Disk Development Kit (VDDK) images are no longer on the old public download, and you now have to request access from VMware/Broadcom. One workaround Red Hat called out was storage offload/XCOPY. Microsoft's Azure Migrate docs say the agentless VMware appliance needs VDDK too, and if you can't get it, you should use agent-based migration instead. I'd already been chewing on a question that this made a lot more relevant: what if moving a VM didn't depend on pulling its data out through the source hypervisor's disk SDK at all? That question ended up being one of the more interesting parts of PHIF, the Pure Hypervisor Integration Framework. PHIF started with a simpler goal. I wanted an easier way to hook a FlashArray up to a bunch of different virtualization platforms. Over time it turned into an experiment around three questions: Can the hypervisor storage integrations be modular and useful on their own, with no management framework at all? Can one capability-driven control plane automate those integrations without becoming something you're stuck with? Once the hypervisors share the same storage, can the array itself become the migration path? From what I've built so far, I think the answer to all three is yes. One thing up front: PHIF is a side project of mine, not a supported Everpure product. There's more on that at the end. Every hypervisor wants storage differently Going in, I figured this was mostly an API problem. The APIs turned out to be the easy part. The hard part is that every platform has its own idea of what storage looks like: VMware has VMFS, vVols, NFS and RDMs. OpenStack wants storage through Cinder. OpenShift and Kubernetes want CSI. Proxmox has its own storage plugin model. XCP-ng has Storage Repositories and SMAPI. HPE VM Essentials is built on Morpheus and KVM, with yet another plugin model. You could hide all of that behind one lowest-common-denominator layer, but you'd throw away most of what makes each platform worth running. So PHIF standardizes the orchestration and lets each platform keep its native integration model. PHIF can connect a FlashArray, deploy or configure the right integration for each platform, manage credentials, run day-2 operations and coordinate VM migrations, without pretending the platforms are the same underneath. Capabilities instead of if-statements Each hypervisor in PHIF is a connector, and the connector declares what that platform supports. The capability list right now looks like this: CONNECT, DEPLOY_PLUGIN, CONFIGURE, HOST_REGISTER, CONNECTIVITY, PROVISION_DATASTORE, PROVISION_VOLUME, SNAPSHOT, CLONE, RESIZE, QOS, REPLICATION, HEALTH, REMOVE, VM_INVENTORY, VM_LIFECYCLE, MIGRATE The front end doesn't carry a pile of "if it's vSphere, show these buttons" logic. It shows whatever each connector says it implements. Adding a hypervisor mostly means writing a new connector. The registry finds it on its own, and the shared services (FlashArray client, job engine, secrets and log streaming) are already there. This is one of my favorite screens in the app. All six platforms show up as peers, even though they look nothing alike under the hood. You don't need PHIF to use the plugins This is the part I care about most. PHIF can install the integrations, configure them, manage their lifecycle and use them in a migration, but several of them can be installed by hand and run without PHIF at all. I didn't want PHIF sitting between the hypervisor and the array. It sits above the integration instead: PHIF | deploy / configure / manage v Hypervisor | native plugin v FlashArray PHIF is an orchestration plane. It isn't in the VM's I/O path, and the storage integration keeps working if PHIF goes away. So if all you want is better FlashArray integration on Proxmox, XCP-ng or HPE VM Essentials, just grab that plugin. You don't have to run the web app or touch migration. Proxmox For Proxmox I wrote a custom purefa storage type as a real PVE::Storage::Plugin , so it runs inside Proxmox's own storage framework. The model is one FlashArray volume per VM disk. Instead of one big shared LUN with LVM on top and guest disks carved out of it, every guest disk gets its own volume: VM 101 |-- disk-0 -------- FlashArray volume A |-- disk-1 -------- FlashArray volume B VM 102 |-- disk-0 -------- FlashArray volume C Those volumes show up in the VM as raw multipathed block devices. Snapshots and clones happen on the array, and each disk keeps its own identity there. None of that needs PHIF. You can install the plugin, define the storage, set up multipathing and register the hosts yourself. PHIF just automates those steps. XCP-ng XCP-ng needed a completely different implementation, built on SMAPIv3: a volume plugin for the FlashArray-backed VDI lifecycle, a datapath that hands the raw multipathed device to the VM, and a host component for things like cleaning up multipath maps. Same idea as Proxmox, though: one VDI, one FlashArray volume, with snapshots and clones done on the array. I've validated it on a live two-host pool. PHIF can deploy it across a pool, or you can install it on the hosts yourself. HPE VM Essentials VME is Morpheus plus KVM, so this one is a native Morpheus/VME storage plugin. It registers FlashArray storage inside VME and lets VME drive the per-disk operations, with one volume per VM disk and snapshot, clone and resize offloaded to the array. I've validated it on a live VME appliance. PHIF can upload and configure it, or you can build and install it by hand. vSphere, OpenShift and OpenStack These three already had integrations: the FlashArray Cinder driver, Portworx CSI, and the vSphere plugin with VASA, VMFS and vVols. PHIF automates deploying and configuring them, and after that Cinder is still Cinder and CSI is still CSI. I don't want PHIF to fix one lock-in problem by adding a new mandatory dependency. How I think about the layers Layer 1 Native storage integration Layer 2 Deployment and configuration automation Layer 3 Lifecycle and day-2 operations Layer 4 Cross-hypervisor orchestration and migration Layer 1 is useful by itself, and you can stop there. Each layer above it is optional. Migration works because the storage model underneath is already there, but the plugins don't exist just to enable migration. Remove PHIF and they keep running. You lose the automation, not the storage integration. The management layer Nothing exotic here. It's a React SPA in front of a FastAPI backend, with an auto-discovered connector registry, a shared FlashArray REST client, an async job engine and encrypted credential storage. Operations run over HTTP APIs, SSH, Ansible or Kubernetes tooling. It runs under Docker Compose or Kubernetes/Helm. There's also a mock mode that stubs out the array and hypervisor I/O, so you can walk through every workflow without any real infrastructure. Day-2 operations PHIF exposes whatever each connector implements as day-2 operations: host registration, connectivity, provisioning, snapshots, clones, resize, QoS, replication, health checks and plugin lifecycle, depending on the platform. The UI is organized around six workflows: FlashArrays, API keys, hypervisors, operations, migrations, and jobs/log history. PHIF still stays out of the data path. The deployment wizard A lot of PHIF's value is just replacing a stack of per-platform install runbooks with one repeatable flow: discover the environment, find the nodes and interfaces, install the integration, set up storage networking, register the hosts, connect the FlashArray and validate. If you only run one environment, you probably don't need the wizard. That's the point of keeping the integrations modular. Then the storage layer became the migration layer I didn't set out to build migration. It came out of the storage design. Once several hypervisors keep each VM disk as its own FlashArray volume, a cross-hypervisor migration starts to look very different. The usual picture has the migration software acting as the data mover: Source hypervisor -> virtual disk -> migration software (read blocks, transfer blocks) -> destination storage -> destination hypervisor But if both platforms are attached to the same FlashArray, the source disk is already sitting on the hardware that's going to serve the destination. In a lot of cases there's no reason to copy it through a migration server. So PHIF captures the source VM's logical configuration, creates a matching VM and managed disks on the destination, and fills those destination volumes with a FlashArray copy-with-overwrite. The source volumes stay the source of the data, and the big block copy happens inside the array instead of going through the migration host. PHIF orchestration Source VM Destination VM | | v v Source FA volume --- array copy ---> Destination FA volume (inside FlashArray) PHIF coordinates. The array moves the data. Copy vs. move PHIF supports both. In copy mode, the source VM stays put while PHIF builds the destination and copies each source volume into a destination-managed volume. In move mode, the source is shut down first and only removed once the destination is created and running. If a migration fails, PHIF cleans up the half-built destination, and in copy mode the source is never touched. I've run boot-confirmed migrations in both directions across all the migration-capable platforms sharing one FlashArray. To be clear, this doesn't hand the same LUN from one hypervisor to another. The destination plugin creates its own volume and the array copies into it, so each platform keeps its own ownership and naming. Migration groups and scheduling Once single-VM migration worked, I added groups, with a shared source and destination, network mapping, scheduling and concurrency controls. That still sits above the plugins, and the plugins don't need it. Why VDDK matters here VDDK is how third-party tools have traditionally read VMware virtual disks. It works, but it puts VDDK squarely in your migration path: VMware VMDK -> VDDK -> migration software -> destination If your migration tool needs VDDK to read the source disk, its version compatibility, licensing and availability are all your problem. PHIF's VMware migration doesn't use VDDK. I didn't build it that way because of the August change. It's a side effect of leaning on the array and VMware's own host tooling instead. PHIF still uses the hypervisor APIs for the VM config, NICs and MACs, network mappings and creating the destination VM. It just doesn't pull the bulk data out through VDDK. RDMs are the easy case An RDM already has an identity as a storage device. PHIF resolves its device ID against the FlashArray, finds the volume, and that volume goes straight into the array-based workflow. VMFS takes more work A VMDK on VMFS is a file. The array holds the datastore, but there's no dedicated volume behind each individual VMDK, so PHIF has to change how the storage is represented. For a VMFS source, PHIF provisions a new FlashArray volume, presents it to ESXi as an RDM, and clones the VMDK onto it with vmkfstools . Where the VMware storage path supports it, that clone is VAAI/XCOPY offloaded to the array. Before: VM -> VMDK file -> VMFS -> FlashArray datastore volume Prep: VMDK file --(vmkfstools / VAAI-XCOPY)--> dedicated FA volume Migration: dedicated FA volume --(FlashArray copy)--> destination-managed FA volume -> destination VM No VDDK required. I also find it interesting that Red Hat independently pointed to storage offload/XCOPY as a way around its own VDDK dependency. vSphere as a destination vSphere can be the destination too. By default PHIF attaches the destination disks as virtual-mode RDMs backed by dedicated FlashArray volumes, which keeps the volume-per-disk model. If you'd rather end up with native VMFS VMDKs, there's an optional conversion. That step is different, because going from a raw device into a file on VMFS does need host-side data movement. PHIF runs it with VMware's storage operations and verifies the result before it frees the temporary volumes. That matters to me. An abstraction should make things simpler, but it shouldn't hide where the bytes are actually moving. Let the hardware do what it's good at Arrays already have snapshots, volume copies, clones, host mappings, replication and QoS. We think of those as storage features, but a lot of them work as mobility tools too. A volume copy can copy a VM disk, and a snapshot gives you a rollback point. So why push all the data through a migration appliance when the array that already owns it can do the copy? I think the VDDK situation points at a bigger issue. If leaving platform A requires a proprietary disk-access SDK from platform A, that SDK is part of your portability strategy whether you planned for it or not. PHIF splits the work. The hypervisor handles what it understands (inventory, CPU and memory, firmware, power state, networks and VM creation), and the array handles the volumes, copies, mappings and data. Who owns the VM? This project has also changed how I think about VM ownership. We usually draw the hypervisor on top, owning everything down to the array. I've started thinking of it as two halves: the compute platform owns the VM config and runs it, and the array owns the durable data that any of these hypervisors can consume. Real migrations still have plenty of complications (boot modes, drivers, disk formats, networking), but the data doesn't have to belong to one hypervisor. What PHIF is, and what it isn't PHIF is an independent, experimental project. It is not a supported Everpure product, and it isn't covered by a support agreement, warranty or SLA. That matters because it does real things to real infrastructure. It can create and destroy array volumes, change storage connectivity and multipathing, apply Kubernetes components, and create, power off or delete VMs. Try it in a lab, start in mock mode, and only point it at data you can afford to lose. The custom Proxmox, XCP-ng and HPE VM Essentials plugins are just as experimental. I put the code out so people can look at it, test it, change it and hopefully make it better. Where it stands today As of right now, PHIF has connectors for six environments: vSphere, OpenShift, OpenStack, Proxmox, XCP-ng and HPE VM Essentials. Each integration has been validated on hardware, and the migration engine has been tested on live hardware between the migration-capable platforms sharing the same FlashArray. That's enough to prove out the architecture. Next I'd like to add more hypervisors through the connector model and see whether array replication opens up cross-array mobility. And since it's modular, you can reuse the one piece you like without buying into the rest. Wrapping up For me, the interesting part of PHIF isn't the UI or the migration wizard. It's how the work is split underneath: the integrations are the foundation, PHIF handles orchestration, and the array is the data plane. When everything shares the same array, you can ask what the storage hardware can do for you. The VDDK changes made that more timely, but they aren't why I built it this way. They just show why those dependency boundaries matter. Sometimes a hypervisor migration really does mean moving a lot of data. But when the source and destination share capable storage, the migration server doesn't have to be the thing doing the moving. The source code, docs, deployment instructions, connector guides and the standalone plugins are all on GitHub: PureStorage-OpenConnect/pure-hypervisor-integration-framework. If you give it a try, I'd like to hear how it goes, so drop a comment here or open an issue on the repo. PHIF is an independent experimental project. It is not a supported Everpure product, is not covered by a support agreement, warranty or SLA, and can perform destructive infrastructure operations. Test it only in environments and against data you can afford to lose.24Views0likes0Comments
Your Last Line of Defense: Everpure + CrowdStrike: Active Defender in Action
October 20 | Register Now AI attacks breach in 29 minutes, driving ransomware toward $74B, while 90% of logs sit invisible in cold tiers*. See how Everpure and CrowdStrike Falcon® bring together visibility, intelligence, investigation, and automated response to turn storage into an active defender. Key takeaways: Extensive CrowdStrike and Everpure integrations: How Falcon NG-SIEM (visibility), Threat Graph (intelligence), Falcon LogScale (investigation), and Fusion SOAR (response) cover the full detect-to-remediate lifecycle. Closed-loop architecture: How telemetry, normalization, triage, and SOAR action combine so storage events become one continuous detection-to-response loop. Speed to containment: How Fusion SOAR turns a FlashArray™ or FlashBlade® detection into containment action within seconds, not hours. *(Source: 2026 CrowdStrike Global Threat Report) Register Now!154Views0likes0CommentsBeyond Awareness: Awareness Won't Save You, Recovery Will
October 15 | Register Now AI has compressed breakout times to minutes, exposing the gap between knowing you're at risk and recovering from it. Rick Orloff, CISO, and Chris Brandt, Consulting Field Solutions Architect, show why resilience, not awareness, decides survival, and how to build the active-defender architecture that closes the gap. We’ll cover: Worse than expected — how the AI threat has grown dramatically in 2026. Backup vs. cyber recovery, and why you need a tested "minimum viable business" plan. How storage becomes an active defender: built-in security, connected detection, dynamic recovery. A real Fortune 100 recovery story showing resilience in action when prevention fails. Register Now!73Views0likes0CommentsWaddle on, federal friends. 🐧
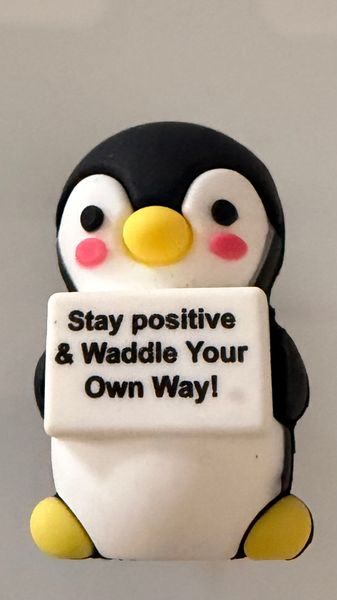
We know the rush of federal busy season is behind us, but the work doesn’t stop. My kids gave me this little toy from their school's "Friday Shop" and it made me smile. Hope this spreads some encouragement for the week ahead. How are our federal folks doing? Drop a comment below. 👇21Views0likes0CommentsEntra ID SAML2 SSO on FlashArray (Purity//FA 6.12.3), including fleets
Hi everyone, Here is a working setup for single sign-on from Microsoft Entra ID to a FlashArray, tested on Purity//FA 6.12.3, which is the newest version at the time of writing. It follows the Microsoft tutorial for Pure Storage SSO (https://learn.microsoft.com/en-us/entra/identity/saas-apps/pure-storage-sso-tutorial) and adds the fixes I needed to get the login test to pass. It also covers adding more arrays and fleets. Two things that break the login if you skip them The gallery app ships with role names that do not match the FlashArray role names. If you do not rename them, the login test fails because the array cannot find the role (Step 6). The claims must have no namespace URI (Step 5). What you need An array admin login Entra admin rights (Enterprise applications and App registrations) The Pure Storage SSO app from the Entra App Gallery A user or group to assign Overview Create a certificate on the array Configure SAML2 SSO on the array Entra app and the array certificate Load the Entra signing certificate on the array Claims (delete the namespace URI) Fix the app role names Assign, test and enable Plus: more arrays and fleets, and a troubleshooting list at the end. Step 1: Create a certificate on the array The array needs its own RSA certificate to sign SAML requests and decrypt assertions. Do not use the management certificate: it is EC 256 and caused a 500 error for me. purecert self-signed create saml-sp --common-name myarray.pure --days 365 purecert list The saml-sp row should show self-signed, rsa, 2048. Note the expiry date: SSO signing stops working when it expires. Step 2: Configure SAML2 SSO on the array Go to Settings › Access › Users and Policies › SAML2 SSO and edit the configuration. Array URL: the array FQDN, for example https://myarray.pure/. Signing Credential and Decryption Credential: type the certificate name saml-sp. Do not paste certificate text. Switch on Sign Request and Encrypt Assertion. IdP Entity ID, URL and IdP Metadata URL: copy them from the Entra app (Set up Pure Storage SSO section). Keep Enabled off for now and save. Without credentials, saving fails with "Must provide signing credential when signed request is enabled" and the same message for decryption. The GUI can silently keep management, so check the result in the CLI: puresso saml2 list puresso saml2 test Both credential columns must show saml-sp. If not, set them directly: puresso saml2 setattr Entra-ID --signing-credential saml-sp --decryption-credential saml-sp This can print "Certificate claim does not exist." even though the values were applied, so trust the list output. Step 3: Entra app and the array certificate In the Entra admin center go to Enterprise apps › New application, search Pure Storage SSO and add it. Open Single sign-on › SAML › Basic SAML Configuration. Set Identifier to the array's SP Entity ID and Reply URL to the array's Assertion Consumer URL. Both are shown in the array's SAML2 SSO dialog, so copy them from there. On the array, open the certificates page and download saml-sp. Rename the extension from .crt to .cer. In the Entra app go to Single sign-on › SAML Certificates › Verification certificates › Edit, tick Require verification certificates, and upload the .cer. Because Encrypt Assertion is on, also import the same .cer under Token encryption and activate it (see the token encryption guide under Links). Check that you exported the right certificate: openssl x509 -in saml-sp.cer -noout -subject -enddate The subject must show the common name you used in Step 1, not the GUI certificate. Step 4: Load the Entra signing certificate on the array The array needs Entra's signing certificate to validate the response. If this is empty the array test still shows OK, but a real login fails. In Entra open Single sign-on › SAML Certificates and download Certificate (Base64). Open the file, copy everything including the BEGIN CERTIFICATE and END CERTIFICATE lines. In the array's SAML2 SSO dialog click Edit next to Verification Certificate and paste it. CLI alternative: puresso saml2 setattr Entra-ID --verification-certificate Step 5: Claims (delete the namespace URI) In the Entra app go to Single sign-on › Attributes & Claims › Edit. Open each claim, clear the Namespace field completely, and make sure the names match exactly: dn: user.onpremisesdistinguishedname email: user.mail (or user.userprincipalname for UPN) family_name: user.surname given_name: user.givenname purity_roles: user.assignedroles (required for array level SSO) Step 6: Fix the app role names The Pure Storage SSO gallery app is set up incorrectly for its role names. It ships readonly_role, ops_admin_role, storage_admin_role and array_admin_role with an empty value. The names must match the FlashArray role names exactly, otherwise the login test fails because the array cannot find the role. The roles are edited in App registrations, not in the Enterprise application: Go to App registrations › All applications and search for the app name. Open App roles and click a role. In Display name, remove the _role suffix. In Value, enter the role name, for example array_admin. Click Apply and repeat for the other roles. array_admin_role → Display name: array_admin, Value: array_admin storage_admin_role → Display name: storage_admin, Value: storage_admin ops_admin_role → Display name: ops_admin, Value: ops_admin readonly_role → Display name: readonly, Value: readonly Leave msiam_access as it is. Step 7: Assign, test and enable In the Entra app go to Users and groups › Add user/group, pick the user, click Select a role and choose one of the renamed roles. Only one role per assignment. On the array open the SAML2 SSO dialog and click Test. All lines must be green and the first two must show saml-sp. Click E2E Test, sign in with the assigned user, then click Check E2E Test Result. If it passes, switch Enabled on and save. The login page now shows Click for Single Sign-On and a Local Access link. Tip: Keep a working local admin login in case something on the Entra side breaks or a certificate expires. More arrays and fleets Each array needs its own certificate, and that certificate must be uploaded to Entra under Verification certificates, next to the ones from the other arrays. You do not need a new Enterprise application per array. If you use Fusion / fleet manager, enable Trust Other SAML Service Providers In Fleet in the SAML2 SSO configuration and apply these settings on each additional array: Create the certificate on that array (Step 1) with its own common name. Use the same SSO configuration name as on the first array. Array URL: the FQDN of the new array. SP Entity ID: set it to Manual and paste the SP Entity ID of the first array. All fleet members must use the same SP Entity ID. Signing Credential and Decryption Credential: saml-sp, the certificate of this array. Switch on Sign Request and Encrypt Assertion. Identity Provider fields and Verification Certificate: the same values you used on the first array. In the Entra app, add a second Reply URL with the Assertion Consumer URL of the new array, and upload the new array's saml-sp .cer under Verification certificates. Run Test and E2E Test before enabling. After that you can sign in on the other arrays with the same Entra users, roles and claims. Note: If you use Encrypt Assertion on several arrays, check this: Entra token encryption uses one active certificate per application, so test each array with the E2E test. Troubleshooting Save fails: must provide signing or decryption credential: Create saml-sp and enter its name in both fields Red error echoes a long MIID... string: You pasted certificate text. Type the certificate name instead Test shows management as credential: Run puresso saml2 setattr as in Step 2 500 Internal Server Error when starting login: The credential was the EC management certificate. Switch to the RSA saml-sp certificate Login test fails, role not found: Rename role display name and value in App registrations (Step 6) Login fails or user has no role: Clear the claim namespaces and check purity_roles = user.assignedroles (Step 5) Verification certificate shows - in the test: Paste the Entra Base64 certificate (Step 4) If you do not need signed requests or encrypted assertions, you can switch off Sign Request and Encrypt Assertion and skip the certificate steps. Links Configure Pure Storage SSO for Single sign-on with Microsoft Entra ID (https://learn.microsoft.com/en-us/entra/identity/saas-apps/pure-storage-sso-tutorial) Configure Microsoft Entra SAML token encryption (https://learn.microsoft.com/en-us/entra/identity/enterprise-apps/howto-saml-token-encryption) Manage certificates for federated single sign-on (https://learn.microsoft.com/en-us/entra/identity/enterprise-apps/tutorial-manage-certificates-for-federated-single-sign-on) App roles UI (https://learn.microsoft.com/en-us/entra/identity-platform/howto-add-app-roles-in-apps#app-roles-ui) Hope this saves someone some time. Questions and corrections are welcome.81Views4likes0CommentsOne Year of “Ask Us Everything”: John “Coz” Colgrove on Everpure’s Past, Present, and Future
A special Ask Us Everything anniversary conversation with Everpure cofounder John “Coz” Colgrove explores Everpure’s origins, technical innovations, AI, and the future of data management.48Views0likes0CommentsOracle Resiliency: Choosing the Right Data Protection Approach for Every Failure
October 1 | Register Now Oracle recovery requires more than a backup strategy. Accidental deletion, logical corruption, infrastructure failure, site loss, and ransomware demand different combinations of backup, snapshots, and replication. This session explains where each data protection layer does and doesn’t belong in an Oracle recovery architecture. Through practical failure scenarios, we’ll examine how to align RPO, RTO, retention, availability, and recovery-location requirements with the right recovery mechanism. You’ll also learn how to identify overlap, avoid common recovery gaps, and use storage automation to apply consistent protection policies across production, development, test, and DR environments. Session takeaways: Map Oracle failure scenarios to the appropriate data recovery mechanism. Identify protection overlap, operational complexity, and recovery gaps before an incident exposes them. Translate workload requirements into practical RPO, RTO, retention, availability, and recovery-location decisions. Register Now!60Views0likes0CommentsThe Idea That Was Supposed to Fail
Why DirectFlash and Evergreen//One suddenly look a lot smarter in a world of NAND and DRAM price shocks Dmitry Gorbatov Mar 20, 2026 Important Note for my readers: Writing this piece took me a lot longer than I normally spend on a post. It took a lot of reading and research. Many articles and blogs were written on the subject before NAND and DRAM costs went crazy. The dry-humor version is that the storage industry spent years insisting flash was just disk with better manners, and then acted surprised when the underlying physics eventually asked to speak with management. Now, let’s get to it. I can still picture the room. It wasn’t anything special — just another corporate competitive training session, the kind you’ve sat through many times if you’ve spent enough years in enterprise tech. This was at NetApp, in 2015 or 2016, back when flash was still a question mark. Not if, but how. The industry had not fully committed yet, and everyone was trying to figure out what role it would play. The presenter clicked to the next slide, paused for a second, and said something that stuck with me in a way most of those sessions never do: “Pure Storage is crazy! They’re building their own flash modules. That’s stupid. It’s not sustainable. They won’t survive.” It wasn’t said for effect. There was no dramatic pause afterward, no attempt to persuade. It was delivered as a simple, almost obvious conclusion. And to be fair, it felt obvious. Because the entire storage industry operated on a shared assumption: you didn’t build components, you assembled them. You relied on a mature ecosystem of suppliers who specialized in drives, storage controllers, and memory, and you focused your differentiation on software features and integration. That was the efficient path. That was the scalable path. That was how serious companies behaved. What Pure was proposing at the time — what would later become Everpure — felt like a deviation from that logic. Building your own flash modules didn’t just introduce complexity; it seemed to reject the economic advantages of the broader supply chain. It looked like a risk without a clear payoff. So the conclusion made sense. Until it didn’t. Looking Back, Differently If I think back to that training session now, I do not really see it as a moment where someone was foolish. I see it as a moment where the industry was trapped inside the logic of its own assumptions. If you believe flash should look like disk, then building your own flash modules sounds silly. If you believe storage is just a sequence of refresh cycles, then a model built around non-disruptive evolution sounds unnecessary. If you believe component pricing will keep trending in the right direction forever, then architectural efficiency feels like an academic luxury. But once those assumptions start to crack, the logic changes. And when it changes, the things that once looked eccentric start to look oddly prescient. A Change You Don’t Notice Right Away For years, nothing about that statement felt particularly worth revisiting. The industry moved forward in predictable ways. Flash became mainstream. Performance improved. Density increased. Vendors competed on features, benchmarks, and price points. The conversations most of us had with customers followed familiar patterns. If anything, the abstraction layers built around flash made things easier to consume. SSDs behaved like faster disks — and that was good enough. There is a reason they showed up in familiar HDD form factors. The industry was trying to preserve the old world while sneaking in a new medium. Keep the slots. Keep the enclosures. Keep the assumptions. Change as little as possible. That made adoption easier, but it also buried the problem. Because flash is not a disk. It never was. It does not behave like one, and it does not particularly enjoy being treated like one. The only reason the illusion worked is because the industry built a fairly elaborate translation layer to maintain it. That translation layer is where the story really starts. The Trick That Made Flash Look Simple When commodity SSDs became the standard way to bring flash into enterprise storage, they depended on a piece of internal firmware called the Flash Translation Layer, or FTL. Its job was deceptively simple: make raw NAND look like a disk. That sounds harmless enough until you think about what that actually requires. NAND cannot just overwrite data in place the way the rest of the stack would like it to. It has to handle erase cycles, wear leveling, garbage collection, bad block management, and the constant translation between logical addresses and physical locations on the media. So every SSD became its own little self-contained world, complete with its own controller, its own metadata tables, and its own DRAM to keep track of everything. In other words, every drive became a tiny independent computer, making local decisions in isolation. That design solved the adoption problem. It did not solve the architecture problem. For a while, the tradeoff seemed worth it. The drives were fast enough, the packaging was familiar, and the whole system kept pretending that flash was just a much nicer version of disk. But what looked neat and modular at small scale turned out to be awkward and expensive at enterprise scale. And that is where the “stupid” decision begins to look a lot smarter. What Commodity SSDs Actually Drag Along With Them The more I researched this topic (and believe me I did), the more I realized how much of the industry got comfortable with an abstraction that was doing a lot of quiet damage. Commodity SSDs carry four structural inefficiencies that matter much more today than they did when pricing was stable. Trapped DRAM. Every SSD maintains its own mapping tables, so large-scale systems end up carrying a remarkable amount of DRAM inside the drives themselves. That memory is necessary for the SSD to function, but it does not really help the array think globally. It is duplicated overhead, repeated again and again, drive by drive. In a petabyte-scale system, that is not a rounding error. It is cost, power, and complexity hiding in plain sight. Unpredictable Latency. Garbage collection inside a traditional SSD happens when the drive decides it needs to happen. When that occurs, the drive may become temporarily less responsive, and in an array full of independent drives, those little stalls start to show up as tail-latency spikes. The system is always vulnerable to one drive having a private crisis at exactly the wrong time. Write Amplification. Because the SSD does not really understand the workload or the data structures above it, it moves data more often than necessary. More movement means more writes. More writes mean more wear. More wear means the media gets consumed faster than it should. Over-provisioning. Every SSD holds back some raw capacity for its own housekeeping and spare-cell management, but that reserved space is siloed. The array cannot use it intelligently across the system because each drive is managing its own private affairs. None of this sounded especially dramatic when NAND kept getting cheaper and the economics of flash kept improving. It sounded like engineering trivia. The sort of thing infrastructure people argue about while everyone else waits for the quote. Today it is not trivia. Today it is exposure. Why AI Made This Suddenly Everyone’s Problem For years, one of the quiet assumptions in enterprise IT was that storage capacity would continue to become cheaper and more abundant over time. Not perfectly, not smoothly, but predictably enough that the inefficiencies of the underlying architecture could be tolerated. That assumption is now not only under pressure, it is getting decimated. AI did not just create a new category of interesting workloads. It created a global appetite for silicon that is large enough to bend supply curves. The cute part of AI is easy to mock. The cat kicking the T-Rex. The surreal generated videos. The deepfakes that make you look twice and then sigh a little for civilization. But behind every one of those outputs is a less funny reality: extraordinary consumption of DRAM, NAND, GPUs, and supporting infrastructure. The novelty at the edge is powered by very serious resource demand at the core. And that demand is landing directly on the components enterprise storage depends on. This is the part customers are beginning to feel in ways that are no longer abstract. Expansion quotes do not look as comfortable as they once did. Refresh cycles feel more expensive. Delivery windows stretch. Budgets built on assumptions from even two years ago suddenly need more explaining than anyone wanted. There is a tendency to call this inflation because that is the easiest word available. It is not really inflation. It is supply and demand, with a side of semiconductor reality. And that matters, because a traditional SSD array is exposed to both sides of the problem at once. It is exposed to NAND because that is the medium you are buying, and it is exposed to DRAM because every SSD drags its own DRAM overhead along for the ride. When those two markets tighten at the same time, the cost of the architecture gets hit twice. That is not just a technical nuance. That is economics. Revisiting the “Stupid” Decision This is where the old training-room comment starts to age badly. Because what looked like unnecessary vertical integration was really a decision to stop pretending flash was a disk and start treating it like what it actually is: semiconductor media with very specific physical behaviors that should be managed at the system level, not hidden inside dozens of drives. That is the DirectFlash idea in plain English. Take the Flash Translation Layer out of the individual drive. Pull media management into the operating environment. Let Purity manage flash globally instead of leaving each device to improvise its own local strategy. That changes more than performance charts. It means metadata no longer has to be duplicated and trapped inside every SSD. It means wear leveling can happen across the full system instead of inside the borders of a single device. It means bad block handling, garbage collection, and data placement can be coordinated with global context. It means the platform can see the difference between data that should live together and data that should not, which dramatically reduces unnecessary movement and lowers write amplification. And when write amplification drops, the economics change. The NAND lasts longer. The useful life of the media extends. Lower-endurance flash, like QLC, becomes viable for serious enterprise use because the software is smart enough not to abuse it. The system extracts more useful work from the same raw silicon. That is not just clever engineering. That is insulation from volatility. The reason this matters now is that DirectFlash changes the ratio between the silicon you buy and the value you get from it. If the rest of the market is paying more for NAND and more for DRAM, an architecture that reduces trapped DRAM, minimizes wasted writes, extends media life, and packs far more capacity into far denser modules is not just elegant. It is economically defensive. This is where the old “they build their own flash” criticism misses the point. Building your own flash modules was never the point by itself. The point was controlling the relationship between software and media well enough to eliminate the inefficiencies the commodity model had normalized. Why Purity Is the Real Story DirectFlash makes for a good visual. It is a module. You can point to it. You can talk about density and reliability and the fact that a 150TB module can do work that would have required a small army of traditional devices not all that long ago. But the real story is Purity Operating Environment, i.e. software. Purity is where the architectural bet pays off. It is what turns raw NAND into a coordinated system instead of a pile of politely disagreeing SSDs. Because Purity sees the entire media pool, it can write more intelligently. It can group data with similar expected lifespans together, so that when a snapshot or a temporary workload disappears, whole regions of storage can be retired cleanly instead of forcing background reshuffling of still-live data. That reduces unnecessary churn. Less churn means fewer writes. Fewer writes mean longer media life. Because Purity sees when a NAND die is busy with an erase or program cycle, it can avoid letting that become a host-visible performance problem. RAID-3D and system-level awareness allow the platform to reconstruct data from parity rather than simply waiting for a busy drive to get its act together. The end result is deterministic performance rather than a roulette wheel of occasional latency spikes. Because Purity owns media management globally, the over-provisioning and spare resources are no longer trapped in per-drive silos. The system can use them strategically. I know that all of this sounds a bit scientific, and to be fair, it is. I did spend over 7 years working for Everpure and a few weeks researching for this post. I wanted to sit with that science for a bit. Where the Economics Start to Matter The moment component pricing becomes unpredictable, architecture stops being an engineering preference and starts becoming a financial strategy. That is the part that matters most to customers right now. A traditional buying model assumes that at some point you will hit a refresh cycle, a capacity wall, or a migration event that forces a purchase whether the market timing is good or terrible. You buy when you have to buy. If NAND is expensive, that is unfortunate. If DRAM is expensive too, even better, because apparently the universe enjoys symmetry. That is what makes the combination of DirectFlash and Evergreen so important. DirectFlash reduces the amount of waste, duplication, and premature wear in the system. Evergreen removes the old habit of tying innovation to forklift replacement. Controllers evolve. Capacity can be consolidated into denser modules over time. Data stays in place. The customer is not forced into rebuying the whole environment every few years just to remain current. That already changes the economics. But it still leaves one more question: who is carrying the price risk? And this is where Evergreen//One matters more than ever. The Part I Actually Wanted to Get To Evergreen//One is not just a consumption model. It is not just a nicer way to finance storage. It is a mechanism for moving volatility away from the customer. That is the conclusion I wanted to earn, not just declare. When NAND and DRAM prices start climbing, most traditional models push that turbulence straight into the customer’s planning cycle. The customer eats the increase, absorbs the uncertainty, and tries to explain to the business why the infrastructure line now behaves like it has a gambling problem. Evergreen//One changes that relationship. The customer consumes capacity as a service. Everpure owns the burden of the underlying hardware lifecycle, the media strategy, and the ongoing optimization. DirectFlash makes that model stronger because the platform is structurally more efficient with the silicon it uses. It needs less trapped DRAM, wastes fewer writes, extends media life, and supports denser modules that deliver more usable capacity per unit of power, space, and raw media. Purity compounds that advantage with data reduction, ongoing software improvements, and smarter system-wide media management. Put differently, Everpure is in a much better position to absorb and manage component volatility than a customer buying boxes on a refresh schedule. That is the real price protection story. Not some magical promise that economics no longer apply. They do. NAND still costs what NAND costs. DRAM still costs what DRAM costs. Physics remains annoyingly undefeated. The difference is who is exposed to that volatility, how much inefficiency is built into the system before the customer ever sees it, and whether the operating model gives the customer a stable runway instead of a quarterly surprise. DirectFlash reduces the waste. Evergreen removes the forced disruption. Evergreen//One shifts the risk. That combination is a lot more interesting than it sounded in that room 11 years ago. The Part I Didn’t Appreciate Then What I did not understand sitting in that room 11 years ago was that some decisions are made for futures that have not arrived yet. The market eventually caught up to the architecture. That does not happen often enough in enterprise tech to ignore when it does. DirectFlash was never interesting just because it was different. It was interesting because it removed layers of inherited inefficiency that the rest of the market had accepted as normal. And in a period where NAND and DRAM pricing are under pressure, removing inefficiency is no longer just a performance story. It is a protection story. That is why this matters now. Not because it makes for a clever slide. Because it gives customers a more predictable way forward when the underlying component markets are anything but predictable. And in the current environment, that might be the most practical definition of innovation there is. Appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere856Views3likes2CommentsFrom CSI to Snapshots: Seamless VM Management on Red Hat OpenShift
September 22 | Register Now Red Hat OpenShift Virtualization is an increasingly popular option for organizations migrating workloads to a new hypervisor. Rather than being an afterthought, storage is actually a critical element of any OpenShift Virtualization deployment. Join this webinar for a set of short demos of Everpure FlashArray™ with Red Hat OpenShift. We'll go from the ground up: connecting the Container Storage Interface (CSI) to storage, spinning up a virtual machine (VM) from a template, and protecting the VM with instant, array-based snapshots. These demos will show how naturally FlashArray fits into an OpenShift environment. Get connected: See how to set up the CSI with the Portworx® operator and define both the StorageCluster and the StorageClass. Run and protect: We’ll demonstrate both VM provisioning in OpenShift Virtualization plus how to create instant, space-efficient snapshots. Register Now!406Views0likes0Comments