PHIF: Modular Hypervisor Integrations and a VMware Migration Path That Doesn't Depend on VDDK
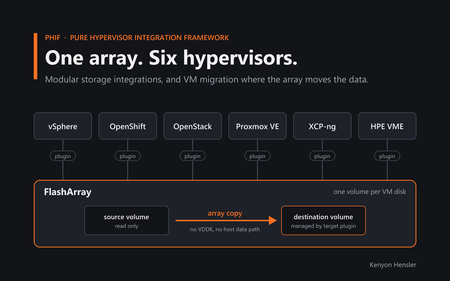
This post first ran on my personal blog, vSkeeBall. The code is on GitHub at PureStorage-OpenConnect/pure-hypervisor-integration-framework. For most of my career, virtualization meant VMware. Storage vendors built their integrations for vSphere, backup tools were built around VMware's APIs, and migration tools treated VMware as a source by reading its virtual disks and copying the blocks somewhere else. That's not the world most of the customers I talk to live in anymore. They're running vSphere next to OpenShift Virtualization, Proxmox VE, XCP-ng, HPE VM Essentials or OpenStack, and sometimes several of those at once. Some of the assumptions under the old tooling are changing too. In August 2026 Red Hat documented that VMware's Virtual Disk Development Kit (VDDK) images are no longer on the old public download, and you now have to request access from VMware/Broadcom. One workaround Red Hat called out was storage offload/XCOPY. Microsoft's Azure Migrate docs say the agentless VMware appliance needs VDDK too, and if you can't get it, you should use agent-based migration instead. I'd already been chewing on a question that this made a lot more relevant: what if moving a VM didn't depend on pulling its data out through the source hypervisor's disk SDK at all? That question ended up being one of the more interesting parts of PHIF, the Pure Hypervisor Integration Framework. PHIF started with a simpler goal. I wanted an easier way to hook a FlashArray up to a bunch of different virtualization platforms. Over time it turned into an experiment around three questions: Can the hypervisor storage integrations be modular and useful on their own, with no management framework at all? Can one capability-driven control plane automate those integrations without becoming something you're stuck with? Once the hypervisors share the same storage, can the array itself become the migration path? From what I've built so far, I think the answer to all three is yes. One thing up front: PHIF is a side project of mine, not a supported Everpure product. There's more on that at the end. Every hypervisor wants storage differently Going in, I figured this was mostly an API problem. The APIs turned out to be the easy part. The hard part is that every platform has its own idea of what storage looks like: VMware has VMFS, vVols, NFS and RDMs. OpenStack wants storage through Cinder. OpenShift and Kubernetes want CSI. Proxmox has its own storage plugin model. XCP-ng has Storage Repositories and SMAPI. HPE VM Essentials is built on Morpheus and KVM, with yet another plugin model. You could hide all of that behind one lowest-common-denominator layer, but you'd throw away most of what makes each platform worth running. So PHIF standardizes the orchestration and lets each platform keep its native integration model. PHIF can connect a FlashArray, deploy or configure the right integration for each platform, manage credentials, run day-2 operations and coordinate VM migrations, without pretending the platforms are the same underneath. Capabilities instead of if-statements Each hypervisor in PHIF is a connector, and the connector declares what that platform supports. The capability list right now looks like this: CONNECT, DEPLOY_PLUGIN, CONFIGURE, HOST_REGISTER, CONNECTIVITY, PROVISION_DATASTORE, PROVISION_VOLUME, SNAPSHOT, CLONE, RESIZE, QOS, REPLICATION, HEALTH, REMOVE, VM_INVENTORY, VM_LIFECYCLE, MIGRATE The front end doesn't carry a pile of "if it's vSphere, show these buttons" logic. It shows whatever each connector says it implements. Adding a hypervisor mostly means writing a new connector. The registry finds it on its own, and the shared services (FlashArray client, job engine, secrets and log streaming) are already there. This is one of my favorite screens in the app. All six platforms show up as peers, even though they look nothing alike under the hood. You don't need PHIF to use the plugins This is the part I care about most. PHIF can install the integrations, configure them, manage their lifecycle and use them in a migration, but several of them can be installed by hand and run without PHIF at all. I didn't want PHIF sitting between the hypervisor and the array. It sits above the integration instead: PHIF | deploy / configure / manage v Hypervisor | native plugin v FlashArray PHIF is an orchestration plane. It isn't in the VM's I/O path, and the storage integration keeps working if PHIF goes away. So if all you want is better FlashArray integration on Proxmox, XCP-ng or HPE VM Essentials, just grab that plugin. You don't have to run the web app or touch migration. Proxmox For Proxmox I wrote a custom purefa storage type as a real PVE::Storage::Plugin , so it runs inside Proxmox's own storage framework. The model is one FlashArray volume per VM disk. Instead of one big shared LUN with LVM on top and guest disks carved out of it, every guest disk gets its own volume: VM 101 |-- disk-0 -------- FlashArray volume A |-- disk-1 -------- FlashArray volume B VM 102 |-- disk-0 -------- FlashArray volume C Those volumes show up in the VM as raw multipathed block devices. Snapshots and clones happen on the array, and each disk keeps its own identity there. None of that needs PHIF. You can install the plugin, define the storage, set up multipathing and register the hosts yourself. PHIF just automates those steps. XCP-ng XCP-ng needed a completely different implementation, built on SMAPIv3: a volume plugin for the FlashArray-backed VDI lifecycle, a datapath that hands the raw multipathed device to the VM, and a host component for things like cleaning up multipath maps. Same idea as Proxmox, though: one VDI, one FlashArray volume, with snapshots and clones done on the array. I've validated it on a live two-host pool. PHIF can deploy it across a pool, or you can install it on the hosts yourself. HPE VM Essentials VME is Morpheus plus KVM, so this one is a native Morpheus/VME storage plugin. It registers FlashArray storage inside VME and lets VME drive the per-disk operations, with one volume per VM disk and snapshot, clone and resize offloaded to the array. I've validated it on a live VME appliance. PHIF can upload and configure it, or you can build and install it by hand. vSphere, OpenShift and OpenStack These three already had integrations: the FlashArray Cinder driver, Portworx CSI, and the vSphere plugin with VASA, VMFS and vVols. PHIF automates deploying and configuring them, and after that Cinder is still Cinder and CSI is still CSI. I don't want PHIF to fix one lock-in problem by adding a new mandatory dependency. How I think about the layers Layer 1 Native storage integration Layer 2 Deployment and configuration automation Layer 3 Lifecycle and day-2 operations Layer 4 Cross-hypervisor orchestration and migration Layer 1 is useful by itself, and you can stop there. Each layer above it is optional. Migration works because the storage model underneath is already there, but the plugins don't exist just to enable migration. Remove PHIF and they keep running. You lose the automation, not the storage integration. The management layer Nothing exotic here. It's a React SPA in front of a FastAPI backend, with an auto-discovered connector registry, a shared FlashArray REST client, an async job engine and encrypted credential storage. Operations run over HTTP APIs, SSH, Ansible or Kubernetes tooling. It runs under Docker Compose or Kubernetes/Helm. There's also a mock mode that stubs out the array and hypervisor I/O, so you can walk through every workflow without any real infrastructure. Day-2 operations PHIF exposes whatever each connector implements as day-2 operations: host registration, connectivity, provisioning, snapshots, clones, resize, QoS, replication, health checks and plugin lifecycle, depending on the platform. The UI is organized around six workflows: FlashArrays, API keys, hypervisors, operations, migrations, and jobs/log history. PHIF still stays out of the data path. The deployment wizard A lot of PHIF's value is just replacing a stack of per-platform install runbooks with one repeatable flow: discover the environment, find the nodes and interfaces, install the integration, set up storage networking, register the hosts, connect the FlashArray and validate. If you only run one environment, you probably don't need the wizard. That's the point of keeping the integrations modular. Then the storage layer became the migration layer I didn't set out to build migration. It came out of the storage design. Once several hypervisors keep each VM disk as its own FlashArray volume, a cross-hypervisor migration starts to look very different. The usual picture has the migration software acting as the data mover: Source hypervisor -> virtual disk -> migration software (read blocks, transfer blocks) -> destination storage -> destination hypervisor But if both platforms are attached to the same FlashArray, the source disk is already sitting on the hardware that's going to serve the destination. In a lot of cases there's no reason to copy it through a migration server. So PHIF captures the source VM's logical configuration, creates a matching VM and managed disks on the destination, and fills those destination volumes with a FlashArray copy-with-overwrite. The source volumes stay the source of the data, and the big block copy happens inside the array instead of going through the migration host. PHIF orchestration Source VM Destination VM | | v v Source FA volume --- array copy ---> Destination FA volume (inside FlashArray) PHIF coordinates. The array moves the data. Copy vs. move PHIF supports both. In copy mode, the source VM stays put while PHIF builds the destination and copies each source volume into a destination-managed volume. In move mode, the source is shut down first and only removed once the destination is created and running. If a migration fails, PHIF cleans up the half-built destination, and in copy mode the source is never touched. I've run boot-confirmed migrations in both directions across all the migration-capable platforms sharing one FlashArray. To be clear, this doesn't hand the same LUN from one hypervisor to another. The destination plugin creates its own volume and the array copies into it, so each platform keeps its own ownership and naming. Migration groups and scheduling Once single-VM migration worked, I added groups, with a shared source and destination, network mapping, scheduling and concurrency controls. That still sits above the plugins, and the plugins don't need it. Why VDDK matters here VDDK is how third-party tools have traditionally read VMware virtual disks. It works, but it puts VDDK squarely in your migration path: VMware VMDK -> VDDK -> migration software -> destination If your migration tool needs VDDK to read the source disk, its version compatibility, licensing and availability are all your problem. PHIF's VMware migration doesn't use VDDK. I didn't build it that way because of the August change. It's a side effect of leaning on the array and VMware's own host tooling instead. PHIF still uses the hypervisor APIs for the VM config, NICs and MACs, network mappings and creating the destination VM. It just doesn't pull the bulk data out through VDDK. RDMs are the easy case An RDM already has an identity as a storage device. PHIF resolves its device ID against the FlashArray, finds the volume, and that volume goes straight into the array-based workflow. VMFS takes more work A VMDK on VMFS is a file. The array holds the datastore, but there's no dedicated volume behind each individual VMDK, so PHIF has to change how the storage is represented. For a VMFS source, PHIF provisions a new FlashArray volume, presents it to ESXi as an RDM, and clones the VMDK onto it with vmkfstools . Where the VMware storage path supports it, that clone is VAAI/XCOPY offloaded to the array. Before: VM -> VMDK file -> VMFS -> FlashArray datastore volume Prep: VMDK file --(vmkfstools / VAAI-XCOPY)--> dedicated FA volume Migration: dedicated FA volume --(FlashArray copy)--> destination-managed FA volume -> destination VM No VDDK required. I also find it interesting that Red Hat independently pointed to storage offload/XCOPY as a way around its own VDDK dependency. vSphere as a destination vSphere can be the destination too. By default PHIF attaches the destination disks as virtual-mode RDMs backed by dedicated FlashArray volumes, which keeps the volume-per-disk model. If you'd rather end up with native VMFS VMDKs, there's an optional conversion. That step is different, because going from a raw device into a file on VMFS does need host-side data movement. PHIF runs it with VMware's storage operations and verifies the result before it frees the temporary volumes. That matters to me. An abstraction should make things simpler, but it shouldn't hide where the bytes are actually moving. Let the hardware do what it's good at Arrays already have snapshots, volume copies, clones, host mappings, replication and QoS. We think of those as storage features, but a lot of them work as mobility tools too. A volume copy can copy a VM disk, and a snapshot gives you a rollback point. So why push all the data through a migration appliance when the array that already owns it can do the copy? I think the VDDK situation points at a bigger issue. If leaving platform A requires a proprietary disk-access SDK from platform A, that SDK is part of your portability strategy whether you planned for it or not. PHIF splits the work. The hypervisor handles what it understands (inventory, CPU and memory, firmware, power state, networks and VM creation), and the array handles the volumes, copies, mappings and data. Who owns the VM? This project has also changed how I think about VM ownership. We usually draw the hypervisor on top, owning everything down to the array. I've started thinking of it as two halves: the compute platform owns the VM config and runs it, and the array owns the durable data that any of these hypervisors can consume. Real migrations still have plenty of complications (boot modes, drivers, disk formats, networking), but the data doesn't have to belong to one hypervisor. What PHIF is, and what it isn't PHIF is an independent, experimental project. It is not a supported Everpure product, and it isn't covered by a support agreement, warranty or SLA. That matters because it does real things to real infrastructure. It can create and destroy array volumes, change storage connectivity and multipathing, apply Kubernetes components, and create, power off or delete VMs. Try it in a lab, start in mock mode, and only point it at data you can afford to lose. The custom Proxmox, XCP-ng and HPE VM Essentials plugins are just as experimental. I put the code out so people can look at it, test it, change it and hopefully make it better. Where it stands today As of right now, PHIF has connectors for six environments: vSphere, OpenShift, OpenStack, Proxmox, XCP-ng and HPE VM Essentials. Each integration has been validated on hardware, and the migration engine has been tested on live hardware between the migration-capable platforms sharing the same FlashArray. That's enough to prove out the architecture. Next I'd like to add more hypervisors through the connector model and see whether array replication opens up cross-array mobility. And since it's modular, you can reuse the one piece you like without buying into the rest. Wrapping up For me, the interesting part of PHIF isn't the UI or the migration wizard. It's how the work is split underneath: the integrations are the foundation, PHIF handles orchestration, and the array is the data plane. When everything shares the same array, you can ask what the storage hardware can do for you. The VDDK changes made that more timely, but they aren't why I built it this way. They just show why those dependency boundaries matter. Sometimes a hypervisor migration really does mean moving a lot of data. But when the source and destination share capable storage, the migration server doesn't have to be the thing doing the moving. The source code, docs, deployment instructions, connector guides and the standalone plugins are all on GitHub: PureStorage-OpenConnect/pure-hypervisor-integration-framework. If you give it a try, I'd like to hear how it goes, so drop a comment here or open an issue on the repo. PHIF is an independent experimental project. It is not a supported Everpure product, is not covered by a support agreement, warranty or SLA, and can perform destructive infrastructure operations. Test it only in environments and against data you can afford to lose.22Views0likes0CommentsOne Year of “Ask Us Everything”: John “Coz” Colgrove on Everpure’s Past, Present, and Future
A special Ask Us Everything anniversary conversation with Everpure cofounder John “Coz” Colgrove explores Everpure’s origins, technical innovations, AI, and the future of data management.48Views0likes0CommentsEnabling Agentic AI via Pure1 Manage MCP Server
Everpure now offers a Pure1® Manage MCP Server so you can query information about your fleet using natural language questions. In this post, I’ll explain how the Pure1 Manage MCP Server works. The first section will explain MCP in general, and the second section will explain how to use our specific server. Feel free to skip to the Quick Start section if you’re already familiar with MCP and just need the parameters to plug into your host. What is MCP? MCP stands for "Model Context Protocol," and it's a way for users to connect their AI applications to external systems using tool calls. MCP tools are fundamentally rooted in application programming interfaces (APIs). An API is a set of rules and protocols that allows different software applications to communicate with each other. It acts as an intermediary, enabling one piece of software (the client) to request information or functionality from another piece of software (the server) without needing to know the server's internal workings. For instance, when you check the weather on your phone, the weather app uses an API to send a request to a weather service, which then returns the current weather data. AI applications have trouble making API calls directly because APIs are designed for completeness and correctness, not for an LLM to use easily. When an AI application wants to use an external system to handle a user’s request, it uses the MCP protocol to make a tool call. The AI (client) requests a function (the tool) from an external system (the server), and the system executes the function and returns a result. This makes MCP a system that standardizes and mediates API-like interactions, allowing AI models to leverage external, real-world capabilities. For more information, see this article on the MCP website: “What is the Model Context Protocol (MCP)?” How can customers benefit from the Pure1 Manage MCP Server? The Pure1 Manage MCP Server enables customers to securely integrate AI assistants, copilots, and agentic systems with live Pure1 telemetry and operational data—without building custom API integrations. It transforms Pure1 from a dashboard-centric experience into an AI-accessible platform, enabling natural language interaction, contextual automation, and real-time operational intelligence. Customers benefit from faster AI integration, reduced engineering effort, preserved security controls, and improved decision velocity across hybrid environments. What types of customer workflows are best suited for MCP? The Pure1 Manage MCP Server is particularly well-suited for agentic and AI-driven workflows, including: Fleet telemetry integration with customer copilots Expose Pure1 telemetry—arrays, volumes, workloads, metrics, and alerts—into internal copilots, chatbots, or AI platforms via MCP endpoints. Value: Unified operational visibility across hybrid and multi-platform environments Automation with context awareness Use MCP to validate storage state, health, performance, or capacity before executing provisioning, backup, or disaster recovery workflows. Value: Safer automation with contextual validation, reduced execution errors, and greater rollback confidence Hybrid cloud observability Correlate Everpure array performance and capacity metrics with application, VM, container, or cloud telemetry across environments. Value: Faster troubleshooting and improved end-to-end performance insights Conversational operational analytics Enable operators to ask real-time natural language questions, such as: “Which arrays are nearing capacity risk?” “Show me the top latency spikes in the last 24 hours.” “Summarize all critical alerts across regions.” Value: Rapid insight without navigating dashboards or exporting reports What the Pure1 Manage MCP Server can do The Pure1 Manage MCP Server exposes the Pure1 Manage REST APIs to AI applications. This means you can ask ad hoc questions about your fleet using natural language, and your AI application will use the server’s tools to query the answer. No programming required. Example conversation Here’s an example conversation demonstrating the use of the Pure1 Manage MCP Server: User: "What is the name of my oldest FlashArray and what is its serial number?" Chatbot:Processing Request: The AI recognizes this as a request for fleet information requiring a tool call. Tool Invocation: Get_hardware Response: The oldest FlashArray in your fleet is named FA-Prod-01 with serial number FA10123456. User: "Can you show me the average I/O latency for that array over the last 7 days?" Chatbot: Let me first check the available latency metrics, then query the historical data: Tool Invocation: Get_metrics Tool Invocation: Get_metrics_history Response: The average I/O latency for FA-Prod-01 (serial FA10123456) over the last 7 days was 0.385 milliseconds. User: "How many arrays do I have in total that are still under warranty?" Chatbot: Processing Request: The AI recognizes this as a request for a count of arrays filtered by warranty status. Tool Invocation: Get_array_support_contracts Response: You currently have 12 arrays in your fleet that are still under active warranty. Quick start Step 1: Register an API key in Pure1 Manage The Pure1 Manage MCP Server leverages the Pure1 Manage REST APIs. In order to access those APIs, you need to register an API key in Pure1 Manage. To do that, follow the directions in the The Pure1® REST API introductory blog post. After going through the instructions, you will have an application id and a private key file, which will be used to generate an access token to access the MCP server in step 2. Step 2: Set up the pure1_token_factory.py script Prerequisites: you need Python 3.12 or greater to run the script. Download pure1_token_factory.zip. Unzip the archive. Go to the unzipped folder in your command-line terminal. Optional but recommended: create and activate a Python virtual environment: python3 -m venv .venv source .venv/bin/activate Install the requirements: pip3 install -r requirements.txt. Run python3 pure1_token_factory.py <application_id> <private_key_file> Copy the generated access token from the script output for the next step. Step 3: Add remote MCP server to your AI application Follow the directions for your AI application to add a remote MCP server (see the Pure1 Manage MCP Server User Guide for instructions for specific chatbots). In general, they need the following information: Remote MCP Server address: https://api.pure1.purestorage.com/mcp Authorization type: header Header name: Authorization Header value: Bearer <access-token> Important: <access-token> is just a placeholder for the access token you generated in step 2. The actual header value should look something like “Bearer eyJ0eXAiO…” Important: you need to generate a new access token every 10 hours and copy it into your AI application You’ll need to run pure1_token_factory.py to generate a new access token every 10 hours, and manually copy the access token into your AI application’s config. Claude Desktop instructions Claude Desktop is a special case because it doesn’t let you set the Authorization header directly. You have to run the mcp-remote local MCP server and configure that to use the Pure1 Manage remote MCP server. Prerequisites You need to have Node.js version 18 or newer installed on your system. Configuration In Claude Desktop, go to Settings > Developer, and click Edit Config. Open the claude_desktop_config.json file in a plain-text editor like VS Code. Configure the mcp-remote server, which is necessary to pass the Authorization header to the Pure1 Manage MCP Server. Paste the token into the configuration file, then restart Claude Desktop. { "mcpServers": { "Pure1 API": { "command": "npx", "args": [ "-y", "mcp-remote", "https://api.pure1.purestorage.com/mcp", "--header", "Authorization:${AUTHORIZATION_HEADER}" ], "env": { "AUTHORIZATION_HEADER": " Bearer <paste access token here>" } } } Note: there might be other configuration options in this file. Be sure to leave them unchanged, and only insert the Pure1 API config in the mcpServers section. The space in the AUTHORIZATION_HEADER environment variable is important. It's there to work around a bug in Windows argument parsing. Please note that: The first time it uses a tool, it will ask you for permission. You can grant permission to all tools at once by going to Customize > Connectors > Pure1 API, and selecting Always Allow under Other tools. For more detailed instructions from Anthropic, please refer to: Connect to local MCP servers - Model Context Protocol.814Views1like0Comments
Using Pure1 AI Copilot to Assess CVE Exposure and Get Upgrade Recommendations
Fleet Security Assessment The Pure1 Fleet Security Assessment provides a fleet-wide view of the security posture of FlashArray and FlashBlade systems by correlating each asset's current software version against Everpure's curated CVE database. Determine whether an asset is exposed to a known CVE A storage administrator can: Log into Pure1. Navigate to Fleet Security Assessment. View all registered arrays within the fleet. For each array, Pure1 automatically identifies: Current Purity version Product family (FlashArray / FlashBlade) Array Name Array ID Serial Number Pure1 compares the running Purity version against the Everpure Product Security Advisory database and determines: Whether the version is affected by known CVEs. Severity of each vulnerability (Critical, High, Medium, Low). Whether a fix is available. Whether a workaround exists. Whether the CVE affects the customer's specific product. Selecting an individual array allows the administrator to review: CVE ID CVSS Score Severity Description Affected component Security Bulletin Fixed version Mitigation guidance This enables administrators to quickly prioritize remediation activities based on risk across their entire storage estate. Using AI Copilot AI Copilot provides a conversational interface to the same security intelligence, allowing administrators to ask questions in natural language rather than navigating multiple dashboards. Examples include: "Is array FA-01 exposed to any critical security vulnerabilities?" Another example: "Which arrays in my fleet are exposed to critical CVEs?" Administrators could also ask: "Show me every FlashBlade affected by OpenSSH vulnerabilities." or "Which arrays are running unsupported Purity versions?" Intelligent Upgrade Recommendations Rather than simply identifying vulnerable arrays, AI Copilot can also recommend an upgrade. AI Copilot will go beyond security and determine whether the array is actually ready for upgrade. Example prompt: "Can I safely upgrade FA-01 to Purity 6.9.4?" AI evaluates: Hardware compatibility Controller generation Installed DirectFlash modules Current Purity version Intermediate upgrade requirements Known upgrade restrictions Health status Replication configuration SafeMode Supportability Current alerts Capacity utilization Pending hardware failures Replication synchronization Outstanding upgrade blockers And determines the most appropriate version based on the customer's environment based on customer’s Current Purity version Current LLR Current ER Security vulnerabilities Feature requirements Hardware support Known software defects Current advisories Upgrade path complexity Engineering recommendations Customer support policy Example: Users could ask: "What version should I upgrade to?" Fleet-wide Upgrade Planning AI could also answer strategic questions such as: "Show every array requiring a security upgrade."or "Which arrays should be upgraded in the next 30 days?" Conclusion The integration of Pure1 Fleet Security Assessment and AI Copilot fundamentally transforms storage security management from a reactive, manual task into a proactive, data-driven strategy. By providing deep visibility into CVE exposure across the entire fleet and delivering intelligent, context-aware Purity upgrade recommendations, Pure1 empowers administrators to mitigate risks before they can be exploited. This shift to strategic fleet planning ensures that storage environments remain resilient, compliant, and optimized, allowing organizations to focus on innovation rather than crisis management.213Views0likes0Comments
The Art of Sizing: The Seven Signals That Help Decide Oracle 26ai Readiness
The Art of Sizing — Series Categories: Databases · Oracle · AI and Machine Learning By Thomas Stutesman, Principal Field Solutions Architect, Everpure A migration readiness scorecard turns raw Oracle AWR telemetry into seven plain-language signals — and shows you exactly where a lift-and-shift would carry yesterday's problems into tomorrow's platform. The migration everyone is planning for Across the industry, many organizations are now looking to move to Oracle AI Database 26ai. The release promises autonomous efficiency, AI-driven insight, and native vector search — but for most teams the path forward is clouded by one uncomfortable question: is our current infrastructure sized for tomorrow, or are we carrying the weight of yesterday's inefficiencies? The 26ai Migration Readiness scorecard is one of the helpful tools Everpure has created to make that migration easier. It takes the telemetry you already have — your Oracle Automatic Workload Repository (AWR) reports — and translates it into a clear, consistent read on where each database stands, so you move with evidence instead of assumptions. This is the first idea in our Art of Sizing series: for a decade, cheap flash and fast cores let us over-provision and "throw hardware at it." Oracle 26ai — with real vector workloads and a hardware market where components cost more and take longer to arrive — ends that era. Disciplined sizing is back, and it starts with reading the right signals. What the scorecard shows Point the assessment at an estate and it produces a single view: every database, scored across seven signals, rolled up into a combined readiness score. In one illustrative example across eight databases, the combined readiness score was 118 out of 168 — with 0 Ready, 7 Caution, and 1 Risk. None were a clean lift-and-shift: seven needed validation and tuning, and one needed remediation before it could move. Each database is scored across the seven signals with a simple traffic light, and the lights roll up into a score out of 21 — seven signals, three points each: Ready — 3 points — inside the healthy threshold Caution — 2 points — worth validating Risk — 1 point — attend to before you move A score of 18–21 is favorable, 13–17 means review needed, and below 13 flags remediation. Think of it as a current-state indicator that tells you where the risk concentrates — not a migration certification. A red flag doesn't mean "cannot migrate." It means the problem will follow you into 26ai — or get worse — if you size the new environment from the old box instead of from the evidence. The seven signals, one by one These are the value items to worry about when sizing for and moving to 26ai. For each, here is what it reads from AWR, why it drives your target design, what a red is telling you, and how Everpure helps you act on it. Signal 01 — System Capacity Reads DB Time against available CPU cores, average active sessions, and host CPU pressure. This sets the compute floor for the target and drives per-core Oracle licensing — size to the old ceiling and you inherit the old bottleneck. On top of that, 26ai's vector and embedding work adds fresh CPU demand. Red means: the source is already CPU-bound; moving as-is relocates the constraint. You need real headroom, not a like-for-like footprint. How Everpure helps: the assessment reports peak (not averaged) CPU demand per database and translates it into a right-sized core count — so the target is provisioned for the real workload plus deliberate headroom, and licensing is planned rather than guessed. Signal 02 — SQL & Parse Reads hard-parse rate, literal (non-bind) SQL, library-cache and cursor-sharing behaviour. 26ai changes optimizer behaviour, so heavy hard-parsing burns CPU, pressures the shared pool, and invites plan regressions on the new release. Red means: application-level SQL that will keep burning CPU or regress on cutover. Plan-stability work (SQL Plan Management, baselines) and shared-pool sizing belong before the move. How Everpure helps: because the assessment looks at the whole estate, not one instance, it surfaces shared SQL/parse patterns across databases — so one remediation effort (often "add bind variables") protects many migrations and lowers the CPU you have to size and license for. Signal 03 — Wait Profile Shows how DB Time splits across CPU, I/O, concurrency, and commit/log waits. It tells you what kind of bottleneck you are actually sizing for — a commit-bound database and an I/O-bound one need very different target designs. Red means: DB Time is dominated by a problematic wait (log file sync, buffer busy, latch/enqueue). Sizing CPU or storage without addressing it just moves the pain. How Everpure helps: Everpure maps the dominant wait class to the right lever — low, predictable write latency on FlashArray for commit/log waits; CPU or memory changes for concurrency waits — so the target attacks the real bottleneck instead of over-buying everywhere. Signal 04 — I/O Profile Reads read/write IOPS, throughput, block size, and latency. This is the direct input to storage sizing, and it separates latency-sensitive OLTP from bandwidth-driven scan/DW workloads — which size very differently. Averages hide the peak windows that actually test the array. Red means: real I/O demand the target tier must sustain. Under-provision here and everything above it — waits, capacity, response time — degrades. How Everpure helps: the assessment moves beyond averages to hour-by-hour peak-window analysis and turns it into a concrete IOPS/throughput/latency target for FlashArray — sub-millisecond and consistent, so the design performs at peak, not just on paper. Signal 05 — Memory Reads SGA/PGA sizing, buffer-cache behaviour, and Oracle's own memory advisories. Right-sizing memory on the target avoids trading RAM savings for a flood of avoidable physical I/O — and under-sized memory quietly inflates the I/O profile, so the two signals move together. Red means: memory is under-provisioned and driving physical reads that should be cache hits. Size SGA/PGA to demand rather than copying the old config. How Everpure helps: Everpure correlates memory pressure with observed I/O, so recommendations account for both together — enough memory to cut needless physical reads, and storage sized for what genuinely reaches disk. Signal 06 — Temp & Work Reads temp tablespace usage, sort/hash spills, PGA work-area activity, and multipass operations. Analytics, reporting, and AI-adjacent workloads live or die on temp and PGA — and 26ai vector operations add sort/compute patterns you have not sized for before. Red means: large sorts/hashes are spilling to temp; without PGA and temp sizing, the workload is slow on day one regardless of platform. How Everpure helps: the assessment quantifies spill behaviour and feeds it into PGA and temp-tier sizing, while FlashArray's consistent low latency keeps unavoidable spill cheap rather than catastrophic. Signal 07 — Segment Risk Reads large or fast-growing segments, chaining, LOBs, partitioning, and use of features like TDE, Hybrid Columnar Compression, and Smart Scan. These are the objects that don't migrate cleanly — reorg candidates, feature-compatibility items, and capacity-growth landmines. Red means: schema-level cleanup, not just capacity: objects that need reorg, or that depend on features the target must be configured to support from day one. How Everpure helps: Everpure auto-detects active features (TDE, HCC, Smart Scan) so the target is configured for them without over-provisioning, and replaces full clones and legacy triple-copy redundancy with space-efficient snapshots and external redundancy to reclaim capacity. From evidence to a right-sized migration The scorecard is the front door. Behind it is an assessment built to turn these seven signals into decisions you can defend to procurement and operations alike. It captures every instance for an ecosystem view, replaces multi-day averages with peak-window analysis, and translates raw metrics into specific storage and configuration recommendations for a 26ai target. It runs privacy-first — hostnames and SQL identifiers are masked, and only the actionable results are shared. Sometimes the biggest finding is what you don't need to buy. One prospect expected to buy 200 TB. The workload needed 18 TB. The gap was legacy ASM high-redundancy (three data copies) plus full clones for dev/test. Moving to Oracle-recommended external redundancy on Everpure and space-efficient snapshots reclaimed roughly two-thirds of the footprint and eliminated over 180 TB of wasted capacity — exactly the kind of trap that nameplate-based sizing would have locked in. From there, a right-sized design lands on a platform built for database density: Everpure FlashArray//XL R5 delivers sub-millisecond, consistent latency and industry-leading data reduction that absorbs vector growth economically. Pure Fusion presets encode your sizing discipline once so every 26ai environment is provisioned the same way, and Pure1 adds fleet-wide performance, capacity forecasting, and application-level context. A sizing-first path to 26ai Assess. Send your AWR reports; the 26ai Readiness Assessment is generated automatically, with identifiers masked. Interpret the signals. Reds are the pre-migration punch list; cautions are the validate list. Watch for fleet-wide patterns. Remediate reds first. Fix CPU, SQL/parse, dominant waits, and segment issues before cutover. Right-size the target. Size compute, memory, temp/PGA, and storage to the measured peak — and strip out redundancy and clone inflation. Provision consistently. Use Pure Fusion presets so every environment is built to the same standard. Validate with a pilot. Confirm behaviour against a representative pilot and target telemetry before scaling the wave. Summary Oracle 26ai brings back the art of sizing. The 26ai Migration Readiness scorecard reads seven signals from your AWR data — System Capacity, SQL & Parse, Wait Profile, I/O Profile, Memory, Temp & Work, and Segment Risk — so you can remediate the reds, right-size the target to your real workload, and move to 26ai with confidence instead of guesswork. Know where you stand — send us an AWR report, and Everpure's Oracle experts will run the 26ai Readiness Assessment on your environment and walk you through the seven signals, your remediation punch list, and a right-sized target design. The readiness score is an AWR-derived, current-state indicator to guide investigation and planning. It is not a migration certification, a final target-platform sizing, or a target-array headroom calculation — those decisions require workload requirements, target telemetry, compatibility checks, and a representative pilot. Database figures shown are illustrative. Oracle is a trademark of Oracle Corporation. © 2026 Everpure, Inc.80Views0likes0CommentsThe Art of Sizing: Breaking the Myths of Oracle Compression
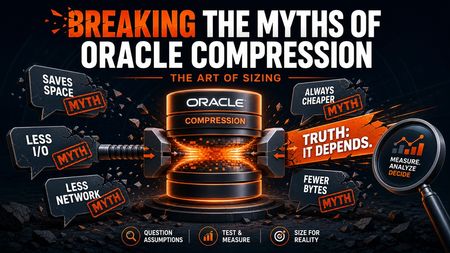
If you work in storage or databases, you have probably heard the pitch: turn on Oracle compression, send fewer bytes, save space, reduce I/O, and lower cost. That sounds great on a slide. In the real world, it is often the opposite. This installment of The Art of Sizing breaks down one of the most persistent myths in enterprise infrastructure: that Oracle host-based compression is automatically a win. We are going to walk through the major compression types, where they help, where they hurt, and why the wrong compression decision can actually create more cost, more network traffic, more I/O, and more work for both storage admins and DBAs. The goal is not to say compression is bad. The goal is to size it correctly, understand where it belongs, and avoid paying premium dollars to make your systems do extra work. Why this myth survives Compression has a good reputation for a reason. Historically, it solved real problems. Storage was expensive, bandwidth was limited, and shrinking data was often the simplest path to efficiency. That logic still holds in some places. But in Oracle environments, especially transactional ones, the story gets more complicated. Oracle is not just writing datafiles. It is writing redo, managing undo, reorganizing blocks, updating symbol tables, and sometimes re-processing data later for deeper compression. That means a “smaller data footprint” does not always equal a smaller infrastructure burden. Sometimes it just shifts the burden somewhere else. First, let’s separate the compression families Not all compression is the same, and not all of it behaves the same way in Oracle. 1. General lossless compression This is the classic world of ZIP, GZIP, LZ77, LZ78, DEFLATE, ZSTD, and similar algorithms. The point is simple: reduce size without losing information. These methods are excellent for files, backups, archives, and many data services. Modern storage platforms use fast versions of these ideas in ways that are largely invisible to the application. 2. Lossy compression Think JPEG, MP3, MPEG, and H.264. These formats intentionally throw away some data in exchange for dramatic size reduction. They are incredibly effective for media, but they are not relevant for Oracle datafiles because databases generally require exact fidelity. 3. Oracle database compression This is where the confusion starts. Oracle has several different compression approaches, each with different behavior, licensing implications, and performance trade-offs: - Basic Table Compression - Advanced Row Compression - Advanced Index Compression - SecureFiles LOB Compression - Hybrid Columnar Compression - RMAN Backup Compression - Automatic Data Optimization and ILM-driven background re-compression Lumping all of those together under “Oracle compression” is one of the fastest ways to make bad architecture decisions. The big myth: compressed writes mean less work Here is the myth in plain English: If Oracle compresses the data before it sends it to storage, the network carries fewer bytes, the array writes less data, and the whole system gets more efficient. What that myth ignores is the full lifecycle of an Oracle write. In active transactional systems, Oracle prioritizes commit latency. That means the redo stream is written first, and it is written uncompressed. Later, as blocks fill and thresholds are crossed, Oracle may compress or re-compress them in memory. That structural change can generate additional redo. If data is later pushed into deeper formats through background optimization or archive-style compression, the system may read, process, and write the same data again. So yes, one part of the path may get smaller. But the total system effort often gets bigger. Figure 1: The life of a compressed I/O inside Oracle (OLTP write path). Notice that data is NOT compressed when it first travels to storage as redo, that write amplification happens at the threshold-hit step, and that this is where the footprint can start to grow. How to actually see it happening This is the part both DBAs and storage admins care about: how do you know Oracle is revisiting blocks, delaying compression, and generating extra work after the commit already succeeded? The threshold delay, in plain English With Advanced Row Compression, Oracle does not usually compress every row the moment it is inserted. Instead, rows are typically written into the block uncompressed first so Oracle can keep transactional latency low. Oracle keeps watching the remaining free space in that 8KB block. Once the block crosses an internal fullness threshold, Oracle goes back, builds or updates the symbol table, batch-compresses the block in memory, and then has to account for that structural change. That delayed work is what I mean by the threshold delay. So the timeline looks more like this: user writes data Oracle writes redo for durability commit returns quickly the block stays in buffer cache the block fills further threshold is crossed Oracle compresses or re-compresses the block in memory additional redo and block maintenance activity can follow That is why the system can look quiet at commit time and then busy again later. How you can tell Oracle is "redoing" things You are usually not looking for one giant smoking gun. You are looking for a pattern where post-commit activity does not line up with the simple story of "we wrote it once and moved on." Common signs include: redo generation that seems higher than expected for the amount of business data changed continued redo and log write activity after the original insert burst is over CPU spikes around block maintenance rather than just around user SQL periodic write bursts that do not line up cleanly with front-end transaction volume maintenance-window bandwidth spikes when colder data is being reworked into deeper compression formats storage-side churn where the array still sees a lot of activity even though the data was supposedly "compressed already" At the database layer, the giveaway is often the mismatch between application change volume and the total work observed in redo, background activity, and later data movement. At the storage layer, the giveaway is seeing traffic patterns that look like read-process-write loops rather than a single smooth write path. Why the database can get larger after a few days This confuses a lot of people because they expect compression to make the footprint immediately smaller and keep it smaller. Figure 2: The background ADO/HCC re-compression path. Days or weeks after the initial write, background jobs read cold data off the array, re-process it on the host, and write it back, so segments can grow from extra redo, undo, rewritten copies, and unreclaimed space. But Oracle compression can create delayed growth behaviors for several reasons: new rows may land uncompressed first and only later be reorganized recompression work can generate extra redo and undo background optimization jobs may read old blocks, reorganize them, and write new versions back out old extents may not be reclaimed immediately even after data is moved or rewritten free space inside segments may become fragmented in ways that do not instantly shrink the physical files if data is updated repeatedly, blocks can split, migrate, or be rewritten in ways that increase segment size before any long-term savings appear So what looks like "compression should have made this smaller" can become "the system created more structures, more history, and more rewritten copies before it settled down." For storage admins, this often shows up as a database that writes out one size on day one and then consumes more logical or physical space over the next several days as Oracle continues block maintenance, redo generation, archive activity, and background reorganization. The practical operator lesson If you want to understand whether compression is helping or hurting, do not just compare the first write size to the final stored size. Instead, look at the full lifecycle: initial redo volume later redo spikes buffer-cache and CPU behavior around block fullness archive log growth background maintenance windows segment growth over time instead of only at load completion storage bandwidth and write churn several days after the original ingest That is where the threshold delay becomes visible. That is where the myth breaks. Why host-based compression can cost more money This is where The Art of Sizing matters most. Compression is often sold as a capacity story, but in Oracle it can quickly become a licensing and CPU story. Advanced Row Compression and SecureFiles LOB Compression are paid features. That means you are not just paying in cycles, you may be paying in Oracle licensing. And if compression overhead pushes CPU consumption higher, you may end up needing to license more cores just to preserve the performance you had before. That is a brutal trade: - You pay for the compression feature. - You spend host CPU running the compression feature. - You may need more licensed cores because of the compression feature. - You still do not eliminate redo overhead. At that point, “saving space” can become one of the most expensive optimizations in the stack. Why it can create more network traffic This is the part that surprises people. On transactional writes, the redo stream still moves as uncompressed change data so Oracle can preserve low-latency commit behavior. That means the initial transactional path does not magically shrink just because the table eventually lands in a compressed state. Then the hidden traffic starts: - secondary redo generated when blocks are compressed or re-compressed - additional log activity to track structural changes - background movement when colder data is reorganized into deeper compression formats - read-process-write cycles for jobs like ADO or HCC-related maintenance For the SAN, that can mean less of a neat “compressed payload” story and more of a churn story. Why it can create more I/O Storage admins know this instinctively: once a system starts revisiting the same data repeatedly, the theoretical savings usually get eaten by operational noise. That is what can happen here. A write is not always a single write anymore. It can become: - the original transactional activity - redo logging for durability - later in-memory compression work - secondary redo for compression state changes - future background read-and-rewrite operations for deeper compression That is not reduced work. That is redistributed work, with extra steps. For busy OLTP systems, that redistribution can show up as more write amplification, more jitter, and more performance variance than people expected when they first heard the word “compression.” Why it creates more operational work Compression decisions do not just affect hardware. They create administrative drag. DBAs have to understand which compression mode is active, what is licensed, what is free, what silently triggered usage, and how it affects redo, CPU, and maintenance windows. Storage admins have to explain why the array still sees redo churn, why bandwidth spikes appear during data reorganization, and why dedupe or downstream efficiency may not look the way a simplified Oracle story suggested. And everyone gets more work when performance troubleshooting starts with a bad assumption. A quick breakdown of the Oracle compression types Basic Table Compression Good for bulk loads and relatively static datasets. It is not a magic answer for active transactional workloads because standard ongoing DML does not benefit the same way. Advanced Row Compression This is the big one in OLTP discussions. It supports active transactional operations, but it is also where deferred compression, block threshold behavior, secondary redo, and paid licensing can combine into a very expensive surprise. Advanced Index Compression Useful in the right indexing scenarios, especially with repetitive keys. This is more targeted and usually not the villain in the story, but it still needs to be understood separately from table compression. SecureFiles LOB Compression Can reduce footprint for large objects like documents, JSON, XML, and similar content, but it pushes work onto host CPU and can throttle ingestion performance when volumes are high. Hybrid Columnar Compression Very powerful for analytics, archival, and cold data patterns. It is not designed like OLTP row compression, and it often belongs in a very different conversation. When used through background movement or deep reorganization, it can generate substantial read-process-rewrite churn. RMAN Backup Compression A separate discussion from live transactional compression. Useful when applied deliberately, but some algorithms can also introduce licensing implications. The sizing lesson This is the heart of the series. Do not size from the brochure claim. Size from the full path of work. When evaluating compression, ask these questions: - What happens on the initial write path? - What happens to redo? - What CPU tax lands on the host? - Does this feature introduce licensing cost? - Will background maintenance create bursts of read-write churn later? - Is the data really a good fit for host-side database compression, or would array-level reduction be cleaner? If you do not answer those questions, you are not sizing compression. You are just hoping it behaves the way marketing described it. Where compression often belongs instead For many environments, especially where modern storage platforms provide inline reduction, the cleaner design is to let the database do database work and let the array do storage work. Figure 3: Myth vs reality, where should compression live? Host-side compression adds CPU, redo, and license cost, while array-level compression keeps host writes normal and delivers predictable I/O with global dedupe. That changes the equation: - less host CPU consumed by compression logic - fewer surprises tied to paid database options - fewer extra redo side effects from re-compression behavior - more predictable storage-side efficiency - a simpler operational model for both DBAs and storage teams That does not mean every Oracle compression feature is wrong. It means compression should be placed where it creates the least total system friction. And in many real-world environments, that is not at the host. Final thought: compression is not free just because it saves space Compression can absolutely be part of a smart architecture. But if you only measure saved capacity and ignore processor cost, network churn, redo behavior, maintenance overhead, and operational complexity, you can easily end up paying more to store less. That is the myth this post is here to break. In The Art of Sizing, the best design is not the one with the smallest number on a capacity chart. It is the one that delivers the best total outcome across cost, performance, simplicity, and operational sanity. And when it comes to Oracle compression, that usually starts with asking a harder question: Is this actually reducing work, or just moving it somewhere more expensive? Coming next In the next installment, we will look at the relationship between compression and encryption in Oracle, and why that combination can further change what the storage team sees and what the database team pays for.144Views0likes0CommentsThe Art of Sizing: When Your "Safe" Standby Database Starts Hurting Production
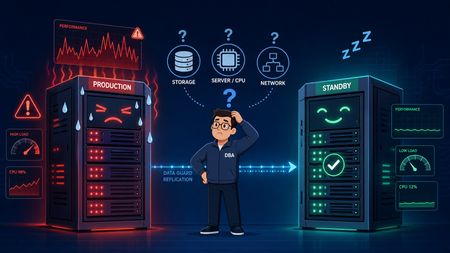
In earlier posts in The Art of Sizing, the focus was on what happens when Oracle systems create their own instability through design shortcuts that seem harmless at first. This post extends that same idea into Data Guard, where a standby database that looks like passive insurance can become part of the foreground performance problem when it is undersized or poorly observed. That is the trap with synchronous disaster recovery. The standby is not just sitting there waiting for a failover. In MAX AVAILABILITY or MAX PROTECTION with SYNC AFFIRM, the primary commit path is directly dependent on the standby receiving redo, writing it to the standby redo log, and acknowledging that write before user sessions are released. When that standby server is short on CPU, struggling on storage, or starved for memory, the latency does not stay isolated on the remote side. It propagates backward into production as log file sync pain, commit stalls, and application slowdown. Why this problem is easy to miss The diagnostic challenge is that the evidence is often sitting on the standby side, but a physical standby in Active Data Guard read-only mode does not behave like a normal local AWR source. Standard local AWR reporting is not enough, and if Remote Management Framework is not already configured, the team can be in the middle of an incident without the standby visibility they actually need. That is what makes this a sizing topic rather than just a monitoring topic. If the standby participates in the commit path, then its storage behavior, CPU headroom, and buffer pressure are part of the production design whether teams acknowledge that or not. How to expose standby performance in Oracle 19c In Oracle 19c, the practical answer is to enable RMF so the primary can collect standby performance snapshots remotely and store them safely in the primary SYSAUX tablespace. The configuration sequence below is the key setup step that makes standby AWR reporting usable during a real production event. -- 1. Enable Management Pack Access on both instances ALTER SYSTEM SET control_management_pack_access='DIAGNOSTIC+TUNING' SCOPE=BOTH; -- 2. Register Nodes and Establish Topology on Primary EXEC DBMS_UMF.configure_node('NODE_PRIMARY', 'PRIMARY'); EXEC DBMS_UMF.configure_node('NODE_STANDBY', 'STANDBY'); EXEC DBMS_UMF.create_topology('ADG_AWR_TOPOLOGY'); -- 3. Link Remote Topology and Enable AWR Service EXEC DBMS_UMF.register_node( 'ADG_AWR_TOPOLOGY', 'NODE_STANDBY', 'DB_LINK_TO_STANDBY', 'DB_LINK_TO_PRIMARY', 'AS_NODE', 'TRUE' ); EXEC DBMS_WORKLOAD_REPOSITORY.register_remote_database( node_name => 'NODE_STANDBY' ); Once the standby is registered, reports can be generated from the primary by running awrrpti.sql and selecting the standby DBID from the menu. What to watch for in a standby AWR report The most useful way to read a standby AWR during a production slowdown is to correlate primary symptoms with standby evidence. The issue usually presents itself as one of a few recognizable patterns. Primary production symptom Standby AWR red flag Likely meaning Spike in log file sync and high SYNC transport lag High log file parallel write on the standby, especially above roughly 5 to 10 ms The standby storage tier is underperforming and slowing standby redo log flushes. Primary LGWR stalls on LNS wait on send Standby host CPU utilization near 100 percent or a high load average The standby is CPU-starved and RFS processes are not acknowledging packets quickly enough. Commit stalls appear at particular hours High ASH on the standby from user reporting activity Heavy Active Data Guard reporting is taking CPU and buffer cache away from recovery work. Flush delays and transport buffer saturation High free buffer waits or checkpoint completed during MRP Buffer cache is too small or DBWR is saturated on the standby. The sizing lesson underneath the incident The bigger lesson is that standby design is not a secondary hardware conversation. In synchronous architectures, the primary database is only as fast as the weakest link in the standby path. That means a disaster recovery platform should not be treated as a low-priority landing zone built from slower storage, thinner CPU allocation, or loosely governed reporting workloads. If it participates in commit acknowledgment, it participates in production performance. The practical operating principles are straightforward: Keep the standby infrastructure performance-symmetric with production where synchronous protection is required. If Active Data Guard is used for reporting, govern those read workloads so they cannot starve RFS or MRP activity. Enable RMF-based standby AWR collection before there is a crisis, not during one. Final thought A standby database is supposed to be your safety net. But in synchronous Data Guard, a poorly sized or poorly monitored standby can become part of the outage story itself. That is the real point here: availability architecture is still performance architecture, and the standby is still part of the sizing equation. That is also why this topic belongs in The Art of Sizing series. Good sizing is not just about capacity. It is about understanding which components quietly sit inside the critical path, and making sure they are designed, monitored, and governed accordingly. Sources The Art of Sizing Data Guard and the Hidden Cost of Small Redo Decisions150Views0likes0CommentsClaude Code as Database SRE: Catching What Your Monitoring Never Will with Everpure Fusion MCP
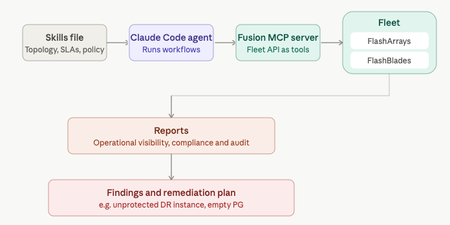
Your DR site might be quietly unprotected and no alert will tell you. That's the gap Anthony Nocentino, Principal Architect at Everpure, Microsoft Data Platform MVP, and self-described computer nerd set out to catch. He built a Database SRE agent using Claude Code and the Everpure Fusion MCP server to audit SQL Server fleets against compliance policy, uncovering a silently unprotected DR instance before disaster struck. Read the full report at "Using Claude Code as a Database SRE Agent with the Everpure Fusion MCP Server"69Views0likes0CommentsAnnouncing the Everpure Fusion™ Mastery Program
Looking for a practical way to build your Everpure Fusion™ expertise? We're excited to introduce the Everpure Fusion™ Mastery Program—a guided, self-paced program designed to help you get more value from Everpure Fusion while earning rewards along the way. Short learning activities are combined with hands-on technical tasks you can apply directly in your own environment. You'll build skills, gain confidence, and put Everpure Fusion to work in real-world scenarios. And the more of the program you complete, the more points you get to use on fun prizes. The program follows three stages: Activation Readiness Prepare your environment and successfully activate Everpure Fusion. Use & Optimization Apply Everpure Fusion to operational workflows, automation, and day-to-day management. Advocacy Share your expertise, contribute to the community, and help others on their journey to unified fleet management. Whether you're just getting started or already using Everpure Fusion, the program meets you where you are. Current users can even earn credit for work they've already completed while continuing to build deeper Everpure Fusion expertise. And because progress deserves recognition, you'll earn Everpure Fusion Points as you complete activities and milestones. Redeem your points for rewards while advancing your Fusion skills. Best of all, the program is designed for busy infrastructure teams. Activities are self-paced and manageable, allowing you to make progress whenever it fits your schedule. Build your skills. Put Everpure Fusion to work. Earn rewards. It’s really that simple. Ready to get started? Click here107Views0likes0CommentsGet rid of stressful infrastructure headaches. Everpure Fusion handles your data, autonomously.
It happens! It's 11:45 PM on a Friday. An alert fires and storage latency has spiked across a production workload. The operator digs in and traces it back to an automated tiering policy that quietly moved a hot dataset to a slower tier because it looked idle based on a 24-hour access window, right before a scheduled batch job that runs every weekend. Nobody changed anything. The policy did exactly what it was configured to do. But nobody remembers configuring it that way, the documentation hasn't been touched in two years, and the monitoring dashboard shows storage as "healthy" because utilization is fine. It's just in the wrong place. The operator overrides the tier, performance recovers, and spends the next hour writing an incident report for a problem that shouldn't exist. A system that was supposed to make life easier made a decision with no context, no warning, and no visibility into why. That's the anger that doesn't go away quickly. It's not just frustration at the incident. It's the feeling that the tools are working against you instead of with you. The core problem in that story was a system making decisions with no context, no warning, and no visibility. Everpure Fusion attacks each of those problems: Unified visibility across the entire fleet: Everpure Fusion provides a global dataset as a single source of truth for discovery, management, and configuration of storage arrays so the operator isn't piecing together what happened across multiple dashboards, multiple arrays, multiple tickets after the fact. They see the full picture in one place, before things go wrong. Intelligent workload placement: Rather than static policies quietly acting on stale access patterns, Everpure Fusion uses AI-guided placement to boost performance and efficiency for every workload. It understands workload behavior, not just utilization snapshots, the kind of context that would have caught a batch job pattern before tiering the dataset down. Policy-driven governance with real control: Automated orchestration cuts manual tasks and speeds service delivery, while unified controls simplify audits, reduce risk, and prove compliance fast. Policies are visible, documented, and governable. Not buried configs nobody remembers setting. Built into the platform, not bolted on: Evepure Fusion is now simply a part of Purity, meaning it is not an add-on you have to install or buy, but rather a core piece of the Purity operating system. The operator doesn't have to manage another tool. The intelligence is already there. The operator in that story didn't need more alerts. They needed a system that understood context, made decisions transparently, and gave them control without requiring them to be online at midnight to maintain it. That's exactly the gap Everpure Fusion is designed to close - with One Fleet, Zero Complexity. Why policy-driven storage operations matter Everpure Fusion is built as the core of Everpure intelligent control plane that manages all arrays including FlashArray, FlashBlade, and cloud as a unified fleet, with one topology, one API, and one operational framework regardless of protocol or local - datacenter, cloud or edge. That uniformity is what makes policy enforcement reliable at scale. Everpure Fusion introduces workload-based provisioning through presets, which are predefined policy-driven templates for specific workload types, encoding protection policies, replication, and SafeMode retention from the moment a workload is provisioned, not patched in after an incident. Admins no longer need to pre-plan and tune deployments manually, which reduces the risk of non-compliance and improves resiliency by ensuring workloads are provisioned correctly from the beginning. The result is infrastructure that enforces your intent, not just your last manual action. Intelligent placement, rebalancing, and fleet-scale capacity control If you manage storage at scale, you've probably seen this scenario play out more than once. One array is buried, running hot, and screaming for relief. Three aisles over, another array is sitting at 40% utilization, doing almost nothing. And somewhere in between, your team is scrambling to provision capacity, kick off an emergency migration, and explain to stakeholders why an SLA was missed on a workload that, in hindsight, never should have been placed there in the first place. This is not a people problem. It is a tooling problem. And it is remarkably common. Everpure Fusion starts solving this problem at the moment of provisioning. When a new workload lands, most storage systems do a simple capacity check and place it wherever space is available. Everpure Fusion does something fundamentally different. The placement engine evaluates every array in the fleet simultaneously, looking at IOPS headroom, throughput capacity, and physical utilization before making a decision. The goal is not just to find somewhere to put the workload. It is to find the right home for it, one where it can live comfortably for the long term without creating a bottleneck down the road. Think of it as placing workloads with intention rather than convenience. Of course, environments do not stay static. Workloads grow, usage patterns shift, and an array that looked healthy six months ago can become a problem today. Everpure Fusion accounts for this with continuous rebalancing built directly into its operation. When an array starts trending toward overload, Everpure Fusion detects it and begins orchestrating data movement across the fleet automatically. No manual intervention required. No application downtime. Data migrates in the background while workloads keep running, and arrays that were sitting underutilized suddenly become productive members of your infrastructure. At fleet scale, now supporting up to 64 arrays, this turns capacity management from a constant firefight into something that largely runs itself. What makes this possible without disruption is how Everpure Fusion executes the move under the hood. It leverages ActiveCluster to stretch the volume across both the source and target arrays simultaneously, creating a synchronous mirror in place. Once the stretch is established, volumes are connected on the target array and hosts auto-discover the new target paths through standard multipathing. The target then validates that path usage is healthy and confirmed before any cutover begins. Only after that validation is complete are the volumes disconnected from the source, ensuring there is zero gap in access at any point in the sequence. Everpure Fusion then unstretches from the source array to complete the rebalance and release its capacity. The result is a seamless, non-disruptive migration that the application never sees. What truly sets Everpure Fusion apart from a standard load balancer is what happens under the hood. Powered by Pure1 AI and up to 30 days of historical workload data, Everpure Fusion does not just look at what is happening right now. It looks at what is about to happen. Say you have a workload that runs a heavy batch job every Saturday night. Everpure Fusion knows that. It has seen the pattern. So when the placement engine is evaluating tier assignments, it will never recommend moving that workload to a lower-performance tier just because it looks quiet on a Tuesday afternoon. It understands what Tuesday quiet actually means in context. And if that workload somehow ends up on the wrong tier, perhaps through a manual change or a migration gone sideways, Everpure Fusion will proactively raise a violation before the weekend arrives. Not after the SLA is missed. Before. The cumulative effect is that customers can operate their fleets closer to full utilization without the anxiety that normally comes with it. Underused hardware gets activated, incremental purchases get deferred, and the reactive, always-behind-the-curve model of capacity management starts to look like a problem from a previous era. And Everpure Fusion does not stop at the infrastructure layer. Through its integration with Pure1 Application Intelligence, Everpure Fusion gains deeper visibility into the nature of the workloads themselves, not just how they behave, but what they actually are. That additional context means smarter decisions at every level, from initial placement to long-term tier management, grounded in a more complete picture of what your environment is really doing. Workload rebalance and mobility will be available towards the end of 2026. Compliance as part of the control plane Most storage compliance workflows follow the same pattern: an audit is announced, someone pulls reports from three different tools, cross-references configuration against a spreadsheet of expected settings, and spends two weeks proving that workloads are protected the way they're supposed to be. Then the audit ends and nothing changes until the next one. That model breaks at fleet scale. When you're managing dozens of arrays across multiple sites and protocols, manual audits don't just slow you down — they leave gaps that only get discovered at the worst possible time. Everpure Fusion Compliance is built into the control plane, not bolted on after provisioning. Because Everpure Fusion presets encode protection policies, replication requirements, SafeMode retention, and QoS settings at deployment time, Everpure Fusion always knows what every workload's intended configuration is. Drift detection is continuous — not periodic. When a workload deviates from its preset, Everpure Fusion instantly surfaces the violation — visible in the UI, queryable via API or CLI, and accessible to AI agents through an MCP server. Remediation can be triggered directly through the same interfaces, without pulling in a separate tool or writing a custom script. Fleet-wide compliance dashboards give storage admins a live view of posture across every array, with exportable audit-ready reports that don't require manual assembly. The shift is meaningful: compliance becomes a property of how the fleet operates, not a project that interrupts how the team works. Everpure Fusion Compliance will be available towards the end of 2026. From dashboards and scripts to natural-language fleet operations You know the drill. A latency spike hits production. You open three dashboards, run a handful of CLI queries, dig through alert logs, and piece together enough context to understand what happened — and by then, you've already spent 45 minutes on a problem that should have taken five. The issue isn't the tools. It's that the context your fleet holds is trapped across systems that don't talk to each other. Everpure Fusion MCP Server changes that. Built on the open Model Context Protocol standard, it connects any MCP-compatible AI assistant — Claude, ChatGPT, Copilot, or internal agents — directly to live Everpure Fusion fleet state. Arrays, workloads, capacity, performance metrics, alert history, configuration, and placement data are normalized into clean, structured JSON and made available to AI in real time, pulled directly from Everpure Fusion and Purity REST APIs. The result: instead of navigating dashboards and stitching together CLI output, you ask a question. "Which arrays are approaching capacity?" "What's driving latency on this workload?" "Which workloads are drifting from their preset?" Everpure Fusion MCP Server answers from live fleet context, not stale snapshots. This is the on-ramp to agentic storage operations. Everpure Fusion already enforces policy and placement across the fleet. Pure1 adds AI-driven analytics and recommendations on top. Together, they give infrastructure operators the foundation to move from reactive troubleshooting to intent-driven, increasingly autonomous fleet management. Using topology groups to encode real infrastructure boundaries If your Everpure Fusion fleet's topology model lives in a color-coded spreadsheet, three wikis, and the institutional memory of one senior admin who never takes vacation — this is for you. Everpure Fusion, built into Purity for FlashArray and FlashBlade, introduces Topology Groups: fleet-scoped objects that let you describe your arrays in the same language your architecture diagrams already use — regions, availability zones, datacenters, rows, racks. No more provisioning a Everpure Fusion workload and hoping it lands in the right building. A Everpure Fusion Topology Group is a hierarchical, tree-structured object. Groups nest up to 10 levels deep (global → us-east → az-us-east-1a → dc01 → row3 → rack12), each array belongs to exactly one parent, and cycles are rejected at write time. Critically, they encode placement semantics — not access control. RBAC stays in Pure1 Resource Groups; topology stays in Everpure Fusion topology. Once modeled, Everpure Fusion presets reference groups using <group>.arrays notation. Everpure Fusion intersects the preset's allowed arrays with the group's membership at placement time. If there's no overlap, Everpure Fusion provisioning fails fast with a clear error — not silently in the wrong zone. The Everpure Fusion CLI shorthand makes automation clean: purevol list --context az-us-east-1a.arrays Everpure Fusion membership changes propagate automatically across the fleet. You stop maintaining a second source of truth outside the control plane. Stop treating topology as tribal knowledge. With Everpure Fusion, make it a first-class part of the intelligent control plane. Extending the model to Kubernetes and virtualization Most infrastructure operators are managing two parallel storage worlds right now: traditional VMs and databases on one side, Kubernetes-based containerized workloads on the other. Separate toolchains. Separate provisioning workflows. Separate everything. Everpure Fusion changes that. Through the Portworx Fusion Controller, Everpure Fusion extends its policy and placement control plane directly into Kubernetes — without forcing developers to change their existing workflows. Everpure Fusion auto-discovers your FlashArray and FlashBlade fleet, then exposes Everpure Fusion presets as native Kubernetes StorageClasses. That means when a developer requests a persistent volume, Everpure Fusion's placement engine resolves it against your existing policy constraints — storage class, protection policy, topology group, replication requirements — the same way it does for any other Everpure Fusion workload. No separate control plane for modern environments. No array-by-array configuration for each cluster. New arrays added to the fleet are automatically discovered and configured, so the operational model stays consistent as infrastructure grows. For VMware environments, Everpure Fusion extends the same operational model through the Everpure Fusion vSphere plugin, connecting storage management directly into virtualization workflows instead of running it as a separate administrative domain. The result: one control plane, one set of policies, one placement engine — spanning VMs, containers, and databases across the fleet. That is fewer parallel stacks to operate, less configuration drift between environments, and a more scalable path to consistent storage operations across the full infrastructure stack. Everpure Fusion as the storage admin foundation for autonomous operations The through-line across everything covered in this blog is simple: Everpure Fusion gives infrastructure operators a unified, policy-driven control plane that enforces intent consistently — across provisioning, placement, compliance, topology, and now Kubernetes and virtualization. That foundation matters because autonomous storage operations do not start with AI. They start with structure. Topology groups encode where workloads belong. Presets encode how they should be configured. Everpure Fusion presets exposed as StorageClasses ensure Kubernetes environments follow the same rules as everything else. When that structure is in place, AI can recommend, optimize, and eventually act — because the context is already clean, trusted, and machine-readable. For storage admins, the shift is real: less time resolving incidents caused by placement decisions nobody remembers making, more time defining the intent that governs the fleet. Everpure Fusion is that foundation — built into Purity, not bolted on. Want to learn more about Everpure Fusion? Check out the following links to dive deeper: Join the Everpure Fusion Mastery Program to build expertise, complete hands-on activities and earn rewards. Sign up for a Fusion test drive to try it out on your own time. Check out more about Fusion product details. Watch our cool new Fusion demo videos. Read Everpure Fusion Datasheet152Views0likes0Comments