FlashCrew London & Glasgow May/June 2025 !!!! Register NOW...
I'd like to invite you to our upcoming FlashCrew Customer User Group in London on May 15th, from midday. Throughout May, we'll be taking our FlashCrew User Group on the road to share ideas, best practices and network on all things Pure over some drinks and food. Plus, as a thank you for your continued support and attendance we will of course have the latest FlashCrew branded gifts for you to take with you! If you can make it, please register at this link below. London 10-11 Carlton House Terrace Thursday 15th May: REGISTER HERE for FLASHCREW LONDON Glasgow Radisson Blu Hotel Thursday 5th June: REGISTER HERE for FLASHCREW GLASGOW These are user group meetings, targeted at a technical audience across Pure's existing customers. Not only will you hear the latest news on the Pure Enterprise Data Cloud, but will also get to network with other like-minded users and exchange ideas and experiences. Agenda: 12:00 - 12:50 Arrival, Lunch and Welcome 13:00 - 14:00 Pure Platform: Features and Roadmap: with demo 14:00 - 14:15 Break 14:15 - 14:45 SQL Databases and Pure 14:45 - 15:15 Voice of the Customer 15:15 - 15:30 Break 15:30 - 16:15 Portworx and the Enterprise Data Cloud 16:15 - 16:45 Modern Virtualisation 16:45 - 17:00 Open Floor Q&A, Raffle, Wrap Up 17:00 - 19:00 Drinks and Networking300Views5likes0CommentsComing soon! The Pure Fusion MCP Server
Have you tried out the power and flexibility of using MCP Servers in your daily admin life? If you haven't, you shoulld really look into the power that they can provide. Pure has developed it's own MCP server for Pure Fusion and we will be releasing it soon. Check out this blog article to read more about the "sneak peek" into what is coming. And always remember - Automate! Automate! Automate!219Views4likes0CommentsEverpure PowerShell SDK 2.52.323 released! New Cmdlets, Parameters, & More!
If your FlashArray automation has reached the point where every new Purity feature means another wrapper function, another chunk of parameter-validation code, and another comment that says “temporary workaround,” this release is for you. Everpure PowerShell SDK 2.52.323 is the latest GA release of the SDK for FlashArray. 64 new cmdlets and 47 existing cmdlets with new parameters. The more useful way to think about it is this: a whole lot of storage operations that used to sit just outside your PowerShell toolbox are now much closer to first-class automation. And yes, there’s an important footnote before we get too excited - we’re still a bit behind on the API parity with Purity. We’re still working on that.Stay tuned!. Wrappers, Drift, Chaos... Oh My PowerShell is great right up until the API surface you need isn’t represented by a cmdlet yet. Then the usual routine begins: A little REST, a little PowerShell. Authentication, URI construction, JSON bodies, response parsing, and error handling all end up in the same script. A little inventory archaeology. Someone has to remember which array has which policy, which workload belongs to which directory, and whether that “new” script still matches the current API. A little parameter drift. The array supports a capability, but your automation doesn’t expose it because the wrapper was written six months ago. A little naming chaos. Not enough to make the script fail, naturally. Just enough to make the next person stare at it for twenty minutes. The old way works. It’s just not especially fun to maintain, and “works” is doing a lot of heavy lifting there. So what exactly is new in 2.52.323? This release updates the SDK’s cmdlet coverage for Purity REST API versions 2.0 through 2.52. It adds new entry points across object storage, policies, quality of service, protection, identity, realms, workload placement, and more. Here are the areas that stood out to me in the release notes. Object Store gets a much bigger PowerShell surface There are new cmdlets for working with: Buckets and bucket performance/space information Lifecycle rules Object Store access keys, accounts, users, and user policies Object Store virtual hosts Object Store access policy members and rules That includes the basic create, update, remove, and get operations you’d expect in an automation workflow. In other words, Object Store administration is less likely to require a detour into raw REST calls just because the script needs to create a bucket or rotate an access key. Network access policies become scriptable The release adds cmdlets for network access policy objects, members, and rules, along with operations for creating, updating, removing, and inspecting them. There are also new array parameters for associating network access policies by ID, name, or resource type. That’s the kind of small-looking addition that becomes important when you’re trying to make a script reusable across arrays instead of hard-coding one environment’s identifiers into it. QoS coverage expands across the stack New cmdlets expose QoS information for hosts, host groups, volumes, volume groups, and realms. Existing host and host-group creation and update cmdlets also gain bandwidth and IOPS limit parameters. That gives you a more consistent way to describe performance intent in automation. Instead of treating QoS as a manual cleanup step after provisioning, your script can include the limits as part of the object lifecycle. Workload-aware directory and file-system operations A large part of the parameter expansion is about workloads. Directory and file-system cmdlets gain workload IDs, workload names, workload configuration, policy associations, default protection options, and related controls. There are also new workload-oriented parameters for NFS, SMB, snapshot, and quota policies. This is useful if your automation thinks in terms of applications and workloads rather than treating every volume, directory, or file system as an isolated object. Presets and placement recommendations expose more detail New-Pfa2PresetWorkload and Set-Pfa2PresetWorkload gain a substantial set of parameters for naming patterns, directory configurations, export configurations, quota and snapshot behavior, periodic replication, QoS, and placement. The placement recommendation cmdlet also gains parameters for richer result data, including target IDs and names, resource types, capacity, model, placement configuration, replication configuration, warnings, and capacity/load projections. This matters because a placement recommendation is more useful when automation can inspect why a target was selected, what its projected state looks like, and what warnings came back — not just whether a recommendation existed. Tags show up in snapshot workflows The new tag-related parameters on volume snapshot and remote protection group snapshot operations include tag namespace, key, value, copyability, and tag context/resource references. That’s a nice fit for scripts that use tags to carry ownership, application, environment, or operational metadata through protection workflows. More coverage around realms, SSO, offload, and remote resources The release also adds or expands cmdlets around: Realm connections and connection keys Remote realms and remote realm tags Remote pods SSO/SAML configuration Azure offload identity and placement settings Active Directory service testing Array cache inspection Support system manifests This is a broad release, not a single-feature release wearing a new version number. The common thread is that more of the things admins already manage in Purity are now represented in the SDK. 47 new parameters is arguably the more interesting part New cmdlets are easy to spot. New parameters are where existing automation gets more capable without needing a complete rewrite. A few examples from the release notes: ContextName and AllowError are added to several commands, including DNS, network interface, realm, and connection-path operations. QosBandwidthLimit and QosIopsLimit are added to host and host-group creation and update operations. WorkloadIds and WorkloadNames are added to directory, file-system, and policy query paths. Azure client, tenant, secret, and placement settings are added to offload creation. Snapshot operations gain tag-related parameters. SSO/SAML operations gain parameters for trusting other SAML service providers in a fleet and setting the service-provider entity ID. Preset workload operations gain a large set of nested configuration parameters, including naming patterns, export settings, quota rules, snapshot rules, replication rules, and placement configuration. The release notes contain the complete cmdlet-by-cmdlet list. I’d use that list as the migration checklist for existing scripts search for the wrapper functions you wrote around these areas, then see whether the SDK now gives you a direct path. There is a HTML Help file available in the GitHub repository. Check it out for an easy reference. The module can be installed side by side with the PowerShell SDK 1.x line, which is helpful if you have older scripts that aren’t ready for a migration project this week. Nobody needs that surprise in the middle of a maintenance window. Compatibility details that kinda matter The release notes call out these requirements and compatibility points: Purity FlashArray support for REST API versions 2.0 through 2.52, inclusive .NET Core 2.1 or later as the stated requirement A 64-bit operating system Windows PowerShell minimum versions for Windows 10, Windows Server 2016, Windows Server 2019, macOS, and Linux macOS and Linux support is noted as not fully tested The practical takeaway: check the host where your automation actually runs, not just the workstation where you first tested the module. A script that works from a newer admin laptop can still fail when it lands on an older jump host with a different PowerShell runtime. A worked example: turning a storage workflow back into storage automation Imagine a team managing application file systems for several environments. Their current process looks like this: Create the file system from PowerShell. Open a separate tool to add policy associations. Manually set QoS on the host group. Add tags to snapshots later, because the first script doesn’t know about them. Keep a second script around to inspect placement results when the environment gets busy. None of those steps is individually terrible. Together, they create the classic “automation” workflow where the human is still the integration layer. With 2.52.323, the team can start consolidating that process around the SDK’s expanded surface: Use the new workload-oriented directory and file-system parameters to carry workload identity and configuration through provisioning. Include host or host-group QoS limits as part of the create or update operation. Use the expanded preset workload parameters to define naming, protection, export, quota, snapshot, replication, and placement behavior together. Inspect placement recommendation targets, warnings, and projections from PowerShell instead of flattening the response into a yes/no result. Apply snapshot tags as part of the protection workflow rather than as a manual afterthought. The point isn’t that one giant script should own the entire storage universe. Please don’t build that script. The point is that each stage can now express more of the intended state directly, with fewer custom REST wrappers sitting between the operator and the array. The nerdy details A few practical observations from the release notes: The SDK exposes Purity REST API functionality as PowerShell cmdlets, so this release is primarily about keeping the PowerShell surface aligned with the API surface. The release adds 64 cmdlets and expands 47 existing cmdlets with new parameters. The release notes do not report performance testing for this release. The full cmdlet and parameter inventory is long, 472 lines in the published release-notes file, so use the source document as the exhaustive reference instead of treating this post as a replacement for it. Why this matters The best SDK release is not the one that gives you the most commands to memorize. It’s the one that lets you delete the most “temporary” code. PowerShell SDK 2.52.323 gives admins more direct coverage for Object Store, policies, QoS, workload configuration, snapshots, tags, realms, placement, and identity. That means fewer hand-built REST calls, fewer disconnected provisioning steps, and a better chance that the automation describes the desired storage state instead of merely replaying the clicks somebody made last quarter. Start with the parts your scripts already work around. Install from the PowerShell Gallery, update the help, compare your wrappers with the new cmdlets and parameters, and migrate incrementally. You don’t have to boil the ocean. You just have to stop rebuilding the same little piece of ocean in every script. Until next time… Cheers!416Views3likes1Comment
Ask Us Everything Recap: Making Purity Upgrades Simple
At our recent Ask Us Everything session, we put a spotlight on something every storage admin has an opinion about: software upgrades. Traditionally, storage upgrades have been dreaded — late nights, service windows, and the fear of downtime. But as attendees quickly learned, Pure Storage Purity upgrades are designed to be a very different experience. Our panel of Pure Storage experts included our host Don Poorman, Technical Evangelist, and special guests Sean Kennedy and Rob Quast, Principal Technologists. Here are the questions that sparked the most conversation, and the insights our panel shared. “Are Purity upgrades really non-disruptive?” This one came up right away, and for good reason. Many admins have scars from upgrade events at other vendors. Pure experts emphasized that non-disruptive upgrades (NDUs) are the default. With thousands performed in the field — even for mission-critical applications — upgrades run safely in the background. Customers don’t need to schedule middle-of-the-night windows just to stay current. “Do I need to wait for a major release?” Attendees wanted to know how often they should upgrade, and whether “dot-zero” releases are safe. The advice: don’t wait too long. With Pure’s long-life releases (like Purity 6.9), you can stay current without chasing every new feature release. And because Purity upgrades are included in your Evergreen subscription, you’re not paying extra to get value — you just need to install the latest version. Session attendees found this slide helpful, illustrating the different kinds of Purity releases. “How do self-service upgrades work?” Admins were curious about how much they can do themselves versus involving Pure Storage support. The good news: self-service upgrades are straightforward through Pure1, but you’re never on your own. Pure Technical Services knows that you're running an upgrade, and if an issue arises you’re automatically moved to the front of the queue. If you want a co-pilot, then of course Pure Storage support can walk you through it live. Either way, the process is fast, repeatable, and built for confidence. Upgrading your Purity version has never been easier, now that Self Service Upgrades lets you modernize on your schedule. “Why should I upgrade regularly?” This is where the conversation shifted from fear to excitement. Staying current doesn’t just keep systems secure — it unlocks new capabilities like: Pure Fusion™: a unified, fleet-wide control plane for storage. FlashArray™ Files: modern file services, delivered from the same trusted platform. Ongoing performance, security, and automation enhancements that come with every release. One attendee summed it up perfectly: “Upgrading isn’t about fixing problems — it’s about getting new toys.” The Takeaway The biggest lesson from this session? Purity upgrades aren’t something to fear — they’re something to look forward to. They’re included with your Evergreen subscription, they don’t disrupt your environment, and they unlock powerful features that make storage easier to manage. So if you’ve been putting off your next upgrade, take a fresh look. Chances are, Fusion, Files, or another feature you’ve been waiting for is already there — you just need to turn it on. 👉 Want to keep the conversation going? Join the discussion in the Pure Community and share your own upgrade tips and stories. Be sure to join our next Ask Us Everything session, and catch up with past sessions here!824Views3likes2Comments
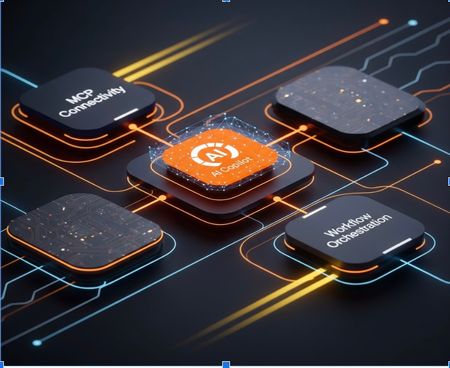
Pure's Intelligent Control Plane: Powered by AI Copilot, MCP Connectivity and Workflow Orchestration
At Accelerate 2025, we announced two capabilities that change how you manage Pure Storage in your broader infrastructure: AI Copilot with Model Context Protocol (MCP) and Workflow Orchestration with production-ready templates. Here's what they do and why they matter. AI Copilot with MCP: Your Infrastructure, One Conversation The Problem Your infrastructure spans multiple platforms. Pure Storage managing your data, VMware running VMs, OpenShift handling containers, security tools monitoring threats, application platforms tracking performance - each with its own console, APIs, and workflows. When you need to migrate a VM or respond to a security incident, you're manually pulling information from each system, correlating it yourself, then executing actions across platforms. You become the integration layer. The Solution Pure1 now supports Model Context Protocol (MCP), taking Copilot from a suggestive assistant to an active operator. With MCP enabled, Copilot doesn’t just recommend - it acts. It serves as a secure bridge between natural language and your infrastructure, capable of fetching data, executing APIs, and orchestrating workflows across diverse systems. Here’s what makes this powerful: You deploy MCP servers within your environment—one for VMware, another for OpenShift, and others for the systems you use. Each server exposes your environment’s capabilities through a standard, interoperable protocol. Pure Storage AI Copilot connects seamlessly to these MCP servers, as well as to Pure services such as Data Intelligence, Workflow Orchestration, and Portworx Monitoring, enabling unified and secure automation across your hybrid ecosystem. What You Can Connect You can deploy an MCP server on any system whether it’s your VMware environment, Kubernetes clusters, security platforms like CrowdStrike, databases, monitoring tools, or custom applications. Pure Storage AI Copilot connects to these servers under your control, securely combining their data with Pure Storage services to deliver richer insights and automation. Getting Started: If you have a use-case around MCP, please contact your Pure Storage account team. Workflow Orchestration: Deploy in Minutes, Not Months The Problem Building production-grade automation takes months. You need error handling, integration with multiple systems, testing for edge cases, documentation, ongoing maintenance. Most teams end up with half-finished scripts that only one person understands. The Solution We built workflow templates for common operations, tested them at scale, and made them available in Pure1. Install them, customize to your needs, and run them in minutes. Key Templates VMware to OpenShift Migration with Portworx Handles complete migration: extracts VM metadata, identifies backing Pure volumes, checks OpenShift capacity, configures vVols Datastore and DirectAccess, uses array-based replication, converts to Portworx format. Traditional migration takes hours for TB-scale VMs. This takes 20 to 30 minutes. SQL / Oracle Database Clone and Copy Automates cloning and copying of SQL Server and Oracle databases for dev/test or refresh needs. Instantly creates storage-efficient clones from snapshots, mounts them to target environments, and applies Pure-optimized settings. The hours-long manual process becomes a quick, consistent workflow completed in minutes Daily Fleet Health Check Scans all arrays for capacity trends, performance issues, protection gaps, hardware health.Posts summary to Slack. Proactive visibility without manually checking each array. Rubrik Threat Detection Response When Rubrik detects a threat, automatically tags affected Pure volumes, creates isolated immutable snapshots, and notifies the security team. Security events propagate to your storage layer automatically. How It Works Workflow Orchestration is a SaaS feature in Pure1. Deploy lightweight agents (Windows, Linux, or Docker) in your data center to execute workflows locally. Group agents together for high availability and governance controls. Integrations Native Pure Storage: Pure1 Connector for full API access, Fusion Connector for storage provisioning (works for Fusion and non-Fusion FlashArray/FlashBlade customers) Third-Party: ServiceNow, Slack, Google, Microsoft,CrowdStrike, HTTP/Webhooks, Pagerduty, Salesforce and more. The connector library continues expanding. Getting Started: Opt-in now in Pure1 - Workflow. Introductory offer available at this time. Check with your Pure account team if you have questions. How They Work Together At Accelerate 2025 in New York, we showcased this capability in action. Here's the scenario: an organization wants to migrate VMs to Kubernetes. Action-enabled Copilot orchestrates communication with Pure Storage appliances and services as well as third-party MCP servers to collect the required information for addressing a problem across a heterogeneous environment. With Pure1 MCP, AI Copilot, and Workflows, there's now a programmatic way to collect information from OpenShift MCP, VMware MCP, and Pure1 storage insights- then recommend an approach on what VMs to migrate based on your selection criteria. You prompt Copilot: "How can I move my VMs to OpenShift in an efficient way?" Copilot communicates across: Your VMware MCP server - to get VM specifications, current configurations, resource usage Your OpenShift MCP server - to check available cluster capacity, validate compatibility Portworx monitoring - to understand current storage performance Copilot reasons across all this information, identifies ideal VM candidates based on your criteria, and recommends the migration approach- which VMs to move, target configurations, and how to preserve policies. Then it can trigger the migration workflow, keeping you updated throughout the process. Why This Matters Storage Admins: Stop being the bottleneck. Enable self-service while maintaining governance. DevOps Teams: Deploy production-tested automation without writing code. Security Teams: Build automated response workflows spanning detection, isolation, and recovery. Infrastructure Leaders: Reduce operational overhead. Teams focus on strategy, not repetitive tasks. Get Started MCP Integration:If you have a use-case around MCP, please contact your Pure Storage account team.. Workflow Orchestration:Opt-in at Pure1 → Workflows. Learn More: Documentation in Pure1 or contact your Pure Storage account team. Pure1 evolved from a monitoring platform to an Intelligent Control Plane. AI Copilot reasons across your infrastructure. Workflow Orchestration executes. Together, they change how you manage data with Pure Storage.1.2KViews2likes0CommentsFlashBlade Ansible Collection 1.22.0 released!
🎊 FlashBlade Ansible Collection 1.22.0 THIS IS A SIGNIFICANT RELEASE as removes all REST v1 components from the collection and adds Fusion support! Update your collections! Download the Collection via Ansible command: ansible-galaxy collection install purestorage.flashblade Download it from Ansible Galaxy here Read the Release Notes here.191Views2likes0CommentsNew Pure Code site is live!
After many months of messing with some very old code, we have launched a revised site for the Pure Code Portal. It is much more minimalistic and cleaner than the old one, and we have plans to add our Code videos and Pure Employee website links in the near future. Have a look and feel free to leave a comment if you would like to see something on the site. https://code.purestorage.com/ Cheers, //Mike490Views2likes1CommentSome Fleet PowerShell code using Invoke-RestMethod
Hello fellow scripters! This script is a PowerShell script that uses native PowerShell cmdlets to do the tasks. It does not use the Pure Storage PowerShell SDK2. This is for folks who do raw API calls using automation packages, runbooks, and scripts. It is not intended to use in it's entirety, but rather to be used as code snippets and starters for your own scripts. The full script is available in this GitHub repository. This script will: Use native PowerShell (non-SDK) Invoke-RestMethod calls to the FlashArray API Authenticates an API Token user and gets the x-auth-token for requests Query a fleet and determine the fleet members Query fleet Presets & Workloads List fleet volumes and hosts (top X, configurable) Create a host, volume, and then connect the volume to the host on a member array. <# .SYNOPSIS Authenticates to Pure Storage FlashArray REST API and retrieves session token. .DESCRIPTION - Authenticates using API token. - Retrieves the x-auth-token from response headers for subsequent requests. - Dynamically queries the FlashArray for the latest available API version and uses it for requests. .PARAMETER Target Required. The FQDN or IP address of the FlashArray to target for REST API calls. .PARAMETER ApiToken Required. The API token used for authentication with the FlashArray REST API. .EXAMPLE .\Connect-FAApi.ps1 -Target "10.0.0.100" -ApiToken "<Your API Token here>" .NOTES Author: [email protected] Origin Date: 10/23/2023 Version: 1.1 #> param ( [Parameter(Mandatory = $true)] [string]$Target, [Parameter(Mandatory = $true)] [string]$ApiToken ) ################ SETUP ################ # Query the array for the latest available API version try { $apiVersions = Invoke-RestMethod -Uri "https://$Target/api/api_version" -Method Get -SkipCertificateCheck $numericApiVersions = $apiVersions.version | Where-Object { $_ -match '^\d+(\.\d+)*$' -and $_ -notmatch '^2\.x$' } $latestApiVersion = ($numericApiVersions | Sort-Object { [version]$_ } -Descending)[0] Write-Host "Latest API Version detected:" $latestApiVersion } catch { Write-Host "Could not retrieve API version, defaulting to 2.45" $latestApiVersion = "2.45" } # Set the Base Uri if ($latestApiVersion) { $baseUrl = "https://$Target/api/$latestApiVersion" } # Prepare headers for authentication $headers = New-Object "System.Collections.Generic.Dictionary[[String],[String]]" $headers["api-token"] = $ApiToken # Authenticate and get session token $response = Invoke-RestMethod "https://$Target/api/$latestApiVersion/login" -Method 'POST' -Headers $headers -SkipCertificateCheck -ResponseHeadersVariable "respHeaders" # Display the value of "username" from the response, if present if ($response.items -and $response.items[0].username) { Write-Host "Username:" $response.items[0].username } else { Write-Host "Username field not found in response." } # TO-DO: Check if user is LDAP or local # Parse "x-auth-token" from response headers and store in $xAuthHeader $xAuthHeader = $respHeaders["x-auth-token"] Write-Host "x-auth-token:" $xAuthHeader # Add x-auth-token to headers for subsequent requests $headers.Add("x-auth-token", $xAuthHeader) # You can now use $headers for further authenticated requests to the FA API ########################################################################### Add pagination, query the fleet: # optional pagination & limit code $continuation_token = $null $limit = 10 # Adjust as needed ################ FLEETS ################ # Get Fleet name $fleetsResponse = Invoke-RestMethod -Uri "$baseUrl/fleets" -Method Get -Headers $headers -SkipCertificateCheck $fleetName = $fleetsResponse.items[0].name #Write-Host "Fleet Name: $fleetName" # Get fleet members $membersUrl = "$baseUrl/fleets/members?fleet_name=$fleetName" $membersResponse = Invoke-RestMethod -Uri $membersUrl -Method Get -Headers $headers -SkipCertificateCheck if (-not $membersResponse.items -or $membersResponse.items.Count -eq 0) { Write-Error "No fleet members found." exit 1 } # Extract Fleet member names $VAR_RESULTS = @() foreach ($item in $membersResponse.items) { if ($item.member -and $item.member.name) { $VAR_RESULTS += $item.member.name } elseif ($item.name) { $VAR_RESULTS += $item.name } } if ($VAR_RESULTS.Count -eq 0) { Write-Error "No member names found in fleet members response." exit 1 } # Write out the fleet members #Write-Host "Extracted Member Names: $($VAR_RESULTS -join ', ')" Query for volumes, hosts: ################ FLEET VOLUMES QUERY ################ # Query volumes for extracted member names $volumesUrl = "$baseUrl/volumes?context_names=$($VAR_RESULTS -join ',')" ## uncomment for full response - no limit, and comment out pagination code below #$volumesResponse = Invoke-RestMethod -Uri $volumesUrl -Method Get -Headers $headers -SkipCertificateCheck #$volumesResponse | ConvertTo-Json -Depth 5 ## with paginated reponse do { ## Build the query string for pagination $queryString = "?limit=$limit" if ($continuation_token) { $queryString += "&continuation_token=$continuation_token" } $volumesUrl = "$baseUrl/volumes$queryString" ## Invoke REST method and capture response headers $volumesResponse = Invoke-RestMethod -Uri $volumesUrl -Method Get -Headers $headers -SkipCertificateCheck -ResponseHeadersVariable respHeaders ## Output volumes data $volumesResponse | ConvertTo-Json -Depth 5 ## Extract x-next-token from response headers for next page $continuation_token = $respHeaders["x-next-token"] ## Continue if x-next-token is present } while ($continuation_token) ################ FLEET HOSTS QUERY ################ # Query hosts for extracted member names $hostsUrl = "$baseUrl/hosts?context_names=$($VAR_RESULTS -join ',')" ## full response - no limit, and comment out pagination code below #$hostsResponse = Invoke-RestMethod -Uri $hostsUrl -Method Get -Headers $headers -SkipCertificateCheck #$hostsResponse | ConvertTo-Json -Depth 5 ## with paginated reponse do { ## Build the query string for pagination $queryString = "?limit=$limit" if ($continuation_token) { $queryString += "&continuation_token=$continuation_token" } $hostsUrl = "$baseUrl/hosts$queryString" ## Invoke REST method and capture response headers $hostsResponse = Invoke-RestMethod -Uri $hostsUrl -Method Get -Headers $headers -SkipCertificateCheck -ResponseHeadersVariable respHeaders ## Output hosts data $hostsResponse | ConvertTo-Json -Depth 5 ## Extract x-next-token from response headers for next page $continuation_token = $respHeaders["x-next-token"] ## Continue if x-next-token is present } while ($continuation_token) Query for Presets & Workloads: ################ FLEET PRESETS QUERY ################ $presetsUrl = "$baseUrl/presets?context_names=$($VAR_RESULTS -join ',')" $presetsResponse = Invoke-RestMethod -Uri $presetsUrl -Method Get -Headers $headers -SkipCertificateCheck -ResponseHeadersVariable respHeaders $presetsResponse | ConvertTo-Json -Depth 5 ################ FLEET WORKLOADS QUERY ################ $workloadsUrl = "$baseUrl/workloads?context_names=$($VAR_RESULTS -join ',')" $workloadsResponse = Invoke-RestMethod -Uri $workloadsUrl -Method Get -Headers $headers -SkipCertificateCheck -ResponseHeadersVariable respHeaders $workloadsResponse | ConvertTo-Json -Depth 5 Create a Host on a fleet member array, create a volume, connect the volume to the host: ################ CREATE VOLUME, HOST, AND CONNECT THEM ON ANOTHER FLASHARRAY IN THE FLEET ################ # Select a secondary FlashArray in the fleet $otherArrayName = $VAR_RESULTS | Where-Object { $_ -ne $Target } | Select-Object -First 1 if (-not $otherArrayName) { Write-Error "No other FlashArray found in the fleet." exit 1 } Write-Host "Selected secondary FlashArray for operations: $otherArrayName" # Create a new volume on the secondary FlashArray $newVolumeName = "APIDemo-Vol01" $volumePayload = @{ name = $newVolumeName size = 10737418240 # 10 GiB in bytes context = @{ name = $otherArrayName } } $createVolumeUrl = "$baseUrl/volumes" $createVolumeResponse = Invoke-RestMethod -Uri $createVolumeUrl -Method Post -Headers $headers -Body ($volumePayload | ConvertTo-Json) -ContentType "application/json" -SkipCertificateCheck Write-Host "Created volume:" $newVolumeName "on" $otherArrayName # Create a new host on the secondary FlashArray $newHostName = "FleetDemoHost01" $IQN = "iqn.2023-07.com.fleetdemo:host01" $hostPayload = @{ name = $newHostName iqn = @($IQN) context = @{ name = $otherArrayName } } $createHostUrl = "$baseUrl/hosts" $createHostResponse = Invoke-RestMethod -Uri $createHostUrl -Method Post -Headers $headers -Body ($hostPayload | ConvertTo-Json) -ContentType "application/json" -SkipCertificateCheck Write-Host "Created host:" $newHostName "with IQN:" $IQN "on" $otherArrayName # Connect the newly created volume to the newly created host $connectPayload = @{ volume = @{ name = $newVolumeName context = @{ name = $otherArrayName } } host = @{ name = $newHostName context = @{ name = $otherArrayName } } } $connectUrl = "$baseUrl/host-volume-connections" $connectResponse = Invoke-RestMethod -Uri $connectUrl -Method Post -Headers $headers -Body ($connectPayload | ConvertTo-Json) -ContentType "application/json" -SkipCertificateCheck Write-Host "Connected volume" $newVolumeName "to host" $newHostName "on" $otherArrayName # Output results $createVolumeResponse | ConvertTo-Json -Depth 5 $createHostResponse | ConvertTo-Json -Depth 5 $connectResponse | ConvertTo-Json -Depth 5168Views2likes0Comments
Pure1 API: get_hardware returns array references with id only (no name/fqdn) for one array
Hi all, We consume the Pure1 public REST API (1.6) via py-pure-client to sync hardware inventory, and hit something I'd like to sanity-check with the community. What we see: For one FlashArray in our fleet, every item returned by get_hardware carries an array reference with only the id and resource_type: {"id": "<array-uuid>", "resource_type": "arrays"} For every other array (several dozen), and for all items from get_network_interfaces — including that same array's interfaces — the reference is complete: {"id": "<array-uuid>", "name": "<array-name>", "resource_type": "arrays", "fqdn": "<array-fqdn>"} Why it matters The SDK model for this reference (FixedReferenceFqdn) documents fqdn as "the fully qualified domain name of the appliance when resource_type is arrays", so the id-only shape looks like it doesn't match the schema. py-pure-client models raise AttributeError when an unset field is accessed, so code that reads ref.name directly crashes rather than getting None. It started roughly a week ago. All the affected items also share one _as_of timestamp from that time, i.e. that array's hardware snapshot hasn't refreshed since. What we've ruled out Not a Purity version effect: the array's Purity//FA version hasn't changed in weeks, and many other arrays on the same version return complete references. Workaround (in case it helps anyone) Resolve the array from the reference id via get_arrays() instead of relying on name: id_to_name = {a.id: a.name for a in client.get_arrays()} ref = item.arrays[0] name = getattr(ref, "name", None) or id_to_name.get(getattr(ref, "id", None)) Questions Has anyone else seen id-only array references from Pure1 — and what triggered it (re-registration, phone-home/connectivity, something on the Pure1 side)? Is an id-only reference ever expected for resource_type "arrays", or is name/fqdn guaranteed? Any recommended way to detect that an array's Pure1 data has stopped refreshing, beyond checking _as_of? We've also raised it with our SE. Thanks!65Views1like1Comment