 513Views5likes0Comments
FlashCrew London & Glasgow May/June 2025 !!!! Register NOW...
I'd like to invite you to our upcoming FlashCrew Customer User Group in London on May 15th, from midday. Throughout May, we'll be taking our FlashCrew User Group on the road to share ideas, best practices and network on all things Pure over some drinks and food. Plus, as a thank you for your continued support and attendance we will of course have the latest FlashCrew branded gifts for you to take with you! If you can make it, please register at this link below. London 10-11 Carlton House Terrace Thursday 15th May: REGISTER HERE for FLASHCREW LONDON Glasgow Radisson Blu Hotel Thursday 5th June: REGISTER HERE for FLASHCREW GLASGOW These are user group meetings, targeted at a technical audience across Pure's existing customers. Not only will you hear the latest news on the Pure Enterprise Data Cloud, but will also get to network with other like-minded users and exchange ideas and experiences. Agenda: 12:00 - 12:50 Arrival, Lunch and Welcome 13:00 - 14:00 Pure Platform: Features and Roadmap: with demo 14:00 - 14:15 Break 14:15 - 14:45 SQL Databases and Pure 14:45 - 15:15 Voice of the Customer 15:15 - 15:30 Break 15:30 - 16:15 Portworx and the Enterprise Data Cloud 16:15 - 16:45 Modern Virtualisation 16:45 - 17:00 Open Floor Q&A, Raffle, Wrap Up 17:00 - 19:00 Drinks and Networking290Views5likes0CommentsWhy Are We Still Designing IT Like It's 2012?
Let’s talk about complexity in IT. Not the fun kind—like building a Raspberry Pi-powered coffee machine or arguing over whether Terraform should be capitalized. I mean the kind of complexity that slows teams down, bloats your stack, and makes security people question their career choices. You know the type: five backup platforms, three monitoring tools, two storage vendors “for resilience,” and a bunch of scripts someone wrote in 2019 that nobody’s brave enough to touch. We tell ourselves it’s “best-of-breed,” “cloud-first,” or my personal favorite—“strategic.” But let’s call it what it is: chaos without any direction. Enter Conway’s Law (aka the Mirror You’ve Been Avoiding) Melvin Conway dropped this gem in 1967: “Organizations design systems that mirror their own communication structures.” Still true. Still brutal. If your company has six teams that don’t talk to each other except through passive-aggressive Jira tickets, your architecture is going to reflect that—fragmented, redundant, over-engineered, and impossible to secure. Conway’s Law isn’t just a quirky observation. It’s a diagnostic tool. If your architecture feels like a group project gone off the rails, chances are it’s because your org works that way too. Cloud Chaos: Now with More Vendors! And just when you thought it couldn’t get worse—we bring in the cloud. Or clouds. Somewhere between “cloud-first” and “cloud-only,” we lost the plot. We started treating hyperscalers like interchangeable gas stations: need compute? Just pull over at the nearest one. We’ve seen it: Migrations from AWS to Azure to GCP like it’s some weird tech pilgrimage Applications lifted and shifted with zero refactoring Hybrid architectures that “just sort of happened” Look, the cloud’s not the problem. I like cloud and I believe it is here to stay. But designing 100% for the cloud without actually understanding your why? That’s Conway’s Law, just with bigger invoices. Even worse? Bouncing between cloud providers because someone read a Forrester report and got nervous about lock-in. That’s not strategy—that’s cloud-induced panic. The Two-Vendor Lie We Keep Telling Ourselves Ah yes, the old two-vendor strategy. Meant to be safe. Designed to reduce dependency. What it really does? Doubles your complexity and halves your team’s sanity. Two vendors = two playbooks, two consoles, two support teams blaming each other It’s not more resilient—it’s just more confusing Gartner even calls it out: more vendors = more risk, not less If you think managing multiple tools with overlapping functions is safer than consolidation, congrats—you’ve just invented the world’s most expensive “Oops” button. Manual ≠ Secure. It Just Feels That Way Let’s talk about the weird rituals we still do in the name of security: Manually copying data to “safe zones” Turning off network access like it’s a security blanket Spinning up siloed sandboxes to avoid risk It’s not protection. It’s procrastination. Manual controls introduce human error, waste time, and don’t scale. If your “strategy” depends on someone remembering to toggle a firewall rule every Thursday, you're not secure—you’re just lucky. And outsourcing that chaos to a vendor doesn’t make it better. Handing over management to a provider that’s Frankensteined a bunch of loosely integrated tech with bailing wire and hope isn’t a strategy—it’s just renting someone else’s mess. If there’s no real roadmap, no cohesion, no architectural vision—it’s not a partnership. It’s a future support ticket waiting to happen. Hybrid Cloud Needs Purpose, Not Permission Hybrid isn’t a backup plan. It’s a design decision. Too many shops end up hybrid by accident—because apps don’t refactor, budgets don’t stretch, or politics get in the way. The result is an environment that’s technically working but operationally exhausting. A good hybrid strategy is opinionated. You should know: What runs where (and why) How data moves What your north star architecture looks like If you don’t have answers to that? You’re not doing hybrid—you’re doing hope. So What Do We Do About It? We simplify. On purpose. Relentlessly. Design like a startup, not a committee. Keep the stack lean. Less is more when you have tools that actually integrate. Use Conway’s Law in reverse. Want systems that work together? Build teams that do too. Break silos before they become dependencies. Treat cloud like architecture, not an escape route. Cloud is amazing if you design for it. Otherwise, it’s just someone else’s complexity in your billing statement. Stop solving people problems with platform purchases. Most complexity isn’t technical—it’s cultural. No vendor can fix your org chart. Final Thought: Complexity Is a Tax. Stop Paying It. Every extra platform, every vendor “just in case,” every manual handoff is a tax. And it’s compounding interest on your ability to execute. If you want to move fast, secure your data, and stay sane—you’ve got to design with purpose. That means fewer tools, better alignment, and architectures that reflect how you want to operate, not how your politics force you to. You want resilience? Start with intention. But what I’m really curious about is your perspective: How are you dealing with complexity? Is hybrid working for you—or just holding you hostage? Have you successfully simplified your architecture without sacrificing flexibility? Let's make this a real convo—not another “cloud is the answer” thread. —Zane Allyn206Views5likes0CommentsPure Certifications
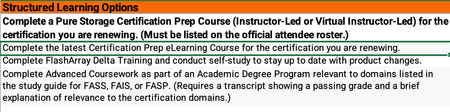
Hey gang, If any of you currently hold a Flash Array certification there is an alternative to retaking the test to renew your cert. The Continuing Pure Education (CPE) program takes into account learning activities and community engagement and contribution hours to renew your FA certification. I just successfully renewed my Flash Array Storage Professional cert by tracking my activities. Below are the details I received from Pure. Customers can earn 1 CPE credit per hour of session attendance at Accelerate, for a maximum of 10 CPEs total (i.e., up to 10 hours of sessions). Sessions must be attended live. I would go ahead and add all the sessions you attended at Accelerate to the CPE_Submission form. Associate-level certifications will auto-renew as long as there is at least one active higher-level certification (e.g., Data Storage Associate will auto-renew anytime a Professional-level cert is renewed). All certifications other than the Data Storage Associate should be renewed separately. At this time, the CPE program only applies to FlashArray-based exams. Non- FA exams may be renewed by retaking the respective test every three years. You should be able to get the CPE submission form from your account team. Once complete email your recertification Log to [email protected] for formal processing.1.1KViews4likes1CommentDon’t Wait, Innovate: Long‑Life Release 6.9.0 Is Your Gateway to Continuous Innovation
How Pure Releases Work (and Why You Should Care) Pure Storage doesn’t make you choose between stability and innovation: Feature Releases arrive monthly and are supported for 9 months. They’re production‑ready and ideal if you like to live on the cutting edge. Long‑Life Releases (LLRs) bundle those feature releases into a thoroughly tested version which is supported for three years. LLR 6.9.0 is essentially all the innovation of those Feature releases, rolled into one update. This dual approach means you can adopt new features as soon as they’re ready or wait for the next stable release—either way, you keep moving forward. Not sure what features you’re missing? Not a problem as we have a tool for that. A coworker reminded me: Pure1’s AI Copilot can tell you exactly what you’ve been missing. Here’s how easy it is to find out: Log into Pure1, click on the AI Copilot tab, and type your question. My coworker reminded me of this last week, so I tried: “Please provide all features for FlashArray since version 6.4 of Purity OS.” Copilot returned a detailed rundown of new capabilities across each release. In just a couple of minutes, I saw everything I’d overlooked—no digging through release notes or calling support required. A Taste of What You’ve Been Missing Here’s a snapshot of the goodies you may have missed across the last few year releases: Platform enhancements: FlashArray//E platform (6.6.0) extends Pure’s simplicity to tier‑3 workloads. Gen 2 chassis support (6.8.0) delivers more performance and density with better efficiency. 150 TB DirectFlash modules (6.8.2) boost capacity without compromising speed. File services advancements: FlashArray File (GA in 6.8.2) lets you manage block and file workloads from the same array. SMB Continuous Availability shares (6.8.6) keep file services online through failures. Multi‑server/domain support (6.8.7) scales file services across larger environments. Security and protection: Enhanced SafeMode protection (6.4.3) quadruples local snapshot capacity and adds hardware tokens for instant data locking which is vital in a ransomware era. Over‑the‑wire encryption (6.6.7) secures asynchronous replication. Pure Fusion: We can't talk about this enough Think of this as fleet intelligence. Fusion applies your policies across every array and optimizes placement automatically, cutting operational overhead . Purity OS: It’s Not Just Firmware Every Purity OS update adds value to your existing hardware. Recent improvements include support for new NAND sources, “titanium” efficiency power supplies, and advanced diagnostics. These aren’t minor tweaks; they’re part of Pure’s Evergreen promise that your hardware investment keeps getting better over time. Why Waiting Doesn’t Pay Off It’s tempting to delay updates, but with Pure, waiting often means you’re missing out on: Security upgrades that counter new threats. Performance gains like NVMe/TCP support and ActiveCluster improvements. Operational efficiencies such as open metrics and better diagnostics. Future‑proofing features that prepare you for upcoming innovations. Your Roadmap to Capture These Benefits Assess your current state: Use AI Copilot to see exactly what you’d gain by moving to LLR 6.9.0. Plan your update: Pure’s non‑disruptive upgrades let you modernize without downtime. Explore new features: Dive into Fusion, enhanced file services, and expanded security capabilities. Connect with the community: Share experiences with other users to accelerate your learning curve. The Bottom Line Pure’s Evergreen model means your hardware doesn’t just retain value it continues to gain it. Long‑Life Release 6.9.0 is a gateway to innovation. In a world where data is your competitive edge, standing still is equivalent to moving backward. Ready to see what you’ve been missing? Log into Pure1, fire up Copilot, and let it show you the difference between where you are and where you could be.805Views4likes0CommentsThe Idea That Was Supposed to Fail
Why DirectFlash and Evergreen//One suddenly look a lot smarter in a world of NAND and DRAM price shocks Dmitry Gorbatov Mar 20, 2026 Important Note for my readers: Writing this piece took me a lot longer than I normally spend on a post. It took a lot of reading and research. Many articles and blogs were written on the subject before NAND and DRAM costs went crazy. The dry-humor version is that the storage industry spent years insisting flash was just disk with better manners, and then acted surprised when the underlying physics eventually asked to speak with management. Now, let’s get to it. I can still picture the room. It wasn’t anything special — just another corporate competitive training session, the kind you’ve sat through many times if you’ve spent enough years in enterprise tech. This was at NetApp, in 2015 or 2016, back when flash was still a question mark. Not if, but how. The industry had not fully committed yet, and everyone was trying to figure out what role it would play. The presenter clicked to the next slide, paused for a second, and said something that stuck with me in a way most of those sessions never do: “Pure Storage is crazy! They’re building their own flash modules. That’s stupid. It’s not sustainable. They won’t survive.” It wasn’t said for effect. There was no dramatic pause afterward, no attempt to persuade. It was delivered as a simple, almost obvious conclusion. And to be fair, it felt obvious. Because the entire storage industry operated on a shared assumption: you didn’t build components, you assembled them. You relied on a mature ecosystem of suppliers who specialized in drives, storage controllers, and memory, and you focused your differentiation on software features and integration. That was the efficient path. That was the scalable path. That was how serious companies behaved. What Pure was proposing at the time — what would later become Everpure — felt like a deviation from that logic. Building your own flash modules didn’t just introduce complexity; it seemed to reject the economic advantages of the broader supply chain. It looked like a risk without a clear payoff. So the conclusion made sense. Until it didn’t. Looking Back, Differently If I think back to that training session now, I do not really see it as a moment where someone was foolish. I see it as a moment where the industry was trapped inside the logic of its own assumptions. If you believe flash should look like disk, then building your own flash modules sounds silly. If you believe storage is just a sequence of refresh cycles, then a model built around non-disruptive evolution sounds unnecessary. If you believe component pricing will keep trending in the right direction forever, then architectural efficiency feels like an academic luxury. But once those assumptions start to crack, the logic changes. And when it changes, the things that once looked eccentric start to look oddly prescient. A Change You Don’t Notice Right Away For years, nothing about that statement felt particularly worth revisiting. The industry moved forward in predictable ways. Flash became mainstream. Performance improved. Density increased. Vendors competed on features, benchmarks, and price points. The conversations most of us had with customers followed familiar patterns. If anything, the abstraction layers built around flash made things easier to consume. SSDs behaved like faster disks — and that was good enough. There is a reason they showed up in familiar HDD form factors. The industry was trying to preserve the old world while sneaking in a new medium. Keep the slots. Keep the enclosures. Keep the assumptions. Change as little as possible. That made adoption easier, but it also buried the problem. Because flash is not a disk. It never was. It does not behave like one, and it does not particularly enjoy being treated like one. The only reason the illusion worked is because the industry built a fairly elaborate translation layer to maintain it. That translation layer is where the story really starts. The Trick That Made Flash Look Simple When commodity SSDs became the standard way to bring flash into enterprise storage, they depended on a piece of internal firmware called the Flash Translation Layer, or FTL. Its job was deceptively simple: make raw NAND look like a disk. That sounds harmless enough until you think about what that actually requires. NAND cannot just overwrite data in place the way the rest of the stack would like it to. It has to handle erase cycles, wear leveling, garbage collection, bad block management, and the constant translation between logical addresses and physical locations on the media. So every SSD became its own little self-contained world, complete with its own controller, its own metadata tables, and its own DRAM to keep track of everything. In other words, every drive became a tiny independent computer, making local decisions in isolation. That design solved the adoption problem. It did not solve the architecture problem. For a while, the tradeoff seemed worth it. The drives were fast enough, the packaging was familiar, and the whole system kept pretending that flash was just a much nicer version of disk. But what looked neat and modular at small scale turned out to be awkward and expensive at enterprise scale. And that is where the “stupid” decision begins to look a lot smarter. What Commodity SSDs Actually Drag Along With Them The more I researched this topic (and believe me I did), the more I realized how much of the industry got comfortable with an abstraction that was doing a lot of quiet damage. Commodity SSDs carry four structural inefficiencies that matter much more today than they did when pricing was stable. Trapped DRAM. Every SSD maintains its own mapping tables, so large-scale systems end up carrying a remarkable amount of DRAM inside the drives themselves. That memory is necessary for the SSD to function, but it does not really help the array think globally. It is duplicated overhead, repeated again and again, drive by drive. In a petabyte-scale system, that is not a rounding error. It is cost, power, and complexity hiding in plain sight. Unpredictable Latency. Garbage collection inside a traditional SSD happens when the drive decides it needs to happen. When that occurs, the drive may become temporarily less responsive, and in an array full of independent drives, those little stalls start to show up as tail-latency spikes. The system is always vulnerable to one drive having a private crisis at exactly the wrong time. Write Amplification. Because the SSD does not really understand the workload or the data structures above it, it moves data more often than necessary. More movement means more writes. More writes mean more wear. More wear means the media gets consumed faster than it should. Over-provisioning. Every SSD holds back some raw capacity for its own housekeeping and spare-cell management, but that reserved space is siloed. The array cannot use it intelligently across the system because each drive is managing its own private affairs. None of this sounded especially dramatic when NAND kept getting cheaper and the economics of flash kept improving. It sounded like engineering trivia. The sort of thing infrastructure people argue about while everyone else waits for the quote. Today it is not trivia. Today it is exposure. Why AI Made This Suddenly Everyone’s Problem For years, one of the quiet assumptions in enterprise IT was that storage capacity would continue to become cheaper and more abundant over time. Not perfectly, not smoothly, but predictably enough that the inefficiencies of the underlying architecture could be tolerated. That assumption is now not only under pressure, it is getting decimated. AI did not just create a new category of interesting workloads. It created a global appetite for silicon that is large enough to bend supply curves. The cute part of AI is easy to mock. The cat kicking the T-Rex. The surreal generated videos. The deepfakes that make you look twice and then sigh a little for civilization. But behind every one of those outputs is a less funny reality: extraordinary consumption of DRAM, NAND, GPUs, and supporting infrastructure. The novelty at the edge is powered by very serious resource demand at the core. And that demand is landing directly on the components enterprise storage depends on. This is the part customers are beginning to feel in ways that are no longer abstract. Expansion quotes do not look as comfortable as they once did. Refresh cycles feel more expensive. Delivery windows stretch. Budgets built on assumptions from even two years ago suddenly need more explaining than anyone wanted. There is a tendency to call this inflation because that is the easiest word available. It is not really inflation. It is supply and demand, with a side of semiconductor reality. And that matters, because a traditional SSD array is exposed to both sides of the problem at once. It is exposed to NAND because that is the medium you are buying, and it is exposed to DRAM because every SSD drags its own DRAM overhead along for the ride. When those two markets tighten at the same time, the cost of the architecture gets hit twice. That is not just a technical nuance. That is economics. Revisiting the “Stupid” Decision This is where the old training-room comment starts to age badly. Because what looked like unnecessary vertical integration was really a decision to stop pretending flash was a disk and start treating it like what it actually is: semiconductor media with very specific physical behaviors that should be managed at the system level, not hidden inside dozens of drives. That is the DirectFlash idea in plain English. Take the Flash Translation Layer out of the individual drive. Pull media management into the operating environment. Let Purity manage flash globally instead of leaving each device to improvise its own local strategy. That changes more than performance charts. It means metadata no longer has to be duplicated and trapped inside every SSD. It means wear leveling can happen across the full system instead of inside the borders of a single device. It means bad block handling, garbage collection, and data placement can be coordinated with global context. It means the platform can see the difference between data that should live together and data that should not, which dramatically reduces unnecessary movement and lowers write amplification. And when write amplification drops, the economics change. The NAND lasts longer. The useful life of the media extends. Lower-endurance flash, like QLC, becomes viable for serious enterprise use because the software is smart enough not to abuse it. The system extracts more useful work from the same raw silicon. That is not just clever engineering. That is insulation from volatility. The reason this matters now is that DirectFlash changes the ratio between the silicon you buy and the value you get from it. If the rest of the market is paying more for NAND and more for DRAM, an architecture that reduces trapped DRAM, minimizes wasted writes, extends media life, and packs far more capacity into far denser modules is not just elegant. It is economically defensive. This is where the old “they build their own flash” criticism misses the point. Building your own flash modules was never the point by itself. The point was controlling the relationship between software and media well enough to eliminate the inefficiencies the commodity model had normalized. Why Purity Is the Real Story DirectFlash makes for a good visual. It is a module. You can point to it. You can talk about density and reliability and the fact that a 150TB module can do work that would have required a small army of traditional devices not all that long ago. But the real story is Purity Operating Environment, i.e. software. Purity is where the architectural bet pays off. It is what turns raw NAND into a coordinated system instead of a pile of politely disagreeing SSDs. Because Purity sees the entire media pool, it can write more intelligently. It can group data with similar expected lifespans together, so that when a snapshot or a temporary workload disappears, whole regions of storage can be retired cleanly instead of forcing background reshuffling of still-live data. That reduces unnecessary churn. Less churn means fewer writes. Fewer writes mean longer media life. Because Purity sees when a NAND die is busy with an erase or program cycle, it can avoid letting that become a host-visible performance problem. RAID-3D and system-level awareness allow the platform to reconstruct data from parity rather than simply waiting for a busy drive to get its act together. The end result is deterministic performance rather than a roulette wheel of occasional latency spikes. Because Purity owns media management globally, the over-provisioning and spare resources are no longer trapped in per-drive silos. The system can use them strategically. I know that all of this sounds a bit scientific, and to be fair, it is. I did spend over 7 years working for Everpure and a few weeks researching for this post. I wanted to sit with that science for a bit. Where the Economics Start to Matter The moment component pricing becomes unpredictable, architecture stops being an engineering preference and starts becoming a financial strategy. That is the part that matters most to customers right now. A traditional buying model assumes that at some point you will hit a refresh cycle, a capacity wall, or a migration event that forces a purchase whether the market timing is good or terrible. You buy when you have to buy. If NAND is expensive, that is unfortunate. If DRAM is expensive too, even better, because apparently the universe enjoys symmetry. That is what makes the combination of DirectFlash and Evergreen so important. DirectFlash reduces the amount of waste, duplication, and premature wear in the system. Evergreen removes the old habit of tying innovation to forklift replacement. Controllers evolve. Capacity can be consolidated into denser modules over time. Data stays in place. The customer is not forced into rebuying the whole environment every few years just to remain current. That already changes the economics. But it still leaves one more question: who is carrying the price risk? And this is where Evergreen//One matters more than ever. The Part I Actually Wanted to Get To Evergreen//One is not just a consumption model. It is not just a nicer way to finance storage. It is a mechanism for moving volatility away from the customer. That is the conclusion I wanted to earn, not just declare. When NAND and DRAM prices start climbing, most traditional models push that turbulence straight into the customer’s planning cycle. The customer eats the increase, absorbs the uncertainty, and tries to explain to the business why the infrastructure line now behaves like it has a gambling problem. Evergreen//One changes that relationship. The customer consumes capacity as a service. Everpure owns the burden of the underlying hardware lifecycle, the media strategy, and the ongoing optimization. DirectFlash makes that model stronger because the platform is structurally more efficient with the silicon it uses. It needs less trapped DRAM, wastes fewer writes, extends media life, and supports denser modules that deliver more usable capacity per unit of power, space, and raw media. Purity compounds that advantage with data reduction, ongoing software improvements, and smarter system-wide media management. Put differently, Everpure is in a much better position to absorb and manage component volatility than a customer buying boxes on a refresh schedule. That is the real price protection story. Not some magical promise that economics no longer apply. They do. NAND still costs what NAND costs. DRAM still costs what DRAM costs. Physics remains annoyingly undefeated. The difference is who is exposed to that volatility, how much inefficiency is built into the system before the customer ever sees it, and whether the operating model gives the customer a stable runway instead of a quarterly surprise. DirectFlash reduces the waste. Evergreen removes the forced disruption. Evergreen//One shifts the risk. That combination is a lot more interesting than it sounded in that room 11 years ago. The Part I Didn’t Appreciate Then What I did not understand sitting in that room 11 years ago was that some decisions are made for futures that have not arrived yet. The market eventually caught up to the architecture. That does not happen often enough in enterprise tech to ignore when it does. DirectFlash was never interesting just because it was different. It was interesting because it removed layers of inherited inefficiency that the rest of the market had accepted as normal. And in a period where NAND and DRAM pricing are under pressure, removing inefficiency is no longer just a performance story. It is a protection story. That is why this matters now. Not because it makes for a clever slide. Because it gives customers a more predictable way forward when the underlying component markets are anything but predictable. And in the current environment, that might be the most practical definition of innovation there is. Appreciate you reading. Dmitry Gorbatov © 2025 Dmitry Gorbatov | #dmitrywashere688Views3likes1CommentCincinnati PUG 3
Well, it's the start of the year and time to start planning our next Cincinnati User Group. In our last meeting we discussed Cyber Resiliency with Shawn Snider, Chief Information Security Officer at SEHP. This session we look to tackle topics around Enterprise File. We have targeted January 28th, again at Ace's Pickleball. I or Nick Fritsch will post the verified details soon. Looking forward to more great discussion and collaboration!334Views3likes2Comments
Ask Us Everything Recap: Making Purity Upgrades Simple
At our recent Ask Us Everything session, we put a spotlight on something every storage admin has an opinion about: software upgrades. Traditionally, storage upgrades have been dreaded — late nights, service windows, and the fear of downtime. But as attendees quickly learned, Pure Storage Purity upgrades are designed to be a very different experience. Our panel of Pure Storage experts included our host Don Poorman, Technical Evangelist, and special guests Sean Kennedy and Rob Quast, Principal Technologists. Here are the questions that sparked the most conversation, and the insights our panel shared. “Are Purity upgrades really non-disruptive?” This one came up right away, and for good reason. Many admins have scars from upgrade events at other vendors. Pure experts emphasized that non-disruptive upgrades (NDUs) are the default. With thousands performed in the field — even for mission-critical applications — upgrades run safely in the background. Customers don’t need to schedule middle-of-the-night windows just to stay current. “Do I need to wait for a major release?” Attendees wanted to know how often they should upgrade, and whether “dot-zero” releases are safe. The advice: don’t wait too long. With Pure’s long-life releases (like Purity 6.9), you can stay current without chasing every new feature release. And because Purity upgrades are included in your Evergreen subscription, you’re not paying extra to get value — you just need to install the latest version. Session attendees found this slide helpful, illustrating the different kinds of Purity releases. “How do self-service upgrades work?” Admins were curious about how much they can do themselves versus involving Pure Storage support. The good news: self-service upgrades are straightforward through Pure1, but you’re never on your own. Pure Technical Services knows that you're running an upgrade, and if an issue arises you’re automatically moved to the front of the queue. If you want a co-pilot, then of course Pure Storage support can walk you through it live. Either way, the process is fast, repeatable, and built for confidence. Upgrading your Purity version has never been easier, now that Self Service Upgrades lets you modernize on your schedule. “Why should I upgrade regularly?” This is where the conversation shifted from fear to excitement. Staying current doesn’t just keep systems secure — it unlocks new capabilities like: Pure Fusion™: a unified, fleet-wide control plane for storage. FlashArray™ Files: modern file services, delivered from the same trusted platform. Ongoing performance, security, and automation enhancements that come with every release. One attendee summed it up perfectly: “Upgrading isn’t about fixing problems — it’s about getting new toys.” The Takeaway The biggest lesson from this session? Purity upgrades aren’t something to fear — they’re something to look forward to. They’re included with your Evergreen subscription, they don’t disrupt your environment, and they unlock powerful features that make storage easier to manage. So if you’ve been putting off your next upgrade, take a fresh look. Chances are, Fusion, Files, or another feature you’ve been waiting for is already there — you just need to turn it on. 👉 Want to keep the conversation going? Join the discussion in the Pure Community and share your own upgrade tips and stories. Be sure to join our next Ask Us Everything session, and catch up with past sessions here!700Views3likes2CommentsPure1 Manage Assessment
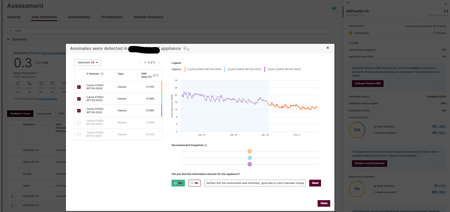
Hey Cincy PUG, I found a cool feature for detecting changes on your Flash Array. Looking at Data Protection under the Assessment menu I saw a lightning bolt on one of my arrays. That lightning bolt led me to an evaluation showing that there had been a significant drop in DRR for a group of volumes. Turns out that change was benign because one of my teammates refreshed an environment causing the change in the Data Reduction Ratio. I see this as just another way Pure 1 Manage can help admins detect threats or problems with data sets. How are you using the tools in Pure1? Share something with the group! -Charles153Views2likes0Comments
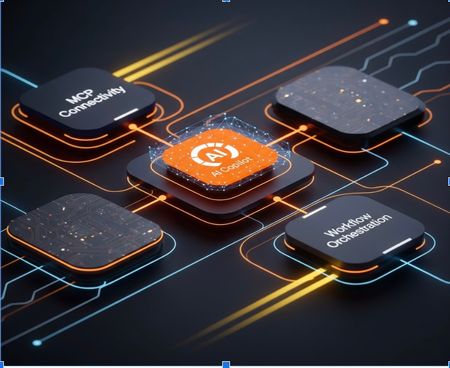
Pure's Intelligent Control Plane: Powered by AI Copilot, MCP Connectivity and Workflow Orchestration
At Accelerate 2025, we announced two capabilities that change how you manage Pure Storage in your broader infrastructure: AI Copilot with Model Context Protocol (MCP) and Workflow Orchestration with production-ready templates. Here's what they do and why they matter. AI Copilot with MCP: Your Infrastructure, One Conversation The Problem Your infrastructure spans multiple platforms. Pure Storage managing your data, VMware running VMs, OpenShift handling containers, security tools monitoring threats, application platforms tracking performance - each with its own console, APIs, and workflows. When you need to migrate a VM or respond to a security incident, you're manually pulling information from each system, correlating it yourself, then executing actions across platforms. You become the integration layer. The Solution Pure1 now supports Model Context Protocol (MCP), taking Copilot from a suggestive assistant to an active operator. With MCP enabled, Copilot doesn’t just recommend - it acts. It serves as a secure bridge between natural language and your infrastructure, capable of fetching data, executing APIs, and orchestrating workflows across diverse systems. Here’s what makes this powerful: You deploy MCP servers within your environment—one for VMware, another for OpenShift, and others for the systems you use. Each server exposes your environment’s capabilities through a standard, interoperable protocol. Pure Storage AI Copilot connects seamlessly to these MCP servers, as well as to Pure services such as Data Intelligence, Workflow Orchestration, and Portworx Monitoring, enabling unified and secure automation across your hybrid ecosystem. What You Can Connect You can deploy an MCP server on any system whether it’s your VMware environment, Kubernetes clusters, security platforms like CrowdStrike, databases, monitoring tools, or custom applications. Pure Storage AI Copilot connects to these servers under your control, securely combining their data with Pure Storage services to deliver richer insights and automation. Getting Started: If you have a use-case around MCP, please contact your Pure Storage account team. Workflow Orchestration: Deploy in Minutes, Not Months The Problem Building production-grade automation takes months. You need error handling, integration with multiple systems, testing for edge cases, documentation, ongoing maintenance. Most teams end up with half-finished scripts that only one person understands. The Solution We built workflow templates for common operations, tested them at scale, and made them available in Pure1. Install them, customize to your needs, and run them in minutes. Key Templates VMware to OpenShift Migration with Portworx Handles complete migration: extracts VM metadata, identifies backing Pure volumes, checks OpenShift capacity, configures vVols Datastore and DirectAccess, uses array-based replication, converts to Portworx format. Traditional migration takes hours for TB-scale VMs. This takes 20 to 30 minutes. SQL / Oracle Database Clone and Copy Automates cloning and copying of SQL Server and Oracle databases for dev/test or refresh needs. Instantly creates storage-efficient clones from snapshots, mounts them to target environments, and applies Pure-optimized settings. The hours-long manual process becomes a quick, consistent workflow completed in minutes Daily Fleet Health Check Scans all arrays for capacity trends, performance issues, protection gaps, hardware health.Posts summary to Slack. Proactive visibility without manually checking each array. Rubrik Threat Detection Response When Rubrik detects a threat, automatically tags affected Pure volumes, creates isolated immutable snapshots, and notifies the security team. Security events propagate to your storage layer automatically. How It Works Workflow Orchestration is a SaaS feature in Pure1. Deploy lightweight agents (Windows, Linux, or Docker) in your data center to execute workflows locally. Group agents together for high availability and governance controls. Integrations Native Pure Storage: Pure1 Connector for full API access, Fusion Connector for storage provisioning (works for Fusion and non-Fusion FlashArray/FlashBlade customers) Third-Party: ServiceNow, Slack, Google, Microsoft,CrowdStrike, HTTP/Webhooks, Pagerduty, Salesforce and more. The connector library continues expanding. Getting Started: Opt-in now in Pure1 - Workflow. Introductory offer available at this time. Check with your Pure account team if you have questions. How They Work Together At Accelerate 2025 in New York, we showcased this capability in action. Here's the scenario: an organization wants to migrate VMs to Kubernetes. Action-enabled Copilot orchestrates communication with Pure Storage appliances and services as well as third-party MCP servers to collect the required information for addressing a problem across a heterogeneous environment. With Pure1 MCP, AI Copilot, and Workflows, there's now a programmatic way to collect information from OpenShift MCP, VMware MCP, and Pure1 storage insights- then recommend an approach on what VMs to migrate based on your selection criteria. You prompt Copilot: "How can I move my VMs to OpenShift in an efficient way?" Copilot communicates across: Your VMware MCP server - to get VM specifications, current configurations, resource usage Your OpenShift MCP server - to check available cluster capacity, validate compatibility Portworx monitoring - to understand current storage performance Copilot reasons across all this information, identifies ideal VM candidates based on your criteria, and recommends the migration approach- which VMs to move, target configurations, and how to preserve policies. Then it can trigger the migration workflow, keeping you updated throughout the process. Why This Matters Storage Admins: Stop being the bottleneck. Enable self-service while maintaining governance. DevOps Teams: Deploy production-tested automation without writing code. Security Teams: Build automated response workflows spanning detection, isolation, and recovery. Infrastructure Leaders: Reduce operational overhead. Teams focus on strategy, not repetitive tasks. Get Started MCP Integration:If you have a use-case around MCP, please contact your Pure Storage account team.. Workflow Orchestration:Opt-in at Pure1 → Workflows. Learn More: Documentation in Pure1 or contact your Pure Storage account team. Pure1 evolved from a monitoring platform to an Intelligent Control Plane. AI Copilot reasons across your infrastructure. Workflow Orchestration executes. Together, they change how you manage data with Pure Storage.1.1KViews2likes0Comments